# Admin API Reference
Source: https://www.credibledata.com/docs/admin-api-reference
Admin API reference for the Credible Data API, generated from the OpenAPI specification. Every endpoint lists its parameters, request and response schemas, and example requests in several languages.
Use it to manage the organization itself: environments, packages and their versions, connections, users and groups, and the permissions that decide who can read which package, workspace, or document. It is the API behind the Credible App and the CLI, so anything either of them does, a script can do with a group access token.
---
# Coding API Reference
Source: https://www.credibledata.com/docs/coding-api-reference
Coding API reference for the Credible Data API, generated from the OpenAPI specification. Every endpoint lists its parameters, request and response schemas, and example requests in several languages.
Use it for Credible's code-assist features. The one externally supported endpoint is Malloy documentation search, which any authenticated caller, including your own MCP server, can invoke with a group access token. The remaining endpoints back the Credible VS Code extension and are not an integration surface.
---
# Support
Source: https://www.credibledata.com/docs/community/support
Email [support@credibledata.com](mailto:support@credibledata.com) with a question, a bug, or a modeling problem you're stuck on. Include your organization name and, for a failed query or publish, the package and version.
---
# Architecture
Source: https://www.credibledata.com/docs/concepts/architecture
Credible is a distributed system built so that a single governed model can serve every consumer — reliably, at scale, and without downtime. The design rests on one central separation: the **control plane** manages your data assets, while the **data plane** serves queries from them.
This split is deliberate. Administrative work — publishing a version, updating permissions, indexing a connection — never contends with live query traffic, and query serving never waits on administration. Each plane scales and fails independently, so a spike in dashboard load can't slow down publishing, and a busy publish pipeline can't slow down the agent answering a question.
Manages the resource hierarchy — environments, connections, packages, versions, permissions — and orchestrates indexing and materialization. Reached at `.admin.credibledata.com` and through the [Credible App](https://credibledata.com).
Serves your published models: executes queries, powers agents, and serves data apps. Optimized for low latency and high concurrency at `.data.credibledata.com`.
## The Query Path
Every request — from a person in a workspace, an [MCP agent](/docs/how-to/analyzing/ai-assistants-mcp), or a [REST API](/docs/how-to/integrating/apis) call — follows the same path through the data plane:
```mermaid
flowchart LR
Consumer["Workspace / Agent / API"] --> Router["Router (data plane)"]
Router --> W1["Worker"]
Router --> W2["Worker"]
Router --> W3["Worker"]
W1 --> DB[("Your warehouse")]
W2 --> DB
W3 --> DB
```
1. **The router resolves your organization** from the request hostname and looks up which workers currently hold the requested package version.
2. **It load-balances across the healthy replicas** holding that version. If a worker becomes slow or unreachable, the router transparently retries another replica — no request is stranded on a failed node.
3. **A worker executes the query.** Workers run [Malloy](/docs/concepts/why-malloy), compiling each request to optimized SQL and executing it against your warehouse through the environment's [managed connection](/docs/how-to/modeling/connect-data).
The engine also has storage of its own — the **lakehouse tier**, a SQL catalog over Parquet on object storage — where it keeps the tables, rollups, and caches it builds from your model (see [Performance & Cost](/docs/how-to/modeling/persistence)). A query that a stored copy covers is served from there; the rest run live against the connected database. Connect data where it already lives; you do not need to bring a warehouse to start.
Credentials never leave the control plane, and consumers never touch the database directly. Every query is proxied, authorized, and logged — the single enforcement point described in [Governance](/docs/concepts/governed-platform).
## Built for Availability
Serving many consumers from one model means the serving layer has to stay up through worker failures, deploys, and new releases of your model. Three properties make that possible.
### Immutable, versioned packages
When you [publish](/docs/how-to/modeling/publishing), the package is written to object storage as an **immutable, versioned archive**. A version is never mutated in place — publishing again creates a new version. This makes serving deterministic (every worker loads byte-identical package contents) and rollback trivial (a previous version is still there, untouched).
### N-way worker replication
Each package version is loaded onto **multiple workers**, not one. The control plane continuously reconciles the fleet: if a worker is lost, it re-replicates the version onto healthy workers to restore the target replica count. The router only routes to workers confirmed to hold the version. You set the replication factor per environment and per package — trading redundancy against footprint — with the [`--replication` flag](/docs/platform-admin/cli) when creating environments or publishing.
### Zero-downtime version promotion
New versions are loaded onto workers **before** they start serving traffic. The current version keeps answering queries until the new one is fully loaded, then promotion flips the `latest` pointer atomically — in-flight queries are never interrupted. Consumers track `latest` by default or pin a specific version. [Auto-promote and auto-archive](/docs/how-to/modeling/publishing) manage this lifecycle: a version is promoted only once it's ready, and superseded versions are archived (and their storage reclaimed) automatically.
Indexing and materialization run **asynchronously** after publish — the model serves live queries immediately, and search and materialized tables come online shortly after. Publishing is never blocked waiting on them, and queries always return correct results by falling back to live execution until a materialized table is ready.
## Built for Scale
The data plane scales horizontally to meet demand:
- **Stateless services** — the router, workers, retrieval, MCP, and agent services hold no per-request state, so they scale out by adding replicas. They autoscale automatically with load.
- **Multi-zone Kubernetes** — services run across availability zones with rolling, disruption-budgeted deploys, so node failures and upgrades don't take the service offline.
- **Secured edge** — all traffic terminates TLS behind a global load balancer with a web application firewall. Outbound queries to your warehouse originate from stable egress IPs, so you can allowlist Credible without opening your database to the world.
## Tenancy and Isolation
Each organization is addressed by its own hostnames — `.app`, `.admin`, `.data`, `.mcp`, and `.retrieval` under `credibledata.com`. Every request carries an [Auth0](/docs/how-to/integrating/apis#authentication) identity or API key whose organization claim must match, and fine-grained authorization is checked on each call. Retrieval data is partitioned per organization with fail-closed isolation.
For customers with strict residency or isolation requirements, Credible also runs **dedicated single-tenant cells** — fully isolated deployments (including on a separate cloud), selected transparently by endpoint.
## How the Concept Index Is Built
Beyond serving queries, the engine builds the **concept index** — a searchable understanding of your model and its data that powers the AI-assisted workflow end to end. It runs as background pipelines with the write path isolated from the read path — so indexing load never affects query or search latency.
- **Before a model exists** — connection indexing profiles your raw data landscape (table and column metadata, schema, and relationships) so agents have the context to help you [build a model](/docs/how-to/modeling/ai-modeling) from scratch.
- **After you publish** — the engine compresses the model into the concept index: every source, dimension, measure, and view, its `#(doc)` definition, and — with optional [value indexing](/docs/how-to/modeling/metadata-tags) — the actual values of every `#(index)` dimension, so an agent matches a question by meaning, not by column name.
Search runs through a dedicated retrieval service, separate from the workers that execute queries, so the two scale independently.
## One Gateway
Because every query — human or agent — enters through one gateway and routes through the governed data model, that gateway becomes a single point of control and improvement:
- **Governance and compliance** — one gateway means [access controls](/docs/how-to/modeling/fine-grained-acls) are enforced consistently and every query is logged to an immutable audit trail.
- **Performance and cost** — the engine observes query cost and latency across all consumption and uses it to guide [materialization](/docs/how-to/modeling/persistence) and caching.
- **A feedback loop** — usage analyzed against the model surfaces coverage gaps, semantic drift between teams, and underused data, so the model evolves with the business instead of decaying.
## Next Steps
Chat with data in governed workspaces
How models become versioned, served packages
Build on the Admin, Data, and Retrieval APIs
Connect agents to your data models
---
# The Data Model
Source: https://www.credibledata.com/docs/concepts/data-model
A **data model** spans the whole distance from your raw operational data to the business domain. It carries the structure underneath — which tables matter, how they relate, the keys and joins — and the meaning on top: what terms like *revenue* and *active customer* actually mean. Because one artifact covers all of that, we call it one thing: the data model.
The model is the input you write. From it, the engine generates everything downstream: the dashboards, data apps, and APIs on top; the **semantic layer** that serves them, where metrics resolve consistently and access is enforced on every query; and the materialized storage, pipelines, and indexes underneath. Credible is that engine, not a semantic layer itself.
In Credible, data models are written in [Malloy](/docs/concepts/why-malloy), versioned as packages, and published from [environments](/docs/how-to/modeling/environment-overview) to every consumer at once. This page covers the concept; the [Modeling Overview](/docs/how-to/modeling/ai-modeling) covers building one.
## Why Data Models Matter
Modern organizations have data spread across many systems — sales in the CRM, marketing in analytics tools, finance in the ERP — and each system, team, and dashboard tends to develop its own definitions of key metrics. When "monthly revenue" is computed five different ways, the numbers disagree, meetings turn into debates about whose figure is right, and trust in data erodes. A data model fixes this at the root: every metric, relationship, and business rule is defined once, in one place, and reused everywhere.
The model also acts as a **data contract** between producers and consumers. Engineering teams evolve schemas, migrate warehouses, and refactor pipelines behind the model; analysts, applications, and agents query stable business definitions in front of it. When the underlying systems change, the contract holds — reports and applications keep working.
AI raises the stakes. An agent answers in seconds, at scale, to people who may not know enough to question the result — so drifting definitions or subtly wrong logic do damage before anyone catches them. A data model is what makes AI trustworthy: instead of guessing at raw schemas, the agent works from your governed definitions, and every answer is consistent with what humans see in dashboards. This is the foundation the engine is built on.
## Anatomy of a Data Model
A data model is built from a handful of constructs. Here's a compact but complete example:
```malloy
source: customers is conn.table('sales.customers') extend {
primary_key: id
#(doc) Sales region assigned at account creation
dimension: region is upper(region_code)
}
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers on customer_id = customers.id
dimension: order_month is order_date.month
#(index)
#(doc) Net revenue recognized at order completion, in USD
measure: total_revenue is sum(order_amount)
view: revenue_by_region is {
group_by: customers.region
aggregate: total_revenue
}
}
```
### Sources
**Sources** are datasets extended with business logic — the reusable building blocks of the model. A source wraps a table (or another source) and attaches everything the organization knows about it: keys, relationships, definitions, and metadata.
### Joins
**Joins** declare how sources relate, once, with explicit business meaning — `orders` join one `customer`. Every query can then traverse the relationship without restating join conditions, and Malloy's aggregate handling guarantees that joined queries never double-count.
- `join_one` — one-to-one or many-to-one relationships
- `join_many` — one-to-many relationships
- `join_cross` — cartesian products (used sparingly)
### Dimensions
**Dimensions** are the attributes you group and filter by — the "who, what, when, where" of your data. They range from simple column references to derived fields, categorizations, and date transformations like `order_month` above.
### Measures
**Measures** are aggregate calculations that produce business metrics — the "how many, how much." A measure like `total_revenue` is defined once on its source and means exactly the same thing in every query, dashboard, and AI-generated answer that references it.
### Views
**Views** are saved query patterns — curated combinations of dimensions, measures, and filters like `revenue_by_region`. They encode the analyses your organization actually runs, giving consumers (and agents) proven starting points instead of blank pages.
### Filters
**Filters** restrict data to relevant subsets and can be applied at every level — source-wide (a source of only completed orders), within a view, or on a single measure (revenue from enterprise customers only).
### Annotations & Metadata
**Annotations** are tags that layer metadata onto the data model — documentation, discovery hints, access rules, and performance directives, living next to the data they describe:
- **Documentation & discovery** — `#(doc)` describes a field in business terms and `#(index)` makes its values searchable, feeding the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) so agents can find and understand your data. See [Discovery Metadata](/docs/how-to/modeling/metadata-tags).
- **Access control** — `#(authorize)` and secure givens define row- and column-level security in the model itself, enforced on every surface. See [Access Control](/docs/how-to/modeling/fine-grained-acls).
- **Performance & cost** — `#@ persist` materializes expensive sources so queries read pre-computed tables. See [Performance & Cost](/docs/how-to/modeling/persistence).
Because annotations are part of the model's code, this metadata is version-controlled, reviewable, and published together with the definitions it describes — not maintained in a separate catalog that drifts out of date.
## From Schema to Semantic Graph
A database schema permits every join its foreign keys allow — a **natural graph** where most paths are meaningless or dangerous, and nothing distinguishes the join an analyst should use from the one that silently double-counts. Modeling transforms that into a **curated semantic graph**: only meaningful business relationships, each declared with explicit intent.
Curation is what makes this valuable: it eliminates ambiguity (one right way to connect orders to customers), enables governance (definitions and access rules attach to the graph), and makes data explorable — a business user or an AI agent can navigate the model without knowing anything about the underlying schema.
## Models Are Versioned Packages
In Credible, a data model doesn't live loose — it ships as a **package**: model files, [data apps](/docs/how-to/analyzing/data-apps), and a manifest, versioned together and [published](/docs/how-to/modeling/publishing) from an environment. This brings the software lifecycle to data:
- **One model, every consumer** — a published package serves [workspace chat](/docs/how-to/analyzing/workspaces), data apps, [MCP agents](/docs/how-to/analyzing/ai-assistants-mcp), and the [REST APIs](/docs/how-to/integrating/apis) from the same definitions
- **Safe evolution** — new versions publish atomically; data apps are versioned with the models they're built on, so a model change never breaks a dashboard mid-flight
- **Accountability** — every definition traces to a reviewed, version-controlled change
The result is an organization that speaks a common data language — consistent definitions, governed access, and AI you can trust, all from one model.
## Next Steps
Start building data models with AI agents
The open-source language data models are written in
How Credible implements and serves semantic data models
How governance becomes the path of least resistance
---
# Governance
Source: https://www.credibledata.com/docs/concepts/governed-platform
Data governance has a reputation for being restrictive and slow — the review board that takes three weeks, the locked-down warehouse nobody can query. At Credible, we believe governance works by making the governed path faster and easier than working around it — so **people choose it**.
Our philosophy: **make governance the path of least resistance**.
## Why Traditional Governance Fails
If the central data platform is slow, inflexible, or confusing, users route around it. When building a private spreadsheet is faster than waiting for the official dashboard, analysts abandon the central system — and the organization inherits data silos, inconsistent metrics, and mistrust in the numbers. Governance becomes a roadblock to bypass, not a guardrail for safety.
AI raises the stakes in both directions. An ungoverned agent pointed at raw data produces confident, wrong answers at scale. But a governed agent — one that answers through vetted data models, quickly and reliably — removes the reason to bypass governance at all. When the governed path is also the best path, good governance becomes the fastest way to get work done.
## How Credible Governs
In Credible, governance is built into how models are defined, published, accessed, and observed, not layered on top as a policy document.
### Definitions Live in Code
Business logic is defined once, in version-controlled [Malloy models](/docs/concepts/data-model). Every dashboard, workspace chat, and AI-generated answer operates from the same verified source of truth — consistent metrics, relationships, and joins across the organization. Because the model is code, changes go through the same discipline as software: reviewed in pull requests, tested in CI, and traceable to an author.
### Data Assets Have a Software Lifecycle
Models, [data apps](/docs/how-to/analyzing/data-apps), and their manifest ship together as versioned packages, with the same atomic [publishing](/docs/how-to/modeling/publishing), auto-promote, and auto-archive lifecycle described in [Architecture](/docs/concepts/architecture) — so updating logic never breaks downstream consumers mid-flight.
### Access Is Controlled at Every Level
- **Permissions** — Role-based permissions govern who can do what: environment roles (Admin, Modeler, Viewer) control modeling and publishing, while workspace and document sharing control analysis. See [Permissions](/docs/platform-admin/permissions).
- **Connections** — Database credentials are stored once, in the environment, and never leave it. Modelers and developers SSO into Credible and work against managed connections — no credentials on laptops, no shared service accounts. Every query is proxied through Credible, access-checked, and logged. See [Environments](/docs/how-to/modeling/environment-overview).
- **Data** — Row- and column-level security is defined in the model itself with `#(authorize)`, secure givens, and field access modifiers — version-controlled, auditable, and enforced identically on every surface, from workspace chat to MCP agents to the REST APIs. See [Access Control](/docs/how-to/modeling/fine-grained-acls).
Because every consumer goes through the same governed data model, there is exactly one enforcement point. There's no BI tool with its own permissions to drift out of sync, and no API path that skips the rules.
### Everything Is Visible
Because all consumption routes through one gateway, Credible gives you a single place to find the code that defines any metric and to trace lineage from source database to final answer. That same gateway is what makes compliance, cost, and model quality observable — see [One Gateway](/docs/concepts/architecture#one-gateway) for how the audit trail, the cost and latency data, and the feedback loop all follow from it.
## Next Steps
Understand Credible's permission model
Define row- and column-level security in your model
Version and serve models as governed packages
How Credible implements and serves semantic data models
---
# Why Malloy?
Source: https://www.credibledata.com/docs/concepts/why-malloy
Every data model in Credible is written in [**Malloy**](https://malloydata.dev), an open-source language for analyzing, transforming, and modeling data. Malloy compiles to optimized SQL for BigQuery, Snowflake, PostgreSQL, Databricks, Trino, DuckDB, and more — so it runs wherever your data lives — but it captures something SQL cannot: what your data *means*.
The ideas behind Malloy are decades in the making, built by the team whose earlier work on LookML defined the modern semantic layer. Malloy is their second take — a full language rather than a configuration format, stewarded in the open by the Linux Foundation.
## SQL Says How. Malloy Says What.
SQL is an instruction set: you tell the database which tables to scan, how to join them, and what to group by — every time, in every query. The business logic is buried in the mechanics, and nothing stops two analysts from writing it two different ways.
Malloy inverts this. Relationships, definitions, and calculations live in the model, declared once. Queries just ask questions of it:
```malloy
source: orders is conn.table('sales.orders') extend {
join_one: customers on customer_id = customers.id
measure: total_revenue is sum(order_amount)
}
```
```malloy
run: orders -> {
group_by: customers.region
aggregate: total_revenue
}
```
The equivalent SQL restates the join condition and the revenue formula inline — and every query that follows restates them again. In Malloy, `total_revenue` means the same thing in every query, every dashboard, and every AI-generated answer, because there is only one definition.
## Correct by Construction
Data teams lose trust one subtly wrong number at a time. Malloy is designed to make the most common classes of error impossible:
- **Symmetric aggregates** — Malloy understands the data graph, so joining `orders` to `order_items` never double-counts order revenue. Aggregates compute correctly at any grain, automatically — the fanout bugs that silently corrupt SQL results don't happen.
- **Compile-time validation** — Every field reference is checked against the warehouse schema before a query runs. Rename a column and the compiler tells you exactly what broke, instead of a dashboard quietly serving wrong numbers.
- **Explicit dependencies** — Sources reference each other as named language constructs, not strings in templates. The compiler builds the dependency graph itself, so breaking changes surface before runtime.
## Freedom and Safety
Raw SQL offers maximum freedom but no safety — there's no way to save or reuse a calculation, so definitions drift. YAML-based semantic layers like LookML offer safety but constrain what you can express, and complex logic ends up escaping back into raw SQL.
Malloy combines both: the safety of a governed data model with the full power of a relational query language. A few examples of what that makes possible:
- **Composition** — Dimensions can reference other dimensions directly; transformations that take four chained CTEs in SQL take four lines in Malloy. Sources extend other sources, so `enterprise_customers` inherits everything from `customers` and adds only what differs.
- **Nesting** — Queries return rich hierarchical results natively — revenue by region, with a monthly breakdown nested inside each row — without rewriting or re-joining anything.
- **Pipelines** — Query results feed into further queries, supporting sophisticated multi-stage analysis in a single readable definition.
And when you genuinely need database-specific functionality, `sql()` blocks give you an escape hatch with type safety intact.
## One Language for the Whole Lifecycle
In most stacks, the model is scattered across tools: SQL for transformation, YAML for metrics, a catalog for documentation, warehouse policies for access control, an orchestrator for materialization. Malloy's annotation system pulls the whole lifecycle into the model itself:
```malloy
#(doc) Net revenue recognized at order completion, in USD
measure: total_revenue is sum(order_amount)
```
- `#(doc)` and `#(index)` document fields and index their values, so agents can [find and understand your data](/docs/how-to/modeling/metadata-tags)
- `#(authorize)` and field modifiers define [row- and column-level access control](/docs/how-to/modeling/fine-grained-acls) next to the data they protect
- `#@ persist` [materializes expensive sources](/docs/how-to/modeling/persistence) — no separate YAML config or external orchestration, with incremental rebuilds handled by the compiler
Everything lives in one set of version-controlled files: reviewable in a pull request, testable in CI, and deployable as a [versioned package](/docs/how-to/modeling/publishing).
## Built for AI
Malloy predates the AI wave, but it turned out to be exactly what AI needed. Frontier models write Malloy fluently — it's in their training data — and the language's design compounds the advantage:
- **Agents write it well.** Malloy is compact and declarative, and the compiler validates every query against the model before execution. When an agent gets something wrong, it gets a precise error instead of a plausible-looking wrong answer.
- **Agents read it well.** A Malloy model is dense with meaning — definitions, relationships, documentation, and access rules in one place. That's the context that turns a generic chatbot into an analyst that answers with *your* definitions.
- **The model is the contract.** Because every AI-generated query runs through the data model, answers are auditable, access-controlled, and consistent with what humans see in dashboards.
This is why the engine and Credible's [open-source agent skills](/docs/introduction#one-set-of-skills-every-surface) are built around Malloy: the language gives agents something SQL never could — the meaning behind the data.
## Open Source, No Lock-In
Malloy is open source and committed to backward compatibility. Your models are portable, inspectable text files — you own the meaning you encode in them. The whole serving stack is open too: [Malloy Publisher](https://github.com/malloydata/publisher) serves Malloy models over REST and MCP, and Credible's agent skills and MCP tools are contributed there in the open. Credible is the hosted, governed engine on top of that stack — not a walled garden around it.
## Next Steps
Start building Malloy data models with your agent
The core components of a data model
For the language itself, see the [Malloy Language Documentation](https://docs.malloydata.dev/documentation/) and the [Malloy GitHub repository](https://github.com/malloydata/malloy).
---
# Data API Reference
Source: https://www.credibledata.com/docs/data-api-reference
Data API reference for the Credible Data API, generated from the OpenAPI specification. Every endpoint lists its parameters, request and response schemas, and example requests in several languages.
Use it to work with the data model: list environments and packages, read a model's sources and views, run queries, and work with materializations. It is the same API the Credible App and every agent surface query through, so an answer here is the governed answer.
---
# MCP Tools
Source: https://www.credibledata.com/docs/how-to/analyzing/ai-assistants-mcp
MCP (Model Context Protocol) is the open standard agents use to connect to tools — and Credible's MCP tools are the same `get_context` and `execute_query` every Credible surface runs, available to any agent you build. They use the [Credible AI Analytics Engine](/docs/how-to/analyzing/overview) to ground any LLM or agent in governed data definitions. When you ask a question, the `get_context` tool parses your input into semantic phrases and matches each phrase to data entities (dimensions, measures, views) in your data model — searching against the `#(doc)` descriptions and `#(index)` annotations declared in your model. Your LLM gets ranked entity matches and Malloy syntax guidance, so it can construct accurate queries without hallucinating field names or misunderstanding your data structure.
This page covers the **consumption MCP server** used by LLMs, workspace chat, and custom agents. The **modeling MCP tools** coding agents use to build models — the same open tools Malloy Publisher provides — are served separately and configured automatically; see the [VS Code Extension](/docs/how-to/developers/vscode-extension#modeling-mcp-tools).
On this page:
- **[The MCP server](#the-mcp-server)** — the endpoint and how to scope it
- **[Connecting custom agents](#connecting-custom-agents)** — your own applications, authenticated with a Bearer token or a group-scoped API key
- **[Tool reference](#tool-reference)** — which tools each endpoint exposes, with parameters and responses
Connecting a personal chat client like Claude, Cowork, or ChatGPT? See [Connect your Agent](/docs/how-to/analyzing/connect-your-llm). Connecting an IDE or CLI coding agent like Claude Code, Codex, Cursor, Copilot, opencode, or Gemini CLI? See [Connect your Coding Agent](/docs/how-to/developers/connect-coding-agent).
## The MCP Server
Use the Credible MCP server URL: `https://mcp.credibledata.com/global/`
This one URL serves every organization and workspace your account can reach — the server resolves scope from who you signed in as, so it is the URL to hand out everywhere: connectors, plugins, and the **Connect AI** page in the Credible App. It is also the URL behind Credible's listing in Anthropic's connector directory and the Credible plugin.
Two narrower endpoints exist as deliberate scope-downs, for an agent that should see less than your account can:
- **Organization-scoped**: `https://.mcp.credibledata.com/mcp` — every published package you can access in that organization, across all environments
- **Workspace-scoped**: `https://.mcp.credibledata.com/mcp/workspace/{workspace_name}` — only the packages in that workspace
You do not have to assemble either by hand: **Connect AI** in the app has an **Access** control that switches between the three, and the per-client setup steps below it are rendered with whichever URL you picked. Open it from the settings gear in the sidebar, then **Connect AI** — every role can reach it. A workspace's settings page links into it with that workspace already selected.
Use a scoped URL to keep one assistant's default retrieval narrow — an agent you don't want drifting across environments, or a connection you want pointed at a single workspace. It is not a sandbox and not a permission boundary: every request is authorized against the identity behind it, so scoping changes where a connection *starts looking*, not what the signed-in account may reach. Handing someone a scoped URL grants them nothing either — they sign in as themselves and see only what they could already see. Note also that scoping targets shared workspaces: your personal **My Workspace** is not a workspace you can narrow a connection to.
One thing a scoped URL cannot do is drive a packaged install. The Claude plugin and the connector-directory listing ignore a pasted URL and connect to everything your account can reach, so Connect AI drops them the moment you narrow and shows you how to add the server by URL instead.
## Connecting Custom Agents
The MCP server accepts the same [two authentication schemes](/docs/how-to/integrating/apis#authentication) as the REST APIs:
- **Bearer token** — Acts as the signed-in user, with their permissions. This is what the OAuth flow in MCP clients produces, and you can use it directly for interactive testing or scripts run by a person:
```
Authorization: Bearer
```
- **API key** — Acts as a group. For custom agents and services — anything running server-to-server, where an OAuth sign-in flow isn't available — create a group-scoped key by following [Create an API Key](/docs/how-to/integrating/apis#create-an-api-key):
```
Authorization: ApiKey your-api-key
```
### Testing with curl
The examples below use the organization-scoped URL, because a custom agent authenticating with a group API key is exactly the case where you want the narrower scope. You can verify your connection with curl before integrating with your agent framework. The examples use an API key; substitute `Authorization: Bearer ` to test as yourself. First, initialize a connection to validate your credentials:
```bash
source .env && curl -X POST \
-H "Authorization: ApiKey ${MCP_API_KEY}" \
-H "Content-Type: application/json" \
-d '{
"jsonrpc": "2.0",
"id": 1,
"method": "initialize",
"params": {
"protocolVersion": "2024-11-05",
"capabilities": {},
"clientInfo": {
"name": "test-client",
"version": "1.0.0"
}
}
}' \
https://.mcp.credibledata.com/mcp | jq
```
Then list the available tools:
```bash
source .env && curl -X POST \
-H "Authorization: ApiKey ${MCP_API_KEY}" \
-H "Content-Type: application/json" \
-d '{
"jsonrpc": "2.0",
"id": 2,
"method": "tools/list",
"params": {}
}' \
https://.mcp.credibledata.com/mcp | jq
```
This should return the tool list for whichever endpoint you called — see [the table below](#tool-reference).
## Tool Reference
`get_context` and `execute_query` are the pair that does the work on every endpoint. What sits alongside them depends on which URL you connected to, because the two endpoints solve different problems: the global URL carries no organization in the hostname, so the agent has to be able to ask what it can reach and to fetch the analysis guides itself.
| Tool | Global (`mcp.credibledata.com/global/`) | Organization-scoped (`.mcp.credibledata.com/mcp`) |
|---|---|---|
| `get_context` | ✅ | ✅ |
| `execute_query` | ✅ | ✅ |
| `search_malloy_docs` | ✅ | ✅ |
| `list_workspaces` | ✅ | — (the organization is in the hostname) |
| `get_skill` | ✅ | — |
| `search_credible_docs` | — | ✅ |
`get_context` and `execute_query` take **different parameters on the two endpoints**. The global versions carry the scope in the call (`organization`, `workspace`) because the hostname doesn't; the organization-scoped versions derive it from the hostname. The sections below document the organization-scoped shapes, with the global differences called out under each.
### get_context
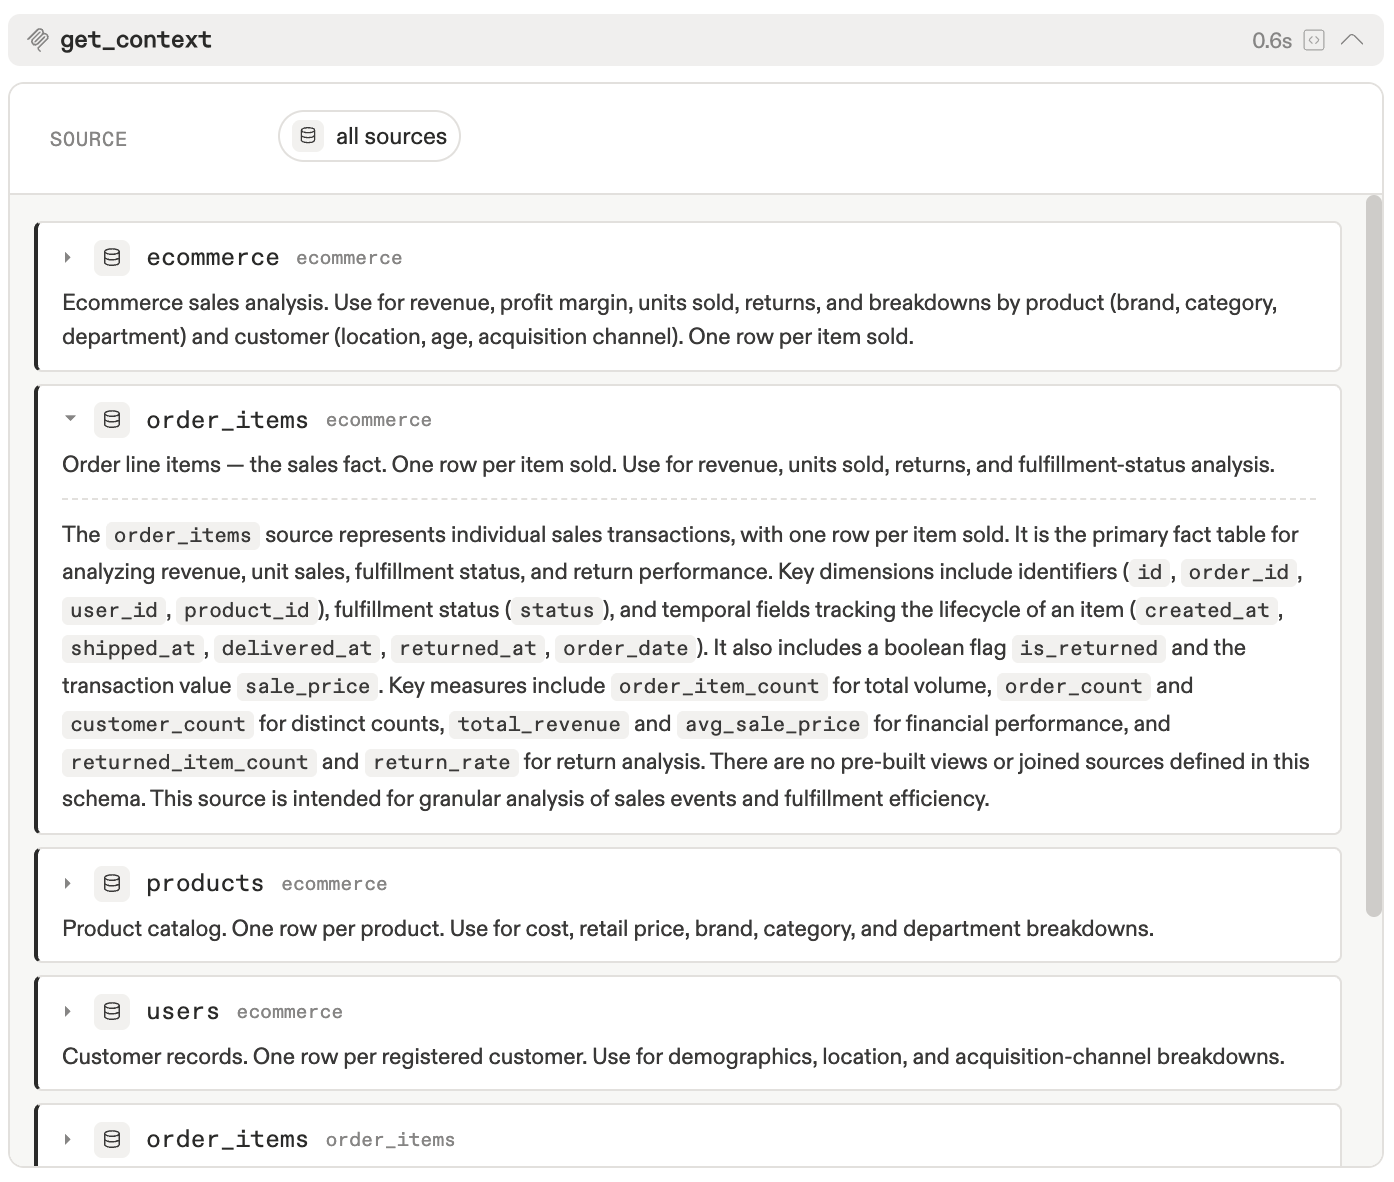
Parses a natural language question into semantic phrases, then matches each phrase to data entities in your published data models. Matches are grounded in the `#(doc)` descriptions and `#(index)` annotations declared in your model — the richer your documentation, the better the matches. This is the core retrieval tool powering the [Credible AI Analytics Engine](/docs/how-to/analyzing/overview#how-it-works).
**How it works:**
1. **Phrase extraction** — An LLM parses your input into semantic phrases (e.g., "top selling brands by month" becomes phrases like "top selling", "brands", "by month")
2. **Entity matching** — Each phrase is matched against your model's indexed metadata using embedding-based semantic search. This searches `#(doc)` descriptions, field names, and `#(index)` dimensional values. Matching is semantic, not exact — for example, "soccer games" can match a program titled "World Cup Finals" via indexed values and a genre of "Sports" via doc tags
3. **Ranked results** — Returns matched entities (dimensions, measures, views, columns) grouped by phrase, sorted by match score
 **Parameters:**
- `natural_language_query` (required): The user's question in natural language (e.g., "What were our top-selling products last year?")
- `environment_name` (optional): Environment name to search within. Only use if known from context.
- `package_name` (optional): Package name to narrow search scope. Requires `environment_name`.
- `model_uri` (optional): Path to a specific `.malloy` model file. Requires `environment_name` and `package_name`.
- `source_name` (optional): Specific source within a model. Requires `environment_name`, `package_name`, and `model_uri`.
**Parameter Dependencies:** `environment_name` → `package_name` → `model_uri` → `source_name`
**On the global endpoint** the call is different, not just wider: `organization`, `workspace`, and `search_targets` are all required, and `search_targets` is an array of typed targets rather than one `natural_language_query` string. `scopes` optionally narrows the search. Call `list_workspaces` first if you don't already know which organization and workspace to name.
**Scope Strategy:** Start broad when uncertain, narrow as you discover structure. If results are insufficient, widen scope by removing parameters from right to left.
**Response:**
- `sources`: Array of matched sources, each containing:
- `phrases`: Matched phrases from your input, each with:
- `phrase`: The extracted phrase text
- `phrase_description`: Extended description of the phrase
- `overall_score`: Match confidence score
- `entities`: Matched data entities (dimensions, measures, views, columns) with `name`, `field_type`, `data_type`, `description`, `score`, `match_reason`, and `values` (for dimensions with indexed values)
- `next_steps`: Instructions for writing Malloy queries using the returned entities
- `malloy_documentation`: Malloy syntax reference and common error patterns
**Example Request:**
```bash
curl -X POST "https://your-org.mcp.credibledata.com/mcp" \
-H "Content-Type: application/json" \
-H "Authorization: ApiKey YOUR_API_KEY" \
-d '{
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "get_context",
"arguments": {
"natural_language_query": "What are the top 10 products by sales?",
"environment_name": "your-environment"
}
}
}'
```
### execute_query
Executes Malloy queries against published data models and returns JSON results.
**Parameters:**
- `environment_name` (required): Environment containing the model
- `package_name` (required): Package containing the model
- `model_uri` (required): Path to the `.malloy` model file
- `query` (optional)\*: Custom Malloy query code. Do NOT provide `source_name` when using this.
- `query_name` (optional)\*: Name of predefined query/view to execute
- `source_name` (optional)\*: Source name. Required when using `query_name`, omit when using custom `query`.
- `version_id` (optional): Specific package version to query against
**\*Execution Patterns:** Use exactly ONE of:
1. Custom query: Provide `query` parameter only
2. Predefined query: Provide both `query_name` and `source_name`
**Response:** Returns query results as JSON with `data`, `totalRows`, `executionTime`, and `metadata`
**On the global endpoint** the parameters name the same things but are spelled differently, and `organization` joins them: `organization`, `environment`, `package`, and `model_path` are required, with `query`, `query_name`, `source`, `version`, `filter_params`, `givens`, and `expanded` optional.
### list_workspaces
*Global endpoint only.* Lists the organizations and workspaces your identity can reach, so an agent connected to the org-agnostic URL can orient itself before its first real call. Optional `organization` filters to one. On the organization-scoped endpoint there is nothing to choose — the hostname already decided.
### get_skill
*Global endpoint only.* Returns Credible's analysis guides — the same [open-source skills](/docs/introduction#one-set-of-skills-every-surface) that ship in the Claude plugin — over MCP. It exists for the surfaces where skills can't ride along with the tools: a chat client connected through a connector has no plugin mechanism, so the guides have to be fetchable. Called with no arguments it lists what's available; `skill_name` returns one.
### search_malloy_docs / search_credible_docs
Both take a single `query` string and return matching documentation — Malloy language reference for the first, Credible product docs (including this page) for the second. `search_malloy_docs` is on both endpoints; `search_credible_docs` is currently on the organization-scoped endpoint only.
### Error Handling
The server returns standard MCP error responses for invalid requests, authentication failures, and query execution errors. Refer to the MCP specification for error code details.
Have custom authentication requirements? [Contact us](mailto:support@credibledata.com) to discuss your use case.
---
# Connect your Agent
Source: https://www.credibledata.com/docs/how-to/analyzing/connect-your-llm
Ask the same questions of the same governed models you [analyze in the Credible App](/docs/how-to/analyzing/workspaces), from the agent you prefer — Claude, ChatGPT, Gemini, or any MCP-compatible chat client. Connect it to Credible and it answers questions grounded in your governed data models — no hallucinated field names, no misread schemas — powered by the same [AI Analytics Engine](/docs/how-to/analyzing/overview) and the same [open-source agent skills](/docs/introduction#one-set-of-skills-every-surface) behind workspace chat. Same analysis discipline, your agent.
Personal agents connect to Credible's [MCP server](/docs/how-to/analyzing/ai-assistants-mcp) and authenticate with OAuth: add the server, complete the sign-in flow as yourself, and start asking questions. Because you sign in as yourself, every query is governed as you — your model's [access rules](/docs/how-to/modeling/fine-grained-acls) apply exactly as they do in the app.
Use the Credible MCP server URL: `https://mcp.credibledata.com/global/`
One URL covers every organization and workspace your account can reach — the server resolves scope from who you signed in as, so there is nothing org-specific to look up. To scope an agent down to one organization or one workspace instead, open **Connect AI** in the Credible App and pick the narrower scope under **Access**; the setup steps it shows carry the scoped URL. See [MCP Tools](/docs/how-to/analyzing/ai-assistants-mcp#the-mcp-server) for the endpoint shapes.
Connect AI is the quickest route to everything on this page: it prints the setup steps for each client with your URL already filled in, and every role can reach it. Open it from the settings gear in the sidebar, then **Connect AI**; a workspace's settings page links straight in with that workspace already selected.
Using an IDE or CLI coding agent — Claude Code, Codex, Cursor, VS Code Copilot, opencode, Gemini CLI, or Windsurf? See [Connect your Coding Agent](/docs/how-to/developers/connect-coding-agent) for connecting it to your published models.
The Credible plugin installs the connection *and* the analysis skills that teach Claude how to use it — phrase detection, Malloy query patterns, chart selection, and the analysis workflow. It works here, in the **Chat** tab of Claude Desktop, and in Cowork:
1. Open **Customize** in the sidebar, then the **Plugins** tab
2. Under **Personal plugins**, click **+** and choose **Add marketplace**
3. Enter `credibledata/credible-plugin`, then click **Sync**
4. Install **Credible** from the list
5. Open the installed plugin, go to its **Connectors** tab, and click **Connect**
Step 5 is easy to miss and is the reason a correct install can show no data: the plugin's connector is a second, separate install, and connecting it is what triggers sign-in.
Use `credibledata/credible-plugin` here, not the community catalog. Credible is listed in `anthropics/claude-plugins-community` as well, and that is the marketplace Claude Code adds — but the same slug fails in this dialog with "Failed to add marketplace". The plugin's own directory page is not a way around it: remove the marketplace and that page stops installing too.
**Connector only, no skills.** Credible is in Anthropic's connector directory, so there is nothing to paste:
1. Open [claude.ai/directory/credible](https://claude.ai/directory/credible), or find **Credible** under **Customize → Connectors → Browse connectors**
2. Click **Connect** and sign in to Credible
The connector works across claude.ai, Claude Desktop, and the mobile apps — you add it once per account. A connector carries the tools; the plugin above carries the tools and the skills.
To add it by URL instead — a narrowed scope from **Connect AI**, or a deployment other than production:
1. Open **Customize → Connectors**
2. Click **+**, then **Add custom connector**
3. Enter Name: `Credible` and the remote MCP server URL: `https://mcp.credibledata.com/global/`
4. Leave the OAuth fields empty and click **Add**
5. Click **Connect** on the next page and complete the sign-in flow
On **Cloud and Enterprise** plans, members cannot add connectors themselves. Only an **Owner** or the **Primary Owner** can, under **Organization settings → Connectors** (**Add**, then **Custom → Web**, then the URL). Each member then connects and signs in individually under **Customize → Connectors** — there is no org-wide pre-authentication. On a Cloud plan, the directory listing shows members a **Request** button that sends it to those Owners.
Cowork installs the same plugin as Claude chat, and gets the same connection and analysis skills. Follow the plugin steps on the **Claude** tab, with one difference: open the **Cowork** tab first, then **Customize**.
Cowork also shares your Claude account's connectors, so a connector added on claude.ai works here too.
Requires developer mode, available on Plus, Pro, Business, Enterprise, and Education accounts, on the web.
1. On the web app, open **Settings → Security and login** and turn on **Developer mode**
2. Open **Plugins**, click **+**, and create a developer-mode app for a remote MCP server
3. Enter a name (e.g., "Credible") and a description
4. Enter the MCP server URL: `https://mcp.credibledata.com/global/`
5. Leave authentication as **OAuth** and create the connection
6. Complete the OAuth sign-in flow
7. Now you can ask ChatGPT to use the Credible tool (or whatever you named it)
On a Business, Enterprise, or Education workspace, an admin has to allow developer mode first, under **Workspace settings → Permissions & roles → Connected data**. On Business plans a published app cannot be edited afterwards — to change it, recreate and republish.
OpenAI has renamed this surface more than once — developer mode and custom MCP apps have lived under **Apps**, **Apps & Connectors**, and now **Plugins**. If a label here doesn't match what you see, look for the nearest equivalent rather than assuming the feature is gone.
The consumer Gemini web app does not support custom MCP connectors. Use **Gemini Enterprise**, or connect the [Gemini CLI](/docs/how-to/developers/connect-coding-agent) instead.
In Gemini Enterprise, connect Credible as a custom MCP server data store:
1. In the Gemini Enterprise console, go to **Data Stores** → **Create Data Store** and select **Custom MCP Server**
2. Enter the MCP Server URL: `https://mcp.credibledata.com/global/`, along with the OAuth configuration for your organization
3. Attach the data store to your Gemini Enterprise app under **Connected data sources**
4. In the Gemini chat input, open the connector menu, **Authorize** the Credible connector, and toggle it on
Gemini Enterprise requires OAuth client credentials to authorize the connection — [contact support](mailto:support@credibledata.com) and we'll help you get set up.
Connecting your own agent over MCP is not metered: your agent, your tokens. Users, seats, and MCP access are free on every plan — see [pricing](/pricing).
## What Your Agent Can Do
Once connected, your agent has the tools every Credible surface uses — `get_context` to discover governed entities in your models and `execute_query` to run Malloy queries against them, plus `list_workspaces` to see what it can reach, `search_malloy_docs` for language reference, and `get_skill` to read Credible's [open-source skills](/docs/introduction#one-set-of-skills-every-surface) on demand. Those skills encode the discipline to use the tools well: parsing your question into the right search phrases, finding the right sources and views, writing correct Malloy, choosing sensible visualizations, and sanity-checking results before trusting them. In your agent, that means you can:
- **Ask data questions in plain language** — *"What were our top products by revenue last quarter?"* — and get answers grounded in your governed definitions, not guesses
- **Iterate in conversation** — follow up, refine, and drill into drivers, with each query building on the matched entities from the last
- **Analyze alongside your other context** — combine Credible answers with the documents, tools, and conversation already in your agent
- **Stay governed throughout** — every query runs through Credible, ACL'd and audit-logged as you
If your agent has several workspaces to choose from, it will ask which one to work in the first time; tell it once and it remembers.
See the [MCP Tools reference](/docs/how-to/analyzing/ai-assistants-mcp#tool-reference) for tool parameters and details.
---
# Build Data Apps
Source: https://www.credibledata.com/docs/how-to/analyzing/data-apps
**Data apps** are interactive dashboards and applications published as part of a Malloy package — full HTML/JavaScript web apps, shipped as a `public/` directory alongside the models they draw from. No build step, no framework, no separate deployment: publishing the package publishes the app.
Because a data app ships with its package, it inherits everything the package guarantees:
- **Governed** — the app queries the package's own data models, with all [access rules](/docs/how-to/modeling/fine-grained-acls) applied to whoever is viewing it. Two viewers with different permissions see different data in the same app
- **Versioned** — the app is published, promoted, and archived together with the model version it was built against. App and model can never drift apart, so a model change never breaks a running app — the dashboard breakage that plagues traditional BI is eliminated by construction
- **Ready everywhere** — when a package containing a data app is added to a workspace, the app appears automatically in the workspace's **Data Apps** section
## Using Data Apps
Open a workspace that includes the package and its data apps are listed, ready to use — there's nothing to deploy, configure, or sign in to. Credible serves the app to the signed-in user, so authentication is automatic and every query the app runs is governed as that user.
Data apps can also hand off to the in-app agent: a well-built app passes the exact view and queries behind a number along with your question, so you can go from a dashboard tile to *"why is this below target?"* in one click — and the agent starts with the context instead of rediscovering it.
## How a Data App Works
A package becomes a data app by adding a `public/` directory of plain web files:
```
my-package/
├── publisher.json # package manifest
├── orders.malloy # the models — private
└── public/ # the app — this is what's served
├── index.html
└── app.js
```
Only `public/` is served to the browser. The models, data files, and manifest stay private — the app reaches them exclusively through the query API (`Publisher.query(...)`), which runs Malloy against the package's models and applies every filter, access modifier, and authorize rule on the way — the same gateway every other query passes through. The app defines the presentation; the model stays the single source of truth for the numbers.
## Building Data Apps
**The fastest way is to ask the [in-app agent](/docs/how-to/modeling/in-app-development#building-a-data-app)**: describe the charts, filters, and layout you want, and the agent generates the app into your draft package. Its [open-source skills](/docs/introduction#one-set-of-skills-every-surface) encode a production recipe — real field names read from the model (never guessed), every tile handling its own loading and error states, defensible numbers (missing data omitted rather than plotted as zero), and assumptions surfaced in the app itself as captions and footnotes rather than buried.
**With the [developer tools](/docs/how-to/developers/overview)**, your coding agent builds to the same recipe, and you get a live authoring loop: run a local [Malloy Publisher](https://github.com/malloydata/publisher) server and edits to your `public/` files reload the open page instantly, while model edits recompile the package. When it's ready, [publish the package](/docs/how-to/modeling/publishing) — the app ships with it.
For new work, build a data app rather than a `.malloynb` notebook — that's the standard Credible expects going forward. And like everything in the stack, they're built on open source: the same app runs unchanged on a self-hosted Malloy Publisher.
## See Also
- [Analyze Data](/docs/how-to/analyzing/workspaces) — Chat with your data in governed workspaces
- [Build & Publish](/docs/how-to/modeling/in-app-development) — Build models and data apps with the agent
- [Publishing](/docs/how-to/modeling/publishing) — How packages, versions, and serving work
---
# Analyze & Deliver Overview
Source: https://www.credibledata.com/docs/how-to/analyzing/overview
The **Credible AI Analytics Engine** delivers your data *and its meaning* — the definitions, relationships, business rules, and access controls captured in your data models — as context, at query time, to every surface.
You've already built that context. [Publishing](/docs/how-to/modeling/publishing) a model hands it to the engine, which **materializes and indexes** it, then serves it everywhere: one model, every surface, consistent answers.
## Choose Your Surface
Chat with your data in governed workspaces in the Credible App.
Build and use interactive dashboards and applications shipped with your packages.
Connect Claude, ChatGPT, Gemini, or any MCP-compatible chat client to your data models.
Ask data questions from any channel or DM with the `@CredibleData` bot.
Building your own? The developer surfaces — [MCP tools](/docs/how-to/analyzing/ai-assistants-mcp) for custom agents and the [REST APIs](/docs/how-to/integrating/apis) — live in the Developers section.
Every surface runs on the same engine, the same two MCP tools — `get_context` and `execute_query` — and the same [open-source agent skills](/docs/introduction#one-set-of-skills-every-surface) that encode how to use them well. The only difference is where the agent runs: inside Credible, inside your agent, or inside your application.
## How It Works
The engine works in three stages: at publish it **compresses** your models into the concept index; at question time it **retrieves** the slice of the model the question needs; and it **generates** a grounded query.
### Compress
When you publish, the engine compresses your model — the data and its context — into a representation built for serving:
- **It indexes meaning.** Everything your model declares — the sources, dimensions, measures, and views; the business definitions in your `#(doc)` descriptions; and the actual data values of every `#(index)`-tagged dimension — becomes the **concept index**. This is the metadata you added in [Discovery Metadata](/docs/how-to/modeling/metadata-tags).
- **It materializes data.** Every `#@ persist` source is built into a managed physical table, so queries serve from a fast, cheap copy instead of re-scanning your warehouse. This is the optimization you added in [Performance & Cost](/docs/how-to/modeling/persistence).
The engine keeps both fresh automatically, so what's served is always ready — no pipelines to run, no caches to manage.
### Retrieve
When a question comes in, embedding-based semantic search matches it to governed entities **by meaning, not by exact names**. Ask about "soccer games" and the engine finds a program titled "World Cup Finals" through its indexed values and a "Sports" genre through its documentation — no exact string match, no prior knowledge of the schema.
Just as important is what the engine *doesn't* do: it doesn't dump the entire model into every request. It retrieves the context that matches the question's intent, so the agent gets the relevant definitions, relationships, and rules — and nothing to get lost in.
### Generate
The engine returns more than matches: it suggests a Malloy query addressing the question, built from governed views and matched entities. From there the agent does the querying — running, refining, and building on that grounded starting point as the conversation develops, guided by Credible's [open-source agent skills](/docs/introduction#one-set-of-skills-every-surface).
## Why Retrieval-First?
This design mirrors how people actually approach data. A business user rarely arrives with a query in hand — they have a **goal** ("understand customer churn"), a **question** ("why did revenue drop?"), or a **hunch** ("I think returns are up"). The traditional path forces them to learn the schema first; the AI Analytics Engine inverts it:
1. **Understand the question** — interpret what the user is trying to learn
2. **Discover relevant data** — find governed entities that can help, even with imprecise terminology
3. **Suggest an approach** — give the agent a starting query, not a blank page
4. **Iterate naturally** — follow up, refine, and explore in conversation, letting each answer and the model's related dimensions suggest where to look next
The result is trustworthy by construction: every answer is grounded in your governed definitions, your [access rules](/docs/how-to/modeling/fine-grained-acls) are enforced on every query, and the retrieval itself is inspectable — `get_context` shows exactly which entities matched and why.
## Optimizing for Retrieval
Beyond trust, a retrieval-based architecture has two big advantages:
1. **It's token-efficient.** The agent receives the context that matches the question — not the whole model — so answers are faster, cheaper, and don't degrade as your models grow.
2. **It's measurable.** You optimize what you measure — and you can't optimize what you can't measure. Retrieval quality is directly measurable, and data model quality with it: every question is a test of whether the model surfaced the right entities.
That measurability makes quality a feedback loop, not a one-way pipe. When the agent can't find something or matches the wrong field, the miss is a signal — add or refine the `#(doc)` and `#(index)` tags, republish, and every surface improves at once. And you're not on your own: Credible's [open-source skills](/docs/introduction#one-set-of-skills-every-surface) and our forward deployed engineers help you measure and optimize your models as your business and data evolve.
See [Discovery Metadata](/docs/how-to/modeling/metadata-tags) for the full guide to documenting and indexing your models.
---
# Connect with Slack
Source: https://www.credibledata.com/docs/how-to/analyzing/slack-integration
Bring the Credible bot into your Slack workspace: the same agent, the same [AI Analytics Engine](/docs/how-to/analyzing/overview) and tools, and the same [open-source skills](/docs/introduction#one-set-of-skills-every-surface) that power [workspace chat](/docs/how-to/analyzing/workspaces) — answering your team's data questions in any channel or DM. Mention `@CredibleData` and you get the same governed, trustworthy analysis, without leaving Slack. Every conversation is stored as a workspace chat you can revisit at `.app.credibledata.com`.
## Setup
### 1. Connect Slack (Admin)
1. Navigate to **Organization Settings** in the Credible App
2. Click **Connect** under the Slack section
3. Complete the Slack OAuth flow to authorize `@CredibleData` for your Slack workspace
### 2. Add the Bot to a Channel
Add `@CredibleData` to any Slack channel where your team wants to ask data questions.
### 3. Link Your Account
The first time you mention `@CredibleData`, you'll be prompted to link your Credible account to your Slack identity. This is a one-time step — you must be a member of the organization and the workspace configured for that channel.
### 4. Set a Workspace for the Channel
Each channel is tied to a single Credible workspace. Configure it with slash commands:
1. Run `/credible_list` to see available shared workspaces
2. Run `/credible_set_workspace ` to set the workspace for this channel
## Usage
Mention `@CredibleData` in a channel to start a conversation:
```
@CredibleData What were our top 10 products by revenue last quarter?
```
- The bot responds **in a thread**. Inside that thread, you can continue chatting without mentioning `@CredibleData` again.
- Each response includes a **link to the chat** in the Credible App, where you can view full results, visualizations, and continue the analysis.
- Every conversation is saved as a **workspace chat** (scoped to the channel's configured workspace) visible to workspace members in the Credible App.
### Direct Messages
DM `@CredibleData` to start a private conversation. DM chats are stored in your **personal workspace**.
**Slack visibility rules apply.** Anyone in a Slack channel can see bot responses, even if they don't have a Credible account. They won't be able to query the bot themselves, but they will see answers posted in the channel. Your Slack organization's access and retention policies govern this content.
## See Also
- [Analyze Data](/docs/how-to/analyzing/workspaces) — Chat with data in the web app
- [Connect your Agent](/docs/how-to/analyzing/connect-your-llm) — Connect Claude, ChatGPT, or other LLMs to your data
- [AI Analytics Engine Overview](/docs/how-to/analyzing/overview#how-it-works) — How phrase-matching and entity retrieval work
---
# Analyze Data
Source: https://www.credibledata.com/docs/how-to/analyzing/workspaces
The Credible App (`https://.app.credibledata.com`) is one way your team can consume published data models. In the Credible App, work happens inside a **workspace** — your personal workspace, or a shared workspace scoped to a set of packages and team members (see [Creating a Workspace](#creating-a-workspace) below).
 ## Chat
Type a question in the chat bar at the top of any workspace. The agent parses your question and uses the [Credible AI Analytics Engine](/docs/how-to/analyzing/overview#how-it-works) to search your published data models — matching phrases to governed entities (dimensions, measures, views) and indexed dimension values via their `#(doc)` and `#(index)` annotations — then constructs and executes a trustworthy Malloy query against your data.
Each chat is saved in the workspace and visible to all members — find previous conversations under **Conversations**.
### How It Works
1. **`get_context`** — The agent parses your question into semantic phrases and calls `get_context` to search your published data models and indexed dimension values, getting back matched data entities. Match quality depends on the `#(doc)` descriptions and `#(index)` annotations in your model.
2. **`execute_query`** — The agent constructs and runs a Malloy query using the matched entities, returning results and visualizations.
This is what makes answers trustworthy — the agent is grounded in governed definitions, not guessing column names or interpreting ambiguous schemas. And how it analyzes — the query patterns and the rigor — comes from Credible's [open-source agent skills](/docs/introduction#one-set-of-skills-every-surface): the same skills every Credible surface runs, curated in the open with the world's data experts.
Published models must be [indexed](/docs/how-to/modeling/publishing#what-happens-when-you-publish) before chat works. Check that the package version shows **Ready** on its package page.
## Creating a Workspace
Personal workspaces are included in every plan. **Shared workspaces** — analysis, apps, and dashboards in one governed home for a team — are part of the [Enterprise plan](/pricing). Questions asked of the in-app agent meter in tokens, at the rates on the [pricing page](/pricing).
Click **+ New Workspace** in the left sidebar of the Credible App. The creation wizard has three steps:
1. **General** — Name your workspace and add an optional description. Choose a name that reflects the team or use case (e.g., "Ecommerce Analysis", "Marketing Metrics")
2. **Members** — Add users or groups, each with a role: **Manager** (full control over workspace settings, members, and packages) or **Member** (can view models, create chats, and create reports)
3. **Packages** — Add the published data model packages you want available in this workspace. Only packages shared with members (via [environment permissions](/docs/platform-admin/permissions#sharing-environments--packages)) can be added
Workspace managers can update settings at any time — add or remove members, change roles, add or remove packages, or delete the workspace. Navigate to your workspace and click **Settings**.
## See Also
- [Build Data Apps](/docs/how-to/analyzing/data-apps) — Build and use interactive dashboards and applications shipped with your packages
- [Build & Publish](/docs/how-to/modeling/in-app-development) — Build and publish a model with the agent, then chat with it
- [AI Analytics Engine Overview](/docs/how-to/analyzing/overview#how-it-works) — How phrase-matching and entity retrieval work
- [Connect your Agent](/docs/how-to/analyzing/connect-your-llm) — Chat with the same models from Claude, ChatGPT, Gemini, or any MCP client
- [MCP Tools](/docs/how-to/analyzing/ai-assistants-mcp) — Technical details on `get_context` and `execute_query` for custom agents
- [Permissions](/docs/platform-admin/permissions) — Sharing workspaces and documents, and the full permission model
---
# Connect your Coding Agent
Source: https://www.credibledata.com/docs/how-to/developers/connect-coding-agent
The [modeling MCP tools](/docs/how-to/developers/vscode-extension#modeling-mcp-tools) are for *building* models. To let your coding agent *analyze data* with your published models — the same governed access as [workspace chat](/docs/how-to/analyzing/workspaces) — connect it to the **consumption MCP server** and authenticate with OAuth.
Use the Credible MCP server URL: `https://mcp.credibledata.com/global/`
One URL covers every organization and workspace your account can reach; the server resolves scope from who you signed in as. To narrow an agent to one organization or one workspace, open **Connect AI** in the Credible app (settings gear in the sidebar, then **Connect AI**), pick the narrower scope under **Access**, and follow the steps it shows — they carry the scoped URL (see [MCP Tools](/docs/how-to/analyzing/ai-assistants-mcp#the-mcp-server) for the endpoint shapes). Every client below takes the same URL — only the syntax changes.
Building models rather than querying them? The [VS Code Extension](/docs/how-to/developers/vscode-extension) writes the modeling MCP config and skills for you in VS Code, Cursor, and Claude Code — no URL to paste. Connecting a personal chat client like Claude, ChatGPT, or Gemini? See [Connect your Agent](/docs/how-to/analyzing/connect-your-llm).
The Credible plugin installs the connection **and** the analysis skills that teach Claude how to use it. These are slash commands — type them **inside a Claude Code session**:
```bash
/plugin marketplace add anthropics/claude-plugins-community
/plugin install credible@claude-community
```
Then run `/mcp` and sign in to Credible.
Anthropic's community marketplace is not pre-added — only the official one is — so the first command is required, not optional.
For the connection without the skills — this one is a shell command, run in your terminal rather than inside a session:
```bash
claude mcp add --transport http credible https://mcp.credibledata.com/global/
```
Run these in your terminal **before you start Codex**. They write to Codex's config, and a session that is already running won't pick the server up until it restarts:
```bash
codex mcp add credible --url https://mcp.credibledata.com/global/
codex mcp login credible
```
Both write to `~/.codex/config.toml`, which you can edit directly instead:
```toml
[mcp_servers.credible]
url = "https://mcp.credibledata.com/global/"
auth = "oauth"
```
Remote servers are first-class in current Codex. Older builds read only stdio servers and skip this one without saying so — if nothing shows up, upgrade Codex, or add this above the server entry:
```toml
[features]
experimental_use_rmcp_client = true
```
In the Codex IDE extension or app there is no terminal step: **Settings → MCP servers → Add server → Streamable HTTP**, paste the URL, save, then **Authenticate**.
1. Press `Cmd+Shift+P` (`Ctrl+Shift+P` on Windows/Linux) and run **"Open MCP Settings"**
2. Click **Add MCP Server**
3. Add the configuration:
```json
{
"mcpServers": {
"credible": {
"url": "https://mcp.credibledata.com/global/"
}
}
}
```
4. Save — Cursor opens the OAuth flow; complete it in your browser
Cursor marks a server as remote by the presence of `url`, so there is no `type` key here. Put the config in `.cursor/mcp.json` for one project, or `~/.cursor/mcp.json` for every project.
1. Open the Command Palette (`Cmd+Shift+P` on Mac, `Ctrl+Shift+P` on Windows/Linux) and run **"MCP: Add Server"**
2. Select **HTTP**
3. Enter the MCP URL: `https://mcp.credibledata.com/global/`
4. Enter a server ID (e.g., "credible")
5. Press Enter and select "Global" or "Workspace" scoped
6. A popup redirects you to the OAuth flow — open it in your browser and complete the authentication
7. The server now shows as "Running" (with a checkbox) in the `mcp.json` file
8. Open Copilot to test it out
To write the config by hand, use `.vscode/mcp.json` for one workspace, or run **"MCP: Open User Configuration"** for every workspace:
```json
{
"servers": {
"credible": {
"type": "http",
"url": "https://mcp.credibledata.com/global/"
}
}
}
```
Add the server to `opencode.json`:
```json
{
"$schema": "https://opencode.ai/config.json",
"mcp": {
"credible": {
"type": "remote",
"url": "https://mcp.credibledata.com/global/",
"enabled": true
}
}
}
```
opencode starts the sign-in flow itself the first time the server answers with a 401, and keeps the tokens for later sessions.
Install the CLI, add the server, then start `gemini` — it opens a browser window for sign-in:
```bash
npm install -g @google/gemini-cli
gemini mcp add -t http credible https://mcp.credibledata.com/global/
gemini
```
`gemini mcp list` confirms the server is connected.
1. In the agent window, click on the plug icon
2. Click **Settings** — this opens `~/.codeium/windsurf/mcp_config.json`, which you can also create and edit directly
3. Add your server configuration:
```json
{
"mcpServers": {
"credible": {
"serverUrl": "https://mcp.credibledata.com/global/"
}
}
}
```
4. Save the file — this automatically opens the OAuth authentication flow
5. Complete the authentication in your browser
Any other MCP client works the same way: Credible is a remote MCP server over Streamable HTTP, and sign-in is OAuth with dynamic client registration — the client registers itself, so there is no key to copy and no client ID to configure.
Once connected, your agent has `get_context` and `execute_query` — the same tools that power workspace chat — plus `list_workspaces`, `search_malloy_docs`, and `get_skill`. See the [MCP Tools reference](/docs/how-to/analyzing/ai-assistants-mcp#tool-reference) for what each one takes.
## Next Steps
The tool reference — which tools each endpoint exposes and how to call them
Better answers start in the model — add doc and index annotations
---
# Embedded Data
Source: https://www.credibledata.com/docs/how-to/developers/embedded-data
You can include CSV, Parquet, or Excel (`.xlsx`) files directly in your packages. When you publish your package, these data files are published along with your models and become queryable via DuckDB.
Embed data files when you need to:
- **Package sample data** — Example datasets for testing or demos
- **Build standalone models** — Models that don't require database connections
- **Version control data** — Keep data synchronized with model changes in your package
Embedded files are read by the package's own DuckDB sandbox, which makes them the right fit for standalone models, sample data, and small lookup tables. To query files alongside a database — Parquet in a bucket joined to Postgres, say — put the files in object storage and use a [DuckDB connection](/docs/how-to/modeling/connect-data) with attached databases instead.
## File Structure
Create a `data/` folder in your package directory and add your files — CSV (`.csv`, with a header row), Parquet (`.parquet`, more efficient for larger datasets), or Excel (`.xlsx`):
```
my-package/
├── publisher.json
├── ecommerce.malloy
└── data/
├── country_codes.csv
├── product_categories.parquet
└── exchange_rates.csv
```
## Referencing Embedded Data in Models
Use `duckdb.table()` to reference embedded files in your Malloy models — the same syntax works for CSV and Parquet:
```malloy
source: country_codes is duckdb.table('data/country_codes.csv') extend {
dimension:
country_code is code
country_name is name
region is geographic_region
}
```
## Next Steps
Publish your package — embedded data ships with it
Build data models on top of your embedded data
---
# Developer Overview
Source: https://www.credibledata.com/docs/how-to/developers/overview
Developers want to work locally — in their own editor, with their own coding agent, on files they control. Data models are [Malloy](https://malloydata.dev) code in plain files: edit them in your IDE, version them in Git, review them in pull requests, and publish from your terminal or [CI/CD](/docs/platform-admin/cicd). Your existing Git and review workflow stays as it is.
Your local agent runs on the **same foundation as every other Credible surface** — the same governed models, the same MCP (Model Context Protocol) tools, the same [open-source skills](/docs/introduction#one-set-of-skills-every-surface). Managed connections mean no credentials ever land on your machine.
**Prefer zero setup?** You can also [build in the app](/docs/how-to/modeling/in-app-development) — entirely in your browser, no IDE required. Start there if you want no setup; work locally if you want Git-based workflows and direct control over files. Both produce the same governed packages.
## The Local Workflow
Local development with Credible looks like development anywhere else:
1. **Set up your IDE** — Install the [VS Code Extension](/docs/how-to/developers/vscode-extension) (works in VS Code and Cursor, with Claude Code picking up the same workspace config). It equips your agent with managed connections, modeling MCP tools, and modeling skills — the same open tools and skills [Malloy Publisher](https://github.com/malloydata/publisher) provides.
2. **Build in files you own** — Your agent discovers your data and drafts `.malloy` models right in your workspace. Edit, refactor, and iterate like any other code.
3. **Version and review in Git** — Commit models alongside the rest of your codebase; review changes in pull requests.
4. **Publish from anywhere** — From your IDE agent, the [CLI](/docs/platform-admin/cli), or automatically on merge with [CI/CD](/docs/platform-admin/cicd).
## Built on Open Source
The stack you're building on is not a black box. Credible contributed its MCP tools and agent skills to [Malloy Publisher](https://github.com/malloydata/publisher), the open-source server for Malloy models: retrieval tools that let an agent look up what your model actually defines, and skills encoding the discipline to use them well — query patterns, gotchas that trip up frontier models, and the rigor that separates a real answer from a plausible one. These are the **same skills the in-app agent runs**, so how your agent models and analyzes is identical in the app and in your IDE. And because they're open, anyone can contribute to them — read them, fork them, or extend them with your organization's institutional knowledge. Read the full story in [We Open Sourced the Thing Everyone Else Is Selling](https://credibledata.com/blog/posts/open-sourcing-skills).
## Set Up Your Tools
Build models in VS Code, Cursor, or Claude Code — managed connections, modeling MCP tools, and skills, no credentials on your machine
Let any coding agent analyze data with your published models — the same governed access as workspace chat
Propose, review, and publish model changes as a team — everyone contributes in plain language, with an engineer's review when you want one
Ship CSV and Parquet files inside your packages for standalone, versioned models
Everything the Credible App manages, scriptable from your terminal
## Automate and Integrate
Version models in Git and publish automatically on merge
Build on the REST APIs
Give your own agents and applications governed access via MCP
---
# VS Code Extension
Source: https://www.credibledata.com/docs/how-to/developers/vscode-extension
Credible ships a **VS Code extension** that works in both **VS Code** and **Cursor**. It connects your IDE to Credible, equipping your coding agent with the same governed models, MCP (Model Context Protocol) tools, and [open-source skills](/docs/introduction#one-set-of-skills-every-surface) as every other Credible surface.
The steps below use Cursor as the example, but the same workflow applies to VS Code — and to **Claude Code** running in a workspace the extension has configured.
## Prerequisites
- **Cursor**, **VS Code**, or **VS Code with Claude Code** installed (latest version recommended)
- **Credible organization** set up by an admin
- **Database connections configured** by your admin — see [Connect a Database](/docs/how-to/modeling/connect-data)
## What the Credible Extension Provides
The Credible Extension configures your IDE workspace with everything the agent needs for data modeling:
- **Modeling MCP tools** — A set of MCP tools built specifically for modeling: the agent can discover tables in your warehouse, suggest modeling approaches, and look up Malloy syntax — the same open tools [Malloy Publisher](https://github.com/malloydata/publisher) provides
- **Modeling skills** — Slash commands (e.g., `/malloy-model`, `/malloy-discover`, `/credible-publish`) that guide the agent through common workflows. These are Credible's [open-source skills](/docs/introduction#one-set-of-skills-every-surface) — the same playbooks the in-app agent runs. The agent uses them automatically based on context
- **Managed database connections** — Access connections configured in the Credible App without storing credentials locally
- **Credible Service Panel** — Browse your environment and its managed connections, down to individual schemas and tables
Installing the Credible Extension also installs the [Malloy extension](https://docs.malloydata.dev/documentation/setup/extension), which provides:
- **Syntax highlighting & compilation checks** for `.malloy`, `.malloynb`, and `.malloysql` files
- **Schema | Explore | Preview buttons** above any source definition
- **Run | Show SQL buttons** above any query or run statement
## Installation
### Install the Credible Extension & Sign In
1. In Cursor or VS Code, go to the Extensions view (`Cmd+Shift+X` on Mac, `Ctrl+Shift+X` on Windows/Linux), search for **Credible**, and install the extension — select **Auto Update** when prompted
2. Open the Explorer (`Cmd+Shift+E` on Mac, `Ctrl+Shift+E` on Windows/Linux), expand the **Credible** panel at the bottom of the sidebar, and click **Sign In** — then follow the steps in your browser
3. Back in your IDE, select your organization from the list (if you only belong to one, it's selected automatically), then select your environment
### Modeling MCP Tools
The extension registers these tools automatically as an environment-scoped **Credible-Modeling** MCP server — no manual enabling required. In Cursor, the extension registers the server programmatically; in VS Code, it writes a workspace-scoped `.vscode/mcp.json` config.
To verify, open Cursor Settings (`Cmd+Shift+J` on Mac, `Ctrl+Shift+J` on Windows/Linux) → **Tools & MCP**. The server appears as **extension-Credible-Modeling** — Cursor uses this naming convention to indicate it was registered by an extension.
To verify, open the Command Palette (`Cmd+Shift+P` on Mac, `Ctrl+Shift+P` on Windows/Linux) and run **"MCP: List Servers"** — you should see **Credible-Modeling** in the list.
When you start Claude Code in your workspace, you'll be prompted to allow Claude Code to run in the directory and to accept the **Credible-Modeling** MCP server. Accept both. Use `/mcp` at any time to view and manage your MCP servers.
Every time you change environments, the extension updates the MCP config automatically. If the agent can't call MCP tools, reload the window (`Cmd+Shift+P` → "Reload Window").
## Credible Service Panel
The **Credible Service Panel** shows your current environment and its connections. Find it at the bottom of the Explorer view (`Cmd+Shift+E` on Mac, `Ctrl+Shift+E` on Windows/Linux):
The Credible Service Panel is part of the IDE extension, so it's available in Cursor and VS Code only. If you use Claude Code from the terminal, manage your environment with the [CLI](/docs/platform-admin/cli) or the Credible App instead.
 Here you can view:
- **Your current environment** — click it to switch environments
- **Connections** — the managed database connections in the environment; expand one to browse its schemas and tables
The extension discovers these connections from your environment; the credentials stay in Credible.
The sidebar may be hidden by default in Cursor:
1. Open the **Explorer** panel (`Cmd+Shift+E` on Mac, `Ctrl+Shift+E` on Windows/Linux)
2. Look for the **Credible** panel at the bottom of the explorer sidebar
The Credible Extension can be configured via the Command Palette (`Cmd+Shift+P`) or clicking icons in the Credible Service Panel:
- **Disable Credible**: Turn off the extension for this workspace
- **Refresh**: Reload your environment and its connections
- **Select Organization**: Choose from your available organizations (auto-selects if you only belong to one)
- **Sign Out**: Log out of Credible
## Next Steps
Your environment is ready — start building data models with your agent
Let your agent analyze data with your published models
---
# API Access
Source: https://www.credibledata.com/docs/how-to/integrating/apis
Build programmatically on your data models with the REST APIs — the same governed models that power workspaces, agents, and data apps, with the same access rules enforced on every request. Sign in as yourself with a **Bearer token**, or — for anything running server-to-server, like custom applications, scripts, and integrations — use an **API key** scoped to a group. The key acts with the group's permissions, so you can adjust what it can access at any time without regenerating it.
Looking to embed interactive analytics in a product? Build a **data app** — a full HTML/JavaScript application shipped with your package and served by Credible. See [Build Data Apps](/docs/how-to/analyzing/data-apps) for how they're built and used.
## The REST APIs
Credible splits its REST surface three ways, matching the [architecture](/docs/concepts/architecture): the **Admin API** manages organizations and their resources, the **Data API** runs queries, and the **Retrieval API** searches your models. Admin traffic and query traffic run on separate planes, so a busy admin job never slows a query. All three enter through the same gateway, where access rules are checked and every request is logged.
Manage organizations, environments, packages, connections, and permissions
Query data models programmatically and retrieve results
Search data model context — the same retrieval that powers the [AI Analytics Engine](/docs/how-to/analyzing/overview)
## Authentication
Every request to the REST APIs carries an `Authorization` header, and Credible accepts two schemes:
| Scheme | Header | Acts as | Best for |
|--------|--------|---------|----------|
| **Bearer token** | `Authorization: Bearer ` | The signed-in user | Interactive use, testing, scripts run by a person |
| **API key** | `Authorization: ApiKey ` | A group | Server-to-server: applications, services, CI/CD |
### Bearer Tokens (User Auth)
Credible's APIs are a standard OAuth resource server: they accept access tokens issued by Credible's identity provider (Auth0) through your organization's SSO. When you sign in — in the browser or via the CLI's device flow — you get a short-lived access token, and every request made with it acts with **your** permissions, enforced by the same access rules as every other surface.
The easiest way to get a token is the CLI:
```bash
cred login
```
After login, the CLI stores your tokens in `~/.cred` and uses them for every command. For quick API testing, you can pass the same access token directly:
```bash
curl -H "Authorization: Bearer " \
https://.data.credibledata.com/api/v0/environments
```
Bearer tokens expire and are refreshed through the OAuth flow, so they're the right fit for interactive use — for anything long-running or unattended, use an API key instead.
## Create an API Key
### 1. Create a Group
Navigate to `.app.credibledata.com`:
1. Click **Users & Groups** in the bottom left of the sidebar
2. Switch to the **Groups** tab
3. Click **+ Create Group** and name your group (e.g., `ai_agents_group`)
### 2. Grant Environment Access
Navigate to the environment you want this group to access:
1. Click **Permissions** on the environment page
2. Add your group and select the appropriate role
3. Verify the group appears in the permissions list
### 3. Generate the Key (CLI)
Install the [Credible CLI](/docs/platform-admin/cli), authenticate, and generate an API key for your group:
```bash
# Install the CLI globally
npm i -g @credibledata/cred-cli
# Login to your organization
cred login
# Create a group access token
cred add group-access-token
```
The final command outputs the API key. Store it securely in your application's credential storage or environment variables — all requests made with it act with the permissions of the group.
## Using the Key
Pass the key in the Authorization header on every request:
```
Authorization: ApiKey your-api-key
```
This works across Credible's programmatic surfaces: the REST APIs above, and the [MCP server](/docs/how-to/analyzing/ai-assistants-mcp#connecting-custom-agents) for custom agents.
## Tenant Isolation for Embedded Products
When your product queries Credible on behalf of your customers, tenant isolation is declared in the model and enforced at the gateway — not reimplemented in application code. The pieces are the ones above:
1. **Declare the given in the model.** A [secure given](/docs/how-to/modeling/fine-grained-acls#row-scope-secure-givens) such as `#(secure) ALLOWED_TENANTS :: string[]`, with a `where:` or `#(authorize)` that reads it, scopes every query on the source tenant by tenant.
2. **Give each tenant a group and a key.** An API key acts as its group, so create one group per tenant (or per plan tier) and generate its key. Requests made with the key resolve secure givens from the group — the caller's verified identity, for a server-to-server caller.
3. **Grant the tenant's values.** On the [Access Control page](/docs/platform-admin/permissions#access-control), grant the group the tenant IDs it may see.
From then on every query that arrives with that key — through the Data API, the Retrieval API, or MCP — is scoped to that tenant before it runs, and logged with the group that made it. Your application never handles a tenant filter, and a bug in the app cannot widen what a customer sees. For interactive analytics inside your product, ship a [data app](/docs/how-to/analyzing/data-apps): it queries through the same gateway, so a customer who opens it sees only their rows.
Have an authentication requirement this doesn't cover? [Email us](mailto:support@credibledata.com).
---
# Migrate from Cube
Source: https://www.credibledata.com/docs/how-to/migrating/cube
Cube and Credible share a worldview: a governed model of measures, dimensions, and joins over your warehouse, queried by intent rather than raw SQL. That makes migration clean — Credible reads your Cube data model and rebuilds it as Malloy, keeping the semantics and shedding the engine-specific tuning.
Still weighing the move? [Credible vs. Cube](/compare/cube) sets the two side by side.
## What Credible Reads
Your Cube **data model** — cubes and views authored in YAML or JavaScript. Point the agent at those files and it has everything it needs to translate. Connecting Cube's **MCP server** (hosted per tenant over OAuth) or its SQL/REST/GraphQL APIs is optional: it lets the agent read the governed catalog directly and validate results against the live model.
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In Cube | In Credible |
|---|---|
| Cubes & views | Malloy **sources** (base + curated); `import`/`export` and `explores` govern exposure |
| Dimensions, measures, segments | Carried over — measures, dimensions, and reusable `where:` filters |
| Pre-aggregations | Not carried over — declare [`#@ preaggregate`](/docs/how-to/modeling/persistence) on the hot measures in the converted model instead |
| Data access policies / member security | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| `title` / `description` | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Dashboards built on Cube | Rebuilt as [data apps](/docs/how-to/analyzing/data-apps) or [notebooks](/docs/how-to/analyzing/workspaces) |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the model, translates cubes to base sources and views to curated sources, enriches each field with `#(doc)`/`#(index)` tags, and — where you connect it — validates row-by-row against Cube's **SQL API**.
## What Credible Handles
- **Pre-aggregations** accelerate Cube's query engine but carry no semantics, so they aren't converted — parity is checked against raw data (a stale pre-agg can differ from the source of truth). Once the model is converted, get the same acceleration by declaring [`#@ preaggregate`](/docs/how-to/modeling/persistence#pre-aggregations) on the hot measures: Credible builds and refreshes the rollup, and routes coarse-grain queries to it without the query naming it.
- **JavaScript-defined models** — dynamic cubes and templated generation are read through Cube's SQL/REST metadata rather than static file parsing.
- **Data access policies** (member-level security, `queryRewrite`) map to Malloy [access control](/docs/how-to/modeling/fine-grained-acls) rather than a 1:1 mechanism.
## Before & After
```yaml
cubes:
- name: orders
sql_table: sales.orders
description: All customer orders
joins:
- name: customers
relationship: many_to_one
sql: "{CUBE.customer_id} = {customers.customer_id}"
dimensions:
- name: order_id
sql: order_id
type: number
primary_key: true
- name: status
description: Current fulfillment status of the order
sql: order_status
type: string
measures:
- name: total_revenue
description: Total revenue in USD
sql: amount
type: sum
format: currency
- name: cancelled_orders
type: count
filters:
- sql: "{CUBE}.status = 'cancelled'"
- name: cancellation_rate
sql: "1.0 * {cancelled_orders} / NULLIF({count}, 0) * 100"
type: number
format: percent
pre_aggregations: # dropped — engine acceleration
- name: orders_rollup
measures: [count, total_revenue]
time_dimension: created_at
granularity: day
```
```malloy
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers is conn.table('sales.customers') on customer_id
dimension:
#(doc) Current fulfillment status of the order
#(index)
status is order_status
measure:
#(doc) Number of orders
order_count is count()
#(doc) Total revenue in USD
# currency
total_revenue is sum(amount)
#(doc) Orders that were cancelled
cancelled_orders is count() { where: status = 'cancelled' }
#(doc) Percentage of orders that were cancelled
# percent
cancellation_rate is cancelled_orders / order_count * 100
view:
#(doc) Daily orders and revenue trend
daily_orders is {
group_by: created_at.day
aggregate: order_count, total_revenue
}
}
```
**More than a reformat.** The model queries live data by default, with rollups you opt into per measure, is AI-discoverable through the [AI Analytics Engine](/docs/how-to/analyzing/overview), and serves agents, apps, and BI — not just Cube's APIs. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Package and publish your migrated model
---
# Migrate from Databricks Metric Views
Source: https://www.credibledata.com/docs/how-to/migrating/databricks
Databricks metric views define governed measures and dimensions over your Delta tables in Unity Catalog. Credible reads that definition, rebuilds it as Malloy, and — where you connect the workspace — validates each measure with the same `MEASURE()` queries you'd run in Databricks.
## What Credible Reads
Your **Unity Catalog metric views** — YAML definitions with a `source`, `dimensions`, `measures`, `joins`, and an optional top-level `filter`. The agent works from that YAML. Connecting to the workspace is optional but the natural way to fetch and validate it: pull the definition with `DESCRIBE TABLE EXTENDED AS JSON`, discover views through Unity Catalog's `information_schema`, or read through a Genie / AI-BI space where one is configured (measures are read only through the `MEASURE()` function).
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In Databricks | In Credible |
|---|---|
| Metric view (source, dimensions, measures, joins) | Malloy **sources**, dimensions, measures, and joins |
| `MEASURE()`-only aggregates | Regular measures you query directly and join natively — no `MEASURE()` wrapper or CTE-to-join workaround |
| Top-level `filter` | Source-level `where:` |
| Unity Catalog grants / row filters / masks | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| Descriptions | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Genie / AI-BI, dashboards | Every surface — agents over MCP, [data apps](/docs/how-to/analyzing/data-apps), [notebooks](/docs/how-to/analyzing/workspaces), dashboards, APIs |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the metric-view YAML, translates the source, joins, dimensions, and measures to Malloy, enriches with `#(doc)`/`#(index)` tags, and — where the workspace is connected — validates row-by-row with `SELECT , MEASURE() … GROUP BY ALL`.
## What Credible Handles
- **`MEASURE()`-only access** — metric-view measures can't be read as plain columns, so Credible mirrors each aggregate expression, preserving semi-additive behavior instead of blindly re-aggregating.
- **Unity Catalog governance** — grants, row filters, and column masks live in Unity Catalog and do **not** travel with the YAML. Credible re-establishes equivalent controls as [`#(authorize)` rules in the model](/docs/how-to/modeling/fine-grained-acls), enforced at the gateway, rather than pretending they came along.
- **Upstream joins** — because joining a metric view to other tables requires wrapping it in a CTE, those joins are modeled explicitly as Malloy sources and joins.
Databricks metric views are a recent Unity Catalog feature and the YAML spec is still evolving. Credible reads the current `version:` from each definition; confirm the spec version in your workspace when you migrate.
## Before & After
A Unity Catalog metric view:
```yaml
version: 1.1
source: samples.sales.orders
comment: "Order metrics with customer attributes"
filter: o_orderdate >= '2024-01-01'
joins:
- name: customer
source: samples.sales.customer
on: source.customer_id = customer.customer_id
cardinality: many_to_one
dimensions:
- name: Order Status
expr: order_status
- name: Order Month
expr: DATE_TRUNC('MONTH', o_orderdate)
measures:
- name: Total Revenue
expr: SUM(amount)
format: { type: currency }
- name: Completed Revenue
expr: SUM(CASE WHEN order_status = 'completed' THEN amount END)
- name: Avg Order Value
expr: SUM(amount) / NULLIF(COUNT(1), 0)
```
```malloy
source: orders is conn.table('samples.sales.orders') extend {
primary_key: order_id
join_one: customer is conn.table('samples.sales.customer') on customer_id
where: o_orderdate >= @2024-01-01
dimension:
#(doc) Order status
#(index)
status is order_status
#(doc) Customer segment
#(index)
customer_segment is customer.segment
measure:
#(doc) Total revenue in USD
# currency
total_revenue is sum(amount)
#(doc) Revenue from completed orders
# currency
completed_revenue is sum(amount) { where: status = 'completed' }
#(doc) Number of orders
order_count is count()
#(doc) Average order value
# currency
avg_order_value is total_revenue / order_count
view:
#(doc) Revenue by month
revenue_by_month is {
group_by: o_orderdate.month
aggregate: total_revenue
}
}
```
The top-level `filter` becomes a source-level `where:`, aggregate expressions become measures (a `SUM(CASE WHEN …)` becomes a clean `{ where: … }` filter), and `format` maps to render tags. Governance stays behind in Unity Catalog and is re-created in Credible.
**More than a reformat.** The model is AI-discoverable through the [AI Analytics Engine](/docs/how-to/analyzing/overview) and composes into follow-up questions your `MEASURE()`-bound metric views couldn't express. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Re-establish Unity Catalog governance in Credible
---
# Migrate from dbt Semantic Layer
Source: https://www.credibledata.com/docs/how-to/migrating/dbt
The dbt Semantic Layer already expresses your business in entities, dimensions, measures, and metrics — which maps unusually cleanly onto Malloy. Credible reads your MetricFlow definitions, flattens the measure/metric split into Malloy measures, and — where you connect it — validates each metric against the Semantic Layer's own query engine.
Still weighing the move? [Credible vs. dbt](/compare/dbt) sets the two side by side.
You don't have to move your transformations to start. The on-ramp is a governed model over the marts dbt already builds — your descriptions and tests read as prior art, and your project is the input, not a rewrite. Transformations can move into the model later, where a [`#@ persist`](/docs/how-to/modeling/persistence) annotation replaces a model file, its config, and the orchestration run.
## What Credible Reads
Your **semantic models** (`semantic_models:` YAML — entities, dimensions, measures) and **metrics** (`metrics:` YAML — simple, ratio, derived, cumulative). The agent parses that project YAML directly — the fullest-fidelity input, since the YAML carries `expr`, `filter`, and `agg_time_dimension` details the compiled APIs abstract away. Connecting the official **dbt MCP server** (`get_metrics`, `get_dimensions`, `get_entities`, `execute_sql`) or the **Semantic Layer APIs** (GraphQL / JDBC / Python) is optional and adds live metric validation.
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In dbt | In Credible |
|---|---|
| Semantic models (entities, dimensions, measures) | Malloy **sources**, joins, dimensions, and measures |
| Metrics (simple / ratio / derived) | Measures — no separate measure-vs-metric layer to maintain |
| Cumulative metrics & `metric_time` | Rebuilt as window views over explicit date fields |
| Metric descriptions | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Governance (none field-level today) | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| Semantic Layer API consumers | Directly queryable on every surface — agents over MCP, [data apps](/docs/how-to/analyzing/data-apps), [notebooks](/docs/how-to/analyzing/workspaces), dashboards, APIs |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the semantic models and metrics, translates entities to keys/joins and measures/metrics to Malloy measures, enriches with `#(doc)`/`#(index)` tags, and — where you connect it — validates by querying each metric through the Semantic Layer API at the same grain and diffing the results. MetricFlow owns SQL generation, so its result is the number to match.
## What Credible Handles
- **The measure/metric split** flattens into one set of Malloy measures. A `simple` metric is often just a rename of its measure — Credible won't create two Malloy fields where one belongs.
- **`metric_time` and the time spine** have no Malloy equivalent. Credible chooses the concrete date field per view and truncates with `.month`/`.day`; cumulative metrics are rebuilt as view-level window calculations.
- **Derived and ratio metrics reference other metrics**, not columns. Credible resolves the dependency chain (metric → metric → measure → column) before writing the Malloy expression.
## Before & After
dbt semantic model and metrics:
```yaml
semantic_models:
- name: orders
model: ref('fct_orders')
defaults:
agg_time_dimension: order_date
entities:
- name: order_id
type: primary
- name: customer
type: foreign
expr: customer_id
dimensions:
- name: order_date
type: time
type_params: { time_granularity: day }
- name: status
type: categorical
expr: order_status
measures:
- name: order_total
description: Sum of order amounts
agg: sum
expr: amount
metrics:
- name: revenue
type: simple
type_params: { measure: order_total }
- name: completed_revenue
type: simple
type_params: { measure: order_total }
filter: "{{ Dimension('order__status') }} = 'completed'"
- name: completion_rate
type: ratio
type_params: { numerator: completed_revenue, denominator: revenue }
```
```malloy
source: orders is conn.table('analytics.fct_orders') extend {
primary_key: order_id
join_one: customers is conn.table('analytics.dim_customers') on customer_id
dimension:
#(doc) Order status
#(index)
status is order_status
measure:
#(doc) Total revenue (USD)
# currency
revenue is sum(amount)
#(doc) Number of orders
order_count is count(order_id)
#(doc) Revenue from completed orders
# currency
completed_revenue is sum(amount) { where: status = 'completed' }
#(doc) Share of revenue from completed orders
# percent
completion_rate is completed_revenue / revenue
view:
#(doc) Revenue by month
revenue_by_month is {
group_by: order_date.month
aggregate: revenue
}
}
```
The two `simple` metrics collapse into their measures rather than duplicating them; `completion_rate` becomes a straight ratio; and the Jinja `filter` becomes a `{ where: … }` on the measure.
**More than a reformat.** Your metrics stop being a metrics API and become directly queryable, composable, AI-discoverable through the [AI Analytics Engine](/docs/how-to/analyzing/overview), and deliverable to every surface. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Tune your migrated model for AI retrieval
---
# Migrate from Looker
Source: https://www.credibledata.com/docs/how-to/migrating/looker
Your LookML is years of encoded business logic — dimension definitions, measure formulas, join relationships, and the curation decisions behind them. Credible reads it as **prior art** and rebuilds the analytical domain as governed Malloy: the same metrics — validated to the row wherever a connection allows — plus the context an AI agent needs to answer the questions your explores couldn't.
Still weighing the move? [Credible vs. Looker](/compare/looker) sets the two side by side.
LookML's UI patterns, Liquid templating, and performance-only constructs are identified and deliberately left behind.
## What Credible Reads
The adapter is [`malloy-lookml-review`](https://github.com/malloydata/publisher/tree/main/skills/malloy-lookml-review), MIT-licensed in [Malloy Publisher](https://github.com/malloydata/publisher). Each phase is a reference file you can read before you run it — field proposals, derived-table classification, visibility mapping, and the coverage report — so the rules applied to your project are inspectable rather than implied.
The agent inventories your LookML project — `manifest`, `model`, `view`, and `explore` files — resolving manifest constants as it goes. Give it the `.lkml` files and it has what it needs; it can also work from dashboards and other unstructured context when that's all you have. How far validation goes depends on what else it can reach:
- **LookML + live data** — with a warehouse connection (and, optionally, the Looker API), LookML supplies the business context and the data *validates* each proposal against live results.
- **LookML only** — with no connection, LookML is the sole source of context and each proposal is flagged unvalidated until data confirms it.
Where API access is available, the agent can reach it through [`looker-mcp-server`](https://github.com/Ultrathink-Solutions/looker-mcp-server), a community project under Apache 2.0 that is not affiliated with Looker, rather than bespoke API code. It takes Looker API credentials, so review it as you would any tool you hand a service account. Its `explore` and `query` groups browse models and run the original explore for parity checks, and its `audit` group reads query history, content usage, and PDT build logs out of [System Activity](https://cloud.google.com/looker/docs/system-activity-dashboards) for the usage trim. Start it with only the groups you need — `looker-mcp-server --groups explore,query,audit` — since the modeling, git, and admin tool groups are opt-in for a reason.
## What Comes Across
Dimensions and measures carry over as they are. The bigger pieces move like this:
| In Looker | In Credible |
|---|---|
| Views & explores | Malloy **sources**, joins folded in; `import`/`export` and the `explores` manifest curate what's exposed |
| Dimensions & measures (filtered, ratio, time) | The everyday building blocks, carried over |
| Persistent (PDT) & native (NDT) derived tables | **[`#@ persist`](/docs/how-to/modeling/persistence) on the source** for performance-only PDTs — one annotation replaces `derived_table`, `datagroup_trigger`, and the datagroup — and **query-as-source** for real transformations, minus the build schedules and cascading rebuilds |
| `access_filter` | A [**row-level `#(authorize)`**](/docs/how-to/modeling/fine-grained-acls#row-level-authorize) — the same annotation, reading a column of the source, so each caller sees the rows their grants admit. Reported as the source's `authorize` in introspection, and it survives derivation |
| `access_grant`, `required_access_grants` | A [**whole-source `#(authorize)`**](/docs/how-to/modeling/fine-grained-acls#source-access-authorize) — the expression names only secure givens and literals, so it admits every row or none |
| Model & explore permissions | [Resource permissions](/docs/platform-admin/permissions) at the package and environment level, with `#(authorize)` for the source-level question |
| `description:` and labels | `#(doc)` / `#(index)` tags, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) so an agent can find the right field and use it correctly |
| Dashboards & Looks | Rebuilt in the shape that fits: a [dashboard](https://github.com/malloydata/publisher/tree/main/skills/malloy-dashboards) (a tagged Malloy file with filter controls, a grid, and drill-through), a [notebook](/docs/how-to/analyzing/workspaces) where the numbers need prose, or an [HTML data app](/docs/how-to/analyzing/data-apps) where the design matters — none capped at Looker's tile set |
| Liquid SQL templating | **Real typed Malloy expressions** — no SQL string-templating to write or debug |
| `drill_fields` | Skipped as Looker UI detail, and reported as `skipped:looker-ui`. Drilling is a separate, deliberate step: a [`# drill`](https://github.com/malloydata/publisher/tree/main/skills/malloy-dashboards) tag on a model dimension makes every result grouped by it clickable, landing on the destination view with the clicked value filtered in — the same in a dashboard and a notebook, because the tag lives in the model rather than on a tile |
| `html:`, viz styling | Presentation, so none of it carries over. Where one hides a business rule — an `html:` block that flags margin under 5% — the rule becomes a real field and the styling is left behind |
## The Migration Flow
Inventory every `.lkml` file, categorize it, and extract source and join candidates with prior-art notes. The `explore`/`view` split collapses into a single Malloy source: joins move from the explore into the source, and `relationship: many_to_one` becomes `join_one`.
Extract field-level proposals from each view — dimensions and measures with a `lookml` provenance — and convert derived tables and struct/`UNNEST` joins. Apply the [keep / skip / flag triage](/docs/how-to/migrating/overview#what-the-agent-keeps-skips-and-flags): keep aggregation formulas, join cardinality, and `CASE` logic; skip `drill_fields`, `html:`/Liquid, and PDT optimization keys; flag 50-line SQL dimensions and synthetic primary keys.
Rewrite each LookML `description:` into a `#(doc)` tag that tells an agent what the field means and how to use it, `#(index)` the categorical dimensions, and map LookML visibility (`hidden`, `fields` exclusions, `required_access_grants`) to Malloy access modifiers and [access control](/docs/how-to/modeling/fine-grained-acls).
Confirm numeric parity and produce a [coverage report](/docs/how-to/migrating/overview#proving-parity) — what was modeled, renamed, rearchitected, deferred, or skipped, and why.
## What Credible Handles
- **Liquid and HTML** — `{% … %}` templating and `html:` conditional formatting are stripped; their *intent* is noted, and re-created as a renderer annotation only if it belongs in the model.
- **Persistent derived tables** — classified as native derived table, performance-only, or transformation. Perf-only PDTs become a [`#@ persist`](/docs/how-to/modeling/persistence) annotation on the base source; real transformations become query-based sources.
- **Refinements** (`+view`) — consolidated into one definition rather than layered, so there's a single source of truth per field.
- **Synthetic keys** — a `primary_key` built from `concat()` or `generate_uuid()` is flagged so you can confirm the real grain instead of baking in a workaround.
- **Access control, by layer** — Looker's three mechanisms all look like security, and conflating them is the failure that stays invisible until it matters. Two of them land on the same annotation: both `access_filter` and `required_access_grants` become `#(authorize)`, and the expression decides which — name a column of the source for row-level scoping, name only givens for a whole-source gate. The third, `sql_always_where`, sits in a security-shaped slot but often carries a data-quality filter, so it is documented as context rather than baked in. Read it before you move on: where it genuinely restricts access, that rule has to be re-expressed deliberately as `#(authorize)` or a `where:`, because documenting it does not enforce it. Every `required_access_grants` is flagged for a person the same way rather than converted.
- **Masking is not gating** — a Malloy model carries no per-viewer context of its own, so a `pick` that coarsens a value keys on row data or a parameter. "Everyone sees a band" is masking; `#(authorize)` decides whether a caller sees the field at all. They are independent layers.
- **Visibility, by reason rather than by keyword** — `hidden: yes` is cosmetic (the field is still queryable by URL and API) while a `fields` exclusion is structural (it never enters the pool). They map by reason: a hidden intermediate calculation keeps a `# hidden` tag and stays reachable, a hidden join key stays plain and public, a field hidden as clutter and genuinely unused becomes `internal:`, an excluded field becomes `internal:` outright, and `required_access_grants` becomes an [access control](/docs/how-to/modeling/fine-grained-acls) decision. Mapping `hidden: yes` straight to `internal:` over a few hundred fields is the quiet way to break a model an agent has to use.
- **Entity-attribute-value joins** — where LookML widened an EAV table by joining it once per attribute, the agent replaces the N joins with one grouped scan of filtered aggregates: one `aggregate:` line per attribute. Adding an attribute later is one more line, not one more join.
## Proving Parity
Two channels, used together:
1. **Looker API** — run the original explore through the API and compare. This requires the service account to satisfy the explore's `required_access_grants`, or restricted explores return 404 — indistinguishable at a glance from "explore not found," and not self-fixable without `administer`/`sudo`. The agent preflights the user attributes those grants key on before building anything on this path, rather than discovering it through 404s.
2. **Malloy against the same warehouse** — run the model against the warehouse the LookML reads and diff it against the equivalent SQL run directly there. Both sides hit the same data, so a difference is a difference in logic. This is the channel that validates the numbers in practice, with or without API access.
## Before & After
A LookML view and explore:
```lookml
view: orders {
sql_table_name: sales.orders ;;
dimension: order_id {
primary_key: yes
type: number
sql: ${TABLE}.order_id ;;
}
dimension: status {
label: "Order Status"
description: "Current fulfillment status of the order"
type: string
sql: ${TABLE}.order_status ;;
}
dimension: order_size {
type: string
sql: CASE
WHEN ${TABLE}.amount >= 100 THEN 'large'
WHEN ${TABLE}.amount >= 20 THEN 'medium'
ELSE 'small'
END ;;
}
dimension_group: created {
type: time
timeframes: [date, week, month, year]
sql: ${TABLE}.created_at ;;
}
measure: order_count {
type: count
drill_fields: [order_id, status, created_date] # dropped — UI only
}
measure: total_revenue {
label: "Total Revenue"
description: "Total revenue in USD"
type: sum
sql: ${TABLE}.amount ;;
value_format_name: usd
}
measure: cancelled_orders {
type: count
filters: [status: "cancelled"]
}
measure: cancellation_rate {
type: number
sql: 1.0 * ${cancelled_orders} / NULLIF(${order_count}, 0) * 100 ;;
value_format_name: percent_1
html: {% if value > 10 %}{{ rendered_value }}{% endif %} ;;
}
}
explore: orders {
join: customers {
type: left_outer
sql_on: ${orders.customer_id} = ${customers.customer_id} ;;
relationship: many_to_one
}
}
```
The same domain in Malloy — one source, joins folded in, Liquid and drill fields dropped:
```malloy
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers is conn.table('sales.customers') on customer_id
dimension:
#(doc) Current fulfillment status of the order
#(index)
status is order_status
#(doc) Order size bucket derived from amount
order_size is
pick 'large' when amount >= 100
pick 'medium' when amount >= 20
else 'small'
#(doc) Date the order was placed
created_date is created_at::date
measure:
#(doc) Number of orders
order_count is count()
#(doc) Total revenue in USD
# currency
total_revenue is sum(amount)
#(doc) Orders that were cancelled
cancelled_orders is count() { where: status = 'cancelled' }
#(doc) Percentage of orders that were cancelled
# percent
cancellation_rate is cancelled_orders / order_count * 100
view:
#(doc) Monthly revenue trend with order counts
monthly_revenue is {
group_by: created_date.month
aggregate: total_revenue, order_count
}
}
```
The `type: time` dimension group becomes a single date dimension you truncate with `.month`/`.year` in a view — no enumerated timeframe list. `drill_fields`, the Liquid `html:` block, and `value_format_name` have no field-level model equivalent: drilling is implicit in Malloy, and formatting moves to `# currency`/`# percent` render tags.
**More than a reformat.** Off LookML, the model is AI-discoverable through the [AI Analytics Engine](/docs/how-to/analyzing/overview), composes into questions your explores couldn't answer, and is open code you own rather than logic locked in Looker. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Tune your migrated model for AI retrieval
---
# Migrate from Omni
Source: https://www.credibledata.com/docs/how-to/migrating/omni
Omni's model spans layers — a shared model every workbook inherits, per-workbook extensions, and branches in between. Credible reads across all of them, reconciles the definitions into one canonical set, and rebuilds your analytical domain as governed Malloy.
Still weighing the move? [Credible vs. Omni](/compare/omni) sets the two side by side.
## What Credible Reads
Your Omni model — `.view` files (dimensions and measures over tables) and `.topic` files (views joined into queryable units, with AI context and default filters), authored in YAML. The agent works from those files directly, inventorying workbook-level extensions too — logic often lives there, not just in the shared model. Connecting Omni's **MCP server** or **Model API** is optional and adds live validation (and can round-trip the model files).
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In Omni | In Credible |
|---|---|
| Shared model, topics, views | Malloy **sources** (base + joined); `import`/`export` curate exposure |
| Dimensions & measures | Carried over, filtered and ratio measures included |
| Field-level `sql:` with `${…}` refs | Resolved into Malloy expressions with explicit types |
| Logic split across shared / branch / workbook layers | Reconciled into **one canonical definition per field** |
| Model access controls | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| `ai_context` and descriptions | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Workbooks & dashboards | Rebuilt as [data apps](/docs/how-to/analyzing/data-apps) or [notebooks](/docs/how-to/analyzing/workspaces) |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the shared model, topics, and workbook layers, translates views to sources and topics to joined sources, enriches with `#(doc)`/`#(index)` tags (seeded from `ai_context`), and — where you connect it — validates against Omni's query engine.
## What Credible Handles
- **Logic split across layers** — the "real" definition of a field may live in an un-promoted workbook model, not the shared model. Credible reconciles the shared, branch, and workbook layers into one canonical Malloy definition, resolving promotion lineage as it goes.
- **Field-level inline SQL** — Omni encourages `sql:` with `${…}` references and implicit typing. Credible resolves the references and makes Malloy types explicit.
- **Removable default filters** belong in the query, not the model, so query-time defaults become part of a named view rather than a source-level filter.
## Before & After
An Omni `.view` and `.topic`:
```yaml
# order_items.view
views:
- name: order_items
sql_table_name: analytics.public.order_items
dimensions:
status:
type: string
sql: ${TABLE}.order_status
value_tier:
type: string
sql: |
CASE WHEN ${TABLE}.sale_price >= 100 THEN 'High'
WHEN ${TABLE}.sale_price >= 25 THEN 'Medium'
ELSE 'Low' END
measures:
total_revenue:
description: Gross merchandise value across all order items
sql: ${TABLE}.sale_price
aggregate_type: sum
completed_revenue:
sql: ${TABLE}.sale_price
aggregate_type: sum
filters: { status: { is: Complete } }
order_count:
sql: ${TABLE}.order_id
aggregate_type: count_distinct
```
```yaml
# order_items.topic
topic:
base_view: order_items
label: Order Analysis
ai_context: |
Order-item level revenue and fulfillment. Use total_revenue for GMV and
completed_revenue for recognized revenue; join users for customer demographics.
joins:
users:
# a removable, query-time default — not baked into the model
filters:
order_items.status:
is: Complete
```
```malloy
source: order_items is conn.table('analytics.public.order_items') extend {
primary_key: order_item_id
join_one: users is conn.table('analytics.public.users') on user_id = users.id
dimension:
#(doc) Order item status
#(index)
status is order_status
#(doc) Sale-price value bucket
value_tier is
pick 'High' when sale_price >= 100
pick 'Medium' when sale_price >= 25
else 'Low'
measure:
#(doc) Gross merchandise value across all order items
# currency
total_revenue is sum(sale_price)
#(doc) Recognized revenue from completed items
# currency
completed_revenue is sum(sale_price) { where: status = 'Complete' }
#(doc) Distinct orders
order_count is count(order_id)
#(doc) Average order value
# currency
avg_order_value is total_revenue / order_count
view:
#(doc) Revenue by month
revenue_by_month is {
group_by: created_at.month
aggregate: total_revenue
}
}
```
The topic's `ai_context` becomes `#(doc)` intent on the source and its views; the same physical view joined multiple ways in a topic becomes multiple named joins in Malloy.
**More than a reformat.** Definitions once split across shared, branch, and workbook layers collapse into one canonical, AI-discoverable model that composes into new questions. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Package and publish your migrated model
---
# Migration Overview
Source: https://www.credibledata.com/docs/how-to/migrating/overview
You've probably already built a semantic layer — whether or not you call it one. And you may well have **more than one**: a Looker instance from one team, a Tableau data source from another, DAX measures in Power BI, a Snowflake semantic view — the sprawl that comes with acquisitions, multiple business units, or just different teams reaching for different tools. Each holds years of business logic your team trusts.
Credible helps you capture that meaning — from one tool or many — and consolidate it into **[governed data models](/docs/concepts/data-model)** in Malloy: readable, versioned in Git, and delivered as trusted context to every surface.
Your source model is **prior art**, not a spec to transpile line-for-line: the agent reads it for intent, keeps the logic worth keeping, drops what's tool-specific, and rebuilds the analytical domain as governed Malloy — running on the same [open-source agent skills](/docs/how-to/analyzing/overview) that power the rest of Credible, extended to read your source tool.
## Migrate the Domain, Not the Dashboard
In practice there isn't *one* dashboard — there are dozens or hundreds, uneven in quality and usage, a handful carrying most of the traffic. Migration shouldn't recreate them tile for tile. Our migration approach anchors on the ones that matter and captures the **analytical domain** beneath them — the fields, metrics, and relationships actually in use, plus what they depend on — modeled by question rather than by tile, so the result rebuilds what those dashboards show *and* answers the follow-ups they imply. How sharply it can tell *used* from merely *defined* depends on the context: with query logs or usage reporting the trim is precise; otherwise the agent works from the data models and the SQL behind your key dashboards.
## Scoping: The Field Survey
Before the four steps below, decide what is in scope. A model that has run for years exposes far more than anyone queries, and the trim is the difference between a migration that lands and one that stalls.
Work outward from a certified dashboard in three passes:
1. **Tile references** — every field used in a tile's selects, filters, and sorts.
2. **Inline measures** — the calculations defined on the tiles themselves rather than in the model. A surprising share of real business logic lives here.
3. **Ad hoc usage** — fields people query that no dashboard touches, plus whatever those fields depend on, so nothing you keep points at something you cut.
Everything else is out. Where the source tool records its own usage — Looker's [**System Activity**](https://cloud.google.com/looker/docs/system-activity-dashboards) model is the clearest case — that trim is evidence rather than opinion.
**From one migration.** A certified dashboard of 28 tiles over three Looker explores: the explores exposed roughly 6,500 fields, the rebuilt model kept 377, and every supported tile was reproduced and validated row by row.
Structure the result by question, not by tile: base sources (one per physical table, no joins), then domain sources grouped by subject area, then named queries carrying `#(doc)` tags an agent can find by intent. Avoid a single "everything" source — cross-domain questions are better answered by an agent running several targeted queries than by one large join graph.
## How It Works
Migration is the **Collect** step at full stretch. The meaning already exists — in your model **code** (LookML, TMDL, a YAML model, a semantic-view definition), in the **dashboards and query logs** built on it, and in the **docs and decks** written around it. The agent connects to wherever it lives and brings it in, including over the source's own **APIs or MCP tools** where those exist, so it can read the live model and validate against it.
Collecting context finds what is written down; it cannot find judgment. Your team supplies that while modeling, and the result hands off to the same [Deliver](/docs/how-to/analyzing/overview) path every model uses. The four steps:
Inventory the source model — tables, dimensions, measures, joins, and the logic buried in calculated fields and filters.
Map each concept to its Malloy equivalent — sources, joins, dimensions, measures, views — keeping the logic and dropping tool-specific presentation and performance constructs.
Add `#(doc)` and `#(index)` [metadata tags](/docs/how-to/modeling/metadata-tags) — documenting what each field means and how to use it (units, rules, caveats) and indexing its values — so an agent finds the right field *and* uses it correctly.
Where a connection is available, run the model against live data and compare it row-by-row to the source's own engine — confirming a match before delivery.
The agent runs in the Credible App or in your IDE via [local development](/docs/how-to/developers/overview) — the same skills either way. A live connection isn't required to produce the model: without one you still get the full translation, ready to validate once a connection — the source engine or the warehouse behind it — is in place.
## What the Agent Keeps, Skips, and Flags
Not every line in a source model belongs in the data model:
| | What it covers | Examples |
|---|---|---|
| **Keep** | Business logic and structure | Dimension and measure names, aggregation formulas, primary keys, joins, `CASE` logic, filtered aggregates, currency/percent formats |
| **Skip** | Dead weight & tool plumbing | Stale, redundant, or unused fields and reports; drill paths, action links, raw HTML and cosmetic styling |
| **Flag** | Judgment calls for a human | Logic that may belong upstream (warehouse or dbt), synthetic primary keys, duplicate or conflicting field definitions |
Presentation isn't ignored where it carries meaning: number and currency formats become render tags, a conditional-format rule ("flag when churn tops 10%") becomes model logic, and whole dashboards are rebuilt as [data apps](/docs/how-to/analyzing/data-apps). What's genuinely dropped is what's *dead* — stale, redundant, or unused — or pure tool plumbing with no meaning. Where Malloy expresses something differently — DAX filter context, table calculations, `metric_time` — it's re-worked explicitly, never dropped silently; each source guide spells out how.
## Proving Parity
When there's query access, the agent validates row-by-row — running each original metric through the source's engine (or equivalent SQL against the same warehouse) and diffing it against the migrated Malloy. Matching numbers confirm the translation; but a source of truth can carry its own errors, ambiguities, and inconsistencies, so any delta is confirmed and flagged for deeper investigation, not silently reconciled. It produces a coverage report — modeled, renamed, deferred, or skipped, each with a reason — plus any discrepancies it surfaced.
## More Than a Reformat
A before/after looks like a translation — same metrics, cleaner syntax. That's the fidelity check; the reasons to migrate are what the new model can do that the old one couldn't:
- **It answers the next question.** Malloy is composable — views nest, chain, and reuse as sources — so the model handles follow-ups the original dashboard never exposed.
- **AI-usable meaning.** `#(doc)` and `#(index)` tags compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) tell an agent what a field means, how to use it, and what values it holds — so it finds the right field *and* queries it correctly, not just by matching a name.
- **Correct by construction.** Malloy's symmetric aggregates stop measures double-counting across one-to-many joins — the silent bug in hand-written SQL and BI extracts.
- **It's real code, and it compiles.** A typed language catches bad references and type mismatches at build time, not as wrong numbers in a dashboard — and it's concise, turning sprawling DAX or LookML into a few readable lines.
- **One model, every surface.** One governed model serves agents over MCP, dashboards, data apps, and the REST APIs, with [access control](/docs/how-to/modeling/fine-grained-acls) enforced at the gateway on every query — open, in Git, no lock-in.
## A Worked Example
The payoff is a question the old dashboard *couldn't* answer — say, how revenue is pacing against target. With the sales domain modeled and a `targets` source joined in, that's one query:
```malloy
#(doc) Monthly revenue vs. target, with attainment
query: revenue_vs_target is sales -> {
group_by: order_month is order_date.month
aggregate:
actual is total_revenue
target is targets.monthly_target
# percent
attainment is actual / target
}
```
## Supported Sources
Each has a dedicated guide with a concept-to-Malloy mapping and a before/after: [Looker](/docs/how-to/migrating/looker), [Sigma](/docs/how-to/migrating/sigma), [Omni](/docs/how-to/migrating/omni), [Cube](/docs/how-to/migrating/cube), [Power BI](/docs/how-to/migrating/power-bi), [Tableau](/docs/how-to/migrating/tableau), [Snowflake](/docs/how-to/migrating/snowflake), [dbt](/docs/how-to/migrating/dbt), and [Databricks](/docs/how-to/migrating/databricks).
Don't see your tool? The same method applies to any semantic layer that exposes its definitions. [Contact us](mailto:support@credibledata.com) and we'll walk through it.
## Next Steps
See the full method applied to LookML, end to end
How `#(doc)` and `#(index)` tags make a model discoverable
---
# Migrate from Power BI
Source: https://www.credibledata.com/docs/how-to/migrating/power-bi
Your Power BI semantic model holds the definitions your business runs on — tables, relationships, and DAX measures. Credible reads the model definition, re-expresses its DAX logic as Malloy, and — where you connect it — validates each measure against Power BI's own query engine before you cut over.
Still weighing the move? [Credible vs. Power BI](/compare/power-bi) sets the two side by side.
## What Credible Reads
Your **tabular model** — tables, columns, relationships, and DAX measures — from its text definition in **TMDL** (Tabular Model Definition Language, the folder-based format inside a PBIP project) or the older TMSL. Hand the agent those files and it can translate. Connecting the official **Power BI Modeling MCP server** (which loads TMDL) or the **XMLA endpoint** is optional: it lets the agent load the model live and run DAX for validation.
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In Power BI | In Credible |
|---|---|
| Tabular model, tables, relationships | Malloy **sources** and joins |
| DAX measures & calculated columns | Measures and dimensions — `CALCULATE`'s filter-context gymnastics become plain, readable filtered aggregates |
| Time-intelligence (`TOTALYTD`, …) | Rebuilt as explicit time-grain truncation and window views |
| Import mode & aggregation tables | [`#@ persist`](/docs/how-to/modeling/persistence) and [`#@ preaggregate`](/docs/how-to/modeling/persistence#pre-aggregations) — one annotation each, built and refreshed by the engine |
| RLS roles | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| Descriptions | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Reports & dashboards | Rebuilt as [data apps](/docs/how-to/analyzing/data-apps) or [notebooks](/docs/how-to/analyzing/workspaces) |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the TMDL, translates tables and relationships to Malloy sources and joins and DAX measures to Malloy measures, enriches with `#(doc)`/`#(index)` tags, and — where you connect it — validates row-by-row using the **ExecuteQueries** API to run the original DAX and diff it against the migrated result.
## What Credible Handles
- **Filter context and `CALCULATE`** — a simple `CALCULATE([Total], Status="shipped")` is an equivalent filtered aggregate in Malloy. DAX that *removes* or *overrides* context (`ALL`, `REMOVEFILTERS`) has no ambient equivalent and is re-modeled as an `all()`/level-of-detail aggregate or a separate query — explicitly, never guessed.
- **Time-intelligence** (`TOTALYTD`, `SAMEPERIODLASTYEAR`) depends on a marked date table and the visual's current filter. Malloy has no ambient filter context, so year-to-date is not a measure — it becomes an explicit cumulative view driven by the query's date grain.
- **Implicit measures** — auto-aggregations that were never stored as named measures are materialized explicitly, so parity checks don't miss them.
## Before & After
A TMDL table (relationships live in a separate `relationships.tmdl`):
```tmdl
table Sales
column OrderID
dataType: int64
isKey
sourceColumn: order_id
/// Date the order was placed
column OrderDate
dataType: dateTime
sourceColumn: created_at
column Status
dataType: string
sourceColumn: order_status
/// Total revenue in USD
measure 'Total Revenue' = SUM('Sales'[Amount])
formatString: \$#,0.00
/// Revenue from shipped orders only (filter context)
measure 'Shipped Revenue' =
CALCULATE ( [Total Revenue], 'Sales'[Status] = "shipped" )
/// Share of revenue that shipped
measure 'Shipped Revenue %' =
DIVIDE ( [Shipped Revenue], [Total Revenue] )
formatString: 0.0%
/// Year-to-date revenue
measure 'Revenue YTD' = TOTALYTD ( [Total Revenue], 'Calendar'[Date] )
```
```malloy
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers is conn.table('sales.customers') on customer_id
dimension:
#(doc) Date the order was placed
order_date is created_at::date
#(doc) Order fulfillment status
#(index)
status is order_status
measure:
#(doc) Total revenue in USD
# currency
total_revenue is sum(amount)
#(doc) Revenue from shipped orders only
# currency
shipped_revenue is sum(amount) { where: status = 'shipped' }
#(doc) Share of revenue that shipped
# percent
shipped_revenue_pct is shipped_revenue / total_revenue
view:
#(doc) Year-to-date revenue — cumulative by month
revenue_ytd is {
group_by: order_date.month
aggregate: total_revenue
calculate: running_total is sum_cumulative(total_revenue) {
partition_by: order_date.year
order_by: order_date.month asc
}
}
}
```
`CALCULATE` with a simple predicate becomes a `{ where: … }` filtered measure; `TOTALYTD` — which relied on ambient filter context — becomes an explicit cumulative view. The `formatString` masks map to `# currency`/`# percent`.
**More than a reformat.** The migration leaves DAX filter-context complexity behind for aggregates that are correct by construction, and your logic becomes portable, AI-discoverable code instead of a Power BI artifact. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Re-establish RLS as governed access rules
---
# Migrate from Sigma
Source: https://www.credibledata.com/docs/how-to/migrating/sigma
Sigma centralizes business logic in **data models** — but in practice, much of the real logic lives in spreadsheet-style formulas scattered across workbooks. Credible reads both, consolidates the duplication, and rebuilds a single governed Malloy model your whole organization can query consistently.
Still weighing the move? [Credible vs. Sigma](/compare/sigma) sets the two side by side.
## What Credible Reads
Your Sigma **data models** (Sigma's first-class semantic layer, which supersedes the older datasets), plus the calculated columns and metrics embedded in workbooks — exportable as code (JSON, or YAML via `?format=yaml`). The agent works from that export. Connecting Sigma's **MCP server** (OAuth, permission-inherited) or REST API is optional: it lets the agent search across data models *and* workbook elements to find logic that never made it into the central model, and validate the result.
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In Sigma | In Credible |
|---|---|
| Data models | Malloy **sources**; `import`/`export` curate exposure |
| Columns, metrics, relationships | Carried over as dimensions, measures, and joins |
| Workbook spreadsheet formulas | Consolidated into one source of truth — not the same metric redefined differently in each workbook |
| Workbook permissions | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| Descriptions | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Workbooks & dashboards | Rebuilt as [data apps](/docs/how-to/analyzing/data-apps) or [notebooks](/docs/how-to/analyzing/workspaces) |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the data model and crawls workbook elements for embedded logic, translates tables to sources and formulas to dimensions/measures, enriches with `#(doc)`/`#(index)` tags, and — where you connect it — validates results against Sigma's query engine.
## What Credible Handles
- **Workbook-embedded logic** is the classic Sigma trap: the true definitions are often spreadsheet formulas duplicated across many workbooks, not the central model. Credible finds them, reconciles the drift, and hoists a single canonical definition into the Malloy source.
- **Spreadsheet-formula semantics** (Excel-like functions, row-level vs. aggregate context) are re-expressed as Malloy dimensions and measures, preserving whether each ran per-row or grouped.
- **External semantic layers** — if a workbook reads dbt Semantic Layer metrics or Snowflake semantic views through Sigma, the logic lives upstream; Credible migrates the [upstream](/docs/how-to/migrating/dbt) [definitions](/docs/how-to/migrating/snowflake), not the passthrough.
## Before & After
A Sigma data model as code:
```json
{
"name": "Orders Model",
"columns": [
{ "name": "Status", "formula": "[ORDERS/order_status]",
"description": "Current fulfillment status of the order" },
{ "name": "Order Size",
"formula": "If([Amount] >= 100, \"large\", [Amount] >= 20, \"medium\", \"small\")" }
],
"metrics": [
{ "name": "Total Revenue", "formula": "Sum([Amount])",
"format": { "type": "currency" } },
{ "name": "Cancelled Orders", "formula": "SumIf(1, [Status] = \"cancelled\")" },
{ "name": "Cancellation Rate",
"formula": "Divide([Cancelled Orders], Count([Order Id])) * 100",
"format": { "type": "percent" } }
],
"relationships": [
{ "kind": "many-to-one", "target": { "path": ["SALES","PUBLIC","CUSTOMERS"] },
"on": "[ORDERS/customer_id] = [CUSTOMERS/customer_id]" }
]
}
```
```malloy
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers is conn.table('sales.customers') on customer_id
dimension:
#(doc) Current fulfillment status of the order
#(index)
status is order_status
#(doc) Order size bucket derived from amount
order_size is
pick 'large' when amount >= 100
pick 'medium' when amount >= 20
else 'small'
measure:
#(doc) Total revenue in USD
# currency
total_revenue is sum(amount)
#(doc) Orders that were cancelled
cancelled_orders is count() { where: status = 'cancelled' }
#(doc) Percentage of orders that were cancelled
# percent
cancellation_rate is cancelled_orders / count() * 100
view:
#(doc) Monthly revenue trend
monthly_revenue is {
group_by: created_at.month
aggregate: total_revenue
}
}
```
Sigma's code representation doesn't cover every construct (input tables, Python elements, and some data-source-level metrics live outside it), so Credible supplements the model-as-code export with workbook and element inspection to capture the full picture.
**More than a reformat.** Logic that was duplicated across workbooks becomes one governed, AI-discoverable source of truth that serves every surface, not just Sigma. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Tune your migrated model for AI retrieval
---
# Migrate from Snowflake Semantic Views
Source: https://www.credibledata.com/docs/how-to/migrating/snowflake
Snowflake semantic views and Malloy are close cousins — both are dimension, measure, and relationship graphs over SQL tables. Credible reads your semantic view definition, maps it almost concept-for-concept to Malloy, and — where you connect it — validates against Snowflake's own verified queries.
Still weighing the move? [Credible vs. Snowflake Cortex](/compare/snowflake-cortex) sets the two side by side.
## What Credible Reads
Your native **`SEMANTIC VIEW`** objects — logical tables, relationships, facts, dimensions, and metrics — or any legacy **Cortex Analyst YAML** models. The agent works from the exported definition (the `CREATE SEMANTIC VIEW` DDL or the YAML). Connecting to Snowflake — via SQL (`DESCRIBE SEMANTIC VIEW`, `SHOW SEMANTIC VIEWS`) or the **Snowflake-managed MCP server** (Cortex) — is optional: it lets the agent read views in place and run parity queries under Snowflake's own RBAC.
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In Snowflake | In Credible |
|---|---|
| Semantic view: logical tables & relationships | Malloy **sources** and joins |
| Dimensions, facts, metrics | Dimensions, row-level facts, and measures — facts feed measures, so you can re-aggregate at any grain |
| `WITH SYNONYMS` / `COMMENT` | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Verified queries | Parity fixtures and named views |
| `PUBLIC` / `PRIVATE`, RBAC | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| Cortex Analyst / BI on top | Every surface — agents over MCP, [data apps](/docs/how-to/analyzing/data-apps), [notebooks](/docs/how-to/analyzing/workspaces), dashboards, APIs |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the semantic view definition, translates logical tables and relationships to sources and joins (facts to row-level dimensions, metrics to measures), enriches with `#(doc)`/`#(index)` tags seeded from synonyms and comments, and — where you connect it — validates against Snowflake.
## What Credible Handles
- **Two coexisting formats** — a deployment may use native `SEMANTIC VIEW` objects, legacy Cortex Analyst YAML on a stage, or both. Credible detects which and reads each accordingly.
- **Facts vs. metrics** — a fact is a row-level expression; a metric is its aggregation. Credible keeps them distinct (fact → row-level dimension, metric → measure) so you can still re-aggregate at different grains. Collapsing them would lose that.
- **Verified queries** are the best thing to validate against — Credible replays each question→SQL pair and diffs the result against the migrated Malloy. (Verified SQL references logical names, not physical tables.)
## Before & After
A `CREATE SEMANTIC VIEW` statement:
```sql
CREATE OR REPLACE SEMANTIC VIEW sales.sales_analytics
TABLES (
orders AS sales.orders PRIMARY KEY (order_id)
WITH SYNONYMS = ('purchase_orders')
COMMENT = 'Order transactions at the order grain',
customers AS sales.customers PRIMARY KEY (customer_id)
)
RELATIONSHIPS (
orders_to_customers AS orders (customer_id) REFERENCES customers (customer_id)
)
FACTS (
orders.line_amount AS orders.amount COMMENT = 'Per-row order amount in USD',
PRIVATE orders.is_shipped AS CASE WHEN orders.status = 'shipped' THEN 1 ELSE 0 END
)
DIMENSIONS (
orders.order_date AS CAST(orders.created_at AS DATE)
COMMENT = 'Date the order was placed',
customers.region AS customers.geographic_region
)
METRICS (
orders.total_revenue AS SUM(orders.line_amount) COMMENT = 'Total revenue in USD',
orders.shipped_revenue AS SUM(orders.line_amount * orders.is_shipped),
orders.shipped_revenue_pct AS
SUM(orders.line_amount * orders.is_shipped) / SUM(orders.line_amount)
);
```
```malloy
#(doc) Order transactions at the order grain. Also known as: purchase_orders
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers is conn.table('sales.customers') on customer_id
dimension:
#(doc) Date the order was placed
order_date is created_at::date
#(doc) Per-row order amount in USD (fact)
line_amount is amount
#(doc) Row-level shipped flag (fact)
is_shipped is pick 1 when status = 'shipped' else 0
measure:
#(doc) Total revenue in USD
# currency
total_revenue is sum(line_amount)
#(doc) Revenue from shipped orders
# currency
shipped_revenue is sum(line_amount) { where: status = 'shipped' }
#(doc) Share of revenue that shipped
# percent
shipped_revenue_pct is shipped_revenue / total_revenue
}
```
`FACTS` become row-level dimensions that feed measures; `METRICS` become measures. `WITH SYNONYMS` and `COMMENT` fold into `#(doc)` (Malloy has no synonym primitive, so alternate names go in the description for retrieval), and `PRIVATE` facts map to access modifiers so they feed measures without being independently queryable.
**More than a reformat.** Semantic views map almost 1:1, so the gain is what surrounds them — composable follow-up queries, [AI Analytics Engine](/docs/how-to/analyzing/overview) discovery, and one model that reaches agents, apps, and BI beyond Cortex. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Package and publish your migrated model
---
# Migrate from Tableau
Source: https://www.credibledata.com/docs/how-to/migrating/tableau
Your Tableau published data sources carry the calculated fields, relationships, and LOD expressions your analysts rely on — and workbooks carry even more. Credible reads both, re-expresses the calculations as Malloy, and — where you connect it — validates them against Tableau's own query service.
Still weighing the move? [Credible vs. Tableau](/compare/tableau) sets the two side by side.
## What Credible Reads
Your **published data sources** (`.tds` / `.tdsx`) — calculated fields, default aggregations, folders, and Tableau's logical and physical layers — plus the calculated fields embedded in **workbooks** (`.twb`). These files are all the agent needs to translate. Connecting the official **Tableau MCP server** (`tableau/tableau-mcp`, hosted at `mcp.tableau.com`) is optional: it reads model metadata via the **Metadata API** and validates through the **VizQL Data Service**.
## What Comes Across
The everyday modeling carries over. The bigger pieces land like this:
| In Tableau | In Credible |
|---|---|
| Published data sources & relationships | Malloy **sources** and joins |
| Calculated fields | Dimensions and measures |
| LOD expressions (`FIXED` / `INCLUDE` / `EXCLUDE`) | Aggregates at a declared grain — no LOD workarounds for fan-out |
| Table calculations (`RUNNING_SUM`, `WINDOW_*`) | Reusable window calcs defined in the model — not view-position-dependent calcs that break when the viz changes |
| Hyper extracts & refresh schedules | [`#@ persist`](/docs/how-to/modeling/persistence) on the source — one annotation, built and refreshed by the engine |
| Data-source & workbook permissions | **Fine-grained access control in the model**, versioned and enforced at the gateway on every query |
| Field captions & comments | `#(doc)` / `#(index)`, compressed into the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) |
| Workbooks & dashboards | Rebuilt as [data apps](/docs/how-to/analyzing/data-apps) or [notebooks](/docs/how-to/analyzing/workspaces) |
## The Migration Flow
Credible [reads](/docs/how-to/migrating/overview) the data source and workbook calcs, translates fields and relationships to Malloy, enriches with `#(doc)`/`#(index)` tags, and — where you connect it — validates row-by-row against the **VizQL Data Service**.
## What Credible Handles
- **LOD expressions** encode a grain independent of the viz. A `{ FIXED [Customer ID] : SUM([Amount]) }` becomes a Malloy aggregate at an explicit grain. Credible also distinguishes "real" LODs from workaround LODs that only existed to dedupe joins — the latter are unnecessary in a clean model.
- **Table calculations** run over the rendered viz and depend on Compute-Using direction. They're reconstructed as explicit Malloy window functions with a declared `partition_by`/`order_by`; `TOTAL()` maps to `all()`.
- **Workbook-embedded calculated fields** — business logic frequently lives in `.twb`, not the published `.tds`, so Credible scans both.
- **Viz-level formatting** — Compute-Using direction, table layout, cosmetic styling — is presentation and is dropped; threshold-based color rules become model logic, and model-worthy defaults and labels carry over.
## Before & After
Tableau calculated fields as authored against a data source:
```
// Relationship: Orders ── Customers (many-to-one)
[Order Date Only] = DATETRUNC('day', [Created At])
[Shipped Revenue] = SUM(IF [Status] = "shipped" THEN [Amount] END)
[Shipped Revenue %] = SUM(IF [Status] = "shipped" THEN [Amount] END) / SUM([Amount])
// LOD: revenue per customer, independent of view grain
[Revenue per Customer] = { FIXED [Customer ID] : SUM([Amount]) }
// Table calcs (viz-context dependent)
[Running Revenue] = RUNNING_SUM(SUM([Amount]))
[Pct of Total Revenue] = SUM([Amount]) / TOTAL(SUM([Amount]))
```
```malloy
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers is conn.table('sales.customers') on customer_id
dimension:
#(doc) Order date truncated to day
order_date is created_at::date
measure:
#(doc) Total revenue in USD
# currency
total_revenue is sum(amount)
#(doc) Revenue from shipped orders
# currency
shipped_revenue is sum(amount) { where: status = 'shipped' }
#(doc) Share of revenue that shipped
# percent
shipped_revenue_pct is shipped_revenue / total_revenue
view:
#(doc) Revenue per customer (LOD FIXED equivalent — aggregate at customer grain)
revenue_per_customer is {
group_by: customers.customer_id
aggregate: total_revenue
}
#(doc) Running revenue and percent of total by day (table-calc equivalent)
revenue_trend is {
group_by: order_date
aggregate: total_revenue
calculate:
running_revenue is sum_cumulative(total_revenue) {
partition_by: order_date.year
order_by: order_date asc
}
pct_of_total is total_revenue / all(total_revenue)
}
}
```
A `FIXED` LOD becomes an aggregate declared at its grain; table calcs become explicit window calculations. Purely visual constructs — Compute-Using direction, quick table calcs, worksheet formatting — have no model equivalent and are dropped.
**More than a reformat.** Logic that lived inside workbooks becomes a reusable, AI-discoverable model that serves every surface, not just Tableau — and Malloy's symmetric aggregates keep totals correct where Tableau needed LODs to avoid double-counting. [See what you gain →](/docs/how-to/migrating/overview#more-than-a-reformat)
## Next Steps
The method behind every migration
Tune your migrated model for AI retrieval
---
# Modeling Overview
Source: https://www.credibledata.com/docs/how-to/modeling/ai-modeling
A **data model** captures what your data means — sources connected to your tables, joins between them, and the dimensions, measures, and views that encode your business definitions — as [Malloy](https://malloydata.dev) code in a versioned package. You build models with AI agents: describe what you want in plain language, and the agent discovers your data, drafts the model, and helps you validate and publish it.
As covered in [Environments](/docs/how-to/modeling/environment-overview), there are two ways to build. [Build & Publish](/docs/how-to/modeling/in-app-development) in the app is the fastest way to get started — the in-app agent handles everything from connecting data to publishing, with nothing to install. The [developer tools](/docs/how-to/developers/overview) bring the same capabilities to your IDE and coding agent for Git-based workflows and direct control over files. Both produce the same governed packages, and this section applies to both.
**New to data modeling?** See [The Data Model](/docs/concepts/data-model) to understand the concepts, or the [Malloy Language Documentation](https://docs.malloydata.dev/documentation/) for language details.
## The Building Blocks
A Malloy model is built from a handful of constructs. You'll see them in everything the agent generates:
- **Sources** — tables from your environment's connections, extended with semantics: `source: orders is conn.table('sales.orders') extend { ... }`
- **Joins** — relationships between sources, declared once and available to every query
- **Dimensions** — attributes to group and filter by
- **Measures** — aggregate calculations like revenue or order count, defined once and reused everywhere
- **Views** — saved query patterns built from dimensions and measures
- **Annotations** — tags on sources and fields that tell Credible how to treat them. Annotations are how you evolve a model beyond its structural definition: `#(doc)` documents a field, `#(index)` makes its values searchable, `#(authorize)` controls who can query a source, and `#@ persist` materializes it for performance. The rest of this section is largely about applying them.
## Stages of Model Development
A model matures in stages, and the pages in this section follow them in order:
1. **Model** — build the model: sources, joins, dimensions, measures, and views (this page)
2. **Optimize for AI retrieval** — document fields and index values with [Discovery Metadata](/docs/how-to/modeling/metadata-tags) tags so the concept index can match questions by meaning
3. **Secure** — control who sees which sources, rows, and columns with fine-grained [Access Control](/docs/how-to/modeling/fine-grained-acls) annotations
4. **Optimize performance and cost** — materialize expensive sources and manage index freshness with persistence annotations ([Performance & Cost](/docs/how-to/modeling/persistence))
5. **Publish** — version and serve the model to every consumer with [Publishing](/docs/how-to/modeling/publishing)
You don't have to do them all at once — a first model can go straight from stage 1 to publish, then pick up retrieval, security, and performance annotations as it evolves.
## Prerequisites
- **A place to build** — a [workspace in the Credible App](/docs/how-to/modeling/in-app-development), or an [IDE with the Credible Extension](/docs/how-to/developers/vscode-extension)
- **A database connection** — see [Connect a Database](/docs/how-to/modeling/connect-data)
The agent only knows about your data after the connection is indexed — this is configured when you [set up the connection's scope](/docs/how-to/modeling/connect-data#configure-scope-for-ai-assisted-modeling). Indexing can take a few minutes, so if the agent can't see a new connection's tables yet, wait and check that your tables are within the indexing limits.
## Build a Model with the Agent
The workflow is the same whether you're chatting in the app or in your IDE:
**Already have a BI tool or a semantic layer?** If your business logic lives in Looker, Power BI, Tableau, Cube, dbt, or a warehouse semantic view, give the agent that context rather than starting from a blank file — it reads your existing definitions for intent and rebuilds them as governed Malloy, which is usually faster and more faithful than describing the model from memory. See [Migrations](/docs/how-to/migrating/overview).
1. **Describe what you want to model.** Be specific about your data and analysis goals:
- *"Build a model of my ecommerce data so I can analyze sales by product and brand"*
- *"Create a data model for customer analytics including lifetime value"*
- *"Model the orders table with customer and product relationships"*
2. **The agent discovers and proposes.** The agent uses its MCP tools — MCP is the open protocol that connects agents to tools — to explore your indexed tables and schemas. Backed by real data, it proposes which tables to include, how they join, and which dimensions and measures to define. Credible's [open-source agent skills](/docs/introduction#one-set-of-skills-every-surface) guide it to follow Malloy best practices. The same skills run on every surface, so the workflow is identical in the app and in your IDE.
3. **Confirm and iterate.** Approve or adjust each proposal in plain language, and the agent writes the model — every field defined, documented with `#(doc)`, and indexed with `#(index)` where it helps discovery. In the app, the agent previews queries in the chat so you see real results at each step; in your IDE, review the generated `.malloy` files and approve the changes.
## Validate as You Build
Preview results against real data before you publish:
- **In the app** — the agent runs queries against the draft package and shows results in the chat; open the draft at any time to browse the generated files
- **In your IDE** — use the buttons above each source definition: **Schema** to view the compiled structure, **Explore** to interactively query in the [Explorer](https://docs.malloydata.dev/documentation/user_guides/publishing/explorer), and **Preview** for a quick data check
## Next Steps
Continue through the stages, or jump straight to publishing your first model:
Document and index your model so agents find and understand your data
Make your model available on every surface
---
# Connect a Database
Source: https://www.credibledata.com/docs/how-to/modeling/connect-data
A **connection** is a secure, managed link to a database or warehouse. Connection configurations are stored in a Credible [environment](/docs/how-to/modeling/environment-overview), and every package in that environment can use them. Credentials never leave the Credible service — all access, for modeling and for serving, is proxied through the engine, making Credible a secure perimeter around your databases.
Credible supports **BigQuery, Snowflake, PostgreSQL, Trino, Databricks, MySQL, DuckDB, MotherDuck, and DuckLake** — and, through DuckDB, **flat files in object storage**: CSV, Parquet, and JSON in GCS, S3, or Azure Data Lake, read in place. Spreadsheets (`.xlsx`) and CSV or Parquet files can also ship inside a package as [embedded data](/docs/how-to/developers/embedded-data). You don't need a warehouse to start: connect data where it already lives, and the engine brings the query engine and the storage.
## Prerequisites
- **Admin access** to an organization, in order to create environments and connections. When you create your own organization you're its admin; if you've been added to an existing one, ask your organization administrator to set connections up for you.
## Setup Process
### Credible App (Recommended)
1. **Access your organization** at `https://your-org.app.credibledata.com`
2. **Select your environment** from the left sidebar under **Packages & Connections**
3. **Click "+ Add Connection"** in the Connections section
4. **Choose your data source type** and fill in the connection details:
Connection names cannot contain spaces or hyphens. Use underscores instead
(e.g., `my_connection`).
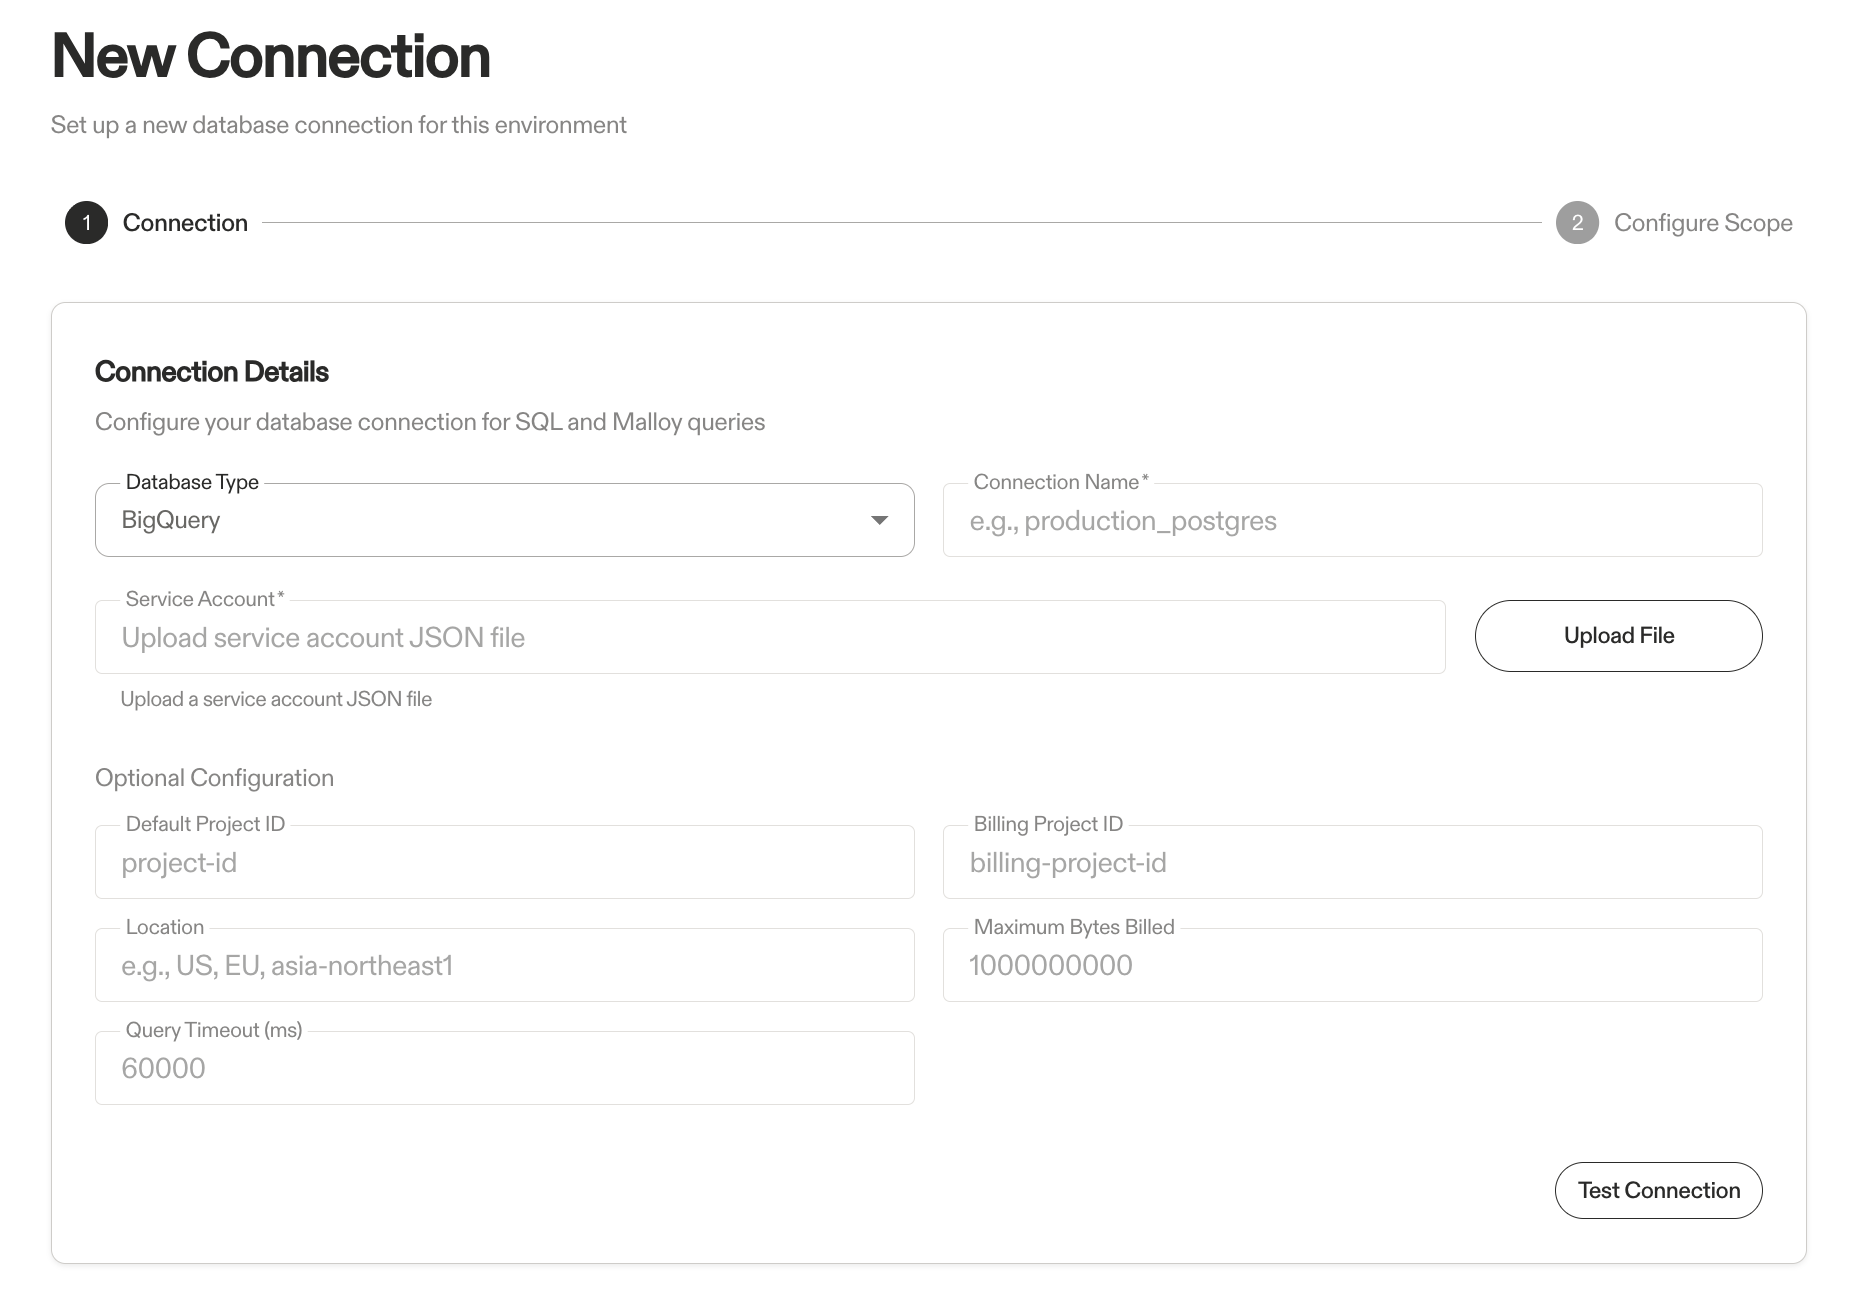
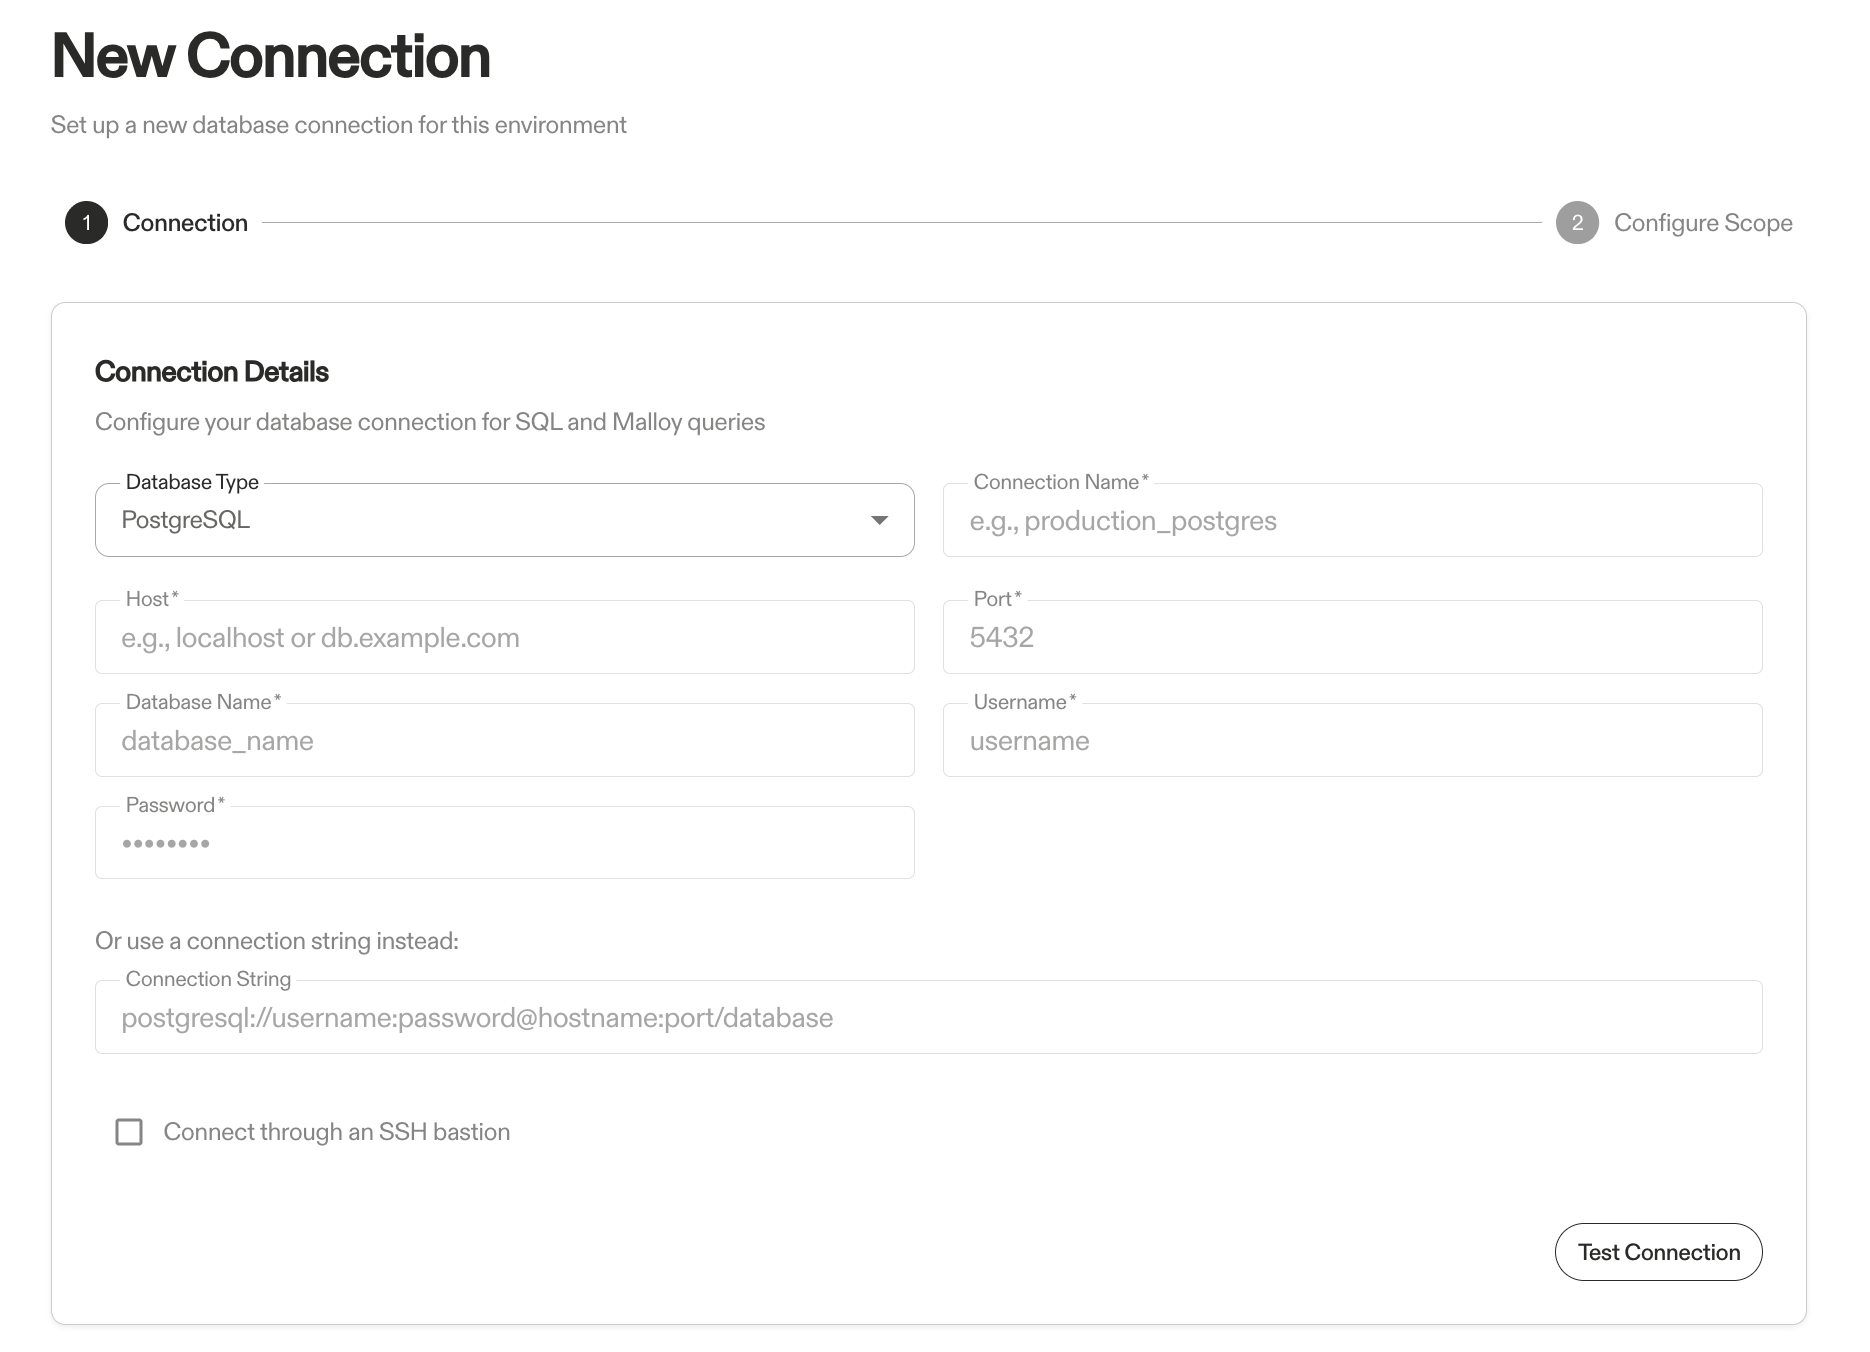
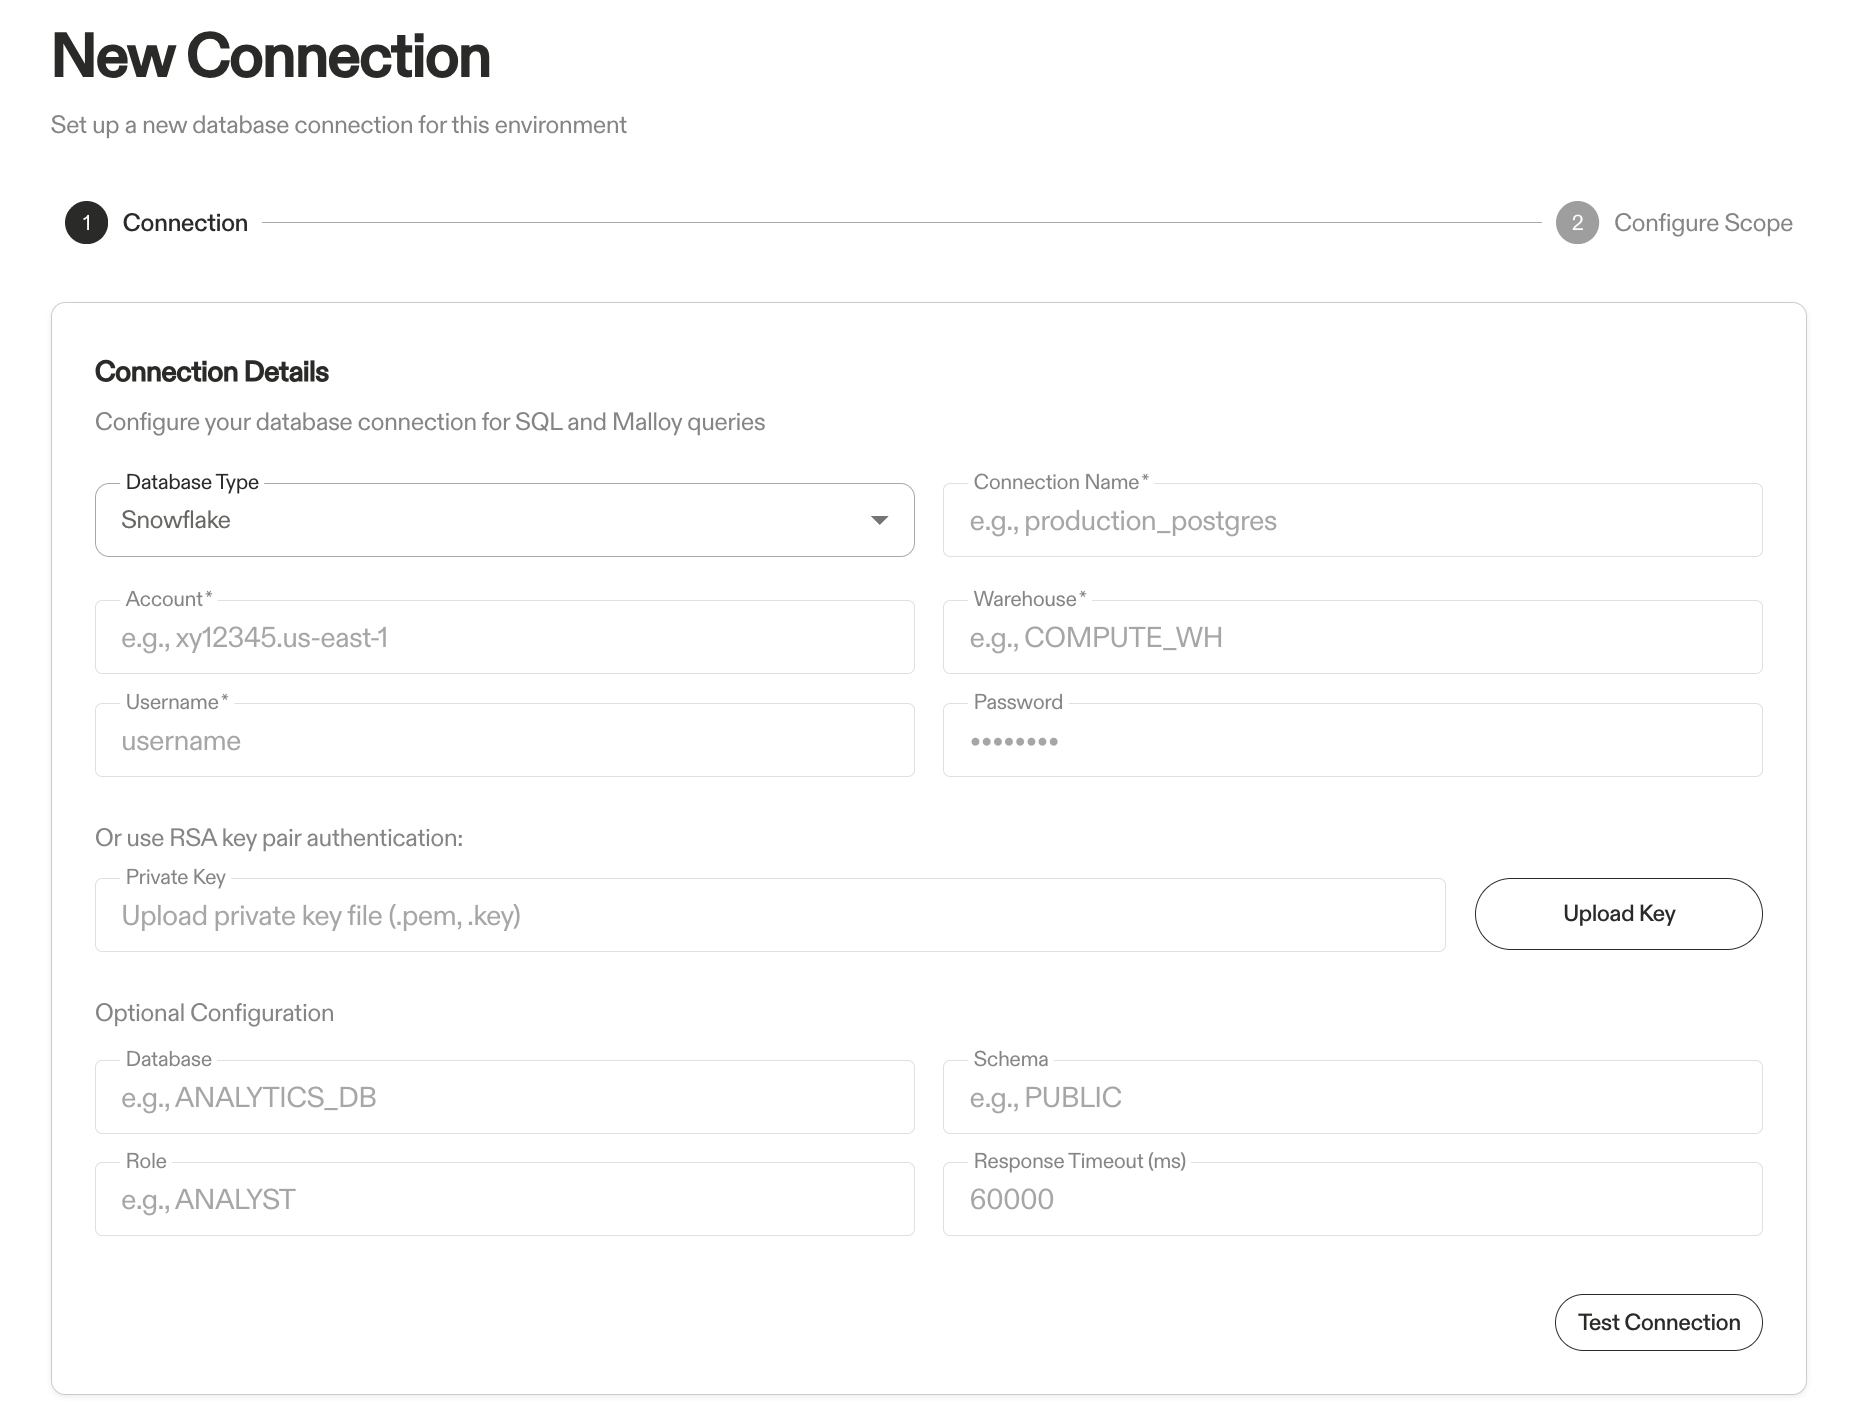
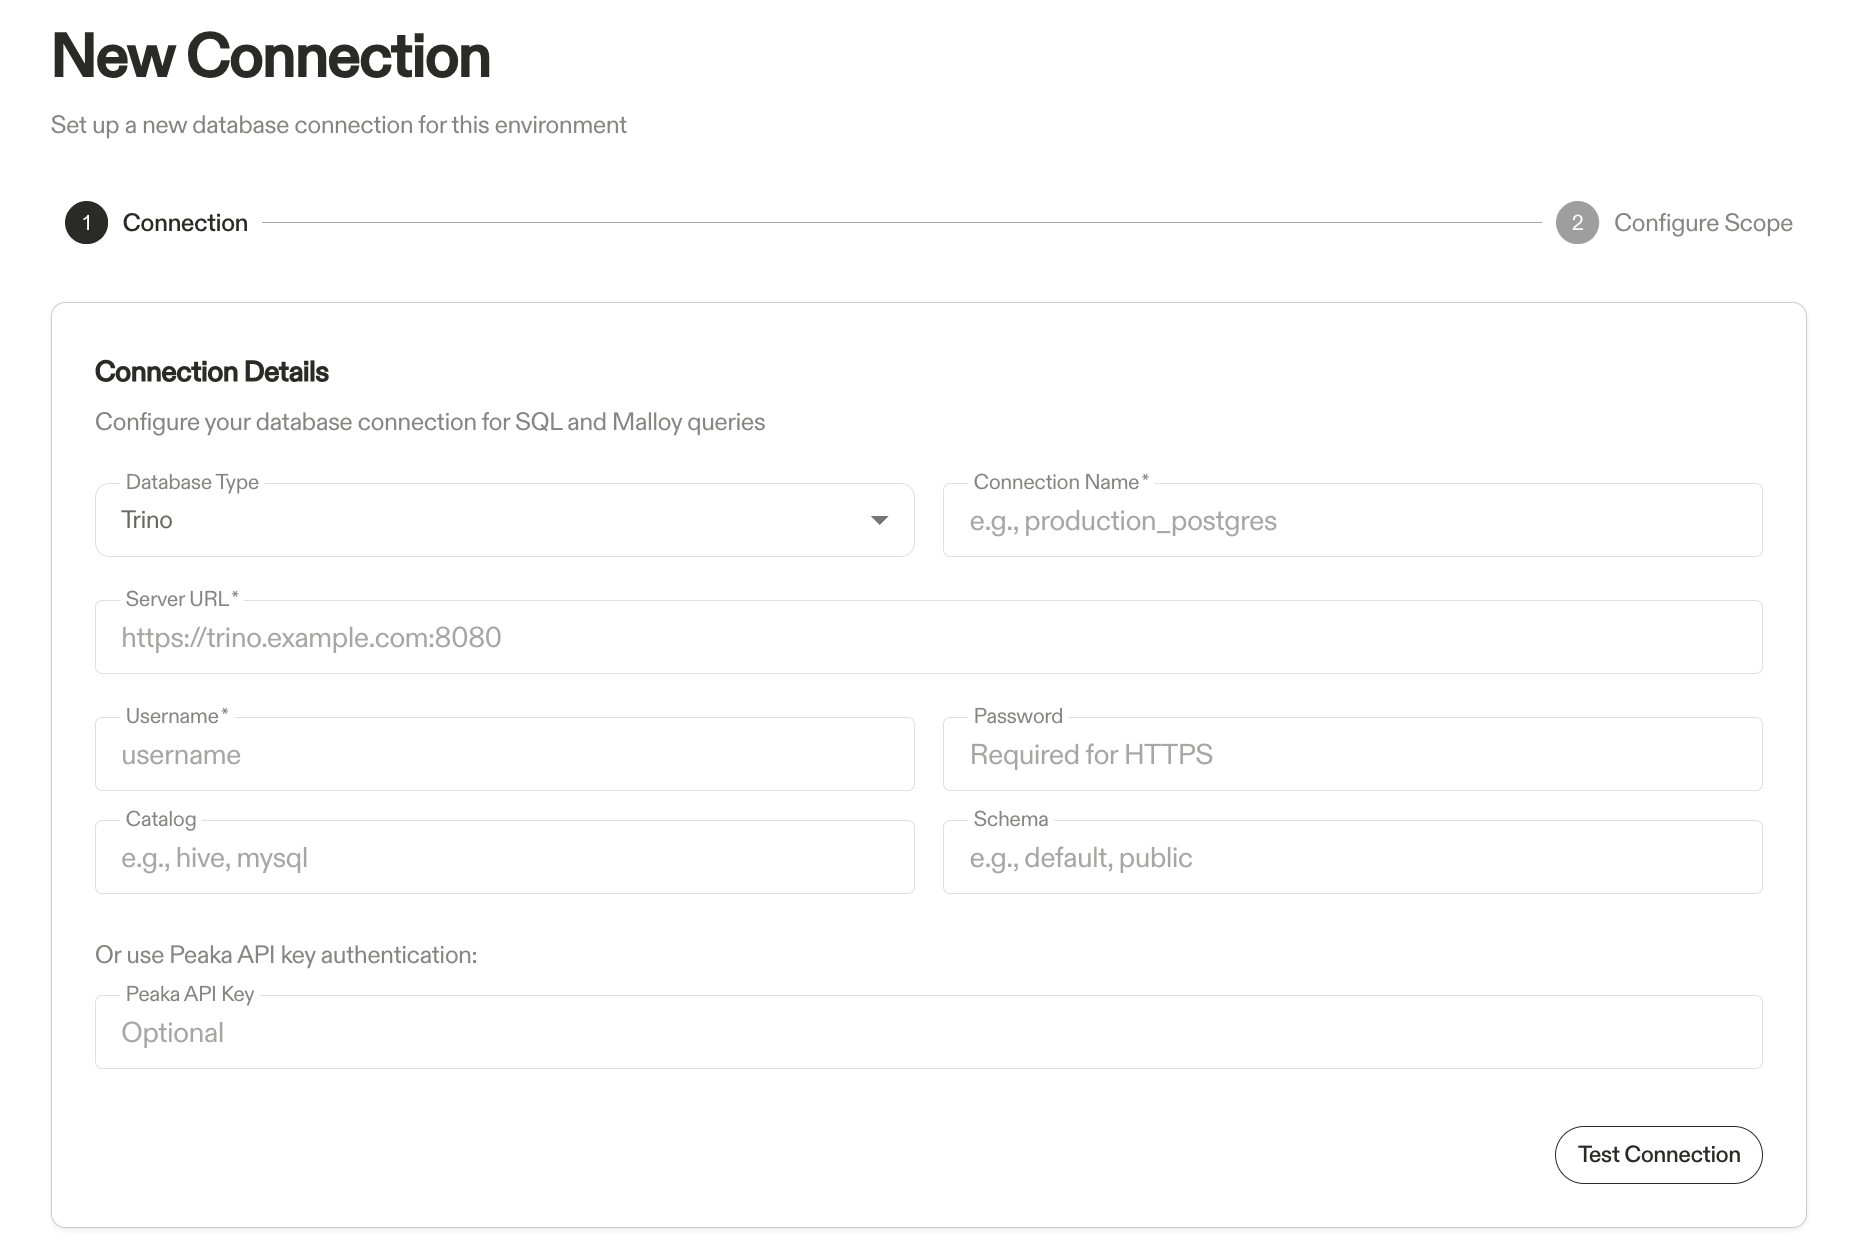
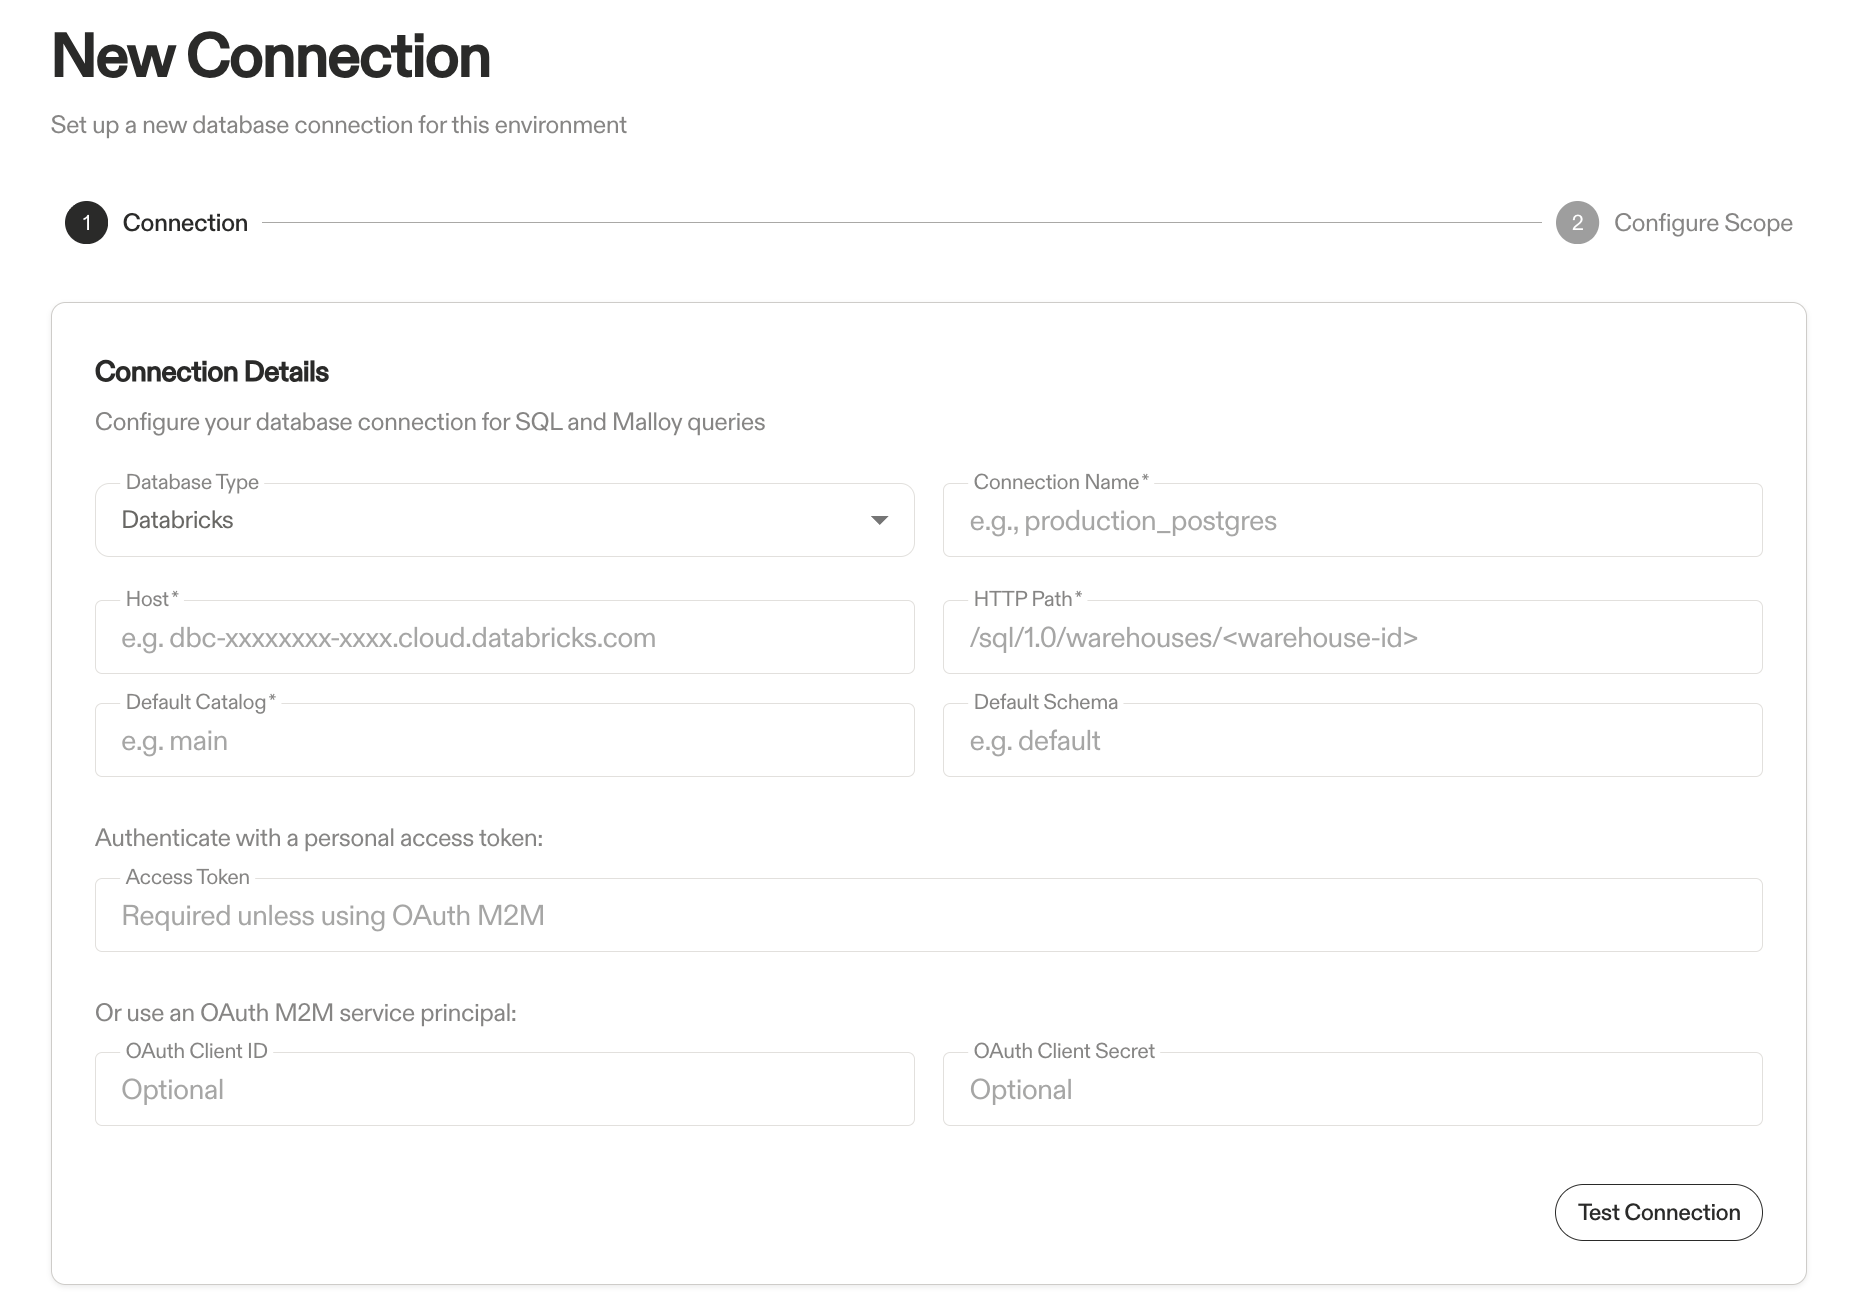 **Required:**
- Connection name
- Host (e.g., `dbc-xxxxxxxx-xxxx.cloud.databricks.com`)
- HTTP Path (e.g., `/sql/1.0/warehouses/`)
- Default Catalog (e.g., `main`)
**Authentication (choose one):**
- **Personal Access Token** - paste a Databricks PAT
- **OAuth M2M** - service principal Client ID + Client Secret
**Optional:**
- Default Schema (e.g., `default`)
See the [Databricks connection reference](/docs/reference/connections/databricks) for details on creating a SQL warehouse, generating a PAT, or configuring an OAuth M2M service principal.
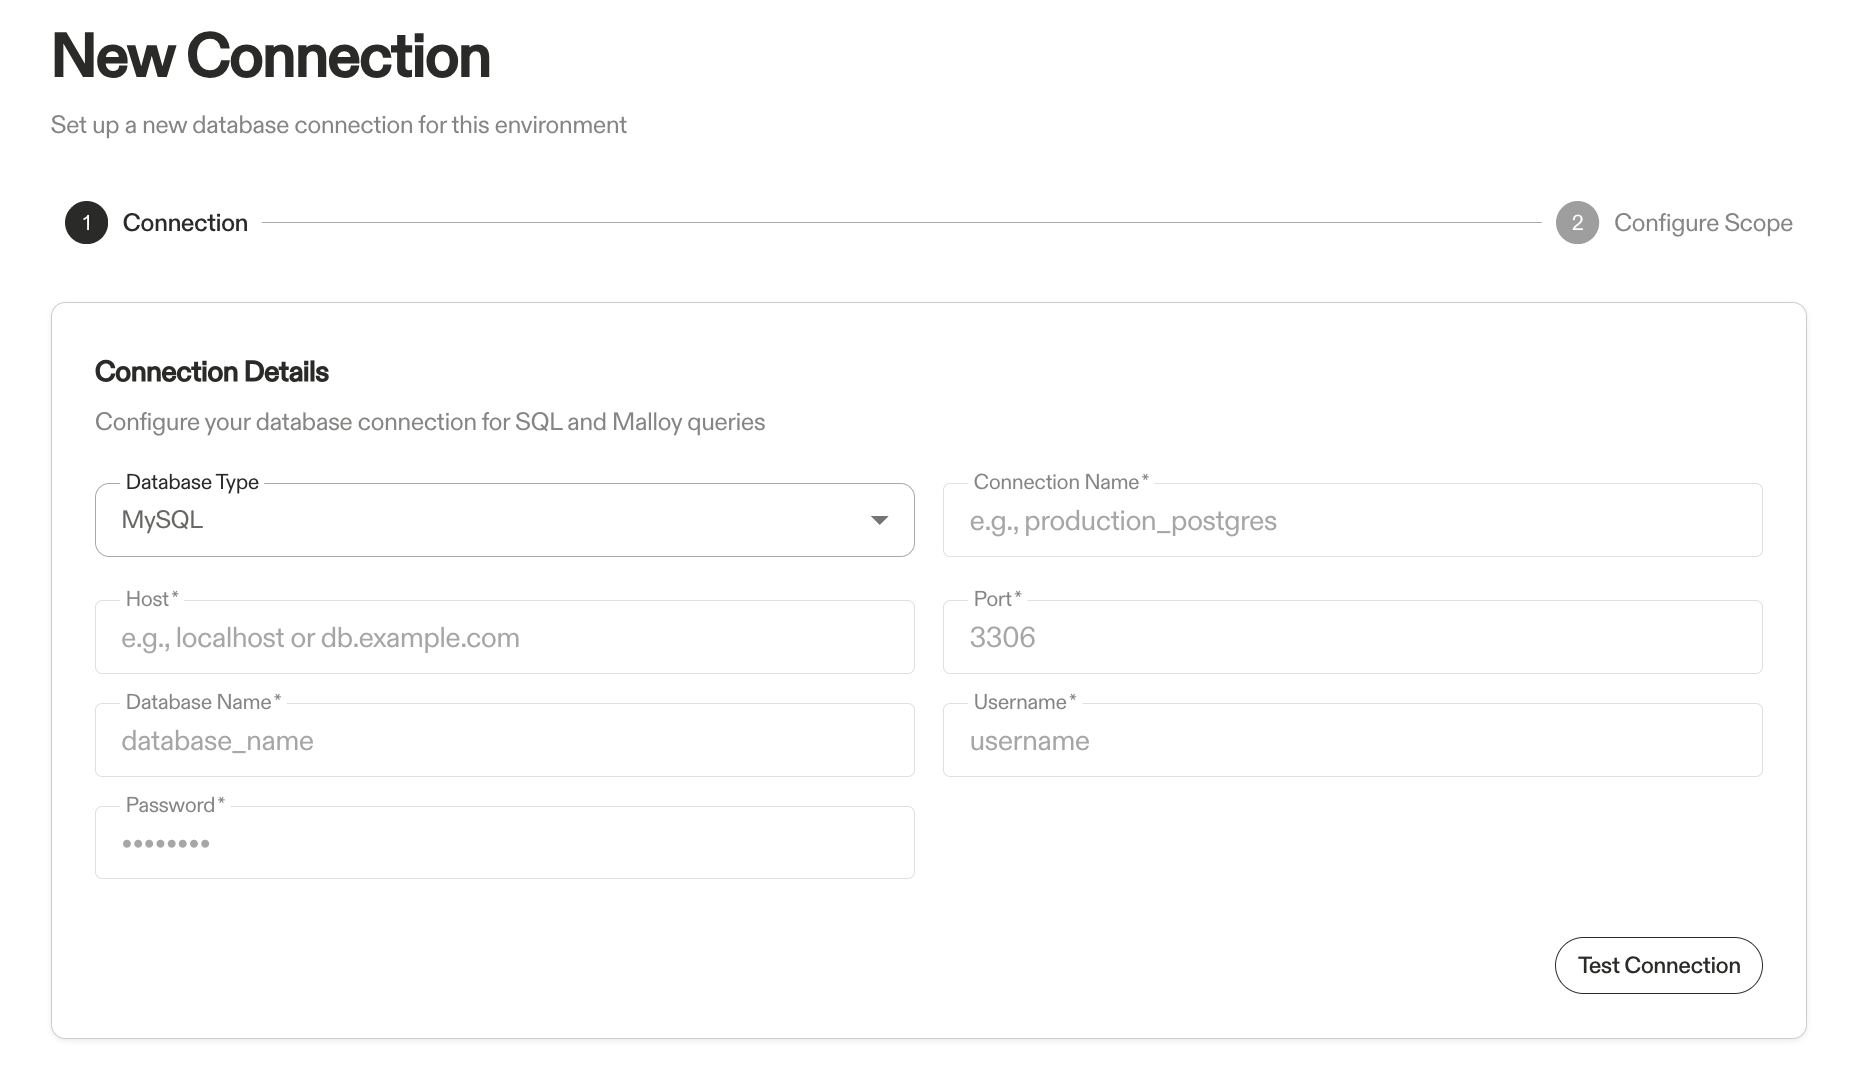
 DuckDB runs in-process and can attach to external databases (PostgreSQL, BigQuery, Snowflake) and object storage (GCS, S3, Azure). Files in a bucket — CSV, Parquet, JSON — are read in place, as a single file, a directory glob (`path/*.parquet`), or a whole subtree (`path/**`), and can be joined with the attached databases in one model. With no attached databases it runs in standalone mode — useful for working with embedded data files (CSV, Parquet, `.xlsx`) included in your packages.
 MotherDuck is a serverless cloud analytics platform built on DuckDB. Get your access token from your [MotherDuck account settings](https://app.motherduck.com/).
 DuckLake needs two backing connections: a **catalog** for metadata (currently PostgreSQL) and **storage** for data (S3 or GCS). Configure both, then test the connection.
5. **Test the connection**
6. Click **Next: Configure Scope**
### Configure Scope for AI-Assisted Modeling
Next, select which schemas and tables to index for AI-assisted modeling:
 - Browse schemas on the left, select tables on the right
- Use **Select All** to include all tables in a schema, or pick individual tables
- Check **"Do not include any tables for AI-assisted modeling"** if you only need the connection for manual queries
These indexing limits apply to AI-assisted model creation:
- **100 tables per schema** for metadata indexing
- **25 tables or fewer** for automated join inference
You can manually write Malloy models for any size dataset. Published models are indexed separately for analysis.
Click **Update Connection** to save. You'll see an indexing status page confirming the connection is being indexed:
 ### CLI Option
Use the Credible command-line tool for programmatic connection management and automation.
1. **Install the CLI**:
```bash
npm i -g @credibledata/cred-cli
```
2. **Login to your organization**:
```bash
cred login
```
3. **Add a connection**:
```bash
cred add connection
```
The connection file should be a JSON file containing an array of connection objects. See the [CLI reference](/docs/platform-admin/cli) for detailed connection file formats and examples.
4. **Configure scope** (optional): Control which tables are indexed for AI-assisted modeling with scope flags on `cred add connection`. Tables are referenced as `{dataset/schema}.{table}`, and `*` matches all tables in a schema:
```bash
# Index only the sales schema and one finance table
cred add connection connections.json --include-tables "sales.*,finance.orders"
# Index everything except temporary and backup data
cred add connection connections.json --exclude-tables "temp_data.*,backup.records"
# Create the connection without indexing any tables
cred add connection connections.json --skip-indexing
```
`--include-tables` and `--exclude-tables` are mutually exclusive (and cannot be combined with `--skip-indexing`).
Scope flags apply at connection creation. To change the scope of an existing connection, edit it in the Credible App (see [Configure Scope](#configure-scope-for-ai-assisted-modeling) above).
## Next Steps
With your data connected, pick how you want to build models:
Build models with the agent in your browser — no setup, recommended to start
Build in your IDE with your preferred coding agent
---
# Environments
Source: https://www.credibledata.com/docs/how-to/modeling/environment-overview
An **environment** is a container within your organization for the two building blocks of a governed data experience:
- **Packages** — versioned data models, plus the reports, dashboards, and data apps built on them.
- **Connections** — secure, managed links to the databases and warehouses those packages read from.
Environments are **stable, governed resource configurations**. They change deliberately — through modeling and publishing — and are the foundation your team analyzes *against*, not where analysis happens. Analysis happens in [workspaces](/docs/how-to/analyzing/workspaces), which consume the models an environment publishes.
## Where an Environment Fits
```
Organization
├── Environment: analytics
│ ├── Connections → secure links to your databases
│ │ └── warehouse (→ snowflake.com)
│ └── Packages → published data models + apps
│ └── sales-model
│ ├── v1.2.3 (versions)
│ └── v1.2.4 (latest)
└── Workspaces → where analysis happens
└── consume published packages
```
Two properties do most of the work:
- **Connections are shared.** Configure a data source once and every package in the environment can use it. Credible indexes each connection's schema so AI agents can discover tables and suggest models. See [Connect a Database](/docs/how-to/modeling/connect-data).
- **Packages are versioned.** Every publish creates a new immutable version. Pin one as **latest**, or publish unpinned to test before promoting. See [Publishing](/docs/how-to/modeling/publishing).
## Common Patterns
Teams typically organize environments around a **department** (finance, HR, RevOps — each owning its own data and models), around **delivery stages** (dev, staging, production, plus private per-developer sandboxes), or a **hybrid** of the two. See [Best Practices](/docs/platform-admin/environments-packages) for these patterns in detail.
## Your Credentials Stay Secure
An admin stores database credentials in the environment once; no one needs to handle them again:
- **No local credentials.** Developers and modelers SSO into Credible and use the environment's managed connections — nothing is stored on their machines.
- **All access is proxied.** Every request to the underlying data — from an IDE, the in-app agent, a workspace, or an API — goes through Credible, never directly to your database.
- **Access-controlled and audit-logged.** Every request is checked against the environment's ACLs and recorded in an audit log.
This makes Credible a secure perimeter around your data — grant analysts, partners, or applications governed access to your models without ever exposing a credential.
## Environment Roles
Grant access to an environment with one of three roles, assigned to users or groups. A role applies to every package in the environment; you can also grant narrower access on an individual package.
| Role | What they can do |
| --- | --- |
| **Admin** | Full control — manage connections, packages, and sharing, and grant access to others. |
| **Modeler** | Build and publish packages. Modelers can list and use the environment's connections, but cannot see or update connection configurations — credentials stay with admins. |
| **Viewer** | Read and query published packages (for example via workspaces or the [MCP tools](/docs/how-to/analyzing/ai-assistants-mcp)), without modeling access. |
For the full permission model — organization roles, groups, and package-level sharing — see [Users & Groups](/docs/platform-admin/groups-permissions) and [Permissions](/docs/platform-admin/permissions).
## Environments vs. Workspaces
The **stable foundation**. Holds governed packages and connections. Changes
through deliberate modeling and publishing. Managed by admins and modelers.
Where **work happens**. Team members chat with data, build reports and data
apps, and explore & iterate on published models. Consumes what environments
serve. See [Analyze Data](/docs/how-to/analyzing/workspaces).
## Next Steps
First connect your data, then pick how you want to build:
Add a managed connection to your environment
Build models with the agent in your browser — no setup
Build in your IDE with your preferred coding agent
---
# Access Control
Source: https://www.credibledata.com/docs/how-to/modeling/fine-grained-acls
Your model is built and documented. This page is about the next stage: **securing your modeled data** — controlling who sees which sources, rows, and columns, with annotations in the model itself. Fine-grained access control lives in your Malloy models and is enforced on every query. While [resource permissions](/docs/platform-admin/permissions) control access at the environment and package level ("can you see this package?"), fine-grained ACLs work at the source level, in three layers:
1. **Row scope** — which rows do they see? Filter with a `where:` clause over a secure given.
2. **Source access** — can this caller query the source at all? Gate it with `#(authorize)`. When the expression reads a row field it scopes rows instead — see [Row-level `#(authorize)`](#row-level-authorize).
3. **Column scope** — which fields are exposed? Restrict them with `include` blocks and access modifiers, and gate sensitive columns with a separate `#(authorize)` source.
Row scope and source access decide access from **secure givens**. [Givens](https://docs.malloydata.dev/documentation/experiments/givens) are a Malloy language construct — named values a model declares once and receives at query time, referenced with `$`. A **secure** given is one Credible fills server-side from the caller's verified identity — their email — so a caller cannot forge it. Column scope builds on the same `#(authorize)` gate. If you need identity resolved from something other than email, [reach out](mailto:support@credibledata.com).
Fine-grained access control and audit logging are part of the [Enterprise plan](/pricing). Access is defined in the model and enforced at the gateway on every query, from every surface.
## In the Model, Not the Warehouse
Fine-grained access control is an industry-standard capability — data warehouses offer it too, as row access policies in Snowflake or row-level security and policy tags in BigQuery. But warehouse controls attach to the **operational shape of your data**: physical tables and columns, expressed in each warehouse's own policy language.
Credible attaches the same fine-grained controls to your **data model — the interface to your data** — which is simpler, makes more sense to admins and agents, and is far easier to manage:
- **Rules live with meaning, versioned like code.** The source that defines what `orders` *means* also defines who sees which orders — reviewed in Git, published with the model, and rolled back with it, never drifting in a separate policy catalog.
- **Write once, enforced everywhere, portable.** One rule applies identically across workspace chat, MCP agents, dashboards, and data apps, and isn't written in any warehouse's policy syntax — so it survives a warehouse migration.
This is separate from **discovery curation** (`explores` / `queryableSources` in [`publisher.json`](/docs/how-to/modeling/metadata-tags#curating-discovery)), which controls *which* sources are listed and queryable by name — not *who* may query them.
## Row Scope: Secure Givens
Scope rows with a `where:` clause over a **secure given** — a `given:` Credible populates from the caller's verified identity. Givens are declared at the top of the model (not inside a source) and referenced with `$`. Mark a custom given `#(secure)` and declare it **set-valued** (`string[]`), then filter with a membership test (`in`) — secure givens are set-valued by design (a scalar secure given isn't enforced).
```malloy
given:
#(secure)
ALLOWED_TENANTS :: string[]
source: orders is conn.table('orders') extend {
// Each caller sees only the tenants Credible grants them
where: tenant_id in $ALLOWED_TENANTS
measure:
order_count is count()
}
```
The given's values aren't in the model — they're a **lookup table** you manage on the [Access Control page](/docs/platform-admin/permissions#access-control). Each row grants a **user** (by email), a **group**, or **everyone** (a default) a list of values — the literal data values your `where:` compares against (here, `tenant_id` values).
At query time Credible takes the caller's verified email, resolves their groups, and **merges every applicable row into one set**: a group grant is a floor shared by all its members, and individual users can be topped up with extra values. A caller with no applicable row resolves to an empty set, which matches nothing — access fails closed.
For the example above: grant the `support` group `["acme"]` and alice@yourco.com `["globex"]`, and Alice — a member of `support` — resolves `$ALLOWED_TENANTS` to `["acme", "globex"]` and sees both tenants' rows, while her teammates see only `acme`'s.
A request made with an [API key](/docs/how-to/integrating/apis) resolves the same way from the key's group. That is how a product embedding Credible scopes each tenant — one group and key per tenant, with the tenant's values granted to the group — with nothing to reimplement in application code; see [Tenant Isolation for Embedded Products](/docs/how-to/integrating/apis#tenant-isolation-for-embedded-products).
Referencing a custom secure given in a published model is also how Credible learns it exists — the attribute appears on the Access Control page once a model gates on it — so declaring `#(secure) ALLOWED_TENANTS` is only half the setup; assigning values is the other half.
`$GROUPS` is built-in — declare `GROUPS :: string[]` in the model (no `#(secure)` needed), and Credible fills it with the **names of the groups** the caller belongs to in your organization (the same groups you manage in [Users & Groups](/docs/platform-admin/groups-permissions)), with no Access Control assignment needed.
The values are literally the group names, matched against your data **exactly, including case** — a group named `West` won't match a `west` value. So filtering on `$GROUPS` means naming groups after your data values: to scope rows by region, create a group per region (`west`, `east`, …), add each user to their regions, and filter with a membership test:
```malloy
given:
GROUPS :: string[]
source: sales_by_group is conn.table('sales') extend {
// $GROUPS is the caller's group names: a user in groups 'east' and
// 'west' sees rows where region = 'east' or region = 'west'
where: region in $GROUPS
measure:
revenue is sum(amount)
}
```
A `where:` clause is the default way to scope rows. There is a second way — an `#(authorize)` annotation whose expression reads a row field — but reach for it only when the rule should surface as *access policy*. See [Row-level `#(authorize)`](#row-level-authorize).
## Source Access: `#(authorize)`
Gate whether a caller can query a source at all with `#(authorize)`, an annotation on its own line directly above the `source:` line, carrying an unquoted, ordinary Malloy boolean expression over the model's givens. A source with no `#(authorize)` is unrestricted; a source may declare **at most one** — publishing refuses a source that declares a second. Spell OR inside the expression itself rather than stacking annotations. Any legal Malloy boolean expression is a legal gate — there's no allowlist of accepted shapes; see [Row-level `#(authorize)`](#row-level-authorize) for what that covers. Where the annotation may sit, and which sources it reaches, are covered in [Which sources `#(authorize)` covers](#which-sources-authorize-covers) below.
```malloy
given:
GROUPS :: string[]
// Only members of the 'support' group (the team granted the acme tenant
// above) can see ticket details — refund notes, customer conversations
#(authorize) 'support' in $GROUPS
source: support_tickets is conn.table('support_tickets') extend {
measure:
open_ticket_count is count() { where: status = 'open' }
}
```
The gate can read **any given, not just `$GROUPS`** — including a custom secure given whose values you assign per user or group on the [Access Control page](/docs/platform-admin/permissions#access-control). That lets you grant source access to specific individuals without hardcoding emails in the model:
```malloy
given:
#(secure)
ALLOWED_TENANTS :: string[]
// Only callers whose assigned tenant list includes 'acme' can query this
#(authorize) 'acme' in $ALLOWED_TENANTS
source: acme_orders is conn.table('orders') extend {
where: tenant_id = 'acme'
measure:
order_count is count()
}
```
Assign dana@yourco.com a user-scope value of `["acme"]` and she passes the gate; change or remove the assignment and her access follows — no republish needed.
For a condition too long to read comfortably on one line, point the gate at an ordinary boolean dimension instead of writing the expression on the annotation line: `#(authorize) authorized` above the source, over `dimension: authorized is org_id in $GROUPS` declared inside it. Validation follows the reference through to the dimension it names — a given the dimension reaches is checked exactly as if the gate had written the expression out directly. There's no `internal`/`private` requirement on that dimension; it's an ordinary one.
**Only gate on a secure given.** An `#(authorize)` gate is only as trustworthy as the given it reads:
- **Secure givens can't be forged** — a `#(secure)` `string[]` given, or the built-in `$GROUPS`. Credible fills these server-side from the caller's identity and ignores any value the caller sends. This is your access boundary; gate and filter with `in`.
- **Every other given is caller-supplied** — the caller can send any value and pass the gate. Fine for parameterizing a query, never an access boundary.
### Which sources `#(authorize)` covers
An `#(authorize)` annotation is checked once, on the **entry point** — the source the query runs against. A source the query reaches only through a **join** is not gated on its own; the gate never fires on a joined source.
```malloy
#(authorize) 'finance' in $GROUPS
source: margins is conn.table('margins') extend {
measure:
total_margin is sum(margin)
}
// Derived from margins, so it carries the same gate: finance only
source: margins_by_region is margins extend {
dimension: region is upper(sales_region)
}
// Declares its own gate, which replaces the inherited one: exec only
#(authorize) 'exec' in $GROUPS
source: margins_exec is margins extend {}
// NOT gated. The join does not carry margins' gate, so anyone who can
// query orders can read total_margin through it
source: orders is conn.table('orders') extend {
join_one: margins on product_id = margins.product_id
}
```
Four rules follow:
- **`extend` and a plain alias inherit, and a source's own gate replaces the inherited one.** `source: child is margins`, with no gate of its own, carries `margins`'s gate unchanged; `margins_exec` above declares its own and that replaces it entirely. This is how you deliberately tighten or loosen a derived source.
- **A query-source derivation is additive, not a replacement.** `source: child is margins -> { ... }` always carries `margins`'s gate — whether or not `child` also declares its own `#(authorize)`. The two combine with **AND** rather than the child's own gate replacing the base's, so a query-source derivation can only add restrictions on top of what it derives from, never drop one by re-declaring its own.
- **Joins carry nothing.** Reaching a gated source through `join_one:` / `join_many:` does not bring its gate along — at any depth, aliased, cross-file, or as a composite member. So joining sensitive data into an ungated source publishes it: above, anyone who can query `orders` reads `total_margin`. Keep gated sources out of the join graph of ungated ones.
- **A composite run target resolves precisely.** When the run target is a composite source, Malloy resolves it to exactly one member branch per query, and that branch's own gate — plus whatever it derives from — applies.
Where a query does collect gates from more than one source — down a derivation chain, or from the [composite](https://docs.malloydata.dev/documentation/experiments/composite_sources) branch Malloy resolved — every one of them must pass (AND). A single source declares at most one `#(authorize)`, so there is no stacking to OR within one source; spell an OR inside the expression itself.
**Where the annotation may sit.** A gate attaches to the one source declaration it is written on. Written anywhere else it silently protects nothing, which is exactly the fail-open case publishing refuses rather than risk: the load is rejected, naming the position, instead of serving a source the author believes is gated.
| Placement | Valid? | What it does |
| --- | :---: | --- |
| Above a standalone `source:` | ✅ | Gates that source. |
| On an item in a multi-definition `source:` block | ✅ | Gates that one item; a sibling with no annotation of its own is left ungated. |
| Above the `source:` keyword of a multi-definition block | ✅ | Gates **every** item in the block, not just the first. Worth knowing before you put a narrow gate there. |
| On a `dimension:`, `measure:`, `join_one:`/`join_many:`, or `view:` line | ❌ | `#(authorize)` only gates from the `source:` line — it is never enforced from inside the source. Refused at load, naming the position. Split sensitive fields into their own gated source instead (see [Column Scope](#column-scope-restricting-fields)). |
| On a top-level `query:` | ❌ | Put the gate on the source the query reads, not on the query statement. Refused at load, naming the position. |
| At the file level — `##(authorize)` (two hashes) | ❌ | A withdrawn feature that once applied model-wide. Declare `#(authorize)` on each source it was meant to protect instead. Refused at load. |
The block form, where a gate stays on its own item and does not reach a sibling:
```malloy
source:
#(authorize) 'finance' in $GROUPS
margins is conn.table('margins'),
// A sibling in the same block. The gate above does NOT reach it
volumes is conn.table('volumes')
```
**Write the tag exactly `#(authorize)`.** Malloy routes an annotation by its literal prefix: a miscased or malformed spelling — `#(AUTHORIZE)`, `#authorize`, a space before the `(`, or a stray space inside the brackets — never reaches the gate at all. That is refused at load, naming the malformed annotation and the exact fix, rather than serving the source unrestricted with no warning.
A gate lives in the model and nowhere else — an `#(authorize)` in caller-submitted Malloy is rejected, so no caller can introduce, replace, or relax one. To test a gate you are writing, save it to the model file, reload the package, and run a query — supplying the givens yourself through the notebook's Parameters panel or a `givens` map. Locally you set `$GROUPS` and any secure given by hand, and Publisher trusts whatever you send, so you are simulating an identity rather than enforcing one; once published, Credible fills those givens from the caller's real identity and ignores any caller-supplied copy.
**`#(index)` value search does not work on an access-controlled source.**
`#(index)` opts a dimension's *values* into [value search](/docs/how-to/modeling/metadata-tags#value-indexing), letting an agent search the column's actual contents. That search runs against one shared index, not a per-caller query — so on an access-controlled source the values are withheld from **every** caller, even one who would pass the gate. A source is access-controlled if it carries any of:
- an `#(authorize)` gate
- a `#(secure)` given, or the built-in `$GROUPS`
- a given whose **name** any source in your organization marked `#(secure)` — that name is reserved org-wide and filled server-side, so even an unmarked `ROLE :: string[]` here is access-scoped
The source itself still appears in `get_context` — its schema, fields, and access-gated status are visible — and a caller reads the values they are authorized for by querying the column with `execute_query`. Only the pre-built value search is off.
If value search matters for a column, keep it on a source with no access control and gate a sensitive companion separately — the same split shown under [Column Scope](#column-scope-restricting-fields).
**Materialization** is partly available on a gated source. A colocated `#@ persist` builds and serves: the build copies the source's own rows and never evaluates the gate, and the gate is still applied per request as a filter over that copy — so the caller's identity and the gate both stay live. What it costs is *freshness*, since the column values the gate reads are frozen until the source rebuilds. `storage=` and `#@ preaggregate` are still refused — the first serves its table to every caller carrying no gate, the second rolls up past the column the gate reads — as is a gate reached only through a join. See [Performance & Cost](/docs/how-to/modeling/persistence#deciding-what-to-persist).
### Row-level `#(authorize)`
Most `#(authorize)` expressions compare only givens and literals, deciding access to the whole source — a **whole-source `#(authorize)`**. Reference a **column of the source** instead, and the same annotation becomes a **row-level `#(authorize)`**, narrowing to the rows that column allows.
Both are enforced the same way — as a **filter on the source's rows**, evaluated once at the entry point. The difference is only how much the filter admits: a whole-source gate reads no field, so it admits either every row or none, uniformly for every caller.
```malloy
given:
GROUPS :: string[]
// `cost_center` is a COLUMN of the margins table. Read together with the
// given: "which margins rows may this caller read".
#(authorize) cost_center in $GROUPS
source: margins is conn.table('margins') extend {
measure: total_margin is sum(margin)
}
```
Every caller may query `margins`; each sees only the rows whose `cost_center` is one of their groups. There is no separate annotation for this — the expression decides: reference only givens and literals and you get the whole-source gate; reference a row field and it narrows to the rows that field allows.
**No gate *verdict* returns a 403.** A caller the filter admits nowhere gets **200 with zero rows** — the request succeeds and returns nothing. That is true of a whole-source gate as well as a row-level one, so no gate denial is visible as a status code. If you have a dashboard, alert, or client branch that treats 403 as "denied", it will not see a gate denial at all.
A 403 still means something, just not this: it is either a package-level access denial decided before any gate runs, or a case where the gate itself could not be attached at all — the entry point's own shape dropped or renamed the field the gate reads, or a given the gate names went unsupplied.
**Any legal Malloy boolean expression is a legal gate.** There's no allowlist of accepted comparison shapes — function calls (`upper(region) = $REGION`), `like`, `is not null`, a joined-field reference, and ordinary comparisons combined with `and`/`or`/`not` are all accepted. If you can paste the expression into a `where:` and see what rows it keeps, you can gate with it. A handful of things are refused anyway, because they make the gate unresolvable or meaningless rather than because the grammar is narrow:
- **At most one `#(authorize)` per source.** Declaring a second fails the load, naming both.
- **Every given the gate references must resolve** against the model's own given surface — declared in the gate's own model, or one `import` hop away. This follows a bare dimension reference through too. An unresolvable reference is refused outright.
- **No given the gate references may carry a declared default.** A caller supplying nothing would silently get whatever rows that default admits — declare the given with no default, so a caller must supply one. This applies whether or not the expression reads a row field.
- **An annotation anywhere but directly above a `source:` line is refused**, naming the position — see the placement table above.
Two shapes still load, but with a warning:
- **A gate that references no given at all** (`1 = 1`, or `false`) evaluates identically for every caller — a fixed predicate, not an access rule keyed on identity. (`false` is the deliberate exception: the locked-base idiom, a source nobody reads directly that a curated extension opens up.)
- **A negated membership test** (`not (org_id in $GROUPS)`) filters correctly for a non-empty given, but an *empty* given then matches **every** row instead of none — the opposite of what `in $GROUPS` alone would do with nothing granted. Prefer a positive membership test wherever the rule can be stated that way.
**Match the operator to the given's declared type.** `cost_center in $GROUPS` (a set-valued given with `in`) and `region = $REGION` (a scalar given with `=`/`!=`/`<`/`<=`/`>`/`>=`) are both fine, and only `in` over a set-valued given is a real access boundary — the only givens Credible secures are set-valued, so a scalar comparison filters rows but reads a value the caller could have supplied themselves. Mismatching the two (`org_id = $GROUPS`, a scalar operator against an array-typed given) is **not** caught at publish — it loads and grafts cleanly, then fails every request at query execution with a warehouse type-conversion error. Use `in` for an array-typed given, not `=`/`!=`.
A gate may reference a **joined** field (`` #(authorize) childtable.name in $GROUPS ``) — the one place a gate reaches through a join, since the join is emitted as part of the gated source's own build.
Watch the cardinality. The `join_one` is still a **left** join, but the gate becomes a filter on the joined column — and a parent with no matching child has a null there, which satisfies no comparison. Those rows are dropped rather than surviving with nulls, so the result matches what an inner join would return. Fail-closed, but it changes row counts where an unfiltered left join wouldn't.
**Rows are protected; the schema is not.** A gate filters data, so the source, its field names, and its documentation stay visible to every caller — a caller who matches no rows sees an empty result over a readable schema. This holds for a whole-source `#(authorize)` too, since it is also enforced as a filter: no gate hides a schema. Where the *existence* of a column is itself sensitive, [Column Scope](#column-scope-restricting-fields) — or splitting it into a separate source — is the only answer.
**Row-level gate, or plain `where:`?** Default to the [Row Scope: Secure Givens](#row-scope-secure-givens) approach — a `where:` clause that filters on a secure given — since it is the simpler tool. Reach for a row-level gate when the rule should read as *access policy*: it is reported as the source's `authorize` in introspection, and it survives derivation, since the filter runs inside the base's own build even where a derived source projects the gated column away.
**If a derivation drops the column the gate reads** (`except:`, or a narrowing `accept:` that doesn't re-list it), the grafted filter can no longer resolve, so the request is denied rather than served unfiltered. A source that **declares** the gate gets a publish error; one that only **inherits** it publishes with a warning and denies every request at that entry point, leaving the rest of the package serving. The one residual gap: drop the gated column and then `rename:` a *different* column onto that exact same name, and the graft resolves again — but now against the wrong data, since there is once more a field with the gate's name to bind to. That takes both a drop and a same-name rename, and still denies unless the two columns' values happen to collide, so it's narrow — but real. Don't recycle a gated column's name.
## Parameterization
Not every given is an access control. The same declaration is also how a source exposes a **knob** — a value the caller supplies per query — which is the job the legacy `#(filter)` annotation did.
The mapping is direct: a presentation filter becomes a given of type `filter` whose default `f''` matches every row, so the source behaves exactly as it did until a caller supplies a value.
```malloy
given:
manufacturer :: filter is f''
source: recalls is conn.table('recalls') extend {
where: manufacturer_name ~ $manufacturer
}
```
Callers supply values in the `givens` request parameter. The older `filterParams` parameter targets the `#(filter)` path and is deprecated.
**Two `#(filter)` roles must keep the annotation.** Neither fails loudly, so don't migrate by pattern:
- **`#(filter, required)`** carries index partition metadata a given cannot express — a given has no `required` flag and binds to no dimension. Migrating one leaves the index partitioned on a value nothing supplies, and the lookup returns **zero rows with no error**.
- **`implicit`** filters are row-level security. Their replacement is a `#(secure)` given resolved server-side (see [Row Scope](#row-scope-secure-givens)), not an ordinary one — migrating them as ordinary givens turns an access decision into a value the caller supplies.
A date or number **range** has no neutral literal to default to, so it stays on the annotation too.
## Column Scope: Restricting Fields
Control which fields a source exposes with Malloy's [access modifiers](https://docs.malloydata.dev/documentation/experiments/include) — an `include` block before `extend` that says which fields are part of the source's interface. These are **static** — they can't read a given, so one source can't show a column to some callers and hide it from others.
Say the `orders` table has five columns: `order_id`, `status`, `amount`, `customer_email`, and `credit_card_number`. Either style hides the sensitive ones:
```malloy
// Denylist style: keep everything except the sensitive fields
source: orders is conn.table('orders') include {
except: customer_email, credit_card_number
} extend {
measure:
order_count is count()
}
// Allowlist style — safer for sensitive tables: a column added to the
// table later stays hidden until you opt it in
source: orders_safe is conn.table('orders') include {
order_id, status, amount
} extend {
measure:
order_count is count()
}
```
Both expose exactly `order_id`, `status`, and `amount` — querying `credit_card_number` against either is a compile error, because the field doesn't exist on the source.
Modifiers offer finer grades than in-or-out: prefix a definition with `public`, `internal`, or `private`, or set levels in the `include` block. An `internal` field can't be queried but can still be used in definitions — handy for intermediate calculations. For example, `include { private: *; public: order_id, status, amount }` keeps every field available for computed dimensions while exposing only three. See [Access Modifiers](https://docs.malloydata.dev/documentation/experiments/include) in the Malloy documentation for the full rules.
To expose a column to **some** callers only, split into two sources and gate the full one with `#(authorize)`:
```malloy
given:
GROUPS :: string[]
// Everyone: orders without the sensitive columns
source: orders is conn.table('orders') include {
except: customer_email, credit_card_number
} extend {
measure:
order_count is count()
}
// The billing team only: the same table, all five columns
#(authorize) 'billing' in $GROUPS
source: orders_billing is conn.table('orders') extend {
measure:
order_count is count()
}
```
Callers in the `billing` group query `orders_billing` and see every column, including `credit_card_number`. Everyone else queries `orders`, where the sensitive columns don't exist.
`#(authorize)` gates *querying*, not *discovery* — the gated source still appears in listings (name, fields, docs) to callers who can't query it. To hide it from listings while keeping it queryable for authorized callers, curate it out of discovery with `queryableSources: "all"` — see [discovery curation](/docs/how-to/modeling/metadata-tags#curating-discovery).
---
Have custom access control requirements? [Contact us](mailto:support@credibledata.com) to discuss your use case.
## Next Steps
Materialize expensive sources and index values for performance and search
Configure environment and package-level access
---
# Git-Backed Modeling
Source: https://www.credibledata.com/docs/how-to/modeling/git-backed-modeling
**Git-backed modeling** is a way of working for larger organizations, where analysts, domain experts, engineers, and AI agents across several functions all work on the same data model. It is turned on per environment. Out of the box, a modeler [builds and publishes](/docs/how-to/modeling/in-app-development) straight from the app, and for one person or a small team that is usually all you need.
The case for it starts when a model has many hands on it. Metrics get redefined, new tables arrive, an edge case turns out to matter, and the people who notice first are rarely the engineers who maintain the model. When every change has to be handed to one team and wait its turn, the model falls behind, and people start working around it. When anyone can change it with no record, nobody trusts it.
Git-backed modeling lets the whole team change the model directly, wth a record of every change and a chance to review it before it goes live. An analyst asks for a new metric in plain language. The agent makes the change in a draft. Whoever your team has chosen looks it over, or the author approves it themselves, and the update is published to every dashboard, agent, and data app that uses the model. Every published version shows who changed what and when.
## How a Team Works on One Model
Each group does the part it is good at, and the model stays one governed thing.
- **Engineers** own the model and decide how changes get in. When the team wants a review step, every proposed change comes to them as something they can read line by line, already checked for errors, with the name of the person who asked for it.
- **Analysts and domain experts** ask for what should change, in plain language: a new metric, a corrected definition, a business rule the data alone cannot settle. The agent makes the change in a draft, and it goes through the same path as any other. No Malloy coding experience required to contribute.
- **AI agents** notice what people actually ask for and suggest improvements, such as a clearer description on a field or a view worth adding, as proposals for a person to approve rather than changes that land on their own.
## What You Get
- **Every change is a proposal.** Work happens in a draft that belongs to the person who opened it. The draft has an author, a description of what it changes, and a record of every edit the agent made along the way. Nothing in it touches the published model until it is approved.
- **You decide who approves.** Approving a proposal is what publishes the new version, and your team decides who may approve. Require an engineer's sign-off on every change, or let the person who owns a model approve their own. Either way there is no side door: the published model only changes through an approved proposal, so what your dashboards and agents serve is always something a person signed off on.
- **Changes are checked before they can land.** The agent checks the model as it works, so a change that would break it is caught while it is being written. Reviewers see the result beside the proposal, and a failing change cannot be approved by accident.
- **A complete history.** Every published version records the proposal that produced it, who asked for it, and when. When a number on a dashboard changes, you can trace it to the change and the person behind it.
- **Two people can change the same model without coordinating.** The agent keeps each draft up to date with the shared model as it goes. Most of the time the other person's work does not touch what you touched, and it is absorbed without anyone being asked anything. When it does overlap, the agent reads your version, theirs, and the version you both started from, reconciles them in the chat, and tells you what it did. Nobody is sent to GitHub to untangle a conflict by hand, and if a change breaks the model the agent fixes that in the same conversation.
- **Engineers work where they already work.** Every proposal is also a pull request in GitHub, so engineers review, comment, and approve with the tools they already use. They can pull a draft branch down, edit it in their own editor, and push it back, or start a branch of their own and open their own pull request. Whatever merges to the base branch publishes the same way. Nobody else has to open GitHub.
## Hosted by Credible, or Your Own Repository
The repository is your choice. Credible can host one for you in its managed GitHub organization, so nobody on your team needs a GitHub account and your side of the setup is one toggle. Or bring your own repository and keep models next to the rest of your code. However, we do advise using a dedicated modeling repository, not your monorepo, to keep good isolation.
**Prefer your own editor?** An enrolled environment does not shut you out of one. What it holds is an
ordinary git repository: clone it, branch from it, edit in the editor you already use, and open a pull
request. Merging publishes exactly as a proposal raised from the app does, because it is the same
repository and the same publish path. The two ways of working are the same pipeline, not a choice between
pipelines. If you would rather keep a model outside the app entirely, that is the
[developer workflow](/docs/how-to/developers/overview): files you own, published from your agent, the
[CLI](/docs/platform-admin/cli), or [CI/CD](/docs/platform-admin/cicd).
## Why It Is Different
Most analytics tools that connect to git make it an engineering project before anyone can start: accounts to create, permissions to grant, a repository to set up. Credible makes that a choice rather than a prerequisite. Take the hosted repository and setup is one toggle, or bring your own and get the same way of working on it.
Two things matter more. First, review is a real gate, not a permission. In most tools the only control is who may press publish, which answers "who may ship" but never "should this ship." Here a team can require a person's sign-off on every change, and a team that does not still gets the record and the checks. Second, the people asking for changes never touch the mechanics. The agent writes the code, keeps drafts current, resolves collisions, and fixes errors, so a domain expert improves a governed, versioned model with nothing but a sentence.
## For Engineers: How It Works
Under the hood this is ordinary git, and that is the point. Once an environment is enrolled, every new draft package is backed by a git repository rather than by Credible's document store:
1. **A draft is a branch.** Asking the agent to build or edit a package cuts a branch from the repository's base branch (usually `main`). The package is a top-level directory in the repository; one repository serves the whole environment.
2. **Every turn is a commit.** As the agent edits, each turn lands as a commit attributed to the modeler, so the history reads like a conversation: what changed, who asked for it, when.
3. **Compile on every edit.** The agent compiles as it goes against your live connections, so a draft that will not publish is caught while it is being written, not at merge time.
4. **A pull request carries the change.** When the draft is ready, **Create pull request** opens a PR whose title names what changed. The compile verdict is posted onto its head commit as a check, and the draft panel mirrors the PR's state.
5. **Merge is the publish.** When a pull request merges to the base branch, the package publishes from that merge commit, and the new version records the commit it came from. It does not matter whether the app raised the pull request or an engineer did. For a git-backed package, this is the only way a version gets made.
The loop repeats. After a merge the draft re-cuts from the new base tip, ready for the next change. Fall behind `main` and **Update from main** absorbs the base branch, showing what it brought in. A direct upload over a git-backed package is refused, so a version can never exist without the commit that produced it.
## What to Know Before Enrolling
- **One repository per environment.** Each package is a top-level directory in it. You do not choose or create repositories per package.
- **Text files only.** A package containing a binary file, or a file larger than about 1 MB, is refused up front with the files named. Keep large data in [embedded data](/docs/how-to/developers/embedded-data) or your warehouse.
- **A git-backed package publishes only through a proposal.** Once a package has published from a merged proposal, `cred publish` and CI uploads to it are refused, so a reviewed version is never replaced by one nobody looked at. In environments that are not enrolled, nothing changes.
- **Attribution is permanent.** Each change records the name and email of the person the agent was working for, and history is not rewritten afterwards.
## Set It Up
Start by telling your account team or [support](/docs/community/support) which environment you want on
git-backed modeling and whose repository it will use. What happens next depends on the answer.
**Credible-hosted.** Nothing to do until we write back. We create a private repository for the
environment in Credible's managed GitHub organization, install our GitHub App on it, and send you the
details to enter.
**Your own repository.** Four steps.
It needs at least one commit; an empty repository has no branch for drafts to fork from. Private is
fine, and what we would choose.
Installing a GitHub App needs owner permission on the account or organization, so this step may
belong to someone else. We send you an installation link. Choose **Only select repositories**, not
**All repositories**, and pick the one repository for this environment, so the App can never reach
anything else you own.
On the same page, GitHub lists what the App will be able to do:
- **Contents (read and write)**, to commit each change to a draft branch.
- **Pull requests (read and write)**, to open the proposal.
- **Checks (write)**, to post the compile verdict onto the commit so your branch protection can require it.
- **Metadata (read)**, which GitHub requires of every App.
The App cannot delete your repository. If we ever need more, GitHub puts the request to your account
owner before anything changes.
Send your account team the repository **owner**, its **name**, and the **base branch**. We register
it to your environment and let you know when it is done.
Either way, you finish in the Credible App. Once we have confirmed, open **Manage environment**, turn on
**Git-backed modeling**, enter the owner, repository name, and base branch, and save. From then on every
new draft in that environment is a proposal. Drafts that already exist keep working the way they were
created.
If you brought your own repository, you can require review before anything publishes: protect the base
branch and require the `Credible / draft compiles` check. That is a setting on your repository, not ours.
## Next Steps
The in-app modeling loop this adds review and history to
Versions, promotion, and what a published package contains
Git for models built outside the app, published on merge
---
# Build & Publish
Source: https://www.credibledata.com/docs/how-to/modeling/in-app-development
The Credible App (`https://.app.credibledata.com`) lets you build data models without leaving your browser and without any local setup. Everything happens through a **natural-language agent**: you describe what you want, and the agent connects your data, drafts the Malloy model, previews results, and publishes.
The in-app experience gets you productive fast, with no IDE or CLI coding agent to manage. It handles most modeling workflows with far less setup than a local environment.
**New to Credible? Start here.** When you outgrow the app — or want Git-based workflows and full control over files — move to the [developer tools](/docs/how-to/developers/overview).
## Prerequisites
- **A Credible account** in a Credible organization — create a new organization or get added to an existing one; every account comes with a personal [workspace](/docs/how-to/analyzing/workspaces) to start in
- **A data source** — either a [connection your admin has configured](/docs/how-to/modeling/connect-data), or one you add through the agent's private connection form. No data handy? The form includes a sample dataset to explore with
That's it. There is nothing to install.
## What the In-App Agent Does
In the app, the agent can do everything you do in Credible — build data models, analyze data, build data apps and reports, and manage your environments — all from a single chat. Its behavior comes from Credible's [open-source agent skills](/docs/introduction#one-set-of-skills-every-surface), the same skills that drive local development — so how it models, analyzes, and publishes is consistent everywhere.
This page covers the core build loop — models, data apps, and publishing. Within your environment, the agent can:
- **Connect your data** — set up an environment and connect your warehouse through a private in-chat form; Credible indexes the schema so the agent can find tables by meaning
- **Explore your data** — discover tables, columns, and relationships, and suggest how to model them
- **Build the model** — author fully documented Malloy sources, joins, dimensions, and measures in a **draft package**
- **Preview as it goes** — run queries against the draft so you can validate results before publishing
- **Build data apps and reports** — generate interactive dashboards and data apps that ship alongside the model (see [Building a Data App](#building-a-data-app))
- **Publish and share** — deploy the finished package so it's available everywhere in Credible, and open a sharing panel so you choose who gets access
## Building a Model
1. **Open your workspace.** The agent introduces itself and asks about your data.
2. **Connect your data.** If nothing is connected yet, the agent sets up an environment and opens a **private connection form** in the chat — pick your warehouse type, enter credentials, and choose which tables to index. Credentials go straight to Credible; the agent never sees them. No data handy? The form offers a sample dataset.
3. **Describe what you want to model.** Tell the agent about the questions you want to answer (e.g., "model our orders and customers so I can analyze revenue by region").
4. **Confirm the agent's proposals.** The agent researches before it asks: it explores your schema, then proposes — backed by real data — which tables to include, how sources join, and which dimensions and measures to define. Confirm or adjust each proposal in plain language.
5. **The agent builds the draft.** It writes fully documented Malloy files — every field defined, documented, and indexed for discovery — into a **draft package** you can open from your workspace at any time. It previews queries as it goes, so you see real results at each step.
6. **Review and publish.** The agent presents the model's structure and assumptions for a final review, and can optionally propose access controls and discovery curation. When you're happy, ask it to publish. See [Publishing](#publishing) below.
## Building a Data App
Once you have a model in your draft package, ask the agent to build a **data app** on top of it — an interactive dashboard or application that ships with the package:
1. **Describe the app.** Tell the agent what you want to see — the charts, filters, and layout (e.g., "build a revenue dashboard with monthly trends, filterable by region").
2. **Iterate.** The agent generates the app into the draft package as plain web files in its `public/` directory. Preview it, then ask for changes in plain language — new charts, different breakdowns, styling.
3. **Publish together.** When the package is published, the data app ships with it — governed by the model's access rules, versioned with the model it draws from, and listed automatically in the **Data Apps** section of every workspace the package is added to. Apps can even hand questions back to the in-app agent, so viewers can go from a dashboard number to "why?" in one click.
See [Build Data Apps](/docs/how-to/analyzing/data-apps) for how data apps work and how they're used.
## Publishing
Ask the agent to publish your draft, right from the chat — it packages the draft, deploys it to your environment, and confirms the published version. The agent only publishes when you ask; it never publishes on its own.
After publishing, the engine builds the [concept index](/docs/how-to/analyzing/overview#how-it-works) for your model — usually a minute or two — and it's ready for consumption. You can then:
- Keep going **in the same chat** — ask questions of the published model, or ask the agent to create your first report
- Chat with your model and build reports and data apps in any [workspace](/docs/how-to/analyzing/workspaces) the package is added to
- [Connect your agent](/docs/how-to/analyzing/connect-your-llm) — chat with the model from Claude, ChatGPT, Gemini, or any MCP client
- **Share it** — the agent opens a private sharing panel where you choose which teammates and groups get access (see [Permissions](/docs/platform-admin/permissions))
For versioning details — pinning a version as "latest", testing before promoting, and version history — see [Publishing](/docs/how-to/modeling/publishing).
## Next Steps
Go deeper on modeling — the building blocks and the stages of model development
Move to an IDE for Git-based workflows and full control over your files
---
# Discovery Metadata
Source: https://www.credibledata.com/docs/how-to/modeling/metadata-tags
Your model now defines what your data means. This page is about the next stage: **optimizing it for AI retrieval**. Metadata tags document your model for humans and — through the engine's [concept index](/docs/how-to/analyzing/overview#how-it-works) — make it discoverable to AI agents: when you publish, the engine compresses your `#(doc)` definitions and `#(index)` values into the concept index, searchable by meaning — by people browsing models and by agents answering natural-language questions.
Two tags do the work: `#(doc)` describes what a field means, and `#(index)` makes a dimension's values searchable. A third lever, [discovery curation](#curating-discovery), narrows which models and sources agents see in the first place. This page covers what to tag, index, and curate; for how indexes are built, kept fresh, and paid for, see [Performance & Cost](/docs/how-to/modeling/persistence).
You don't have to write tags by hand: the agent documents as it builds — every field it defines gets its `#(doc)` and `#(index)` tags as part of the [modeling workflow](/docs/how-to/modeling/ai-modeling#build-a-model-with-the-agent) — and you can ask it to document an existing model the same way. Review its work with this page in mind; good documentation directly improves the quality of chat-based analysis downstream.
## Documentation Tags
Use `#(doc)` tags to add human-readable descriptions to fields. Place the tag on the line before the field definition.
```malloy
source: orders is conn.table('sales.orders') extend {
dimension:
#(doc) The unique identifier for each order
order_id is id
#(doc) The date when the order was placed
order_date is created_at::date
#(doc) Customer segment based on lifetime value: High (>$10k), Medium (>$1k), Low
customer_segment is case
when lifetime_value > 10000 then 'High'
when lifetime_value > 1000 then 'Medium'
else 'Low'
end
measure:
#(doc) Total revenue from all orders
total_revenue is sum(amount)
#(doc) Number of orders that have shipped
shipped_orders is count() { where: status = 'shipped' }
}
```
The best `#(doc)` descriptions carry meaning the code can't: units, business rules, thresholds, and caveats — like the segment cutoffs above — not restatements of the field name.
## Value Indexing
Use `#(index)` to index all distinct values from a column, so agents can find fields by searching for data values, not just field names or descriptions.
One exception to know before you tag: on a source carrying an access-control signal — an `#(authorize)` gate, a `#(secure)` given, `$GROUPS`, or a given whose name another source in your organization has declared `#(secure)` — indexed values are withheld from value search for every caller. See [access control and value search](/docs/how-to/modeling/fine-grained-acls#which-sources-authorize-covers).
```malloy
source: products is conn.table('catalog.products') extend {
dimension:
#(index)
#(doc) The product name
product_name is name
#(index)
#(doc) The product category (e.g., Electronics, Clothing, Home & Garden)
category is product_category
#(index)
#(doc) The brand name
brand is brand_name
}
```
### Why Value Indexing Matters
Consider a product catalog where the column is named `product_category` but contains values like "Running Shoes" and "Athletic Apparel". When a user asks *"What are our top-selling sports gear products?"*, field names and documentation alone won't surface those products — nothing is named "sports gear".
With value indexing, the engine searches the actual values in the concept index: it matches the question to fields whose values fit, then helps the agent construct a query with the correct filter — finding "Running Shoes" and "Athletic Apparel" without exact string matching.
### When to Use Value Indexing
Use `#(index)` on:
- **Names and titles** - Product names, customer names, program titles
- **Categorical values** - Status codes, types, categories
- **Lookup values** - Region names, department names, brand names
Skip value indexing for:
- Numeric fields (amounts, counts, IDs)
- Timestamps and dates
## Example: Well-Documented Model
```malloy
source: orders is conn.table('sales.orders') extend {
primary_key: order_id
join_one: customers is conn.table('sales.customers') on customer_id = customers.id
join_one: products is conn.table('catalog.products') on product_id = products.id
dimension:
#(doc) Date the order was placed
order_date is created_at::date
#(doc) Order status: pending, processing, shipped, delivered, cancelled
#(index)
status is order_status
#(doc) Product category from the catalog
#(index)
category is products.product_category
#(doc) Customer's geographic region
#(index)
region is customers.region
measure:
#(doc) Total number of orders
order_count is count()
#(doc) Total revenue in USD
total_revenue is sum(amount)
#(doc) Average revenue per order in USD
avg_order_value is total_revenue / order_count
#(doc) Percentage of orders that were cancelled
cancellation_rate is count() { where: status = 'cancelled' } / order_count * 100
view:
#(doc) Monthly revenue trend with order counts
monthly_revenue is {
group_by: order_date.month
aggregate: total_revenue, order_count
}
}
```
## Curating Discovery
Tags improve how well agents understand what they find; discovery curation narrows **what they find in the first place**. By default, every model is listed and every source is directly queryable. Curation happens at two levels: `export` in the model itself controls which sources a file exposes, and manifest fields control which files agents land on.
### `export { … }` — in the model
[`export { … }`](https://docs.malloydata.dev/documentation/language/imports) filters which *sources within a file* are exposed. A file with no `export` exposes all its top-level sources; add one to keep imported or scaffolding sources out of discovery.
```malloy
// Intermediate building block — hidden from discovery
source: raw_order_lines is conn.table('sales.order_lines') extend {
measure: line_count is count()
}
// The curated interface built on it — this is what agents should find
source: orders is raw_order_lines extend {
measure: order_revenue is sum(amount)
}
export { orders }
```
With the `export`, agents discover `orders` but not `raw_order_lines`; without it, both would be listed.
### `explores` and `queryableSources` — in the manifest
Add optional fields to the package manifest (`publisher.json`, described in [Publishing](/docs/how-to/modeling/publishing#the-package-manifest)) to point agents at the model *files* that matter:
```json
{
"name": "ecommerce",
"version": "0.0.1",
"description": "ecommerce demo data",
"explores": ["orders.malloy", "customer_health.malloy"],
"queryableSources": "declared"
}
```
**`explores`** — `.malloy` file paths (relative to the package root) whose models agents should discover and land on.
- **Omit** — discovery unchanged; every model and source stays listed.
- **Set** — listings narrow to these files, plus each file's `export { … }` closure.
**`queryableSources`** — whether non-curated sources can still be queried by name. Only applies when `explores` is set.
| Value | Listing | Query by name |
|-------|---------|---------------|
| `"declared"` (default) | Curated set only | Non-curated sources return 404 |
| `"all"` | Curated set only | All sources still queryable |
This curates **discovery**, not access — *what* is listed and queryable by name, not *who* may query. To restrict access by user or group, use [`#(authorize)` and secure givens](/docs/how-to/modeling/fine-grained-acls), covered on the next page.
**Hiding an `#(authorize)`-gated source.** An access gate blocks *querying*, not *discovery*, so a gated source still appears in listings to callers who can't query it. To hide it while keeping it queryable for authorized callers, leave it out of the curated `explores`/`export` set **and** set `queryableSources: "all"`. Under the default `"declared"`, the non-curated source returns 404 by name — which blocks authorized callers too.
## Next Steps
Secure your model — row, column, and source-level access rules
Learn how metadata powers AI discovery
---
# Performance & Cost
Source: https://www.credibledata.com/docs/how-to/modeling/persistence
Your model is documented and secured — the last stage before publishing is **optimizing how your modeled data is stored and served, for performance and cost**. Credible maintains managed, derived copies of your data, and you opt parts of your model into them with a single annotation. The engine builds the copy, keeps it fresh, reuses it where it can, and wires it into serving — so your model gets faster, cheaper, and more searchable without you managing any of the machinery.
There are three kinds of derived copy, each opted into at its natural grain:
| Derived copy | Goal | What you opt in | Annotation |
| --- | --- | --- | --- |
| **Materialized table** | Make a source fast and cheap to query | A source | `#@ persist` on the source |
| **Search index** | Make a dimension's values searchable | A dimension | `#(index)` on the dimension |
| **Pre-aggregation** | Make a measure fast and cheap at coarse grains | A measure | `#@ preaggregate` on the measure |
Each is derived from your published model, kept fresh by Credible, and reused automatically.
`#(index)` appears in two stories. For **what to index and how it improves AI retrieval**, see [Discovery Metadata](/docs/how-to/modeling/metadata-tags). This page covers the other side: how the index is built, kept fresh, and served.
## Serving Behavior
A query **serves from a derived copy when one covers it, and otherwise runs live** against the source database. The result is always correct — if a derived copy isn't available yet, or doesn't cover the query, the query is simply slower, not wrong.
- A **materialized table** persists a source's data as a physical table and routes queries to it.
- A **search index** embeds a dimension's values so they are findable by value search, filter suggestions, and the AI agent.
- A **pre-aggregation** stores a measure rolled up to a declared grain and answers queries at that grain, or any coarser one it can correctly re-aggregate to, from the rollup instead of the base source.
## How the Derived Copies Compose
The three features work together automatically, with no extra configuration. If you index a dimension on a source you have also materialized, Credible builds the search index **from the materialized table** instead of re-scanning the warehouse — and reverts to the warehouse if you un-materialize the source. A pre-aggregation on that source is built the same way: from the materialized table when there is one, straight from the warehouse when there isn't.
You can rely on three properties:
- **Consistent** — the index reflects the materialized snapshot, so searchable values match what queries return.
- **Stable** — a table-backed index refreshes exactly when its source table refreshes. An index on a source you have *not* materialized refreshes on publish and on demand, and — if you declare a freshness window — on that window.
- **Cheap** — indexing reuses the table you already built instead of paying to re-scan the warehouse.
The recommended pattern for an expensive, frequently-queried source is **"persist the source, index its dimensions, and pre-aggregate its hot measures."** Credible sequences the work for you so an index or rollup is always built after the table it derives from.
## Deciding What to Persist
Queried often or expensive to compute? Add `#@ persist`.
Values that users or the agent search or filter by? Add `#(index)`.
A hot measure queried at coarse grains? Add `#@ preaggregate` with its grain.
No annotation: queried live from the source database, not searchable.
The annotation alone is the intended usage. Defaults are chosen so the engine can optimize on your behalf — deduplicating copies across model versions and scheduling refreshes to meet a freshness objective. At most, add a freshness window for data with a real staleness requirement.
Two guardrails are enforced when you publish an indexed dimension: it may be partitioned by **at most one required filter**, and it may **not** sit on a source that requires parameters. Both surface as publish-time errors rather than silent wrong answers.
**A gated source can use `#@ persist`, but not the other tiers.** A colocated `#@ persist` on a source carrying an [`#(authorize)` gate](/docs/how-to/modeling/fine-grained-acls) builds and serves normally: the build freezes the source's own relation and never evaluates the gate, and the gate is applied per request as a filter over the frozen copy. The caller's identity and the gate expression both stay live.
Still refused, because in each case no gate would be left to evaluate:
- **`storage=`** — the built table is served to every caller as-is, carrying no gate.
- **`#@ preaggregate`** — a rollup groups away the column the gate reads, so the grain can't express it.
- **A gate reached only through a join** — the source must carry the gate at the entry point callers use. Persist the ungated base instead and let the gated source read through it live.
**What a persisted gated source costs you is freshness, not access.** The gate is re-evaluated on every request, but the *column values it reads* are frozen at build time. So a row that changes hands — a `cost_center` reassigned, an owner changed — keeps serving to its former owner until the source rebuilds.
Bound that with a `materialization.freshness` window plus `fallback: live`: an artifact that ages past the window drops out of serving and the query runs live instead. A gated source with neither a freshness window nor a rebuild cadence is one whose access decisions are as old as its last build.
Three things decide whether that window actually binds:
- **Declare it on the source's own tag** — `#@ persist name="..." freshness.window="24h" freshness.fallback="live"`. Window and fallback resolve independently, per property, per layer, so a package-level `fallback: stale_ok` silently defeats a window set on the source; and a package-wide window forces every *other* persisted source to recompute once stale.
- **`refresh="incremental"` does not bound revocation.** A delta only re-reads rows past the watermark, so a row that changes owner without its watermark advancing is never re-read again — while the source keeps reporting an advancing boundary and reads as healthy. Only a full rebuild recomputes the gating column.
- **A content-identical sibling shares the artifact, and the window.** Reuse is keyed on a content address that folds the connection and the SQL but *not* the source name, so two persist sources whose bodies compute the same SQL resolve to one table carrying one freshness policy. The tightest window any of them declares governs all of them. If two sources need genuinely different windows, give them genuinely different SQL.
## Configuration
### Annotations
Add the annotation to the source, dimension, or measure you want to persist. Options are optional `key="value"` pairs; omit them to accept the default.
```malloy
#@ persist name="orders_fast" refresh="incremental" watermark="order_date" freshness.window="24h"
source: orders is conn.table('sales.orders') extend {
#(index)
dimension: status is order_status
}
```
- `name` — choose where the materialized table lands (optional; container-qualifiable).
- `refresh` — `"full"` (the default) rebuilds the whole copy; `"incremental"` applies only what changed and requires a `watermark` (see [Incremental Refresh](#incremental-refresh)).
- `watermark` / `merge_key` — how an incremental table finds and applies new rows (see [Incremental Refresh](#incremental-refresh)).
- `freshness.window` — the staleness objective the engine schedules against (see [Freshness](#freshness)).
### Package Manifest
Reuse scope and the refresh cadence are declared once for the whole package in `publisher.json` (the same manifest described in [Publishing](/docs/how-to/modeling/publishing)):
```json
{
"scope": "package",
"materialization": { "freshness": { "window": "24h", "fallback": "live" } }
}
```
- **`scope: package`** (the default) — a derived copy is reused across the package's versions whenever they define the same thing. Maximal reuse, lowest cost.
- **`scope: version`** — each version keeps its own copies, with no cross-version reuse. Choose this when you want to own an exact rebuild schedule for a version.
Declare **either** a `freshness` objective **or** an explicit `materialization.schedule`, never both. A fixed schedule is the power-tier option and is only valid under `scope: version`.
## Incremental Refresh
By default (`refresh="full"`) every refresh recomputes the whole table. For a large, append-mostly source — a fact table that grows daily — that means re-reading years of data to add one day. Declare `refresh="incremental"` instead, and each refresh reads only the rows that are new since the last build and applies them to the existing table:
```malloy
#@ persist refresh="incremental" watermark="order_date"
source: daily_revenue is orders -> {
group_by: order_date
aggregate: revenue is amount.sum()
}
```
The whole declaration lives on the `#@ persist` tag — the source body is exactly what you would write with no persistence at all, queries against the source are unchanged, and search indexes are already incremental with no declaration needed.
| Key | Means |
| --- | --- |
| `refresh` | Set to `"incremental"` to advance the table with a bounded delta instead of a full recompute. Requires `watermark`. |
| `watermark` | Names the one output dimension a refresh derives its range from — an event timestamp, an order date, an ingestion time. Its values must be **monotone**: a given row's watermark value never decreases. |
| `merge_key` | Declare this **only when a row's watermark value moves** (e.g., `watermark="updated_at"` on a mutable table). Names the row's stable identity — one or more output dimensions, comma-separated — so a changed row is merged in place of its stale copy instead of appended beside it. |
The three keys form a chain — `merge_key` requires `watermark`, and `watermark` requires `refresh="incremental"` — and publishing fails with a targeted error if any link is missing, if a named dimension doesn't resolve to an output column, or if it names a measure. You find out where you declared it, not by watching a table that never advances.
### Which shape is yours
**A rollup or an append-only fact — no `merge_key`.** A row's `order_date` or `ingested_at` never changes, so each refresh replaces its date range outright. This also picks up rows deleted upstream *within* the refreshed range:
```malloy
#@ persist refresh="incremental" watermark="ingested_at"
source: events is conn.table('raw.events') -> {
select: ingested_at, event_id, user_id, payload
}
```
**A mutable table — `watermark` plus `merge_key`.** `updated_at` moves when a row changes, so the engine needs `id` to find and replace the stale copy:
```malloy
#@ persist refresh="incremental" watermark="updated_at" merge_key="id"
source: accounts is conn.table('raw.accounts')
```
**No monotone dimension — leave `refresh` unset.** A small lookup table overwritten wholesale upstream has nothing to order rows by; full-copy is a supported, cheap answer.
### Limits and repairs
Incremental trades completeness for cost, and two gaps are disclosed at publish rather than solved:
- **Late data.** A row that arrives with a watermark value below the range already covered is never picked up automatically.
- **Hard deletes.** A row deleted upstream can't appear in any delta, so a `merge_key` source retains it. Prefer **soft deletes** — a tombstone flag arrives as an ordinary update — and keep the flag in the persisted source's output, filtering it in consuming views instead.
Both are repaired the same two ways: correct the row upstream and advance its watermark so the next refresh applies it, or force a full rebuild with a **Rerun** from the package page (or `forceFullRebuild` on the runs API). Changing the model always triggers a full rebuild automatically — a delta is never applied across a logic change.
Non-additive measures — an exact `count_distinct`, a median — are **safe** in incremental sources: each refresh recomputes affected output rows from the full input rather than merging stored partial aggregates. Window calculations that look *forward* along the watermark (`lead()`, whole-partition percentages) are rejected at publish, because rows already materialized would go silently stale; trailing windows are fine.
## Pre-Aggregations
A pre-aggregation makes a **measure** fast and cheap at coarse grains. You mark a hot measure and its rollup grain; Credible maintains a rolled-up copy and silently answers coarse queries from it. You never hand-write a rollup source, and no query ever names one — routing is a property of the engine, not a judgment the caller (or the AI agent) makes per query:
```malloy
#@ preaggregate grain="order_time.day, category"
measure: total_revenue is amount.sum()
```
- `grain` — **required**: the dimensions the rollup stores. A query is served from the rollup when everything it groups by and filters on is covered by the grain — a coarser truncation of a stored time dimension (`order_time.month` over a `day` grain) counts. Anything else falls back to the base source and runs live: "unsupported" and "unaccelerated" are the same, correct outcome.
- `#@ -preaggregate` pins a measure to the base even when a covering rollup exists — the escape hatch for a consumer that can't tolerate the rollup's freshness.
Routing is correctness-aware — the engine never serves a silently wrong number from a rollup:
- **Additive measures** (`sum`, `count`, `min`, `max`) and `avg` are re-aggregated from the rollup at any covered grain.
- **Non-additive measures** (`count(distinct)`, `median`, percentiles) can't be correctly re-aggregated to a coarser grain, so a rollup answers them only at exactly its declared grain — other grains run live. You're told this once, as a publish-time warning on the measure.
Everything else on this page applies unchanged. Measures declared at the same grain pack into a single rollup table, built by the same runs — from the materialized table when the base source is also `#@ persist`-ed, straight from the warehouse when it isn't (often the right choice: a rollup is frequently worth maintaining when a full copy of the base is not). Rollups share their base's freshness window — a rollup is never fresher than the table it was built from, and a stale rollup is skipped in favor of the base, never served — and they're reused and garbage-collected like any other derived copy.
For an expensive source with hot measures, this is the same three-part pattern described above — persist, index, and pre-aggregate — with Credible sequencing all three annotations for you.
## Freshness
`freshness.window` is an **objective**, not a fixed refresh time: it tells Credible how stale the derived copy is allowed to get, and the engine schedules refreshes to meet it. This lets Credible batch work, run off-peak, and skip a refresh any recent publish or on-demand run already covered.
The `fallback` setting controls what a query does when a materialized table is older than its window — `live` runs the query against the warehouse instead of serving stale data.
Search indexes surface their staleness on the version page and in search and retrieval responses, so the agent can tell when suggestions come from an older snapshot.
## Builds and Refreshes
- **On publish** — Credible builds every persisted source, search index, and pre-aggregation for the new version automatically.
- **On demand** — trigger a **Rerun** from the package page (or the runs API) to force a rebuild. You can rerun a whole version, or a single source or dimension — optionally including its upstream persisted sources.
- **On a schedule** — the engine refreshes derived copies to meet their freshness objectives.
The version page shows **Materialized sources** and **Indexed dimensions** side by side, each with a simple status and its build and refresh history, so you can see at a glance whether a version is fully built.
### What It Costs
Derived copies meter the way the [pricing page](/pricing) describes: the tables, rollups, and indexes the engine keeps are **storage**, billed per GB-month; a query the engine answers from them meters **compute time**, billed per second; a query that runs directly on your warehouse incurs no compute charge from Credible. Storage is the optimization that makes the other two meters small.
### Storage Reclamation
Credible **garbage-collects every unused derived copy** — a materialized table, index, or rollup is kept only while an unarchived package version references it. Archiving a version releases its references, and any copies no longer referenced by another version are reclaimed automatically. So the way to keep storage costs down is to **archive package versions you no longer use** — [auto-archive](/docs/how-to/modeling/publishing#auto-archive) (on by default) does this for you on a retention window you control.
## Next Steps
Publish to build your materialized tables, indexes, and rollups
How search indexes power AI discovery and analysis
---
# Publishing
Source: https://www.credibledata.com/docs/how-to/modeling/publishing
Publishing is the final stage of model development. Everything the previous pages added to your model — the sources, joins, dimensions, measures, and views; the `#(doc)` and `#(index)` [metadata](/docs/how-to/modeling/metadata-tags); the `#(authorize)` and secure-given [access rules](/docs/how-to/modeling/fine-grained-acls); the `#@ persist` [performance annotations](/docs/how-to/modeling/persistence) — ships as a **package**. When you publish, the Credible service takes that package and serves it to every consumer: workspace chat, [data apps](/docs/how-to/analyzing/data-apps), [MCP agents](/docs/how-to/analyzing/ai-assistants-mcp), and the [REST APIs](/docs/how-to/integrating/apis).
## Packages: The Unit of Publishing
A package is a folder containing your model and everything that ships with it:
- **`.malloy` files** — data model definitions
- **Data apps** — dashboards and applications built on the model, shipped as a `public/` directory of plain web files. A data app queries the package's own models — with all access rules applied — and automatically appears in every workspace the package is added to
- **Data files** (CSV or Parquet) — embedded data published with the package (see [Embedded Data](/docs/how-to/developers/embedded-data))
- **`publisher.json`** — the package manifest
Packages can also include `.malloynb` notebooks, which render as reports in workspaces — but for new dashboards and curated views, build a data app.
A package is published and versioned **as a single unit**: model, metadata, access rules, apps, and manifest move together, so every version is a complete, reproducible artifact — reviewed in Git, published together, rolled back together.
## The Package Manifest
`publisher.json` is your control surface for how Credible serves and manages the package. At minimum it identifies the package — `name`, `version`, and `description`; the rest is optional:
```json
{
"name": "ecommerce",
"version": "0.0.1",
"description": "ecommerce demo data",
"explores": ["orders.malloy", "customer_health.malloy"],
"queryableSources": "declared",
"scope": "package",
"materialization": { "freshness": { "window": "24h", "fallback": "live" } }
}
```
Beyond identity, the optional fields control two aspects of serving:
- **Discovery** — `explores` and `queryableSources` curate what agents and users see; see [Curating Discovery](/docs/how-to/modeling/metadata-tags#curating-discovery) on the Discovery page
- **Serving policy** — `scope` and `materialization.freshness` set how the package's derived copies (materialized tables and search indexes) are reused across versions and how fresh they're kept; see [Performance & Cost](/docs/how-to/modeling/persistence#package-manifest)
## How to Publish
Wherever you build, one step takes a draft to a published version:
- **In the Credible App** — ask the agent to publish your draft. It packages the draft, deploys it to your environment, and confirms the published version. See [Build & Publish](/docs/how-to/modeling/in-app-development#publishing).
- **In your IDE** — type `/credible-publish` in your agent's chat. The agent creates a `publisher.json` if needed, bumps the version on a republish (versions are immutable), and runs the publish for you.
- **With the CLI directly**:
```bash
npm i -g @credibledata/cred-cli # install (once)
cred login # authenticate (once)
cred set environment
cd /path/to/your/package
cred publish --set-latest
```
The `--set-latest` flag promotes the version to the package's "latest" **immediately**, before its indexes and materialized tables are built. You can usually omit it: with [auto-promote](#auto-promote) (on by default), the new version is promoted automatically once it's fully built and ready to serve. See the [CLI](/docs/platform-admin/cli) page for all commands.
- **From CI/CD** — automate publishing when changes merge to Git. A GitHub Actions workflow versions and publishes the package on every merge, so your main branch is always what's served. See [CI/CD Setup](/docs/platform-admin/cicd).
## What Happens When You Publish
Publishing hands your package to the Credible service, which prepares the new version for serving. Each annotation you added in the earlier stages becomes work the engine now does for you:
1. **Validate and version.** The service compiles the model and creates a new **immutable version** of the package. Model errors and publish-time guardrails (like the [indexed-dimension rules](/docs/how-to/modeling/persistence#deciding-what-to-persist)) surface here — as publish errors, not silent wrong answers downstream.
2. **Build derived copies.** Every `#@ persist` source is materialized and every `#(index)` dimension gets its search index built, sequenced so an index derives from the materialized table it depends on. From then on, the engine keeps these copies fresh on your declared objectives. See [Performance & Cost](/docs/how-to/modeling/persistence#builds-and-refreshes).
3. **Build the concept index.** The engine compresses your model — sources, dimensions, measures, views, `#(doc)` descriptions, and the `#(index)` values from step 2 — into the [concept index](/docs/how-to/analyzing/overview#how-it-works), which is what lets agents match a question by meaning and find the right slice of the model. Indexing usually takes a minute or two; a model spanning hundreds of tables can take 10 minutes or more.
4. **Wire up enforcement.** Your `#(authorize)` gates and secure givens are enforced on **every query against the served version**, identically across every consumer — workspace chat, MCP agents, dashboards, data apps, and APIs.
The package page rolls all of this up into a single build status per version — **Building** while indexing and materialization are in flight, then **Ready** once the version has settled into a servable state (or **Failed** if either side failed).
 Until indexing completes, the [`get_context` MCP tool](/docs/how-to/analyzing/ai-assistants-mcp#tool-reference) will not return results for the new version. The `execute_query` tool and Data API are available immediately after publishing.
## Serving and Version Management
Once prepared, the version is served to every consumer. Versions work like software releases:
- **One pinned "latest".** One version is designated as latest — the default served to consumers who don't specify a version. Consumers on "latest" automatically pick up updates when the pin moves; consumers that need stability (like a production dashboard) can pin to a specific version.
- **Versions remain available.** Published versions are preserved, enabling rollbacks, pinned production deployments, gradual adoption across teams, and historical audits.
This treats data models as versioned software artifacts, with the same deployment safety and flexibility modern software engineering provides. Two package-level policies automate the routine parts of this lifecycle so most packages never need manual version management:
### Auto-Promote
With **auto-promote** (on by default), publishing arms the new version, and Credible promotes it to the package's latest **once it is ready** — fully indexed, with its materialized tables built. You publish; Credible waits for the version to be servable and then moves the pin.
This is safer than promoting at publish time: consumers never get switched to a version whose indexes and tables are still building, and a version whose build **fails is never promoted**. Two guardrails keep it predictable:
- **Rollbacks stick.** Auto-promote only promotes a version that has *never* been latest. If you roll back by re-pinning an older version, Credible won't fight you and re-pin the newer one.
- **No going backward.** A version that's ready but older than the current latest isn't promoted.
Turn auto-promote off if you want to control promotion yourself — for example, to validate a version by querying it directly before manually pinning it as latest.
### Auto-Archive
With **auto-archive** (on by default, with a 30-day retention), Credible reclaims old versions automatically: once a version stops being latest, it's retained for the package's retention window and then archived — removed from service. The current latest is **never** archived, and the window gives you a cheap rollback target for as long as it lasts.
Archiving is also how storage gets reclaimed: the engine **garbage-collects every materialized table and index not referenced by an unarchived package version**, so archiving unused versions is what keeps storage costs down. Copies shared with a still-active version are kept — only the copies nothing references are reclaimed.
Tune the retention to your rollback needs: units are seconds to weeks (`24h`, `30d`, `2w`), and `0` archives a version as soon as it's demoted — a keep-only-latest mode that minimizes storage cost but gives up the instant-rollback window. Turn auto-archive off to retain every version indefinitely.
Both policies are configured per package — on the package page in the Credible App or via the [Admin API](/docs/admin-api-reference) — and they're independent: use either without the other.
### Viewing Published Versions
- **Credible App** at `https://your-org.app.credibledata.com` — navigate to your environment and click a package to see complete version history, pin or unpin versions, check build and indexing status, and view package metadata
- **Credible CLI** — list a package's versions from the command line:
```bash
cred ls versions
```
## Next Steps
Your model is served. Now put it to work:
Analyze and build with your published models — workspace chat, data apps, your own agent, and Slack
Automate publishing from your Git workflow
---
# Welcome to Credible
Source: https://www.credibledata.com/docs/introduction
Credible is the **AI Analytics Engine**. Without context, AI gives confident answers no one trusts. Credible helps you capture what your data means — the definitions, business rules, and relationships buried in docs, dashboards, SQL, and your experts' heads — as **governed [data models](/docs/concepts/data-model)**, then delivers your data and its meaning as context to every surface: AI agents, dashboards, data apps, and whatever you build next.
Models are built on [Malloy](https://malloydata.dev), an open-source language designed for capturing and querying data's meaning. Your models are code — readable, versioned in Git, portable, and free from vendor lock-in.
## How It Works
Everything in Credible follows one path from raw data to trusted answers — collect, govern, deliver:
1. **Collect context and model.** Link your databases through [managed connections](/docs/how-to/modeling/connect-data) — credentials stay in Credible, never on anyone's machine. Then build data models with AI agents, [in your browser](/docs/how-to/modeling/in-app-development) or [in your IDE](/docs/how-to/developers/overview).
2. **Govern and publish.** Models live in [environments](/docs/how-to/modeling/environment-overview) as versioned packages, with [access control](/docs/how-to/modeling/fine-grained-acls) defined in the model and enforced on every surface, and [materialization](/docs/how-to/modeling/persistence) to optimize performance and cost. [Publishing](/docs/how-to/modeling/publishing) makes a model available to every consumer at once.
3. **Deliver.** Chat with your data and build reports in [workspaces](/docs/how-to/analyzing/workspaces), give AI agents governed access [via MCP](/docs/how-to/analyzing/ai-assistants-mcp) (the open protocol that connects agents to tools), ship [data apps](/docs/how-to/analyzing/data-apps) with your models, or build on the [REST APIs](/docs/how-to/integrating/apis). One model, every surface, consistent answers.
## One Set of Skills, Every Surface
Credible's agents are not a black box. Their behavior is encoded as **agent skills** — readable playbooks for discovering data, modeling in Malloy, analyzing without hallucinating, building data apps, and publishing — and the **MCP tools** those skills use. Both are open source in [Malloy Publisher](https://github.com/malloydata/publisher), the server for Malloy models.
The in-app agent, the Credible Extension in your IDE, and the agent plugins we publish all run the **same skills** — so the agentic experience is consistent across every surface, and an answer arrived at in the app follows the same discipline as one in your coding agent. And because the skills are open, they're curated with the world's data experts — a community whose expertise runs deeper than any one vendor's bench. Every skill is readable: fork them, or extend them with your organization's institutional knowledge. Read the full story in [We Open Sourced the Thing Everyone Else Is Selling](https://credibledata.com/blog/posts/open-sourcing-skills).
## Get Started
You can build data models, analyze data, and build data apps entirely in your browser or in your own IDE. Both produce the same governed packages — start with whichever fits you and mix them freely.
Build with a natural-language agent in the Credible App — no setup or code editor. Ideal for getting started fast and for business users.
Build in your preferred IDE with any coding agent — Cursor, VS Code, Claude Code, and more. Ideal for engineers who want Git-based workflows and full control over files.
Both paths use managed connections, publish to the same [environments](/docs/how-to/modeling/environment-overview), and produce models ready for every consumer.
## Explore the Docs
The documentation follows the same path — foundation first, then building, then consuming:
- **[Environments](/docs/how-to/modeling/environment-overview)** — **Start here.** The rest of this Get Started section covers the governed foundation: what environments are, how to connect your databases, and how to build and publish in the app.
- **[Data Modeling](/docs/how-to/modeling/ai-modeling)** — Building models with AI agents, then evolving them: metadata, fine-grained access control, performance and cost, and publishing. Already have a semantic layer in Looker, Tableau, Power BI, and more? [Migrate it](/docs/how-to/migrating/overview) into governed Malloy.
- **[Analyze & Deliver](/docs/how-to/analyzing/overview)** — Everything downstream of publish: analyzing data in workspaces, building data apps, and connecting your agent and Slack.
- **[Developers](/docs/how-to/developers/overview)** — The same foundation — same models, same skills, same MCP tools — in your own toolset: the VS Code extension, the CLI, CI/CD, MCP tools for custom agents, and the REST APIs.
- **[Admins](/docs/platform-admin/groups-permissions)** — Managing your organization: users and groups, permissions and access control, and best practices for organizing environments and packages.
- **[Concepts](/docs/concepts/data-model)** — The ideas behind the engine: the data model, the architecture, and [why Malloy](/docs/concepts/why-malloy).
## Next Step
Everything you build lives in an environment, so that's the place to start:
Understand environments — the stable, governed foundation that holds your connections and packages
---
Have questions or need assistance? Contact us at [support@credibledata.com](mailto:support@credibledata.com).
---
# CI/CD Setup
Source: https://www.credibledata.com/docs/platform-admin/cicd
Your data models are Malloy code in plain files, so they fit the engineering workflow you already have: version them in Git, review them in pull requests, and publish automatically when changes merge. This page sets up that last step — a CI/CD pipeline using our GitHub Actions template.
**Two ways to work in Git.** This page is for models built **in your IDE** and kept in a repository you own. Models built **in the Credible App** get the same review and history through [git-backed modeling](/docs/how-to/modeling/git-backed-modeling), where each change becomes a branch and a pull request in a repository Credible hosts and merging is what publishes. The two coexist in one environment, package by package — see [How this fits with git-backed modeling](#how-this-fits-with-git-backed-modeling).
## How It Works
When you push changes to your `main` branch:
1. **Detect** — the pipeline identifies which packages changed
2. **Version** — it bumps the patch version in each changed package's `publisher.json`, because a published version is immutable
3. **Publish** — it publishes the new versions to your Credible environment with the [CLI](/docs/platform-admin/cli)
A compile error fails the publish step, so a broken model never becomes a served version.
Rolling back never touches CI: re-pin the previous version as latest in the Credible App and every consumer follows, with nothing to rebuild (see [Serving and version management](/docs/how-to/modeling/publishing#serving-and-version-management)).
## Prerequisites
- A GitHub repository for your packages
- Admin access to the repository
- A Credible organization and environment
## Setup
### Step 1: Create Repository from Template
1. Go to the [CI/CD template repository](https://github.com/credibledata/credible-cicd-template)
2. Click **"Use this template"** → **"Create a new repository"**
3. Choose your organization and enter a repository name
The template includes all necessary scripts and GitHub Actions workflows.
### Step 2: Configure GitHub App
The CI/CD bot needs a GitHub App to commit version bumps back to your repository.
**Create the App:**
1. Go to your GitHub organization: **Settings** → **Developer settings** → **GitHub Apps** → **New GitHub App**
2. Configure:
- **Name**: a name unique across all of GitHub (e.g., `credible--cicd-bot`). GitHub App names are global, so `credible-cicd-bot` is already taken — pick your own. The name is cosmetic; the workflow authenticates with the App ID and private key, not the name.
- **Homepage URL**: required by GitHub — any valid URL works (e.g., your repository URL)
- **Webhook**: Uncheck "Active"
- **Repository permissions**: Contents (Read/Write), Pull requests (Read/Write), Metadata (Read), Environments (Read)
- **Installation**: "Only on this account"
3. Click **Create GitHub App**
4. Note the **App ID** at the top of the page
5. Scroll to **Private keys** → **Generate a private key** (save the `.pem` file)
6. Go to **Install App** → **Install**, choose **Only select repositories**, and select your repository. Avoid **All repositories**: the App can write repository contents, and this pipeline only ever needs the one.
### Step 3: Configure Secrets
Go to your repository: **Settings** → **Secrets and variables** → **Actions** → **New repository secret**
| Secret | Value |
|--------|-------|
| `CICD_BOT_APP_ID` | Your GitHub App ID |
| `CICD_BOT_APP_PRIVATE_KEY` | Entire contents of the `.pem` file, including the `-----BEGIN` and `-----END` lines |
| `JWT_ACCESS_TOKEN` | Credible API token (see note below) |
Generate a Credible API token using the CLI: `cred add group-access-token`. Create a group whose only member is the pipeline, so the token carries exactly the access the pipeline needs. The token is shown once — store it as a repository secret, never in the repository itself. See the [CLI documentation](/docs/platform-admin/cli#resource-management) for details.
The group used to generate the token needs **Modeler** access to your environment:
 ### Step 4: Configure Variables
Go to: **Settings** → **Secrets and variables** → **Actions** → **Variables**
| Variable | Value |
|----------|-------|
| `CRED_ORG` | Your Credible organization name |
| `CRED_ENV` | Your Credible environment name |
| `SET_LATEST` | `true` or `false` (optional, defaults to `true`) |
### Step 5: Configure Branch Protection
1. Go to **Settings** → **Branches** → **Add branch protection rule**
2. Branch name pattern: `main`
3. Enable:
- **Require a pull request before merging**, with at least one approval
- **Allow specified actors to bypass required pull requests** → add your App
- **Require status checks to pass before merging**
- **Require conversation resolution before merging**
- **Restrict who can push to matching branches** → add your App
The two App entries are what let the pipeline commit its version bump to a
branch that otherwise refuses direct pushes. Without them the bump cannot land
and the publish never runs.
## Publishing to More Than One Environment
The template publishes to a single environment. To promote through staging and
production, give `deploy.yaml` one publish job per environment and pass each an
`environment` name, which binds that job to a
[GitHub Environment](https://docs.github.com/en/actions/how-tos/deploy/configure-and-manage-deployments/manage-environments)
and applies its protection rules:
```yaml
jobs:
publish-staging:
needs: bump
if: needs.bump.outputs.bumped != ''
uses: ./.github/workflows/publish-packages.yml
with:
environment: staging
packages: ${{ needs.bump.outputs.bumped }}
cred_org: ${{ vars.CRED_ORG }}
cred_env: ${{ vars.CRED_ENV_STAGING }}
secrets:
jwt_access_token: ${{ secrets.JWT_ACCESS_TOKEN_STAGING }}
```
Referencing a GitHub Environment is what buys you the gate: add a required
reviewer to `production` and the production publish waits for a human while
staging proceeds untouched. Each environment carries its own token, so a
staging credential can never publish to production.
This is why the App needs **Environments (Read)** in Step 2. Give each
environment its own `CRED_ENV*` variable and token secret rather than reusing
one pair.
## Repository Structure
Your repository should follow this structure:
```
your-repo/
├── .github/workflows/ # CI/CD workflows (from template)
├── packages/
│ ├── package-one/
│ │ ├── publisher.json
│ │ └── [your .malloy files]
│ └── package-two/
│ └── ...
└── scripts/ # CI/CD scripts (from template)
```
Each package needs a `publisher.json`:
```json
{
"name": "your-package-name",
"version": "0.0.0",
"description": "Package description"
}
```
## Merge Strategy
**Do not use "Squash and merge"** for pull requests that modify packages. Squashing can cause the pipeline to miss package changes. Use **Merge commit** or **Rebase and merge** instead.
## How This Fits With Git-Backed Modeling
Both paths give a model change a pull request, a review, and a published version with a record of where it came from. They differ in who builds the model and where the source lives.
| | **CI/CD from your repository** (this page) | **Git-backed modeling** |
|---|---|---|
| Where the model is built | Your IDE and your coding agent | The Credible App, by the in-app agent |
| Where the source lives | A repository you own, in your layout | A repository per environment that Credible hosts |
| What publishes a version | Your pipeline runs `cred publish` on merge | Merging the pull request Credible opened for the draft |
| Review and checks | Your pull requests, your rules, your CI | A pull request per change, with Credible's compile verdict as a check run |
| Who contributes | Engineers | Engineers, analysts, and domain experts, in plain language |
They work side by side in one environment:
- **Packages you publish from here keep publishing from here** after an environment is enrolled in git-backed modeling. Enrollment applies to drafts created in the App; a package git-backed modeling has never seen is untouched by it.
- **A package becomes git-backed the first time it is edited in the App.** The agent imports the published version as the starting point, and from then on that package publishes only through a pull request.
- **Decide per package which side owns it,** and keep it there. Both serve from the same environment and the same governed model.
## Next Steps
The same review and history for models built in the App, with merge as the publish
Versions, promotion, and rollback
The deploy step this pipeline runs, from your terminal
When a run fails, the workflow logs in the GitHub Actions tab name the step. [Email us](mailto:support@credibledata.com) the run ID and the error if the cause isn't there.
---
# CLI
Source: https://www.credibledata.com/docs/platform-admin/cli
The Credible CLI (`cred`) puts Credible in your terminal. Everything the Credible App manages is scriptable — the same environments, packages, connections, and groups — which makes the CLI the natural building block for automation and [CI/CD](/docs/platform-admin/cicd).
## Installation
**Prerequisites**: Node.js version 20+ and npm package manager
Install the Credible CLI globally from the npm registry:
```bash
npm install -g @credibledata/cred-cli
```
View package details at [npmjs.com/package/@credibledata/cred-cli](https://www.npmjs.com/package/@credibledata/cred-cli)
### Shell Autocompletion
The CLI supports bash/zsh autocompletion. To set it up, run:
```bash
cred --install
```
Restart your shell, then type `cred ` + TAB to see available commands, or `cred ls ` + TAB to see resource types. Completion is context-aware — `cred set environment ` + TAB completes your environment names, and `cred ls version ` + TAB completes your package names. To remove it, run `cred --cleanup`.
## Core Commands
### Authentication & Session
#### Login
Authenticate with your organization via Auth0:
```bash
cred login [-c gcp|aws]
```
Options:
- `-c, --cluster `: Target cluster (`gcp` or `aws`). Defaults to your organization's default cluster (`gcp` for most organizations)
#### Check Status
View your current organization and environment:
```bash
cred status
```
#### Logout
Clear stored credentials:
```bash
cred logout
```
#### Authenticate as a Service Account
For scripts and CI/CD, authenticate with a service account JWT instead of the browser-based login — for example, a [group access token](#resource-management):
```bash
cred set-access-token [-o ]
```
Options:
- `-o, --organization `: Organization to set for the session
### Resource Management
#### List Environments
```bash
cred ls environment
```
#### Get Environment Details
```bash
cred get environment
```
#### Create Environment
```bash
cred add environment [--readmeFile ] [--replication ] [-y]
```
Options:
- `--readmeFile `: Path to README file to include
- `--replication `: Replication count for the environment's packages (must be at least 1)
#### Update Environment
```bash
cred update environment [--replication ] [--git-modeling ] [--git-repository-owner --git-repository-name --git-base-branch ] [-y]
```
Options:
- `--replication `: Replication count for the environment's packages
- `--git-modeling `: Enroll (or un-enroll) the environment for [git-backed modeling](/docs/how-to/modeling/git-backed-modeling) drafts
- `--git-repository-owner`, `--git-repository-name`, `--git-base-branch`: The repository drafts commit to. All three or none; pass `""` to all three to unset
#### Delete Environment
```bash
cred rm environment [-y]
```
#### Set Default Environment
```bash
cred set environment
```
Setting a default environment applies only to CLI sessions — it doesn't change anything in the Credible App
#### List Packages
```bash
cred ls package
```
#### Delete Package
```bash
cred rm package [-y]
```
#### Update Package
```bash
cred update package [options]
```
Options:
- `--version `: Set which version is latest/pinned
- `--description `: Update package description
- `--replication `: Set replication count (must be at least 1)
The "latest" version may also be called "pinned" in the web UI
#### Publish New Version
Run from your package directory:
```bash
cred publish [--set-latest] [--replication ] [-y]
```
Options:
- `--set-latest`: Set the published version as the package's latest version
- `--replication `: The number of replicas to create
#### List Package Versions
```bash
cred ls version
```
#### Archive Version
```bash
cred archive [-y]
```
#### Unarchive Version
```bash
cred unarchive [-y]
```
There is no `cred set package` command. Use `cred set environment` to set your default environment. Packages are managed through publish/archive/unarchive commands.
#### List Connections
```bash
cred ls connection
```
#### Create Connection
```bash
cred add connection [--include-tables ] [--exclude-tables ] [--skip-indexing] [-y]
```
Options:
- `--include-tables `: Comma-separated list of tables to index for AI-assisted modeling, as `{dataset/schema}.{table}` (use `*` for all tables in a schema, e.g., `sales.*,finance.orders`)
- `--exclude-tables `: Comma-separated list of tables to exclude from indexing (same format); mutually exclusive with `--include-tables`
- `--skip-indexing`: Disable automatic indexing for this connection; cannot be combined with the table flags
The `connectionFileName` should be a JSON file containing an array of connection objects. The connection name is a field within the JSON, not a command-line argument.
**Command Syntax:**
```bash
cred add connection
```
**JSON File Structure:**
Each connection has:
- `name`: The connection name (required)
- `type`: Connection type (`postgres`, `bigquery`, `snowflake`, `trino`, `databricks`, `mysql`, `duckdb`, `motherduck`, `ducklake`)
- Connection-specific configuration based on type
**BigQuery Example:**
```json
[
{
"name": "my-bigquery-connection",
"type": "bigquery",
"bigqueryConnection": {
"defaultProjectId": "my-project",
"billingProjectId": "billing-project",
"location": "us-central1",
"serviceAccountKeyJson": "{\"type\":\"service_account\",\"project_id\":\"...\"}",
"maximumBytesBilled": "1000000",
"queryTimeoutMilliseconds": "30000"
}
}
]
```
Note: For BigQuery, the `serviceAccountKeyJson` field contains the entire JSON content as a string (not a file path).
**PostgreSQL Example:**
```json
[
{
"name": "my-postgres-connection",
"type": "postgres",
"postgresConnection": {
"host": "localhost",
"port": 5432,
"databaseName": "mydb",
"userName": "myuser",
"password": "mypassword"
}
}
]
```
Alternatively, you can use a connection string:
```json
[
{
"name": "my-postgres-connection",
"type": "postgres",
"postgresConnection": {
"connectionString": "postgresql://user:password@localhost:5432/mydb"
}
}
]
```
**Snowflake Example:**
```json
[
{
"name": "my-snowflake-connection",
"type": "snowflake",
"snowflakeConnection": {
"account": "myaccount.us-east-1",
"username": "myuser",
"password": "mypassword",
"warehouse": "COMPUTE_WH",
"database": "MYDB",
"schema": "PUBLIC",
"responseTimeoutMilliseconds": 60000
}
}
]
```
**Databricks Example (Personal Access Token):**
```json
[
{
"name": "my-databricks-connection",
"type": "databricks",
"databricksConnection": {
"host": "dbc-xxxxxxxx-xxxx.cloud.databricks.com",
"path": "/sql/1.0/warehouses/abcdef1234567890",
"token": "dapiXXXXXXXXXXXXXXXXXXXXXXXXXXXX",
"defaultCatalog": "main",
"defaultSchema": "default"
}
}
]
```
Alternatively, authenticate with an OAuth M2M service principal:
```json
[
{
"name": "my-databricks-connection",
"type": "databricks",
"databricksConnection": {
"host": "dbc-xxxxxxxx-xxxx.cloud.databricks.com",
"path": "/sql/1.0/warehouses/abcdef1234567890",
"oauthClientId": "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx",
"oauthClientSecret": "doseXXXXXXXXXXXXXXXXXXXXXXXXXXXX",
"defaultCatalog": "main",
"defaultSchema": "default"
}
}
]
```
See the [Databricks connection reference](/docs/reference/connections/databricks) for details on creating a SQL warehouse and credentials.
Connection names can contain only letters, numbers, and underscores, and must start with a letter or underscore.
#### Delete Connection
```bash
cred rm connection [-y]
```
#### List Groups
```bash
cred ls group
```
#### Get Group Details
```bash
cred get group
```
#### Create Group
```bash
cred add group [-d ] [-y]
```
Options:
- `-d, --description`: Description for the group
- `-y, --yes`: Skip confirmation
#### Delete Group
```bash
cred rm group [-y]
```
#### Create Group Access Token
```bash
cred add group-access-token [-e ] [-j]
```
Arguments:
- ``: The name of the group
- ``: Name for the API key/token
Options:
- `-e, --expires-at `: Token expiration date in ISO 8601 format (e.g., `2027-12-31T23:59:59Z`); defaults to no practical expiration
- `-j, --json-output`: Output only JSON, for use in scripts
**Example:**
```bash
cred add group-access-token ai-agents-group production-token
```
The command prints the API key once. Requests made with it act with the group's permissions.
#### List Group Access Tokens
```bash
cred ls group-access-token
```
#### Delete Group Access Token
```bash
cred rm group-access-token [-y]
```
#### Add Member to Group
```bash
cred add member
```
Arguments:
- ``: The name of the group
- ``: Type of member (`user` or `group`)
- ``: Name of the user or group to add
- ``: Member role (`admin` or `member`)
**Examples:**
```bash
# Add a user as admin
cred add member engineering-team user john.doe@example.com admin
# Add a nested group as member
cred add member engineering-team group data-analysts member
```
#### Remove Member from Group
```bash
cred rm member
```
Arguments:
- ``: The name of the group
- ``: Type of member (`user` or `group`)
- ``: Name of the user or group to remove
**Example:**
```bash
cred rm member engineering-team user john.doe@example.com
```
Groups enable role-based access control (RBAC) for organizing users and managing permissions across environments and packages. Groups can contain both individual users and other groups (nested groups).
These commands monitor and manage the [materialized tables and search indexes](/docs/how-to/modeling/persistence) the Credible service builds for a published package version.
#### List Materializations
List the materializations of a package version, with status and any failure reason:
```bash
cred ls materialization
```
#### Get Materialization Details
Status, physical table and connection, serving build, and freshness/staleness:
```bash
cred get materialization
```
#### List Indexes
List the dimensional search indexes of a package version, with status, any failure reason, and freshness:
```bash
cred ls index
```
#### Get Index Details
Status, row count, last indexed time, and freshness/staleness:
```bash
cred get index
```
#### List Runs
List a package's build/refresh runs, most recent first. Runs are package-scoped and cover both materialized sources and dimensional indexes:
```bash
cred ls run [versionId] [--source ] [--dimension ]
```
Options:
- `[versionId]`: Filter to the runs a specific version initiated (e.g., `0.1.21`); omit to list every run in the package
- `--source `: Only list runs targeting this persisted source
- `--dimension `: Only list runs targeting this indexed dimension
#### Get Run Details
Includes the run's build-plan graph — per-unit state, physical table names, and row counts:
```bash
cred get run
```
#### Trigger a Run
Trigger an on-demand rebuild/refresh for a package version. Defaults to a full run (all sources and indexes):
```bash
cred rerun [--source ] [--dimension ] [-y]
```
Options:
- `--source `: Scope the run to a single persisted source
- `--dimension `: Scope the run to a single indexed dimension
- `--model-file `: Disambiguate a source/dimension defined in more than one model file
- `--include-upstream`: Also force-rebuild the target's upstream persisted dependencies (only meaningful with `--source`/`--dimension`)
#### Cancel a Run
Cancel an in-flight run:
```bash
cred cancel-run [-y]
```
## Command Options
### Global Options
| Option | Description |
|--------|-------------|
| `-V, --cli-version` | Display the CLI version number |
| `-h, --help` | Display help (use alone for general help or after a command for specific help) |
| `--debug` | Enable debug output (most commands) |
| `-y, --yes` | Skip confirmation prompts |
### Pagination
List commands (`cred ls environment`, `cred ls connection`, `cred ls package`, `cred ls index`, `cred ls run`) return all records by default and accept:
| Option | Description |
|--------|-------------|
| `--page ` | Page number (starts at 1) |
| `--page-size ` | Items per page (max: 500) |
Earlier CLI versions used `project` where Credible now uses `environment` (e.g., `cred ls project`). The `project` commands still work as deprecated aliases — use the `environment` forms going forward.
## Next Steps
Put the CLI to work — publish packages automatically on merge
Use group access tokens to authenticate applications with the REST APIs
---
# Deployment
Source: https://www.credibledata.com/docs/platform-admin/deployment
Credible is a fully managed service: there is nothing to deploy, patch, or scale. You connect your data where it already lives, publish a model, and the engine runs everything underneath — the gateway, the control plane, the workers that serve queries, the retrieval service, and the storage it keeps for itself. See [Architecture](/docs/concepts/architecture) for how those pieces fit.
## Cloud
The [Cloud plan](/pricing) runs on Credible's multi-tenant clusters. Each organization is addressed by its own hostnames — `.app`, `.admin`, `.data`, `.mcp`, and `.retrieval` under `credibledata.com` — and every request carries an identity or API key whose organization must match. Services run across availability zones on multi-zone Kubernetes with rolling, disruption-budgeted deploys, so node failures and upgrades don't take the service offline; new model versions load onto workers before they serve traffic, so promotion and rollback are zero-downtime.
Because Credible is one engine rather than an instance per customer, it prices like cloud infrastructure: users, publishing, and MCP access are free, and you pay for tokens, compute time, and storage. See [pricing](/pricing) for the meters and rates.
## Enterprise: Dedicated Clusters
For strict residency or isolation requirements, the [Enterprise plan](/pricing) runs Credible on **dedicated single-tenant clusters** — fully isolated deployments, selected transparently by endpoint — with:
- **Multi-region deployment**, on GCP or AWS. The CLI targets a cluster with `cred login -c gcp|aws`.
- **VPC connectivity and Private Link** to the databases and warehouses Credible reads from, so queries never traverse the public internet.
- **A 99.99% SLA with 24/7 pager support.** Credible is SOC 2 compliant; see [Security](/security).
- **Forward Deployed Engineers** — hands-on help from modeling to production.
## Connecting Your Data
However Credible is deployed, database credentials are stored once, in an [environment](/docs/how-to/modeling/environment-overview), and never leave the control plane. Outbound queries originate from stable egress IPs, so you can allowlist Credible without opening your database to the world. See [Connect Your Data](/docs/how-to/modeling/connect-data) for the supported sources.
## Next Steps
One gateway, two planes, and the engine's own storage
Identity, access control, and the audit trail
---
# Best Practices
Source: https://www.credibledata.com/docs/platform-admin/environments-packages
The [Environments](/docs/how-to/modeling/environment-overview) page covered what environments and packages are. This page is about how many to create and where to draw the boundaries — the organizational patterns that scale, and the versioning habits that keep releases safe.
Everything below builds on two properties from the overview: **connections are shared** by every package in an environment, and **packages are versioned** with one version pinned as latest.
## Environment Patterns
An environment maps to whatever boundary your organization wants a stable, separately-governed configuration around. Three patterns cover most teams — and they compose.
### Pattern 1: Department or Team Environments
Give each department or team — finance, HR, RevOps, marketing — its own environment, with the connections, packages, and access that team owns. This mirrors how data and responsibility are already split across your organization.
```
Organization: acme-corp
├── Environment: finance
│ ├── Connection: finance-warehouse
│ └── Packages: gl-model, revenue-model
├── Environment: revops
│ ├── Connection: salesforce-warehouse
│ └── Packages: pipeline-model, quota-model
└── Environment: hr
├── Connection: workday-warehouse
└── Packages: headcount-model
```
**When to use:**
- Departments own distinct data sources and databases
- Access should be scoped to each team — [grant a team access](/docs/platform-admin/permissions#sharing-environments--packages) to its own environment, and one team's connections stay out of another's reach
- Teams model and publish independently, on their own cadence, each holding multiple packages over the environment's shared connections
### Pattern 2: Development-Stage Environments
Use separate environments for the stages of your delivery lifecycle — development, staging, and production — and optionally a **private environment per developer** for isolated iteration.
```
Organization: acme-corp
├── Environment: analytics-dev
│ ├── Connection: dev-snowflake (→ dev.snowflake.com)
│ └── Package: sales-model v1.3.0
├── Environment: analytics-staging
│ ├── Connection: staging-snowflake (→ staging.snowflake.com)
│ └── Package: sales-model v1.3.0
├── Environment: analytics-prod
│ ├── Connection: prod-snowflake (→ prod.snowflake.com)
│ └── Package: sales-model v1.2.0
└── Environment: analytics-jdoe (private)
├── Connection: dev-snowflake
└── Package: sales-model (work in progress)
```
**When to use:**
- You have different database connections for each stage
- You want to test models against non-production data before promoting
- Individual developers need a sandbox that won't disturb shared environments
**Workflow:**
1. Iterate in a private (or `dev`) environment against dev connections
2. Publish and test a new version in `dev`, then promote it to `staging`
3. After validation, publish to `prod` and pin as latest
### Pattern 3: Hybrid (Department × Stage)
Combine the two: give each department its own set of stage environments. This is common once several teams each need an independent delivery lifecycle.
```
Organization: acme-corp
├── Environment: finance-dev
├── Environment: finance-prod
├── Environment: revops-dev
└── Environment: revops-prod
```
**When to use:**
- Multiple departments each own their data *and* need dev/prod separation
- Teams promote changes independently without coordinating a shared release
**Keep it as simple as it needs to be.** More environments means more configurations to govern. Start with the boundary that matters most — a department split or a stage split — and add the second axis only when a team actually needs it. Within any environment you can hold multiple packages that share its connections, and use [versioning](#versioning-best-practices) to manage releases without adding environments.
## Versioning Best Practices
### Version Numbering
Use semantic versioning in `publisher.json`:
```json
{
"name": "sales-model",
"version": "1.2.3",
"description": "Sales analytics data model"
}
```
- **Major (1.x.x)**: Breaking changes (rename fields, remove views)
- **Minor (x.2.x)**: New features (add dimensions, new views)
- **Patch (x.x.3)**: Bug fixes, documentation
### Publish, Validate, Promote
Every publish creates a new immutable version, and the version pinned as **latest** is what consumers get by default — see [Publishing](/docs/how-to/modeling/publishing) for the mechanics, including auto-promote and auto-archive. The safe release habit is three steps:
1. **Publish & validate**: Publish the new version without pinning. Test and validate with a small group who explicitly request the new version.
2. **Pin as latest**: Once validated, pin the version as latest to serve it to everyone as the default.
3. **Roll back if needed**: re-pin the previous version as latest. Nothing rebuilds; every consumer follows the pin.
And archive versions you no longer serve — Credible garbage-collects the materialized tables and indexes that no unarchived version still references, which keeps storage costs down.
## Next Steps
Your environment structure is settled — start building, or go deeper on governance:
Start building data models with your agent
Learn how permissions work across environments and packages
Automate deployments with CI/CD workflows
---
# Users & Groups
Source: https://www.credibledata.com/docs/platform-admin/groups-permissions
Manage your organization's users and groups from the Credible App — click **Users & Groups** in the bottom left of the sidebar. This page covers who is in your organization; for what they can access, see [Permissions](/docs/platform-admin/permissions).
## Manage Members
View and manage users in your organization. The Users tab shows all organization members with their email, role, and actions.
 ### Organization Roles
| Role | Access |
|------|--------|
| **Admin** | Full access to the Credible App — can create environments, manage connections, and administer users and groups |
| **Modeler** | Can build and publish packages in environments shared with them |
| **Member** | Can access workspaces shared with them in the Credible App — chat with data, view reports and data apps, and explore models. Can also be granted viewer access to environments and packages |
An organization role sets what someone can do overall — access to specific environments, packages, and workspaces is granted separately (see [Permissions](/docs/platform-admin/permissions)).
### Actions
- **Invite** — Send an email invitation to add a new user to your organization
- **Edit role** — Change a user's role between Admin, Modeler, and Member
- **Remove** — Remove a user from the organization
## Manage Groups
Groups let you grant access to many users at once. [Permissions](/docs/platform-admin/permissions) covers when to reach for one.
Switch to the **Groups** tab to view and manage groups. Click a group to view its members and manage membership.
 ### Group Roles
| Role | Access |
|------|-------------|
| **Admin** | Can add/remove members and manage group settings |
| **Member** | Inherits the group's access permissions |
### Actions
- **Create Group** — Create a new group with a name and description
- **Add members** — Add users or other groups to a group
- **Remove members** — Remove users or groups from a group
- **Delete Group** — Remove the group (does not affect individual user accounts)
### Group Access Tokens (API Keys)
A group can hold **access tokens** — API keys that let applications and services act with the group's permissions. Because the key's access is the group's access, you can adjust or revoke what an integration can reach by editing the group, without touching the key itself. Create and manage tokens with the [CLI](/docs/platform-admin/cli#resource-management) (`cred add group-access-token`), and see [API Access](/docs/how-to/integrating/apis#create-an-api-key) for the full setup.
## Next Steps
Grant users and groups access to environments, packages, workspaces, and documents
Authenticate applications with group access tokens
---
# Monitoring
Source: https://www.credibledata.com/docs/platform-admin/monitoring
Because every query from every surface passes through one gateway, there is one place to see who is asking what, how the model is being used, and what it costs.
## The Audit Trail
Every query is logged to an immutable audit trail: the caller (a user's verified identity or an API key's group), the surface it came from (workspace, MCP, data app, REST API), the model and package version it ran against, and the query itself. This is the record compliance asks for, and it is the same record whether the question came from a person or an agent. Audit logging is part of the [Enterprise plan](/pricing).
## Usage and Cost
Credible meters in the units your stack already bills in — tokens, compute time, and storage — and the same gateway that enforces access is where those meters are read. Every meter starts with a monthly allowance; see [pricing](/pricing) for the rates. Queries that run directly on your warehouse incur no compute charge from Credible, so the compute meter is a direct view of how much work the engine is doing on your behalf.
## What the Engine Does With It
The engine watches every query from every consumer and uses what it sees:
- **Performance and cost** — query cost and latency across all consumption guide [materialization and caching](/docs/how-to/modeling/persistence). The hot paths are the ones worth keeping warm.
- **Model quality** — every retrieval is a test of whether the model surfaced the right concepts. Misses point at a missing `#(doc)` line or an unindexed dimension; see [Discovery Metadata](/docs/how-to/modeling/metadata-tags). Automated tuning from these signals is in preview.
- **Lineage** — find the code that defines any metric and trace an answer from the source database to the number on the screen, because there is one definition and one path to it.
## Next Steps
Identity, access control, and the audit trail
Materialize, index, and pre-aggregate — and what it costs
---
# Permissions
Source: https://www.credibledata.com/docs/platform-admin/permissions
Permissions in Credible layer from broad to narrow: an **organization role** sets what someone can do overall, **environment and package permissions** control who can build with and consume governed data, and **workspace and document permissions** control who sees analysis work. Organization roles and groups are managed in [Users & Groups](/docs/platform-admin/groups-permissions); this page covers the resource permissions built on top of them.
## How Access Is Granted
Adding a member to the organization does not automatically grant access to any environments or packages. To grant access:
1. **Share directly**: Navigate to the resource, click **Share** (or **Permissions**), and add the user
2. **Add to a group**: Add the user to a [group](/docs/platform-admin/groups-permissions#manage-groups) that already has access
**Recommended approach**: Configure a few groups with the appropriate environment or package access. When a new user joins, add them to the relevant group as a second step after adding them to the organization.
## Sharing Environments & Packages
Grant users or groups access to specific environments or packages.
1. Navigate to the environment or package under **Packages & Connections** in the sidebar
2. Click **Permissions**
3. Add the user or group and select their role
Environments contain packages, so granting environment access also grants access to all packages in that environment.
### Environment Roles
| Role | Access |
|------|--------|
| **Admin** | Full environment control — manage connections, packages, and sharing |
| **Modeler** | Build and publish packages in the environment. Modelers can list and use the environment's connections, but cannot see or update connection configurations — credentials stay with admins |
| **Viewer** | View packages and run queries via the Data API (e.g., [MCP tools](/docs/how-to/analyzing/ai-assistants-mcp)) |
Environment viewers automatically get viewer access to all packages in that environment.
### Package Roles
| Role | Access |
|------|--------|
| **Admin** | Full package control — manage sharing and versions |
| **Modeler** | Publish new versions of the package |
| **Viewer** | View and query the package via the Data API (e.g., [MCP tools](/docs/how-to/analyzing/ai-assistants-mcp)) |
Package access can also be granted to a **workspace** — that's what adding a package to a workspace does: every workspace member can query the package through that workspace, without needing individual package permissions.
## Sharing Workspaces & Documents
Environment and package permissions govern the data; workspace and document permissions govern the **analysis work** built on top of it.
### Workspace Roles
| Role | Access |
|------|--------|
| **Manager** | Full control over workspace settings, members, and packages |
| **Viewer** | Work in the workspace — chat with data, view reports and data apps (labeled **Member** in the workspace creation wizard) |
Users can also **request access** to a workspace they can't see into; a workspace manager approves the request from the workspace's permissions list.
### Document Sharing
Individual documents in a workspace — chats, reports, and data apps — can be shared with users or groups at two levels:
| Role | Access |
|------|--------|
| **Editor** | Modify the document and manage its sharing |
| **Viewer** | View the document |
Document permissions are inherited from the workspace, so workspace members can already see shared work; per-document sharing is for granting access beyond the workspace's membership, and supports the same request-access flow.
## Access Control
The **Access Control** page in the Credible App manages the lookup table behind [secure givens](/docs/how-to/modeling/fine-grained-acls#row-scope-secure-givens) — the values Credible resolves server-side when a published model filters or gates on a `#(secure)` given. Each row grants a **user** (by email), a **group**, or **everyone** (a default) a list of values for an attribute. An attribute appears here automatically once a published model references it, so assigning values here is the second half of setting up fine-grained access control.
## Next Steps
Row and field-level security using Malloy annotations
Draw environment boundaries that make permissions easy to manage
---
# Security
Source: https://www.credibledata.com/docs/platform-admin/security
Every query from every surface — a person in a workspace, an agent over MCP, an API call from your application — enters through **one gateway**, where it is checked against the model's access rules and logged to a permanent audit trail. Security is not a layer added around Credible; it is a property of the path every query takes.
## Identity
- **People sign in through your SSO.** Credible's APIs are a standard OAuth resource server: users authenticate through your organization's identity provider — [Microsoft Entra ID](/docs/reference/auth/entra-id) and others via Auth0 — and every request they make acts with their permissions. See [Users & Groups](/docs/platform-admin/groups-permissions).
- **Services use API keys scoped to a group.** Anything server-to-server — your product, a script, CI/CD — authenticates with an [API key](/docs/how-to/integrating/apis) that acts with its group's permissions. Keys are minted from the CLI and can be revoked at any time.
- **Every request names its organization.** Each organization has its own hostnames, and a request's identity or key must belong to the organization it addresses.
## Access Control
Access is defined in the model and enforced at the gateway, on every query, from every surface:
- **Environment roles** (Admin, Modeler, Viewer) control who can model, publish, and query; workspace and document sharing control analysis. See [Permissions](/docs/platform-admin/permissions).
- **Row and column scope** live next to the data they protect, as [`#(authorize)` gates, secure givens, and field access modifiers](/docs/how-to/modeling/fine-grained-acls) in the model — version-controlled, reviewed like code, and enforced identically for workspace chat, MCP agents, data apps, and the REST APIs.
- **Secure givens resolve server-side** from the caller's verified identity — their email and groups, or an API key's group — so a caller cannot forge them. This is how a product embedding Credible isolates tenants without reimplementing row-level security in application code; see [Tenant Isolation for Embedded Products](/docs/how-to/integrating/apis#tenant-isolation-for-embedded-products).
Fine-grained access control and audit logging are part of the [Enterprise plan](/pricing).
## Data Protection
- **Credentials never leave the control plane.** Database credentials are stored once, in an environment; modelers and consumers never touch the database directly, and every query is proxied.
- **Encrypted in transit.** All traffic terminates TLS behind a global load balancer with a web application firewall. Outbound queries originate from stable egress IPs you can allowlist.
- **Isolation.** Organizations are isolated by identity and hostname on shared clusters; the [Enterprise plan](/docs/platform-admin/deployment) adds dedicated single-tenant clusters, VPC connectivity, and Private Link.
- **Compliance.** Credible is SOC 2 compliant, covering the Security trust services criteria; the security package is available on request from [security@credibledata.com](mailto:security@credibledata.com). Subprocessors and data handling are described in the [privacy policy](/privacy) and [subprocessor list](/subprocessors).
## Audit Trail
Because all consumption routes through one gateway, every query is logged — who asked, from which surface, against which model version, and what it returned — to an immutable audit trail. See [Monitoring](/docs/platform-admin/monitoring).
## Next Steps
Row scope, source access, and column scope in the model
Bearer tokens, API keys, and tenant isolation
---
# Sign In with Microsoft Entra ID
Source: https://www.credibledata.com/docs/reference/auth/entra-id
## Prerequisites
Before configuring Entra ID sign-in, ensure that Credible has set up an organization for you using your work email. If you don't have an organization yet, [contact support](mailto:support@credibledata.com).
## Step 1: Admin Consent for the Credible App
An administrator of your Microsoft Entra ID (Azure AD) tenant must approve the Credible application. This is a one-time setup that allows your organization's users to sign in with their existing Microsoft credentials.
Share the following consent URL with an Entra ID administrator in your organization. Click to open directly, or copy the URL to share:
[Approve Credible Entra ID App →](https://login.microsoftonline.com/common/adminconsent?client_id=ddb6167e-a4a7-40bd-bdf3-159351f9e6ea&redirect_uri=https://docs.credibledata.com/reference/auth/entra-consent-approved)
```
https://login.microsoftonline.com/common/adminconsent?client_id=ddb6167e-a4a7-40bd-bdf3-159351f9e6ea&redirect_uri=https://docs.credibledata.com/reference/auth/entra-consent-approved
```
When the admin clicks the link, Microsoft will ask them to approve the Credible app with the following permissions:
| Permission | Purpose |
|------------|---------|
| **Basic profile details** | Name and email to identify the user in Credible |
| **User Principal Name (UPN)** | Unique identifier used to match users to your Credible organization |
No additional permissions are requested. The Entra ID integration is used solely for authentication — it does not grant Credible access to your organization's directory, mailbox, or any Microsoft 365 resources beyond basic profile information.
The Entra ID admin who approves this does not need to be a Credible admin — they just need admin privileges in your Microsoft Entra ID tenant.
## Step 2: Sign In
After your admin approves the app, you can sign in to Credible using Microsoft Entra ID:
1. Navigate to your Credible app (`https://.app.credibledata.com`)
2. Select the **Microsoft Azure AD** sign-in option
3. An Auth0 authentication page will open — sign in with your Microsoft work account
4. You'll be redirected to the Credible app
You can also sign in via the CLI or the [Credible IDE extension](/docs/how-to/developers/vscode-extension):
```bash
cred login
```
Both will open a browser window where you can select the Microsoft Azure AD sign-in option.
---
# Setting Up BigQuery
Source: https://www.credibledata.com/docs/reference/connections/bigquery
To connect BigQuery to Credible, you'll need to create a Google Cloud service account and download its JSON key file.
## Create a Service Account
1. Go to the [Google Cloud Console](https://console.cloud.google.com)
2. Select your project
3. Navigate to **IAM & Admin** > **Service Accounts**
4. Click **Create Service Account**
5. Enter a name (e.g., `credible-bigquery`)
6. Click **Create and Continue**
## Assign Permissions
Add these roles to the service account:
- **BigQuery Data Viewer** (for read-only access)
- **BigQuery Job User** (to run queries)
If you need write access, use **BigQuery Data Editor** instead of Data Viewer.
Click **Continue**, then **Done**.
## Download the JSON Key
1. Find your service account in the list and click on it
2. Go to the **Keys** tab
3. Click **Add Key** > **Create new key**
4. Select **JSON** and click **Create**
The JSON key file will download automatically. Keep this file secure - it provides access to your BigQuery data.
## Connect in Credible
1. Go to `your-org.app.credibledata.com`
2. Navigate to your environment
3. Click **Add Connection**
4. Select **BigQuery**
5. Upload the JSON key file
6. Test and save the connection
Never commit JSON key files to version control.
---
# BigQuery ML for LLM Classification
Source: https://www.credibledata.com/docs/reference/connections/bigquery-ml
This guide walks through the one-time GCP setup needed to use LLM-based classification via BigQuery ML. Once complete, you can run `ML.GENERATE_TEXT` queries against Gemini models directly from BigQuery.
**Time estimate:** ~15 minutes
## Prerequisites
- A GCP project with BigQuery enabled
- `roles/owner` or `roles/bigquery.admin` + `roles/aiplatform.admin` on the project
## Step 1: Enable the Vertex AI API
1. Go to [APIs & Services](https://console.cloud.google.com/apis/library) in the Google Cloud Console
2. Select your project
3. Search for **"Vertex AI API"**
4. Click on it and click **Enable** (if not already enabled)
## Step 2: Create a Vertex AI Connection in BigQuery
1. In the BigQuery console explorer, click **"+ Add Data"**
2. Search for **"Vertex AI"** and select it
3. Select **"BigQuery Federation"**
4. Name it `vertex-ai-conn` (or any name you prefer)
5. Set the location to match your data (e.g., `US`)
6. Click **"Create Connection"**
## Step 3: Grant the Connection's Service Account Vertex AI Access
1. In BigQuery console explorer, expand **External connections** under your project
2. Click on the `vertex-ai-conn` connection you just created
3. Copy the **Service account id** (looks like `bqcx-123456789-abcd@gcp-sa-bigquery-condel.iam.gserviceaccount.com`)
4. Go to [IAM & Admin](https://console.cloud.google.com/iam-admin/iam) in the Google Cloud Console
5. Click **"Grant Access"**
6. Paste the service account id in the **"New principals"** field
7. In **"Select a role"**, search for and select **"Vertex AI User"**
8. Click **Save**
This step occasionally fails on the first attempt saying the service account doesn't exist. If that happens, wait a minute and try again — it usually works on the second attempt.
## Step 4: Create the Remote LLM Model
1. In BigQuery console, click on your project in the explorer
2. Click the three dots next to your target dataset and select **"Create ML Model"**
3. Name the model (e.g., `gemini_flash`)
4. Choose **"Connect to Vertex AI LLM service and CloudAI services"**
5. In **"Model Options"** select **"Google and Partner Models"**
6. In **"Model Selection"** search for and select **"gemini-2.5-flash-lite"**
7. For the connection, select the `vertex-ai-conn` connection you created in Step 2
8. Click **"Create Model"**
Alternatively, run this SQL directly:
```sql
CREATE OR REPLACE MODEL `your_project.your_dataset.gemini_flash`
REMOTE WITH CONNECTION `your_project.region.vertex-ai-conn`
OPTIONS (ENDPOINT = 'gemini-2.5-flash-lite');
```
Replace `your_project`, `your_dataset`, and `region` with your actual values.
## Step 5: Smoke Test
Run this query in the BigQuery console. If it returns a result, everything is working.
```sql
SELECT *
FROM ML.GENERATE_TEXT(
MODEL `your_project.your_dataset.gemini_flash`,
(SELECT 'What is 2 + 2? Reply with just the number.' AS prompt),
STRUCT(0.0 AS temperature, 10 AS max_output_tokens, TRUE AS flatten_json_output)
);
```
Expected result: a row with `ml_generate_text_llm_result` containing `4`.
## Using Other Models
The same setup works for other Vertex AI models. Repeat Step 4 with a different model selection:
| Use Case | Model | BigQuery Function |
|----------|-------|-------------------|
| Text classification / generation | `gemini-2.5-flash-lite` | `ML.GENERATE_TEXT` |
| Text embeddings (similarity search) | `text-embedding-005` | `ML.GENERATE_EMBEDDING` |
| Multilingual embeddings | `text-multilingual-embedding-002` | `ML.GENERATE_EMBEDDING` |
Each model needs its own `CREATE MODEL` statement, but they can all share the same Vertex AI connection.
## Using with Malloy
There are three ways to use BigQuery ML models from Malloy, depending on your needs.
### Approach 1: Inline LLM Call with `sql_string()`
Calls the LLM at query time for each row. The fastest way to get started — no separate pipeline needed.
```malloy
source: feedback is my_connection.table('my_dataset.feedback') extend {
dimension:
ai_sentiment is sql_string("""
JSON_EXTRACT_SCALAR(
(SELECT ml_generate_text_result
FROM ML.GENERATE_TEXT(
MODEL `my_project.my_dataset.gemini_flash`,
(SELECT CONCAT(
'Classify this feedback as: POSITIVE, NEGATIVE, or NEUTRAL.\n',
'Feedback: ', ${comment}
) AS prompt),
STRUCT(0.0 AS temperature, 10 AS max_output_tokens)
)),
'$.candidates[0].content.parts[0].text'
)
""")
measure:
feedback_count is count()
view: by_sentiment is {
group_by: ai_sentiment
aggregate: feedback_count
}
}
```
This makes an LLM call per row at query time. Great for small datasets and prototyping. For large tables, use Approach 3 to batch-classify and join the results back.
### Approach 2: Wrap ML Results as a Malloy Source with `connection.sql()`
Use `connection.sql()` to make a BigQuery ML query available as a joinable Malloy source. Useful when the ML output needs to be combined with other sources via joins.
```malloy
source: item_embeddings is my_connection.sql("""
SELECT *
FROM ML.GENERATE_EMBEDDING(
MODEL `my_project.my_dataset.embedding_model`,
(SELECT item_name AS content, item_id FROM `my_project.my_dataset.items`),
STRUCT(TRUE AS flatten_json_output, 'SEMANTIC_SIMILARITY' AS task_type)
)
""")
source: items is my_connection.table('my_dataset.items') extend {
join_one: item_embeddings on item_id = item_embeddings.item_id
dimension:
embedding is item_embeddings.ml_generate_embedding_result
}
```
### Approach 3: Batch Classify via MalloySQL, Join Results Back
Best for classifying a large set of items once and reusing the results. Run a `.malloysql` file to materialize a classification table, then reference it as a Malloy source.
**Step 1 — Materialize** (in a `.malloysql` file):
```sql
-- connection:my_connection
CREATE OR REPLACE TABLE `my_project.my_dataset.item_classification` AS
SELECT
src.item_name,
TRIM(llm.ml_generate_text_llm_result) AS category
FROM ML.GENERATE_TEXT(
MODEL `my_project.my_dataset.gemini_flash`,
(SELECT *, CONCAT(
'Classify this item as: Electronics, Clothing, Food, or Other.\n',
'Item: "', item_name, '"\nReturn one word only.'
) AS prompt FROM `my_project.my_dataset.distinct_items`),
STRUCT(0.0 AS temperature, 10 AS max_output_tokens, TRUE AS flatten_json_output)
) AS llm
JOIN `my_project.my_dataset.distinct_items` AS src ON src.item_name = llm.item_name;
```
**Step 2 — Join into your model** (in a `.malloy` file):
```malloy
source: item_classification is my_connection.table('my_dataset.item_classification') extend {
primary_key: item_name
}
source: orders is my_connection.table('my_dataset.orders') extend {
join_one: item_classification with item_name
dimension:
category is item_classification.category ?? 'Unclassified'
measure:
order_count is count()
view: by_category is {
group_by: category
aggregate: order_count
order_by: order_count desc
}
}
```
Items not yet in the classification table fall back to `'Unclassified'` via `??`.
---
# Setting Up Databricks
Source: https://www.credibledata.com/docs/reference/connections/databricks
To connect Databricks to Credible you need a SQL warehouse and credentials for either a **personal access token (PAT)** or an **OAuth machine-to-machine (M2M) service principal**.
## Prerequisites
- A Databricks workspace with Unity Catalog enabled
- Permission to create or use a SQL warehouse
- Permission to create a personal access token, or workspace admin access to create an OAuth service principal
## Step 1: Find or Create a SQL Warehouse
Credible queries Databricks through a SQL warehouse.
1. In the Databricks workspace, go to **SQL Warehouses** in the left sidebar
2. Use an existing warehouse or click **Create SQL warehouse**
3. Give it a name (e.g., `credible-warehouse`) and pick a size — a `Small` Serverless warehouse is a good starting point
4. Click **Create**
Once the warehouse exists, open it and note the following from the **Connection details** tab:
- **Server hostname** — looks like `dbc-xxxxxxxx-xxxx.cloud.databricks.com`. This is the **Host** field in Credible.
- **HTTP Path** — looks like `/sql/1.0/warehouses/`. This is the **HTTP Path** field in Credible.
## Step 2: Create Credentials
Choose **one** of the following authentication methods.
### Option A: Personal Access Token (PAT)
Best for getting started or for connections owned by an individual user.
1. In Databricks, click your user avatar (top right) > **Settings**
2. Go to **Developer** > **Access tokens** > **Manage**
3. Click **Generate new token**
4. Add a comment (e.g., `credible`) and choose a lifetime
5. Click **Generate** and copy the token — you cannot view it again
Treat the PAT like a password. Anyone with the token can act as you in Databricks.
### Option B: OAuth M2M Service Principal
Recommended for production. The connection is owned by a service principal rather than a person, so it survives user offboarding.
1. In Databricks, go to **Settings** > **Identity and access** > **Service principals**
2. Click **Add service principal**, name it (e.g., `credible-sp`), and create it
3. Open the service principal and go to the **Secrets** tab
4. Click **Generate secret** and copy both the **Client ID** and **Client Secret** — the secret is shown only once
5. Grant the service principal access to your SQL warehouse and Unity Catalog data:
- In **SQL Warehouses**, open the warehouse, click **Permissions**, and grant the service principal **Can use**
- In Unity Catalog, grant the service principal `USE CATALOG`, `USE SCHEMA`, and `SELECT` on the catalogs/schemas/tables you want Credible to read
## Step 3: Grant Data Access
Whichever identity you chose (your user for a PAT, or the service principal for OAuth), it needs Unity Catalog privileges on the data you plan to model. At a minimum:
- `USE CATALOG` on the target catalog
- `USE SCHEMA` on each schema
- `SELECT` on each table or view
You can grant these in the Databricks **Catalog Explorer** or via SQL:
```sql
GRANT USE CATALOG ON CATALOG main TO `credible-sp`;
GRANT USE SCHEMA ON SCHEMA main.sales TO `credible-sp`;
GRANT SELECT ON SCHEMA main.sales TO `credible-sp`;
```
## Step 4: Connect in Credible
1. Go to `your-org.app.credibledata.com`
2. Navigate to your environment
3. Click **Add Connection**
4. Select **Databricks**
5. Fill in:
- **Host** — the workspace hostname from Step 1
- **HTTP Path** — the warehouse HTTP path from Step 1
- **Default Catalog** — the Unity Catalog to use by default (e.g., `main`)
- **Default Schema** — optional, the default schema within the catalog (e.g., `default`)
- **Access Token** — paste the PAT from Step 2A, **or**
- **OAuth Client ID** + **OAuth Client Secret** — paste the credentials from Step 2B
6. Click **Test Connection** to verify connectivity
7. Save the connection
Provide either a personal access token **or** OAuth client credentials, not both.
## Troubleshooting
- **`Invalid access token` / `401 Unauthorized`** — The PAT has expired or was revoked. Generate a new one in Databricks user settings.
- **`PERMISSION_DENIED` on a table** — The user or service principal is missing `USE CATALOG`, `USE SCHEMA`, or `SELECT`. Grant the missing privilege in Unity Catalog.
- **Connection times out** — A Serverless warehouse may be cold-starting. Open the warehouse in Databricks and confirm it can start; for classic warehouses, ensure auto-stop hasn't paused it indefinitely.
- **`Catalog not found`** — Double-check the **Default Catalog** value matches a Unity Catalog the identity has `USE CATALOG` on.
---
# Setting Up DuckLake
Source: https://www.credibledata.com/docs/reference/connections/ducklake
DuckLake is a lakehouse format that keeps table metadata in a SQL **catalog** database and stores the underlying data as files in **object storage**. To connect DuckLake to Credible you provide both: a catalog connection for metadata and a storage connection for data.
## Prerequisites
- A **catalog** database for DuckLake metadata — currently **PostgreSQL** is supported
- An **object storage** location for the data — **Amazon S3** or **Google Cloud Storage (GCS)**
- Credentials with read access to both the catalog database and the storage bucket
## Step 1: Prepare the Catalog (PostgreSQL)
DuckLake stores its table metadata in a PostgreSQL database. You can point at an existing database or create a dedicated one.
Have the following ready for the connection:
- **Host** and **Port** (default `5432`)
- **Database Name**
- **Username** and **Password**
You can supply these fields individually or as a single PostgreSQL **connection string** (`postgresql://username:password@hostname:port/database`).
## Step 2: Prepare Storage (S3 or GCS)
DuckLake reads and writes its data files in object storage. Choose S3 or GCS and gather credentials.
For **Amazon S3**:
- **Bucket URL** — e.g. `s3://my-bucket/path`
- **Access Key ID** and **Secret Access Key**
- Optional: **Region**, a **Custom Endpoint** (for S3-compatible stores), and a **Session Token** for temporary STS credentials
Grant the credentials read access to the bucket and prefix that hold your DuckLake data. Write access is only needed if you plan to materialize data back to the lake. You do not need DuckLake to use materialization — the engine keeps its own tables. Connect DuckLake when you want to read from, or write to, a lake you already run.
## Step 3: Connect in Credible
1. Go to `your-org.app.credibledata.com`
2. Navigate to your environment
3. Click **Add Connection**
4. Select **DuckLake**
5. Under **Catalog**, choose **PostgreSQL** and enter the catalog database details from Step 1
6. Under **Storage**, choose **S3** or **GCS** and enter the storage details from Step 2
7. Click **Test Connection** to verify both the catalog and storage are reachable
8. Save the connection
## Troubleshooting
- **Catalog connection fails** — Confirm the PostgreSQL host, port, and credentials are correct and that the database is reachable from the Credible service.
- **Storage access denied** — Check the bucket URL and that the access key can list and read objects under the given prefix. For S3-compatible stores, set the **Custom Endpoint**.
- **Temporary credentials expired** — If you used a **Session Token**, STS credentials are short-lived; regenerate them or switch to a long-lived key.
---
# Retrieval API Reference
Source: https://www.credibledata.com/docs/retrieval-api-reference
Retrieval API reference for the Credible Data API, generated from the OpenAPI specification. Every endpoint lists its parameters, request and response schemas, and example requests in several languages.
Use it to search a published data model's context, the sources, fields, and documentation an agent needs to answer a question, and to search or enumerate the entities the engine has indexed from a connection. It is the retrieval an agent runs before it writes a query.
---
# Delete a group-scoped attribute value
Source: https://www.credibledata.com/docs/admin-api-reference/attributes/delete-a-group-scoped-attribute-value
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/groups/{groupName}/attributes/{attributeName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/attributes/{attributeName}:
delete:
tags:
- attributes
summary: Delete a group-scoped attribute value
operationId: deleteGroupAttributeValue
parameters:
- name: organizationName
in: path
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
schema:
type: string
- name: attributeName
in: path
required: true
schema:
type: string
responses:
"200":
description: Value deleted (idempotent)
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete a user-scoped attribute value
Source: https://www.credibledata.com/docs/admin-api-reference/attributes/delete-a-user-scoped-attribute-value
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/users/{userName}/attributes/{attributeName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/users/{userName}/attributes/{attributeName}:
delete:
tags:
- attributes
summary: Delete a user-scoped attribute value
description: |
Deletes the attribute value for one user (idempotent).
**Authorization**: Requires organization admin.
operationId: deleteUserAttributeValue
parameters:
- name: organizationName
in: path
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userName
in: path
required: true
description: >
The user's userName — their email address (userName == email in this
system; the identity the router resolves attribute values against).
Matches the /users/{userName} resource key.
schema:
type: string
format: email
- name: attributeName
in: path
required: true
schema:
type: string
responses:
"200":
description: Value deleted (idempotent)
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get a trusted attribute and its assigned values
Source: https://www.credibledata.com/docs/admin-api-reference/attributes/get-a-trusted-attribute-and-its-assigned-values
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/attributes/{attributeName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/attributes/{attributeName}:
get:
tags:
- attributes
summary: Get a trusted attribute and its assigned values
description: |
Returns the attribute's declared schema (name + type) and all assigned
user/group values.
**Authorization**: Requires organization admin.
operationId: getAttribute
parameters:
- name: organizationName
in: path
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: attributeName
in: path
required: true
schema:
type: string
responses:
"200":
description: The attribute and its values
content:
application/json:
schema:
$ref: "#/components/schemas/Attribute"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Attribute:
type: object
description: A trusted attribute's declared schema plus all its assigned values.
required:
- name
- attributeType
properties:
name:
type: string
attributeType:
type: string
description: Declared Malloy type; trailing `[]` denotes multi-value.
declaredInModels:
type: array
items:
type: string
values:
type: array
description: User- and group-scoped value entries.
items:
$ref: "#/components/schemas/AttributeValueEntry"
AttributeValueEntry:
type: object
required:
- scope
- subject
properties:
scope:
type: string
enum:
- default
- group
- user
subject:
type: string
description: Email for user scope, group name for group scope, empty string for
default.
precedence:
type: integer
default: 0
value:
description: Scalar or array matching the attribute's declared Malloy type,
validated server-side. Intentionally schema-less because the
concrete type varies per attribute (e.g. string[], number).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List trusted attributes and their assigned values
Source: https://www.credibledata.com/docs/admin-api-reference/attributes/list-trusted-attributes-and-their-assigned-values
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/attributes
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/attributes:
get:
tags:
- attributes
summary: List trusted attributes and their assigned values
description: >
Returns every trusted attribute registered for the organization, each
with
its declared schema (name + type) and all assigned values across
user/group/default scopes. Pages over attribute names; the embedded
user-values within each attribute are NOT bounded by this pagination.
**Authorization**: Requires organization admin.
operationId: listAttributes
parameters:
- name: organizationName
in: path
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–500."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: All trusted attributes with their values
headers:
Total-Count:
description: Total number of trusted attributes available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Attribute"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Attribute:
type: object
description: A trusted attribute's declared schema plus all its assigned values.
required:
- name
- attributeType
properties:
name:
type: string
attributeType:
type: string
description: Declared Malloy type; trailing `[]` denotes multi-value.
declaredInModels:
type: array
items:
type: string
values:
type: array
description: User- and group-scoped value entries.
items:
$ref: "#/components/schemas/AttributeValueEntry"
AttributeValueEntry:
type: object
required:
- scope
- subject
properties:
scope:
type: string
enum:
- default
- group
- user
subject:
type: string
description: Email for user scope, group name for group scope, empty string for
default.
precedence:
type: integer
default: 0
value:
description: Scalar or array matching the attribute's declared Malloy type,
validated server-side. Intentionally schema-less because the
concrete type varies per attribute (e.g. string[], number).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Set a group-scoped attribute value
Source: https://www.credibledata.com/docs/admin-api-reference/attributes/set-a-group-scoped-attribute-value
## OpenAPI
````yaml /docs/api-specs/admin.yaml put /organizations/{organizationName}/groups/{groupName}/attributes/{attributeName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/attributes/{attributeName}:
put:
tags:
- attributes
summary: Set a group-scoped attribute value
description: |
Assigns (creates or replaces) the attribute value for one group, with an
optional precedence rank (lower wins for scalar multi-group resolution).
**Authorization**: Requires organization admin.
operationId: setGroupAttributeValue
parameters:
- name: organizationName
in: path
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
schema:
type: string
- name: attributeName
in: path
required: true
schema:
type: string
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/SetGroupAttributeValueRequest"
responses:
"200":
description: Value assigned
content:
application/json:
schema:
$ref: "#/components/schemas/AttributeValueEntry"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Conflict (value writes for the FGA-sourced GROUPS name are rejected)
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
"422":
description: Value does not match the attribute's declared type
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
SetGroupAttributeValueRequest:
type: object
required:
- value
properties:
value:
description: Scalar or array matching the attribute's declared Malloy type,
validated server-side. Intentionally schema-less because the
concrete type varies per attribute (e.g. string[], number).
precedence:
type: integer
default: 0
description: Group rank for multi-group resolution; lower wins.
AttributeValueEntry:
type: object
required:
- scope
- subject
properties:
scope:
type: string
enum:
- default
- group
- user
subject:
type: string
description: Email for user scope, group name for group scope, empty string for
default.
precedence:
type: integer
default: 0
value:
description: Scalar or array matching the attribute's declared Malloy type,
validated server-side. Intentionally schema-less because the
concrete type varies per attribute (e.g. string[], number).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Set a user-scoped attribute value
Source: https://www.credibledata.com/docs/admin-api-reference/attributes/set-a-user-scoped-attribute-value
## OpenAPI
````yaml /docs/api-specs/admin.yaml put /organizations/{organizationName}/users/{userName}/attributes/{attributeName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/users/{userName}/attributes/{attributeName}:
put:
tags:
- attributes
summary: Set a user-scoped attribute value
description: >
Assigns (creates or replaces) the attribute value for one user. The
value
is type-checked against the attribute's declared type.
**Authorization**: Requires organization admin.
operationId: setUserAttributeValue
parameters:
- name: organizationName
in: path
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userName
in: path
required: true
description: >
The user's userName — their email address (userName == email in this
system; the identity the router resolves attribute values against).
Matches the /users/{userName} resource key.
schema:
type: string
format: email
- name: attributeName
in: path
required: true
schema:
type: string
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/SetAttributeValueRequest"
responses:
"200":
description: Value assigned
content:
application/json:
schema:
$ref: "#/components/schemas/AttributeValueEntry"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Conflict (value writes for the FGA-sourced GROUPS name are rejected)
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
"422":
description: Value does not match the attribute's declared type
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
SetAttributeValueRequest:
type: object
required:
- value
properties:
value:
description: Scalar or array matching the attribute's declared Malloy type,
validated server-side. Intentionally schema-less because the
concrete type varies per attribute (e.g. string[], number).
AttributeValueEntry:
type: object
required:
- scope
- subject
properties:
scope:
type: string
enum:
- default
- group
- user
subject:
type: string
description: Email for user scope, group name for group scope, empty string for
default.
precedence:
type: integer
default: 0
value:
description: Scalar or array matching the attribute's declared Malloy type,
validated server-side. Intentionally schema-less because the
concrete type varies per attribute (e.g. string[], number).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a new bookmark
Source: https://www.credibledata.com/docs/admin-api-reference/bookmarks/create-a-new-bookmark
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/bookmarks
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/bookmarks:
post:
tags:
- bookmarks
summary: Create a new bookmark
description: >
Creates a new bookmark for the current user within the organization.
Bookmarks
allow users to save references to workspaces, models, and chat
conversations.
**Authorization**: Requires read access to the organization.
**Constraints**: Users can only create bookmarks for themselves.
Duplicate bookmarks
(same type and objectId) are not allowed.
operationId: createBookmark
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Bookmark"
responses:
"200":
description: Bookmark created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Bookmark"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Bookmark already exists
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Bookmark:
type: object
description: Represents a user bookmark for saving references to chats, reports,
models, and governed reports
properties:
organizationName:
type: string
description: The organization name this bookmark belongs to
readOnly: true
userName:
type: string
description: The username of the user who owns the bookmark
readOnly: true
bookmarkType:
$ref: "#/components/schemas/BookmarkType"
objectId:
type: string
description: >
The fully-qualified identifier of the bookmarked object. Required
shape per type:
* `CHAT` — `{workspaceName}/{chatDocumentPath}` (1+ slash)
* `REPORT` — `{workspaceName}/{reportDocumentPath}` (1+ slash)
* `MODEL` — `{projectName}/{packageName}/{modelPath}` (2+ slashes)
* `GOVERNED_REPORT` — `{projectName}/{packageName}/{reportPath}` (2+ slashes)
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the bookmark was created
readOnly: true
required:
- bookmarkType
- objectId
BookmarkType:
type: string
description: The type of object being bookmarked
enum:
- CHAT
- REPORT
- MODEL
- GOVERNED_REPORT
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete a bookmark
Source: https://www.credibledata.com/docs/admin-api-reference/bookmarks/delete-a-bookmark
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/bookmarks/{bookmarkType}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/bookmarks/{bookmarkType}:
delete:
tags:
- bookmarks
summary: Delete a bookmark
description: >
Deletes a specific bookmark for the current user. This operation cannot
be undone.
**Authorization**: Requires read access to the organization.
**Constraints**: Users can only delete their own bookmarks.
operationId: deleteBookmark
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: bookmarkType
in: path
required: true
description: The type of bookmark
schema:
$ref: "#/components/schemas/BookmarkType"
- name: objectId
in: query
required: true
description: The fully-qualified identifier of the bookmarked object (see
Bookmark schema)
schema:
type: string
responses:
"200":
description: Bookmark deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
BookmarkType:
type: string
description: The type of object being bookmarked
enum:
- CHAT
- REPORT
- MODEL
- GOVERNED_REPORT
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get a specific bookmark
Source: https://www.credibledata.com/docs/admin-api-reference/bookmarks/get-a-specific-bookmark
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/bookmarks/{bookmarkType}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/bookmarks/{bookmarkType}:
get:
tags:
- bookmarks
summary: Get a specific bookmark
description: >
Retrieves a specific bookmark for the current user by type and object
ID.
**Authorization**: Requires read access to the organization.
**Constraints**: Users can only access their own bookmarks.
operationId: getBookmark
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: bookmarkType
in: path
required: true
description: The type of bookmark
schema:
$ref: "#/components/schemas/BookmarkType"
- name: objectId
in: query
required: true
description: The fully-qualified identifier of the bookmarked object (see
Bookmark schema)
schema:
type: string
responses:
"200":
description: Bookmark retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Bookmark"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
BookmarkType:
type: string
description: The type of object being bookmarked
enum:
- CHAT
- REPORT
- MODEL
- GOVERNED_REPORT
Bookmark:
type: object
description: Represents a user bookmark for saving references to chats, reports,
models, and governed reports
properties:
organizationName:
type: string
description: The organization name this bookmark belongs to
readOnly: true
userName:
type: string
description: The username of the user who owns the bookmark
readOnly: true
bookmarkType:
$ref: "#/components/schemas/BookmarkType"
objectId:
type: string
description: >
The fully-qualified identifier of the bookmarked object. Required
shape per type:
* `CHAT` — `{workspaceName}/{chatDocumentPath}` (1+ slash)
* `REPORT` — `{workspaceName}/{reportDocumentPath}` (1+ slash)
* `MODEL` — `{projectName}/{packageName}/{modelPath}` (2+ slashes)
* `GOVERNED_REPORT` — `{projectName}/{packageName}/{reportPath}` (2+ slashes)
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the bookmark was created
readOnly: true
required:
- bookmarkType
- objectId
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List bookmarks for current user
Source: https://www.credibledata.com/docs/admin-api-reference/bookmarks/list-bookmarks-for-current-user
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/bookmarks
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/bookmarks:
get:
tags:
- bookmarks
summary: List bookmarks for current user
description: >
Retrieves all bookmarks for the current user within the specified
organization.
Optionally filter by bookmark type.
**Authorization**: Requires read access to the organization.
**Filtering**: Use `bookmarkType` parameter to filter by type (CHAT,
REPORT, MODEL, GOVERNED_REPORT).
operationId: listBookmarks
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: bookmarkType
in: query
required: false
description: Optional filter by bookmark type
schema:
$ref: "#/components/schemas/BookmarkType"
responses:
"200":
description: List of bookmarks retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Bookmark"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
BookmarkType:
type: string
description: The type of object being bookmarked
enum:
- CHAT
- REPORT
- MODEL
- GOVERNED_REPORT
Bookmark:
type: object
description: Represents a user bookmark for saving references to chats, reports,
models, and governed reports
properties:
organizationName:
type: string
description: The organization name this bookmark belongs to
readOnly: true
userName:
type: string
description: The username of the user who owns the bookmark
readOnly: true
bookmarkType:
$ref: "#/components/schemas/BookmarkType"
objectId:
type: string
description: >
The fully-qualified identifier of the bookmarked object. Required
shape per type:
* `CHAT` — `{workspaceName}/{chatDocumentPath}` (1+ slash)
* `REPORT` — `{workspaceName}/{reportDocumentPath}` (1+ slash)
* `MODEL` — `{projectName}/{packageName}/{modelPath}` (2+ slashes)
* `GOVERNED_REPORT` — `{projectName}/{packageName}/{reportPath}` (2+ slashes)
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the bookmark was created
readOnly: true
required:
- bookmarkType
- objectId
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create database connection
Source: https://www.credibledata.com/docs/admin-api-reference/connections/create-database-connection
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/environments/{environmentName}/connections
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/connections:
post:
tags:
- connections
summary: Create database connection
description: >
Creates a new database connection for the specified environment with
secure credential
storage and connection validation.
**Authorization**: Requires environment admin permissions.
**Validation**: Tests connection before saving if dryRun is false.
**Security**: Credentials are encrypted and stored securely.
operationId: createConnection
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: dryRun
in: query
required: false
description: Whether to test the connection without saving it
schema:
type: boolean
default: false
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
required: true
responses:
"200":
description: Connection created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Connection:
x-class-name: Connection
allOf:
- $ref: "#/components/schemas/ConnectionBase"
- type: object
properties:
template:
type: string
writeOnly: true
enum:
- bq_demo
description: >
Create this connection from a managed sample template instead of
supplying credentials. The server fills the connection type,
configuration, and credentials from the named template
(currently only `bq_demo`, our sample BigQuery dataset); any
credential or table fields in the request are ignored and the
connection name defaults to the template name when omitted.
Create-only: never stored or returned.
includeTables:
type: array
nullable: true
description: >
The list of tables to include, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to include all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- sales.orders
- finance.*
excludeAllTables:
type: boolean
description: Whether to exclude all tables.
default: false
excludeTables:
type: array
nullable: true
description: >
The list of tables to exclude, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to exclude all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- backup.records
- temp_data.*
indexingStatus:
type: string
enum:
- UNKNOWN
- SCHEMA_INDEXING
- INDEXED
- SKIPPED
- FAILED
- RETRY
- MODEL_SUGGESTION_INDEXING
nullable: true
description: >
Current indexing status of the connection. UNKNOWN means
indexing is queued and starts automatically on creation (no
manual action; "Start indexing" is an optional re-trigger).
SCHEMA_INDEXING means schema indexing is in progress,
MODEL_SUGGESTION_INDEXING means schema indexing finished (schema
search is usable) and the model-suggestions pipeline is
generating dimensions/measures/joins, INDEXED means both
pipelines finished, SKIPPED means the connection is excluded
from indexing, FAILED means schema indexing failed, RETRY means
the connection was updated while indexing was in progress and
will be re-indexed when the current job finishes.
indexingStatusLastUpdated:
type: string
format: date-time
nullable: true
description: ISO 8601 timestamp of when the indexing status was last updated
indexingProgress:
$ref: "#/components/schemas/ConnectionIndexingProgress"
ConnectionBase:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
TableNamePattern:
type: string
pattern: ^(?:[a-zA-Z0-9_-]+\.)?[a-zA-Z0-9_-]+\.(?:[a-zA-Z0-9_-]+|\*)$
description: Table name pattern matching {schema}.{table}, {schema}.*,
{catalog}.{schema}.{table}, or {catalog}.{schema}.*
ConnectionIndexingProgress:
type: object
nullable: true
description: >
Aggregate per-pipeline indexing progress for a connection, polled from
the entity-indexing service while the connection is being indexed.
Populated on the single-connection read while indexing is in progress
(SCHEMA_INDEXING / MODEL_SUGGESTION_INDEXING); null once INDEXED or when
progress is unavailable.
properties:
schemaProgress:
$ref: "#/components/schemas/SchemaIndexingProgress"
modelSuggestionsProgress:
$ref: "#/components/schemas/ModelSuggestionsIndexingProgress"
SchemaIndexingProgress:
type: object
description: Connection-schema pipeline progress (tables and columns).
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
columnsTotal:
type: integer
nullable: true
description: Sum of column counts over all tables (null if no counts recorded
yet).
columnsCompleted:
type: integer
nullable: true
description: Sum of column counts over completed tables.
ModelSuggestionsIndexingProgress:
type: object
description: Connection-model-suggestions pipeline progress.
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
joinWorkTotal:
type: integer
nullable: true
description: Stable denominator for join progress (sum of join-work estimates
over planned tables).
joinWorkCompleted:
type: integer
nullable: true
description: Numerator for join progress (sum of join-work estimates over
completed tables).
joinsGenerated:
type: integer
nullable: true
dimensionsGenerated:
type: integer
nullable: true
measuresGenerated:
type: integer
nullable: true
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete database connection
Source: https://www.credibledata.com/docs/admin-api-reference/connections/delete-database-connection
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/environments/{environmentName}/connections/{connectionName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/connections/{connectionName}:
delete:
tags:
- connections
summary: Delete database connection
description: >
Permanently deletes a database connection and removes all associated
credentials.
This operation is irreversible.
**Authorization**: Requires environment admin permissions.
**Warning**: This operation will remove access to the associated
database.
**Side Effects**: Removes all connection configuration and credentials.
operationId: deleteConnection
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
required: true
description: The unique identifier of the connection
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Connection deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get connection details
Source: https://www.credibledata.com/docs/admin-api-reference/connections/get-connection-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/connections/{connectionName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/connections/{connectionName}:
get:
tags:
- connections
summary: Get connection details
description: >
Retrieves detailed information about a specific database connection
including
configuration, status, and metadata (credentials are not included for
security).
**Authorization**: Requires environment admin permissions.
**Security**: Sensitive credential data is excluded from the response.
operationId: getConnection
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
required: true
description: The unique identifier of the connection
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Connection retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Connection:
x-class-name: Connection
allOf:
- $ref: "#/components/schemas/ConnectionBase"
- type: object
properties:
template:
type: string
writeOnly: true
enum:
- bq_demo
description: >
Create this connection from a managed sample template instead of
supplying credentials. The server fills the connection type,
configuration, and credentials from the named template
(currently only `bq_demo`, our sample BigQuery dataset); any
credential or table fields in the request are ignored and the
connection name defaults to the template name when omitted.
Create-only: never stored or returned.
includeTables:
type: array
nullable: true
description: >
The list of tables to include, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to include all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- sales.orders
- finance.*
excludeAllTables:
type: boolean
description: Whether to exclude all tables.
default: false
excludeTables:
type: array
nullable: true
description: >
The list of tables to exclude, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to exclude all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- backup.records
- temp_data.*
indexingStatus:
type: string
enum:
- UNKNOWN
- SCHEMA_INDEXING
- INDEXED
- SKIPPED
- FAILED
- RETRY
- MODEL_SUGGESTION_INDEXING
nullable: true
description: >
Current indexing status of the connection. UNKNOWN means
indexing is queued and starts automatically on creation (no
manual action; "Start indexing" is an optional re-trigger).
SCHEMA_INDEXING means schema indexing is in progress,
MODEL_SUGGESTION_INDEXING means schema indexing finished (schema
search is usable) and the model-suggestions pipeline is
generating dimensions/measures/joins, INDEXED means both
pipelines finished, SKIPPED means the connection is excluded
from indexing, FAILED means schema indexing failed, RETRY means
the connection was updated while indexing was in progress and
will be re-indexed when the current job finishes.
indexingStatusLastUpdated:
type: string
format: date-time
nullable: true
description: ISO 8601 timestamp of when the indexing status was last updated
indexingProgress:
$ref: "#/components/schemas/ConnectionIndexingProgress"
ConnectionBase:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
TableNamePattern:
type: string
pattern: ^(?:[a-zA-Z0-9_-]+\.)?[a-zA-Z0-9_-]+\.(?:[a-zA-Z0-9_-]+|\*)$
description: Table name pattern matching {schema}.{table}, {schema}.*,
{catalog}.{schema}.{table}, or {catalog}.{schema}.*
ConnectionIndexingProgress:
type: object
nullable: true
description: >
Aggregate per-pipeline indexing progress for a connection, polled from
the entity-indexing service while the connection is being indexed.
Populated on the single-connection read while indexing is in progress
(SCHEMA_INDEXING / MODEL_SUGGESTION_INDEXING); null once INDEXED or when
progress is unavailable.
properties:
schemaProgress:
$ref: "#/components/schemas/SchemaIndexingProgress"
modelSuggestionsProgress:
$ref: "#/components/schemas/ModelSuggestionsIndexingProgress"
SchemaIndexingProgress:
type: object
description: Connection-schema pipeline progress (tables and columns).
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
columnsTotal:
type: integer
nullable: true
description: Sum of column counts over all tables (null if no counts recorded
yet).
columnsCompleted:
type: integer
nullable: true
description: Sum of column counts over completed tables.
ModelSuggestionsIndexingProgress:
type: object
description: Connection-model-suggestions pipeline progress.
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
joinWorkTotal:
type: integer
nullable: true
description: Stable denominator for join progress (sum of join-work estimates
over planned tables).
joinWorkCompleted:
type: integer
nullable: true
description: Numerator for join progress (sum of join-work estimates over
completed tables).
joinsGenerated:
type: integer
nullable: true
dimensionsGenerated:
type: integer
nullable: true
measuresGenerated:
type: integer
nullable: true
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List database connections
Source: https://www.credibledata.com/docs/admin-api-reference/connections/list-database-connections
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/connections
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/connections:
get:
tags:
- connections
summary: List database connections
description: >
Retrieves all database connections configured for the specified
environment, including
connection metadata, status, and configuration details.
**Authorization**: Requires environment admin or modeler permissions.
**Response**: Returns array of connection objects with configuration
details.
**Pagination**: Supports offset-based pagination with limit and offset
parameters.
operationId: listConnections
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–100."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: List of connections retrieved successfully
headers:
Total-Count:
description: Total number of connections available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
example: ;
rel="first",
;
rel="next"
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Connection"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Connection:
x-class-name: Connection
allOf:
- $ref: "#/components/schemas/ConnectionBase"
- type: object
properties:
template:
type: string
writeOnly: true
enum:
- bq_demo
description: >
Create this connection from a managed sample template instead of
supplying credentials. The server fills the connection type,
configuration, and credentials from the named template
(currently only `bq_demo`, our sample BigQuery dataset); any
credential or table fields in the request are ignored and the
connection name defaults to the template name when omitted.
Create-only: never stored or returned.
includeTables:
type: array
nullable: true
description: >
The list of tables to include, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to include all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- sales.orders
- finance.*
excludeAllTables:
type: boolean
description: Whether to exclude all tables.
default: false
excludeTables:
type: array
nullable: true
description: >
The list of tables to exclude, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to exclude all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- backup.records
- temp_data.*
indexingStatus:
type: string
enum:
- UNKNOWN
- SCHEMA_INDEXING
- INDEXED
- SKIPPED
- FAILED
- RETRY
- MODEL_SUGGESTION_INDEXING
nullable: true
description: >
Current indexing status of the connection. UNKNOWN means
indexing is queued and starts automatically on creation (no
manual action; "Start indexing" is an optional re-trigger).
SCHEMA_INDEXING means schema indexing is in progress,
MODEL_SUGGESTION_INDEXING means schema indexing finished (schema
search is usable) and the model-suggestions pipeline is
generating dimensions/measures/joins, INDEXED means both
pipelines finished, SKIPPED means the connection is excluded
from indexing, FAILED means schema indexing failed, RETRY means
the connection was updated while indexing was in progress and
will be re-indexed when the current job finishes.
indexingStatusLastUpdated:
type: string
format: date-time
nullable: true
description: ISO 8601 timestamp of when the indexing status was last updated
indexingProgress:
$ref: "#/components/schemas/ConnectionIndexingProgress"
ConnectionBase:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
TableNamePattern:
type: string
pattern: ^(?:[a-zA-Z0-9_-]+\.)?[a-zA-Z0-9_-]+\.(?:[a-zA-Z0-9_-]+|\*)$
description: Table name pattern matching {schema}.{table}, {schema}.*,
{catalog}.{schema}.{table}, or {catalog}.{schema}.*
ConnectionIndexingProgress:
type: object
nullable: true
description: >
Aggregate per-pipeline indexing progress for a connection, polled from
the entity-indexing service while the connection is being indexed.
Populated on the single-connection read while indexing is in progress
(SCHEMA_INDEXING / MODEL_SUGGESTION_INDEXING); null once INDEXED or when
progress is unavailable.
properties:
schemaProgress:
$ref: "#/components/schemas/SchemaIndexingProgress"
modelSuggestionsProgress:
$ref: "#/components/schemas/ModelSuggestionsIndexingProgress"
SchemaIndexingProgress:
type: object
description: Connection-schema pipeline progress (tables and columns).
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
columnsTotal:
type: integer
nullable: true
description: Sum of column counts over all tables (null if no counts recorded
yet).
columnsCompleted:
type: integer
nullable: true
description: Sum of column counts over completed tables.
ModelSuggestionsIndexingProgress:
type: object
description: Connection-model-suggestions pipeline progress.
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
joinWorkTotal:
type: integer
nullable: true
description: Stable denominator for join progress (sum of join-work estimates
over planned tables).
joinWorkCompleted:
type: integer
nullable: true
description: Numerator for join progress (sum of join-work estimates over
completed tables).
joinsGenerated:
type: integer
nullable: true
dimensionsGenerated:
type: integer
nullable: true
measuresGenerated:
type: integer
nullable: true
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update database connection
Source: https://www.credibledata.com/docs/admin-api-reference/connections/update-database-connection
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/environments/{environmentName}/connections/{connectionName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/connections/{connectionName}:
patch:
tags:
- connections
summary: Update database connection
description: >
Updates the configuration of an existing database connection, including
credentials,
settings, and connection parameters.
**Update semantics**: submit the complete connection. Every field is
replaced
with what you send — to clear an optional parameter (e.g. `proxy`), omit
it.
The sole exception is write-only secrets (passwords, tokens, SSH private
keys): these are never returned by reads, so leaving a secret field
blank
keeps its stored value rather than clearing it.
**Authorization**: Requires environment admin permissions.
**Security**: Credentials are encrypted and stored securely.
**Validation**: Tests connection before saving changes.
operationId: updateConnection
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
required: true
description: The unique identifier of the connection
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
responses:
"200":
description: Connection updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Connection:
x-class-name: Connection
allOf:
- $ref: "#/components/schemas/ConnectionBase"
- type: object
properties:
template:
type: string
writeOnly: true
enum:
- bq_demo
description: >
Create this connection from a managed sample template instead of
supplying credentials. The server fills the connection type,
configuration, and credentials from the named template
(currently only `bq_demo`, our sample BigQuery dataset); any
credential or table fields in the request are ignored and the
connection name defaults to the template name when omitted.
Create-only: never stored or returned.
includeTables:
type: array
nullable: true
description: >
The list of tables to include, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to include all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- sales.orders
- finance.*
excludeAllTables:
type: boolean
description: Whether to exclude all tables.
default: false
excludeTables:
type: array
nullable: true
description: >
The list of tables to exclude, in the format
`{dataset/schema}.{table}`. The first part represents the
dataset or schema, and the second part is the table name. The
second part can be a literal `*` to exclude all tables.
items:
type: string
$ref: "#/components/schemas/TableNamePattern"
example:
- backup.records
- temp_data.*
indexingStatus:
type: string
enum:
- UNKNOWN
- SCHEMA_INDEXING
- INDEXED
- SKIPPED
- FAILED
- RETRY
- MODEL_SUGGESTION_INDEXING
nullable: true
description: >
Current indexing status of the connection. UNKNOWN means
indexing is queued and starts automatically on creation (no
manual action; "Start indexing" is an optional re-trigger).
SCHEMA_INDEXING means schema indexing is in progress,
MODEL_SUGGESTION_INDEXING means schema indexing finished (schema
search is usable) and the model-suggestions pipeline is
generating dimensions/measures/joins, INDEXED means both
pipelines finished, SKIPPED means the connection is excluded
from indexing, FAILED means schema indexing failed, RETRY means
the connection was updated while indexing was in progress and
will be re-indexed when the current job finishes.
indexingStatusLastUpdated:
type: string
format: date-time
nullable: true
description: ISO 8601 timestamp of when the indexing status was last updated
indexingProgress:
$ref: "#/components/schemas/ConnectionIndexingProgress"
ConnectionBase:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
TableNamePattern:
type: string
pattern: ^(?:[a-zA-Z0-9_-]+\.)?[a-zA-Z0-9_-]+\.(?:[a-zA-Z0-9_-]+|\*)$
description: Table name pattern matching {schema}.{table}, {schema}.*,
{catalog}.{schema}.{table}, or {catalog}.{schema}.*
ConnectionIndexingProgress:
type: object
nullable: true
description: >
Aggregate per-pipeline indexing progress for a connection, polled from
the entity-indexing service while the connection is being indexed.
Populated on the single-connection read while indexing is in progress
(SCHEMA_INDEXING / MODEL_SUGGESTION_INDEXING); null once INDEXED or when
progress is unavailable.
properties:
schemaProgress:
$ref: "#/components/schemas/SchemaIndexingProgress"
modelSuggestionsProgress:
$ref: "#/components/schemas/ModelSuggestionsIndexingProgress"
SchemaIndexingProgress:
type: object
description: Connection-schema pipeline progress (tables and columns).
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
columnsTotal:
type: integer
nullable: true
description: Sum of column counts over all tables (null if no counts recorded
yet).
columnsCompleted:
type: integer
nullable: true
description: Sum of column counts over completed tables.
ModelSuggestionsIndexingProgress:
type: object
description: Connection-model-suggestions pipeline progress.
properties:
tablesTotal:
type: integer
tablesProcessing:
type: integer
tablesCompleted:
type: integer
tablesFailed:
type: integer
joinWorkTotal:
type: integer
nullable: true
description: Stable denominator for join progress (sum of join-work estimates
over planned tables).
joinWorkCompleted:
type: integer
nullable: true
description: Numerator for join progress (sum of join-work estimates over
completed tables).
joinsGenerated:
type: integer
nullable: true
dimensionsGenerated:
type: integer
nullable: true
measuresGenerated:
type: integer
nullable: true
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create demo environment
Source: https://www.credibledata.com/docs/admin-api-reference/demo/create-demo-environment
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /demo/create_environment
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/demo/create_environment:
post:
tags:
- demo
summary: Create demo environment
description: >
Creates a demo environment with sample data and configurations for
testing and
demonstration purposes.
**Authorization**: No authentication required for demo purposes.
**Purpose**: Provides a quick way to set up a sample environment for
evaluation.
**Content**: Includes sample packages, connections, and data models.
operationId: createDemoEnvironment
responses:
"200":
description: Demo environment created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
Environment:
type: object
description: Represents a environment entity that serves as a container for
packages and related resources
properties:
name:
type: string
description: The unique name of the environment within its organization
$ref: "#/components/schemas/IdentifierPattern"
readme:
type: string
description: Markdown-formatted documentation describing the environment's
purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create self-service organization
Source: https://www.credibledata.com/docs/admin-api-reference/demo/create-self-service-organization
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /demo/create_self_service_organization
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/demo/create_self_service_organization:
post:
tags:
- demo
summary: Create self-service organization
description: >
Creates a new organization through self-service registration, allowing
users to
quickly set up their own organizational environment.
**Authorization**: No authentication required for self-service
registration.
**Purpose**: Enables quick onboarding and organization setup.
**Features**: Creates organization with default permissions and initial
structure.
operationId: createSelfServiceOrganization
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Organization"
responses:
"200":
description: Self-service organization created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Organization"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
Organization:
type: object
description: Represents an organization entity that serves as the top-level
container for all resources
properties:
name:
type: string
description: |
The unique identifier for the organization. Used as the resource
name in API paths AND as the DNS subdomain label routing traffic
to the org, so it follows RFC 1035 hostname rules — lowercase
letters, digits, and hyphens; no underscores; no leading or
trailing hyphen; max 63 chars.
$ref: "#/components/schemas/DnsLabelPattern"
displayName:
description: Human-readable name for the organization, displayed in user
interfaces
$ref: "#/components/schemas/HumanTextPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was last modified
mpaVersion:
type: string
readOnly: true
description: |
Version identifier of the Master Platform Agreement the organization
accepted at creation time (file basename, e.g. `v1-2026-05-19`).
Server-set: clients do not (and cannot) submit this field — when an
organization is created via the invite-redemption path, the server
stamps its current active MPA version. Null on legacy organizations
created before MPA acceptance was required.
Only the version is exposed on this resource. The per-user / per-
timestamp audit fields (`mpa_accepted_by`, `mpa_accepted_at`)
are kept internal — useful for compliance audit on the server
side, not for API consumers. If a future use case needs them on
the API, add them then; widening is easier than narrowing.
$ref: "#/components/schemas/MpaVersionPattern"
DnsLabelPattern:
type: string
minLength: 1
maxLength: 63
pattern: ^[a-z0-9](?:[a-z0-9-]{0,61}[a-z0-9])?$
description: DNS label — 1–63 chars, lowercase letters / digits / hyphens, no
leading or trailing hyphen. Used as a subdomain for organizations.
HumanTextPattern:
type: string
minLength: 1
maxLength: 128
pattern: ^[^\u0000-\u001F\u007F]+$
description: Short human-readable text — non-empty, no ASCII control characters,
capped at 128 chars. Used for display names, person names, and similar
free-text fields where we want to keep things short and printable.
MpaVersionPattern:
type: string
minLength: 1
maxLength: 32
pattern: ^[a-zA-Z0-9._-]+$
description: MPA version identifier — alphanumeric, dot, hyphen, underscore;
mirrors the version-string convention used in the on-disk markdown file
names (e.g. v1-2026-05-19).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create document permission
Source: https://www.credibledata.com/docs/admin-api-reference/documentpermissions/create-document-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions:
post:
tags:
- documentPermissions
summary: Create document permission
description: >
Creates a new permission assignment for a user or group within the
document,
granting them specific roles and access levels. Can also be used to
request access
to the document when the user doesn't have editor or workspace manager
permissions.
**Authorization**: Requires document editor or workspace manager
permissions, unless `requestPermission` is true.
**Parameters**: Use `requestPermission` to indicate the user is
requesting access to the resource.
**Roles**: Supports editor and viewer roles.
operationId: createDocumentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
- name: requestPermission
in: query
required: false
description: Indicates that the user is requesting access to the resource
schema:
type: boolean
default: false
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/DocumentPermission"
responses:
"200":
description: Document permission created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/DocumentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
DocumentPermission:
type: object
description: Represents a permission assignment for a user or group within a document
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- editor
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent workspace
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete document permission
Source: https://www.credibledata.com/docs/admin-api-reference/documentpermissions/delete-document-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions/{userGroupId}:
delete:
tags:
- documentPermissions
summary: Delete document permission
description: >
Removes the permission assignment for a user or group within the
document,
revoking their access to document resources.
**Authorization**: Requires document editor or workspace manager
permissions.
**Side Effects**: User/group loses access to document resources.
operationId: deleteDocumentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Document permission deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get document permission
Source: https://www.credibledata.com/docs/admin-api-reference/documentpermissions/get-document-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions/{userGroupId}:
get:
tags:
- documentPermissions
summary: Get document permission
description: >
Retrieves the permission details for a specific user or group within the
document,
including their role and access level.
**Authorization**: Requires document editor or workspace manager
permissions.
**Response**: Returns permission object with role and metadata.
operationId: getDocumentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Document permission retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/DocumentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
DocumentPermission:
type: object
description: Represents a permission assignment for a user or group within a document
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- editor
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent workspace
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List document permissions
Source: https://www.credibledata.com/docs/admin-api-reference/documentpermissions/list-document-permissions
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions:
get:
tags:
- documentPermissions
summary: List document permissions
description: >
Retrieves all permission assignments for the specified document,
including user and group
permissions with their roles and access levels.
**Authorization**: Requires document editor or workspace manager
permissions.
**Response**: Returns array of permission objects with user/group
identifiers and roles.
operationId: listDocumentPermissions
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
responses:
"200":
description: List of document permissions retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/DocumentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
DocumentPermission:
type: object
description: Represents a permission assignment for a user or group within a document
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- editor
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent workspace
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update document permission
Source: https://www.credibledata.com/docs/admin-api-reference/documentpermissions/update-document-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}/permissions/{userGroupId}:
patch:
tags:
- documentPermissions
summary: Update document permission
description: >
Updates the permission assignment for a user or group within the
document,
modifying their role and access level.
**Authorization**: Requires document editor or workspace manager
permissions.
**Validation**: Role changes are validated against document constraints.
operationId: updateDocumentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/DocumentPermission"
responses:
"200":
description: Document permission updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/DocumentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
DocumentPermission:
type: object
description: Represents a permission assignment for a user or group within a document
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- editor
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent workspace
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create document
Source: https://www.credibledata.com/docs/admin-api-reference/documents/create-document
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/workspaces/{workspaceName}/documents
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents:
post:
tags:
- documents
summary: Create document
description: >
Creates a new document within the workspace (the `{workspaceName}` in
the path is the
destination), such as a workbook or dashboard.
**Authorization**: Requires workspace manager or editor permissions.
**Parameters**: Use `overwrite` to replace existing documents with the
same path.
**Content**: Supports Malloy code, configuration, and other document
types.
**Relocating an existing document**: Set `moveFrom` to the `credible://`
URI of a
document in another workspace to atomically relocate it into this
workspace instead of
creating from the request body. The source document is deleted, its
content/metadata are
transplanted under the same path here, and chat/report bookmarks are
re-pointed. The
request body is ignored in this mode. The destination workspace must be
a shared (Group)
workspace and must already have every package the source document
references — the
endpoint deliberately does NOT silently attach packages (that would be a
backdoor for
granting package read access). Returns 400 if a required package is
missing; attach it
via the package-permission endpoints first and retry.
operationId: createDocument
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the destination workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: overwrite
description: If true, the document will be overwritten if it already exists
in: query
required: false
schema:
type: boolean
- name: moveFrom
description: "Optional `credible://` URI of a source document to relocate into
this workspace (e.g.
`credible://workspaces/{sourceWorkspace}/documents/{sourcePath}`).
When set, the source document is moved here under the same path and
the request body is ignored. Only data chats and reports may be
moved. Not constrained by ResourceIdentifierPattern: the embedded
workspace name and document path allow spaces and punctuation (see
WorkspaceNamePattern / DocumentPathPattern). The URI is structurally
validated by the server (parsed into workspace + document path) and
the move is authorized against the resolved source document."
in: query
required: false
schema:
type: string
maxLength: 512
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Document"
responses:
"200":
description: Document created (or relocated) successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Document"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: A document already exists at the destination path (relocate without
overwrite)
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
Document:
type: object
description: Represents a document within a workspace, such as a workbook or dashboard
properties:
path:
type: string
description: The file path of the document within the workspace
$ref: "#/components/schemas/DocumentPathPattern"
content:
type: string
description: The content of the document, typically Malloy code or configuration
type:
type: string
description: The type of document, determining its purpose and behavior
enum:
- workbook
- dashboard
- modeling_chat
- data_chat
- agent_report
- agent_modeling_file
- agent_html_report
- draft_agent_html_report
- draft_agent_report
- draft_package
- model_summary
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was last modified
modifiedBy:
type: string
nullable: true
description: The userId of the user who last modified this document
metadata:
type: object
nullable: true
description: Optional JSON metadata associated with the document (e.g. title,
tags)
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete document
Source: https://www.credibledata.com/docs/admin-api-reference/documents/delete-document
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}:
delete:
tags:
- documents
summary: Delete document
description: >
Permanently deletes a document from the workspace. This operation is
irreversible.
**Authorization**: Requires document editor or workspace manager
permissions.
**Warning**: This operation will permanently remove the document and its
content.
operationId: deleteDocument
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
responses:
"200":
description: Document deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get document details
Source: https://www.credibledata.com/docs/admin-api-reference/documents/get-document-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}:
get:
tags:
- documents
summary: Get document details
description: >
Retrieves detailed information about a specific document including
content, metadata,
and configuration details.
**Authorization**: Requires read access to the document.
**Parameters**: The `checkAdmin` parameter can be used to verify admin
privileges.
operationId: getDocument
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
- name: checkAdmin
in: query
required: false
description: Whether to verify admin privileges for the resource
schema:
type: boolean
default: false
responses:
"200":
description: Document updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Document"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
Document:
type: object
description: Represents a document within a workspace, such as a workbook or dashboard
properties:
path:
type: string
description: The file path of the document within the workspace
$ref: "#/components/schemas/DocumentPathPattern"
content:
type: string
description: The content of the document, typically Malloy code or configuration
type:
type: string
description: The type of document, determining its purpose and behavior
enum:
- workbook
- dashboard
- modeling_chat
- data_chat
- agent_report
- agent_modeling_file
- agent_html_report
- draft_agent_html_report
- draft_agent_report
- draft_package
- model_summary
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was last modified
modifiedBy:
type: string
nullable: true
description: The userId of the user who last modified this document
metadata:
type: object
nullable: true
description: Optional JSON metadata associated with the document (e.g. title,
tags)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List workspace documents
Source: https://www.credibledata.com/docs/admin-api-reference/documents/list-workspace-documents
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/{workspaceName}/documents
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents:
get:
tags:
- documents
summary: List workspace documents
description: >
Retrieves all documents within the specified workspace, including
workbooks, dashboards,
and other content files.
**Authorization**: Requires read access to the workspace.
**Response**: Returns array of document objects with metadata and
content information.
operationId: listDocuments
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: retrieveContent
in: query
required: false
description: If true, include the document content in the response. Defaults to
false.
schema:
type: boolean
default: false
responses:
"200":
description: List of documents retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Document"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
Document:
type: object
description: Represents a document within a workspace, such as a workbook or dashboard
properties:
path:
type: string
description: The file path of the document within the workspace
$ref: "#/components/schemas/DocumentPathPattern"
content:
type: string
description: The content of the document, typically Malloy code or configuration
type:
type: string
description: The type of document, determining its purpose and behavior
enum:
- workbook
- dashboard
- modeling_chat
- data_chat
- agent_report
- agent_modeling_file
- agent_html_report
- draft_agent_html_report
- draft_agent_report
- draft_package
- model_summary
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was last modified
modifiedBy:
type: string
nullable: true
description: The userId of the user who last modified this document
metadata:
type: object
nullable: true
description: Optional JSON metadata associated with the document (e.g. title,
tags)
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update document
Source: https://www.credibledata.com/docs/admin-api-reference/documents/update-document
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/documents/{documentPath}:
patch:
tags:
- documents
summary: Update document
description: >
Updates the content and metadata of an existing document within the
workspace.
**Authorization**: Requires document editor or workspace manager
permissions.
**Content**: Supports updating document content, type, and other
properties.
operationId: updateDocument
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: documentPath
in: path
required: true
description: The path to the document within the workspace
schema:
$ref: "#/components/schemas/DocumentPathPattern"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Document"
responses:
"200":
description: Document updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Document"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
DocumentPathPattern:
type: string
maxLength: 255
pattern: ^(?!.*\.\.)[a-zA-Z0-9_/. \-&:,'+?!()$^–—]+$
description: "Document path. Permits alphanumerics, spaces, ASCII hyphen,
Unicode en-dash/em-dash (U+2013/U+2014), and common title punctuation (&
: , ' + ? ! ( ) $ ^). Bans path traversal (..). Length capped at 255 to
match the underlying varchar(255) storage column. % is deliberately
excluded because @InitBinder decodes %2F → / in path variables to fix
encoded-slash routing, which would collide with any path that
legitimately contained '%2F'."
Document:
type: object
description: Represents a document within a workspace, such as a workbook or dashboard
properties:
path:
type: string
description: The file path of the document within the workspace
$ref: "#/components/schemas/DocumentPathPattern"
content:
type: string
description: The content of the document, typically Malloy code or configuration
type:
type: string
description: The type of document, determining its purpose and behavior
enum:
- workbook
- dashboard
- modeling_chat
- data_chat
- agent_report
- agent_modeling_file
- agent_html_report
- draft_agent_html_report
- draft_agent_report
- draft_package
- model_summary
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the document was last modified
modifiedBy:
type: string
nullable: true
description: The userId of the user who last modified this document
metadata:
type: object
nullable: true
description: Optional JSON metadata associated with the document (e.g. title,
tags)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create environment permission
Source: https://www.credibledata.com/docs/admin-api-reference/environmentpermissions/create-environment-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/environments/{environmentName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/permissions:
post:
tags:
- environmentPermissions
summary: Create environment permission
description: >
Creates a new permission assignment for a user or group within the
environment,
granting them specific roles and access levels. Can also be used to
request access
to the environment when the user doesn't have admin permissions.
**Authorization**: Requires environment admin permissions, unless
`requestPermission` is true.
**Parameters**: Use `requestPermission` to indicate the user is
requesting access to the resource.
**Notification**: Use `notifyPeople` to send email notifications to
affected users.
operationId: createEnvironmentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: requestPermission
in: query
required: false
description: Indicates that the user is requesting access to the resource
schema:
type: boolean
default: false
- name: notifyPeople
in: query
required: false
description: Whether to notify people when permissions are granted
schema:
type: boolean
default: false
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/EnvironmentPermission"
responses:
"200":
description: Environment permission created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/EnvironmentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
EnvironmentPermission:
type: object
description: Represents a permission assignment for a user or group within a
environment
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete environment permission
Source: https://www.credibledata.com/docs/admin-api-reference/environmentpermissions/delete-environment-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/environments/{environmentName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/permissions/{userGroupId}:
delete:
tags:
- environmentPermissions
summary: Delete environment permission
description: >
Removes the permission assignment for a user or group within the
environment,
revoking their access to environment resources.
**Authorization**: Requires environment admin permissions.
**Side Effects**: User/group loses access to environment resources.
operationId: deleteEnvironmentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Environment permission deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get environment permission
Source: https://www.credibledata.com/docs/admin-api-reference/environmentpermissions/get-environment-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/permissions/{userGroupId}:
get:
tags:
- environmentPermissions
summary: Get environment permission
description: >
Retrieves the permission details for a specific user or group within the
environment,
including their role and access level.
**Authorization**: Requires environment admin, modeler, or viewer
permissions.
**Response**: Returns permission object with role and metadata.
operationId: getEnvironmentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Environment permission retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/EnvironmentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
EnvironmentPermission:
type: object
description: Represents a permission assignment for a user or group within a
environment
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List environment permissions
Source: https://www.credibledata.com/docs/admin-api-reference/environmentpermissions/list-environment-permissions
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/permissions:
get:
tags:
- environmentPermissions
summary: List environment permissions
description: >
Retrieves all permission assignments for the specified environment,
including user and group
permissions with their roles and access levels.
**Authorization**: Requires environment admin, modeler, or viewer
permissions.
**Response**: Returns array of permission objects with user/group
identifiers and roles.
operationId: listEnvironmentPermissions
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: List of environment permissions retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/EnvironmentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
EnvironmentPermission:
type: object
description: Represents a permission assignment for a user or group within a
environment
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update environment permission
Source: https://www.credibledata.com/docs/admin-api-reference/environmentpermissions/update-environment-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/environments/{environmentName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/permissions/{userGroupId}:
patch:
tags:
- environmentPermissions
summary: Update environment permission
description: >
Updates the permission assignment for a user or group within the
environment,
modifying their role and access level.
**Authorization**: Requires environment admin permissions.
**Validation**: Role changes are validated against environment
constraints.
operationId: updateEnvironmentPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/EnvironmentPermission"
responses:
"200":
description: Environment permission updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/EnvironmentPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
EnvironmentPermission:
type: object
description: Represents a permission assignment for a user or group within a
environment
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a new environment
Source: https://www.credibledata.com/docs/admin-api-reference/environments/create-a-new-environment
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/environments
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments:
post:
tags:
- environments
summary: Create a new environment
description: >
Creates a new environment within the specified organization.
Environments serve as containers
for packages and provide a logical grouping for related data models.
**Authorization**: Requires organization admin permissions.
**Validation**: Environment names must be unique within the
organization.
**Side Effects**: Creates default environment permissions and
initializes environment structure.
operationId: createEnvironment
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
required: true
responses:
"200":
description: Environment created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Environment:
type: object
description: Represents a environment entity that serves as a container for
packages and related resources
properties:
name:
type: string
description: The unique name of the environment within its organization
$ref: "#/components/schemas/IdentifierPattern"
readme:
type: string
description: Markdown-formatted documentation describing the environment's
purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete environment
Source: https://www.credibledata.com/docs/admin-api-reference/environments/delete-environment
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/environments/{environmentName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}:
delete:
tags:
- environments
summary: Delete environment
description: >
Permanently deletes a environment and all associated packages, versions,
and connections.
This operation is irreversible.
**Authorization**: Requires environment admin permissions.
**Warning**: This operation will cascade delete all child resources.
**Side Effects**: Removes all packages, versions, and connections within
the environment.
operationId: deleteEnvironment
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Environment deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get environment details
Source: https://www.credibledata.com/docs/admin-api-reference/environments/get-environment-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}:
get:
tags:
- environments
summary: Get environment details
description: >
Retrieves detailed information about a specific environment including
metadata,
configuration, and administrative details.
**Authorization**: Requires read access to the environment.
**Parameters**: The `checkAdmin` parameter can be used to verify admin
privileges.
operationId: getEnvironment
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: checkAdmin
in: query
required: false
description: Whether to verify admin privileges for the resource
schema:
type: boolean
default: false
responses:
"200":
description: Environment details retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Environment:
type: object
description: Represents a environment entity that serves as a container for
packages and related resources
properties:
name:
type: string
description: The unique name of the environment within its organization
$ref: "#/components/schemas/IdentifierPattern"
readme:
type: string
description: Markdown-formatted documentation describing the environment's
purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List environments in organization
Source: https://www.credibledata.com/docs/admin-api-reference/environments/list-environments-in-organization
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments:
get:
tags:
- environments
summary: List environments in organization
description: >
Retrieves all environments within the specified organization, including
metadata such as
names, descriptions, creation dates, and replication counts.
**Authorization**: Requires read access to the organization.
**Response**: Returns array of environment objects with full metadata.
**Pagination**: Supports offset-based pagination with limit and offset
parameters.
operationId: listEnvironments
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–100."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: List of environments retrieved successfully
headers:
Total-Count:
description: Total number of environments available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
example: ;
rel="first",
;
rel="next"
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Environment"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Environment:
type: object
description: Represents a environment entity that serves as a container for
packages and related resources
properties:
name:
type: string
description: The unique name of the environment within its organization
$ref: "#/components/schemas/IdentifierPattern"
readme:
type: string
description: Markdown-formatted documentation describing the environment's
purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update environment details
Source: https://www.credibledata.com/docs/admin-api-reference/environments/update-environment-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/environments/{environmentName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}:
patch:
tags:
- environments
summary: Update environment details
description: >
Partially updates a environment's details. Only the provided fields will
be updated.
This operation allows for selective updates without requiring all
environment fields.
**Authorization**: Requires environment admin permissions.
**Validation**: All provided fields are validated according to their
schema constraints.
**Side Effects**: Updates the environment's `updatedAt` timestamp.
operationId: updateEnvironment
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization containing the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique name of the environment to update
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
description: Partial environment data to update
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
responses:
"200":
description: Environment updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Environment:
type: object
description: Represents a environment entity that serves as a container for
packages and related resources
properties:
name:
type: string
description: The unique name of the environment within its organization
$ref: "#/components/schemas/IdentifierPattern"
readme:
type: string
description: Markdown-formatted documentation describing the environment's
purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the environment was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Add group members
Source: https://www.credibledata.com/docs/admin-api-reference/groups/add-group-members
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/groups/{groupName}/members
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/members:
post:
tags:
- groups
operationId: addGroupMembers
summary: Add group members
description: >
Adds new members to a group, including users and nested groups with
their
specified roles and status.
**Authorization**: Requires group admin permissions.
**Members**: Supports adding users and other groups as members.
**Roles**: Members can be assigned admin or member status.
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
requestBody:
content:
application/json:
schema:
type: object
properties:
members:
type: array
items:
$ref: "#/components/schemas/GroupMember"
description: List of members to add with their status and CredibleResourceUri
responses:
"200":
description: Members added successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
GroupMember:
type: object
description: Represents a member of a group with their role and status
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
status:
type: string
description: The membership role within the group, determining permissions and
capabilities
enum:
- admin
- member
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a new group token
Source: https://www.credibledata.com/docs/admin-api-reference/groups/create-a-new-group-token
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/groups/{groupName}/tokens
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/tokens:
post:
tags:
- groups
summary: Create a new group token
description: >
Creates a new access token for the specified group. The token secret
is only returned in the response to this creation request and cannot be
retrieved later.
**Authorization**: Requires group admin permissions.
**Security**: Store the returned secret securely as it cannot be
retrieved again.
operationId: createGroupAccessToken
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
- name: name
in: query
required: true
description: The unique name for the token within the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: expiresAt
in: query
required: false
description: Optional expiration date for the token. If not provided, defaults
to 99 years from creation
schema:
type: string
format: date-time
responses:
"200":
description: Group token created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/GroupAccessToken"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
GroupAccessToken:
type: object
description: Represents an access token/key for a service account
properties:
name:
type: string
description: Unique name for the access token within the organization
$ref: "#/components/schemas/IdentifierPattern"
jwtToken:
type: string
description: The JWT token (only returned when creating a new token)
writeOnly: true
groupName:
type: string
description: The name of the group that the token belongs to
$ref: "#/components/schemas/GroupNamePattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the token was created
expiresAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the token expires
expired:
type: boolean
description: Whether the token has expired
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create user group
Source: https://www.credibledata.com/docs/admin-api-reference/groups/create-user-group
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/groups
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups:
post:
tags:
- groups
summary: Create user group
description: >
Creates a new user group within the organization for organizing users
and
managing group-based permissions.
**Authorization**: Requires organization admin permissions.
**Validation**: Group names must be unique within the organization.
operationId: createGroup
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Group"
responses:
"200":
description: Group created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Group"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Group:
type: object
description: Represents a user group for organizing users and managing
group-based permissions
properties:
organizationName:
type: string
description: The name of the organization that owns this group
$ref: "#/components/schemas/IdentifierPattern"
groupName:
type: string
description: The unique identifier for the group within the organization
$ref: "#/components/schemas/GroupNamePattern"
description:
type: string
description: Human-readable description of the group's purpose and membership
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was last modified
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete a group token
Source: https://www.credibledata.com/docs/admin-api-reference/groups/delete-a-group-token
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/groups/{groupName}/tokens/{tokenName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/tokens/{tokenName}:
delete:
tags:
- groups
summary: Delete a group token
description: >
Deletes an existing group token. This action is irreversible and will
immediately invalidate the token.
**Authorization**: Requires group admin permissions.
**Warning**: This operation cannot be undone and will immediately revoke
access.
operationId: deleteGroupAccessToken
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
- name: tokenName
in: path
required: true
description: The unique identifier of the token to delete
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Group token deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete user group
Source: https://www.credibledata.com/docs/admin-api-reference/groups/delete-user-group
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/groups/{groupName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}:
delete:
tags:
- groups
summary: Delete user group
description: >
Permanently deletes a user group and removes all associated permissions.
This operation is irreversible.
**Authorization**: Requires group admin or organization modeler
permissions.
**Warning**: This operation will remove all group permissions and
memberships.
**Side Effects**: Removes group from all permission assignments.
operationId: deleteGroup
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
responses:
"200":
description: Group deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get group details
Source: https://www.credibledata.com/docs/admin-api-reference/groups/get-group-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/groups/{groupName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}:
get:
tags:
- groups
summary: Get group details
description: >
Retrieves detailed information about a specific group including
metadata,
description, and configuration details.
**Authorization**: Requires read access to the group.
**Response**: Returns complete group object with all metadata.
operationId: getGroup
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
responses:
"200":
description: Group details retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Group"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
Group:
type: object
description: Represents a user group for organizing users and managing
group-based permissions
properties:
organizationName:
type: string
description: The name of the organization that owns this group
$ref: "#/components/schemas/IdentifierPattern"
groupName:
type: string
description: The unique identifier for the group within the organization
$ref: "#/components/schemas/GroupNamePattern"
description:
type: string
description: Human-readable description of the group's purpose and membership
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get group members
Source: https://www.credibledata.com/docs/admin-api-reference/groups/get-group-members
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/groups/{groupName}/members
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/members:
get:
tags:
- groups
operationId: getGroupMembers
summary: Get group members
description: >
Retrieves all members of a group from FGA (Fine-Grained Authorization),
including
users and nested groups with their membership status and roles.
**Authorization**: Requires read access to the group.
**Response**: Returns array of group members with status and resource
identifiers.
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
responses:
"200":
description: Group members retrieved successfully
content:
application/json:
schema:
type: object
properties:
members:
type: array
items:
$ref: "#/components/schemas/GroupMember"
description: List of all group members (users and groups) with their status and
CredibleResourceUri
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
GroupMember:
type: object
description: Represents a member of a group with their role and status
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
status:
type: string
description: The membership role within the group, determining permissions and
capabilities
enum:
- admin
- member
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List group tokens
Source: https://www.credibledata.com/docs/admin-api-reference/groups/list-group-tokens
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/groups/{groupName}/tokens
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/tokens:
get:
tags:
- groups
summary: List group tokens
description: |
Retrieves all access tokens for the specified group. Token secrets are
not included in the response for security reasons.
**Authorization**: Requires group admin permissions.
**Security**: Secrets are never returned in list operations.
operationId: listGroupAccessTokens
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
responses:
"200":
description: List of group tokens retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/GroupAccessToken"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
GroupAccessToken:
type: object
description: Represents an access token/key for a service account
properties:
name:
type: string
description: Unique name for the access token within the organization
$ref: "#/components/schemas/IdentifierPattern"
jwtToken:
type: string
description: The JWT token (only returned when creating a new token)
writeOnly: true
groupName:
type: string
description: The name of the group that the token belongs to
$ref: "#/components/schemas/GroupNamePattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the token was created
expiresAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the token expires
expired:
type: boolean
description: Whether the token has expired
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List organization groups
Source: https://www.credibledata.com/docs/admin-api-reference/groups/list-organization-groups
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/groups
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups:
get:
tags:
- groups
summary: List organization groups
description: >
Retrieves all groups within the specified organization, including
metadata such as
names, descriptions, and member counts.
**Authorization**: Requires read access to the organization.
**Response**: Returns array of group objects with full metadata.
operationId: listGroups
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: List of groups retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Group"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Group:
type: object
description: Represents a user group for organizing users and managing
group-based permissions
properties:
organizationName:
type: string
description: The name of the organization that owns this group
$ref: "#/components/schemas/IdentifierPattern"
groupName:
type: string
description: The unique identifier for the group within the organization
$ref: "#/components/schemas/GroupNamePattern"
description:
type: string
description: Human-readable description of the group's purpose and membership
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was last modified
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Remove group members
Source: https://www.credibledata.com/docs/admin-api-reference/groups/remove-group-members
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/groups/{groupName}/members
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/members:
delete:
tags:
- groups
operationId: removeGroupMembers
summary: Remove group members
description: >
Removes members from a group, revoking their group membership and
associated
permissions.
**Authorization**: Requires group admin permissions.
**Members**: Supports removing users and nested groups from membership.
**Side Effects**: Removed members lose group-based permissions.
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
requestBody:
content:
application/json:
schema:
type: object
properties:
members:
type: array
items:
$ref: "#/components/schemas/GroupMember"
description: List of members to remove (only member CredibleResourceUri is
required)
responses:
"200":
description: Members removed successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
GroupMember:
type: object
description: Represents a member of a group with their role and status
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
status:
type: string
description: The membership role within the group, determining permissions and
capabilities
enum:
- admin
- member
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update group configuration
Source: https://www.credibledata.com/docs/admin-api-reference/groups/update-group-configuration
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/groups/{groupName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}:
patch:
tags:
- groups
summary: Update group configuration
description: >
Updates the configuration and metadata of an existing group, including
description
and other group-level properties.
**Authorization**: Requires group admin or organization modeler
permissions.
**Validation**: Updates are validated against group constraints.
operationId: updateGroup
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Group"
responses:
"200":
description: Group updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Group"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
Group:
type: object
description: Represents a user group for organizing users and managing
group-based permissions
properties:
organizationName:
type: string
description: The name of the organization that owns this group
$ref: "#/components/schemas/IdentifierPattern"
groupName:
type: string
description: The unique identifier for the group within the organization
$ref: "#/components/schemas/GroupNamePattern"
description:
type: string
description: Human-readable description of the group's purpose and membership
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the group was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update group member status
Source: https://www.credibledata.com/docs/admin-api-reference/groups/update-group-member-status
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/groups/{groupName}/members/{memberName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/groups/{groupName}/members/{memberName}:
patch:
tags:
- groups
operationId: updateGroupMemberStatus
summary: Update group member status
description: >
Updates a member's status (admin/member) in a group. This operation
manages group
membership through FGA (Fine-Grained Authorization) and affects the
member's
permissions within the group.
**Authorization**: Requires group admin permissions.
**Status**: Supports changing between admin and member roles.
**Side Effects**: Status changes affect member permissions and
capabilities.
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: groupName
in: path
required: true
description: The unique identifier of the group
schema:
$ref: "#/components/schemas/GroupNamePattern"
- name: memberName
in: path
required: true
description: The group member identifier. Either a user (user:{email}) or a
nested group (group:{groupName}). Parsed by UserGroupId in the
controller.
schema:
$ref: "#/components/schemas/UserGroupIdPattern"
requestBody:
content:
application/json:
schema:
type: object
properties:
status:
type: string
enum:
- admin
- member
description: The new status for the member
responses:
"200":
description: Member status updated successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GroupNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,70}$
description: Group name pattern. Allows any character except `/` (would split
the FGA resource path — see ResourceIdentifier.parseFromFga) and `*`
(FGA wildcard). Length cap of 70 covers both user-defined groups (max 63
chars, enforced by Validators.isValidString) and workspace-derived
groups (workspace name 1-63 + "-group" suffix).
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get an index
Source: https://www.credibledata.com/docs/admin-api-reference/indexes/get-an-index
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/indexes/{indexId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/indexes/{indexId}:
get:
tags:
- indexes
summary: Get an index
operationId: getIndex
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: path
required: true
description: The unique identifier of the version
schema:
$ref: "#/components/schemas/VersionIdPattern"
- name: indexId
in: path
required: true
description: The unique identifier of the index (binding)
schema:
type: string
responses:
"200":
description: Index retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Index"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Index:
type: object
description: >
A version's serving anchor for one indexed (`#(index)`-tagged)
dimension.
It binds the version to the content-addressed, package-scoped built
index
(shared across versions, and — when the source is materialized — derived
from the materialized table). That underlying artifact and its content
address are internal and never exposed here.
properties:
id:
type: string
sourceName:
type: string
description: Fully-qualified source name within the package that owns the
dimension.
dimension:
type: string
description: The indexed dimension path (e.g. "country" or "people.name").
modelFilePath:
type: string
description: >
The model file that declares this (source, dimension). Two files in
one
package version can declare the same source + dimension name with
different definitions (each its own index), so this disambiguates
otherwise-identical entries. Empty for legacy/unknown.
status:
type: string
enum:
- PENDING
- READY
- FAILED
error:
type: string
description: >
When `status` is FAILED, the reason the most recent build for this
dimension failed — a read-time projection of the failing built
index's
error, surfaced inline so the cause is visible without drilling into
individual runs. Null while PENDING/READY.
stale:
type: boolean
readOnly: true
description: >
True when this index is serving non-current data for any reason
(docs/persistence.md §9.7). Unifies the reused-over-failed-source
case
(`SOURCE_BUILD_FAILED`) with age-based staleness against a declared
index `freshness.window` (`FRESHNESS_WINDOW_EXCEEDED`, §9.5). The
machine-readable cause(s) are in `staleReasons`. Display-only: the
index still serves its prior values. False/absent otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: |
The fresh→stale crossover instant — the age-based component
(`lastIndexedAt + effective freshness.window`). Null when the
staleness is only failure-derived, or when the index is fresh.
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: |
The machine-readable staleness cause(s) (§9.7). Empty when fresh.
rowCount:
type: integer
format: int64
description: Number of indexed values currently serving for this dimension (null
until first READY build).
lastIndexedAt:
type: string
format: date-time
description: When the currently serving index generation was built (null until
the first READY build).
scope:
type: string
enum:
- version
- package
description: >
The scope mode this index was built under (replaces the removed
per-dimension `sharing`): `version` = version-owned; `package` =
reusable across the package's own versions when fresh. Null =
unknown.
The dimension-grain analog of `Materialization.scope`, and — like it
—
a per-anchor **convenience mirror** of the canonical `Version.scope`
(declared once at the package-manifest root, uniform across the
version), not an independent per-dimension knob.
NOTE (current phase): unlike `Materialization.scope`, this value is
display metadata only — it does NOT isolate the index artifact.
Index
artifacts remain content-addressed by `index_entity_id` and are
reused across versions regardless of `scope` (identical definition +
data identity ⇒ identical index, so reuse is result-correct). A
`version`-scoped index therefore records its owning version but may
still share one physical artifact with another version that binds
the
same address; per-version artifact isolation lands with the
index-cadence scheduler (persistence.md §9.5).
refresh:
type: string
description: |
The dimension's declared `#(index ... refresh=...)` value ("full" |
"incremental"), reported verbatim. Null = unset. Policy metadata for
display (inert to the build today).
freshnessWindowSeconds:
type: integer
format: int64
description: >
The dimension's declared `#(index ... freshness.window=...)` refresh
objective, in seconds (parsed from the "24h"/"7d" surface form).
Null =
unset — index freshness is opt-in per dimension (§9.5), so a bare
`#(index)` reports nothing and no proactive cadence applies.
freshnessFallback:
type: string
enum:
- live
- stale_ok
- fail
description: >
The dimension's declared `#(index ... freshness.fallback=...)` —
query-time behavior intent when the window is missed (indexes have
no
gate today; metadata). Null = unset.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List indexes for a version
Source: https://www.credibledata.com/docs/admin-api-reference/indexes/list-indexes-for-a-version
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/indexes
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/indexes:
get:
tags:
- indexes
summary: List indexes for a version
description: |
Lists the per-dimension search indexes bound to a package version, most
recent first. Each index is the version's serving anchor for one indexed
(`#(index)`-tagged) dimension. The underlying built index is
content-addressed and package-scoped (shared across versions that define
the same dimension), so it is not exposed here; this returns only the
version's bindings.
**Authorization**: Requires read access to the package.
operationId: listIndexes
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: path
required: true
description: The unique identifier of the version
schema:
$ref: "#/components/schemas/VersionIdPattern"
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–500."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: List of indexes retrieved successfully
headers:
Total-Count:
description: Total number of indexes available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Index"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Index:
type: object
description: >
A version's serving anchor for one indexed (`#(index)`-tagged)
dimension.
It binds the version to the content-addressed, package-scoped built
index
(shared across versions, and — when the source is materialized — derived
from the materialized table). That underlying artifact and its content
address are internal and never exposed here.
properties:
id:
type: string
sourceName:
type: string
description: Fully-qualified source name within the package that owns the
dimension.
dimension:
type: string
description: The indexed dimension path (e.g. "country" or "people.name").
modelFilePath:
type: string
description: >
The model file that declares this (source, dimension). Two files in
one
package version can declare the same source + dimension name with
different definitions (each its own index), so this disambiguates
otherwise-identical entries. Empty for legacy/unknown.
status:
type: string
enum:
- PENDING
- READY
- FAILED
error:
type: string
description: >
When `status` is FAILED, the reason the most recent build for this
dimension failed — a read-time projection of the failing built
index's
error, surfaced inline so the cause is visible without drilling into
individual runs. Null while PENDING/READY.
stale:
type: boolean
readOnly: true
description: >
True when this index is serving non-current data for any reason
(docs/persistence.md §9.7). Unifies the reused-over-failed-source
case
(`SOURCE_BUILD_FAILED`) with age-based staleness against a declared
index `freshness.window` (`FRESHNESS_WINDOW_EXCEEDED`, §9.5). The
machine-readable cause(s) are in `staleReasons`. Display-only: the
index still serves its prior values. False/absent otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: |
The fresh→stale crossover instant — the age-based component
(`lastIndexedAt + effective freshness.window`). Null when the
staleness is only failure-derived, or when the index is fresh.
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: |
The machine-readable staleness cause(s) (§9.7). Empty when fresh.
rowCount:
type: integer
format: int64
description: Number of indexed values currently serving for this dimension (null
until first READY build).
lastIndexedAt:
type: string
format: date-time
description: When the currently serving index generation was built (null until
the first READY build).
scope:
type: string
enum:
- version
- package
description: >
The scope mode this index was built under (replaces the removed
per-dimension `sharing`): `version` = version-owned; `package` =
reusable across the package's own versions when fresh. Null =
unknown.
The dimension-grain analog of `Materialization.scope`, and — like it
—
a per-anchor **convenience mirror** of the canonical `Version.scope`
(declared once at the package-manifest root, uniform across the
version), not an independent per-dimension knob.
NOTE (current phase): unlike `Materialization.scope`, this value is
display metadata only — it does NOT isolate the index artifact.
Index
artifacts remain content-addressed by `index_entity_id` and are
reused across versions regardless of `scope` (identical definition +
data identity ⇒ identical index, so reuse is result-correct). A
`version`-scoped index therefore records its owning version but may
still share one physical artifact with another version that binds
the
same address; per-version artifact isolation lands with the
index-cadence scheduler (persistence.md §9.5).
refresh:
type: string
description: |
The dimension's declared `#(index ... refresh=...)` value ("full" |
"incremental"), reported verbatim. Null = unset. Policy metadata for
display (inert to the build today).
freshnessWindowSeconds:
type: integer
format: int64
description: >
The dimension's declared `#(index ... freshness.window=...)` refresh
objective, in seconds (parsed from the "24h"/"7d" surface form).
Null =
unset — index freshness is opt-in per dimension (§9.5), so a bare
`#(index)` reports nothing and no proactive cadence applies.
freshnessFallback:
type: string
enum:
- live
- stale_ok
- fail
description: >
The dimension's declared `#(index ... freshness.fallback=...)` —
query-time behavior intent when the window is missed (indexes have
no
gate today; metadata). Null = unset.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create an organization-creation invite token
Source: https://www.credibledata.com/docs/admin-api-reference/invites/create-an-organization-creation-invite-token
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /invites
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/invites:
post:
tags:
- invites
summary: Create an organization-creation invite token
description: >
Creates a single organization-creation invite token. The token can be
redeemed exactly once via `POST /organizations` with the
`X-Invite-Token`
header set, to create a new organization on the fly. To mint a batch
(e.g. for an outreach campaign), call this endpoint once per token —
the operation is independent per call so per-invite settings
(`boundEmail`,
`expiresAt`) can vary freely.
**Authorization**: Requires the system-level `can_create_organization`
permission.
**Body fields:** only `boundEmail` and `expiresAt` are honored. Server
defaults
apply when omitted (open invite; 30-day expiry; server caps at 90 days).
Tokens are short, case-insensitive signup codes (e.g. `ABCDE-FGHJK`) —
they
are the natural id used for all subsequent reads and revocations.
operationId: createInvite
requestBody:
required: false
content:
application/json:
schema:
$ref: "#/components/schemas/Invite"
responses:
"200":
description: Invite created successfully. The response includes the raw `token`.
content:
application/json:
schema:
$ref: "#/components/schemas/Invite"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
components:
schemas:
Invite:
type: object
description: >
An organization-creation invite token. Tokens are short,
case-insensitive
signup codes (e.g. `ABCDE-FGHJK`) — they are the natural id for the
resource and are returned by all reads.
properties:
token:
type: string
readOnly: true
description: |
The invite token (e.g. `ABCDE-FGHJK`). Use in the redemption URL
`https://{signupHost}/?token={token}` and as the path id for
`GET /invites/{token}` / `DELETE /invites/{token}`.
boundEmail:
type: string
description: >
Optional. If set, restricts redemption to a caller with this email
(case-insensitive). Leave unset for open invites — typical for
outreach
campaigns. Honored on `POST /invites`; immutable thereafter.
expiresAt:
type: string
format: date-time
description: |
ISO 8601 timestamp at which the invite expires. On `POST /invites`,
defaults to now + 30 days; server caps at now + 90 days. Immutable
thereafter.
createdBy:
type: string
readOnly: true
description: Email of the system admin who created the invite.
createdAt:
type: string
format: date-time
readOnly: true
description: ISO 8601 timestamp indicating when the invite was created.
consumedAt:
type: string
format: date-time
readOnly: true
description: ISO 8601 timestamp indicating when the invite was redeemed (null if
unconsumed).
consumedBy:
type: string
readOnly: true
description: Email of the user who redeemed the invite (null if unconsumed).
consumedOrganizationName:
type: string
readOnly: true
description: Name of the organization created on redemption (null if unconsumed).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get a single invite by its token
Source: https://www.credibledata.com/docs/admin-api-reference/invites/get-a-single-invite-by-its-token
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /invites/{token}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/invites/{token}:
get:
tags:
- invites
summary: Get a single invite by its token
description: |
Returns invite metadata for the given token (e.g. `ABCDE-FGHJK`). Used
by the signup flow to check redeemability before walking the user
through MPA acceptance, and by admin tooling to inspect a specific
invite.
**Authorization**: Any authenticated user. Tokens are non-secret signup
codes — the caller is either an admin or someone who already has the
token from their invite email, so returning its state is not a new
information leak.
operationId: getInvite
parameters:
- name: token
in: path
required: true
description: The invite token (case-insensitive; hyphen optional).
schema:
type: string
responses:
"200":
description: Invite retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Invite"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
Invite:
type: object
description: >
An organization-creation invite token. Tokens are short,
case-insensitive
signup codes (e.g. `ABCDE-FGHJK`) — they are the natural id for the
resource and are returned by all reads.
properties:
token:
type: string
readOnly: true
description: |
The invite token (e.g. `ABCDE-FGHJK`). Use in the redemption URL
`https://{signupHost}/?token={token}` and as the path id for
`GET /invites/{token}` / `DELETE /invites/{token}`.
boundEmail:
type: string
description: >
Optional. If set, restricts redemption to a caller with this email
(case-insensitive). Leave unset for open invites — typical for
outreach
campaigns. Honored on `POST /invites`; immutable thereafter.
expiresAt:
type: string
format: date-time
description: |
ISO 8601 timestamp at which the invite expires. On `POST /invites`,
defaults to now + 30 days; server caps at now + 90 days. Immutable
thereafter.
createdBy:
type: string
readOnly: true
description: Email of the system admin who created the invite.
createdAt:
type: string
format: date-time
readOnly: true
description: ISO 8601 timestamp indicating when the invite was created.
consumedAt:
type: string
format: date-time
readOnly: true
description: ISO 8601 timestamp indicating when the invite was redeemed (null if
unconsumed).
consumedBy:
type: string
readOnly: true
description: Email of the user who redeemed the invite (null if unconsumed).
consumedOrganizationName:
type: string
readOnly: true
description: Name of the organization created on redemption (null if unconsumed).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List invite tokens
Source: https://www.credibledata.com/docs/admin-api-reference/invites/list-invite-tokens
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /invites
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/invites:
get:
tags:
- invites
summary: List invite tokens
description: >
Lists previously-created invites along with their consumed state. Each
row
exposes its raw `token` (e.g. `ABCDE-FGHJK`) — tokens are non-secret
signup codes, used as the natural id by `GET /invites/{token}` and
`DELETE /invites/{token}`.
**Authorization**: Requires the system-level `can_create_organization`
permission.
operationId: listInvites
parameters:
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–100."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: List of invites retrieved successfully
headers:
Total-Count:
description: Total number of invites available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Invite"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
components:
schemas:
Invite:
type: object
description: >
An organization-creation invite token. Tokens are short,
case-insensitive
signup codes (e.g. `ABCDE-FGHJK`) — they are the natural id for the
resource and are returned by all reads.
properties:
token:
type: string
readOnly: true
description: |
The invite token (e.g. `ABCDE-FGHJK`). Use in the redemption URL
`https://{signupHost}/?token={token}` and as the path id for
`GET /invites/{token}` / `DELETE /invites/{token}`.
boundEmail:
type: string
description: >
Optional. If set, restricts redemption to a caller with this email
(case-insensitive). Leave unset for open invites — typical for
outreach
campaigns. Honored on `POST /invites`; immutable thereafter.
expiresAt:
type: string
format: date-time
description: |
ISO 8601 timestamp at which the invite expires. On `POST /invites`,
defaults to now + 30 days; server caps at now + 90 days. Immutable
thereafter.
createdBy:
type: string
readOnly: true
description: Email of the system admin who created the invite.
createdAt:
type: string
format: date-time
readOnly: true
description: ISO 8601 timestamp indicating when the invite was created.
consumedAt:
type: string
format: date-time
readOnly: true
description: ISO 8601 timestamp indicating when the invite was redeemed (null if
unconsumed).
consumedBy:
type: string
readOnly: true
description: Email of the user who redeemed the invite (null if unconsumed).
consumedOrganizationName:
type: string
readOnly: true
description: Name of the organization created on redemption (null if unconsumed).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Revoke an unconsumed invite
Source: https://www.credibledata.com/docs/admin-api-reference/invites/revoke-an-unconsumed-invite
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /invites/{token}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/invites/{token}:
delete:
tags:
- invites
summary: Revoke an unconsumed invite
description: >
Permanently deletes an unconsumed invite, rendering its token
unredeemable.
Used to revoke leaked or no-longer-needed invites from an outreach
batch.
Consumed invites are preserved for audit and cannot be deleted (returns
409).
**Authorization**: Requires the system-level `can_create_organization`
permission.
operationId: deleteInvite
parameters:
- name: token
in: path
required: true
description: The invite token to revoke (case-insensitive; hyphen optional).
schema:
type: string
responses:
"204":
description: Invite revoked successfully.
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: >
Invite has already been consumed and cannot be revoked (audit trail
is preserved).
`code` is `INVITE_ALREADY_CONSUMED_REVOKE`.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
schemas:
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get a materialization
Source: https://www.credibledata.com/docs/admin-api-reference/materializations/get-a-materialization
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/materializations/{materializationId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/materializations/{materializationId}:
get:
tags:
- materializations
summary: Get a materialization
operationId: getMaterialization
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: path
required: true
description: The unique identifier of the version
schema:
$ref: "#/components/schemas/VersionIdPattern"
- name: materializationId
in: path
required: true
description: The unique identifier of the materialization
schema:
type: string
responses:
"200":
description: Materialization retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Materialization"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Materialization:
type: object
description: |
A per-source materialization (Malloy Persistence v0). It is the lineage
anchor for one persist source of the version — identified within the
version by its (`sourceName`, `modelFilePath`) — and points at the
physical table currently serving that source. The underlying artifact's
content address is internal and never exposed here.
properties:
id:
type: string
sourceName:
type: string
description: Fully-qualified persist source name within the package.
modelFilePath:
type: string
description: >
The model file that declares this source. Two files in one version
may
declare the same `sourceName` as distinct anchors, so a scoped
source
rerun must pass both `sourceName` and `modelFilePath` to target the
right
one (mirrors `Index.modelFilePath`). Empty string (never null) for
an
anchor with no recorded path — the column is `NOT NULL DEFAULT ''`.
status:
type: string
enum:
- PENDING
- READY
- FAILED
error:
type: string
description: >
When `status` is FAILED, the reason the most recent build failed —
the error of the materialization's latest run (where build failures
occur), surfaced here so the cause (e.g. a BigQuery "Permission
bigquery.tables.delete denied" warehouse error, or a build that
produced no table) is visible inline without drilling into
individual
runs. A read-time projection of the run's error; null while
PENDING/READY.
connectionName:
type: string
description: Name of the connection whose warehouse holds the currently serving
materialized table (null until first READY build).
servingRunId:
type: string
description: Id of the run whose materialized table this version currently
serves; the physical table name is exposed directly on this DTO as
`materializedTableName` (and per-source on that run's
`buildPlan.nodes[].tableName`). Auto-advances to the latest
successful run. A materialization always has a serving run once it
has a successful build; null only until the first table is built.
servingBuildNumber:
type: integer
description: |
The `buildNumber` (the "gNNN" the UI shows) of the run named by
`servingRunId`, resolved server-side so the client can render the
serving build label without a second, version-scoped run lookup.
Under table reuse the serving run can belong to a *prior* version,
so a client-side lookup against the current version's runs would
miss it; this field is version-agnostic. Null until the first table
is built, or for a legacy serving run created before build numbers
existed.
materializedTableName:
type: string
description: Physical name of the currently serving materialized table (null
until the first READY build).
servingStartedAt:
type: string
format: date-time
description: When the currently serving table was materialized, i.e. began
serving (null until the first READY build).
scope:
type: string
enum:
- version
- package
description: >
The materialization scope mode this source's table was built under
(replaces the removed per-source `sharing`): `version` =
version-owned,
no cross-version reuse; `package` = reusable across the package's
own
versions when fresh. Null = unknown (materialized before scope was
recorded).
This is a per-anchor **convenience mirror** of the canonical
`Version.scope`, not an independent per-source knob: scope is
declared
once at the package-manifest root and is uniform across every source
and
index of a version, so this always equals the owning version's
`scope`.
It is surfaced here so a single materialization is self-describing
without a second `getVersion`; read `Version.scope` when you want
the
authoritative version-grain value.
refresh:
type: string
description: |
The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim. Null = unset. Policy metadata for
display (inert to the build today).
freshnessWindowSeconds:
type: integer
format: int64
description: >
The source's EFFECTIVE freshness window (after most-specific-wins
resolution: source > model-file > package), in seconds — the control
plane's refresh objective for this source's materialized table. Null
=
unset at every level (the system default applies).
freshnessFallback:
type: string
enum:
- live
- stale_ok
- fail
description: |
The source's EFFECTIVE freshness fallback — the declared query-time
behavior when the window is missed. Null = unset.
stale:
type: boolean
readOnly: true
description: |
True when this source is serving non-current data for any reason
(docs/persistence.md §9.7). The unified staleness indicator; the
machine-readable cause(s) are in `staleReasons`. False/absent
otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: |
The fresh→stale crossover instant — the age-based component
(`dataAsOf + freshness.window`). Null when the staleness is only
failure-derived (no age crossover), or when the source is fresh.
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: |
The machine-readable staleness cause(s) (§9.7). Empty when fresh.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List materializations for a version
Source: https://www.credibledata.com/docs/admin-api-reference/materializations/list-materializations-for-a-version
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/materializations
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}/materializations:
get:
tags:
- materializations
summary: List materializations for a version
description: |
Lists the per-source materializations bound to a package version
(Malloy Persistence v0), most recent first. Each materialization is the
lineage anchor for one persist source of the version — identified within
the version by its (`sourceName`, `modelFilePath`) — and points at the
physical table currently serving that source.
In v0 materializations are addressed under the version that binds them.
Package-level (cross-version) materialization resources will be added
once versions can share materialized tables.
**Authorization**: Requires read access to the package.
operationId: listMaterializations
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: path
required: true
description: The unique identifier of the version
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: List of materializations retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Materialization"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Materialization:
type: object
description: |
A per-source materialization (Malloy Persistence v0). It is the lineage
anchor for one persist source of the version — identified within the
version by its (`sourceName`, `modelFilePath`) — and points at the
physical table currently serving that source. The underlying artifact's
content address is internal and never exposed here.
properties:
id:
type: string
sourceName:
type: string
description: Fully-qualified persist source name within the package.
modelFilePath:
type: string
description: >
The model file that declares this source. Two files in one version
may
declare the same `sourceName` as distinct anchors, so a scoped
source
rerun must pass both `sourceName` and `modelFilePath` to target the
right
one (mirrors `Index.modelFilePath`). Empty string (never null) for
an
anchor with no recorded path — the column is `NOT NULL DEFAULT ''`.
status:
type: string
enum:
- PENDING
- READY
- FAILED
error:
type: string
description: >
When `status` is FAILED, the reason the most recent build failed —
the error of the materialization's latest run (where build failures
occur), surfaced here so the cause (e.g. a BigQuery "Permission
bigquery.tables.delete denied" warehouse error, or a build that
produced no table) is visible inline without drilling into
individual
runs. A read-time projection of the run's error; null while
PENDING/READY.
connectionName:
type: string
description: Name of the connection whose warehouse holds the currently serving
materialized table (null until first READY build).
servingRunId:
type: string
description: Id of the run whose materialized table this version currently
serves; the physical table name is exposed directly on this DTO as
`materializedTableName` (and per-source on that run's
`buildPlan.nodes[].tableName`). Auto-advances to the latest
successful run. A materialization always has a serving run once it
has a successful build; null only until the first table is built.
servingBuildNumber:
type: integer
description: |
The `buildNumber` (the "gNNN" the UI shows) of the run named by
`servingRunId`, resolved server-side so the client can render the
serving build label without a second, version-scoped run lookup.
Under table reuse the serving run can belong to a *prior* version,
so a client-side lookup against the current version's runs would
miss it; this field is version-agnostic. Null until the first table
is built, or for a legacy serving run created before build numbers
existed.
materializedTableName:
type: string
description: Physical name of the currently serving materialized table (null
until the first READY build).
servingStartedAt:
type: string
format: date-time
description: When the currently serving table was materialized, i.e. began
serving (null until the first READY build).
scope:
type: string
enum:
- version
- package
description: >
The materialization scope mode this source's table was built under
(replaces the removed per-source `sharing`): `version` =
version-owned,
no cross-version reuse; `package` = reusable across the package's
own
versions when fresh. Null = unknown (materialized before scope was
recorded).
This is a per-anchor **convenience mirror** of the canonical
`Version.scope`, not an independent per-source knob: scope is
declared
once at the package-manifest root and is uniform across every source
and
index of a version, so this always equals the owning version's
`scope`.
It is surfaced here so a single materialization is self-describing
without a second `getVersion`; read `Version.scope` when you want
the
authoritative version-grain value.
refresh:
type: string
description: |
The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim. Null = unset. Policy metadata for
display (inert to the build today).
freshnessWindowSeconds:
type: integer
format: int64
description: >
The source's EFFECTIVE freshness window (after most-specific-wins
resolution: source > model-file > package), in seconds — the control
plane's refresh objective for this source's materialized table. Null
=
unset at every level (the system default applies).
freshnessFallback:
type: string
enum:
- live
- stale_ok
- fail
description: |
The source's EFFECTIVE freshness fallback — the declared query-time
behavior when the window is missed. Null = unset.
stale:
type: boolean
readOnly: true
description: |
True when this source is serving non-current data for any reason
(docs/persistence.md §9.7). The unified staleness indicator; the
machine-readable cause(s) are in `staleReasons`. False/absent
otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: |
The fresh→stale crossover instant — the age-based component
(`dataAsOf + freshness.window`). Null when the staleness is only
failure-derived (no age crossover), or when the source is fresh.
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: |
The machine-readable staleness cause(s) (§9.7). Empty when fresh.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create organization permission
Source: https://www.credibledata.com/docs/admin-api-reference/organizationpermissions/create-organization-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/permissions:
post:
tags:
- organizationPermissions
summary: Create organization permission
description: >
Creates a new permission assignment for a user or group within the
organization,
granting them specific roles and access levels. Can also be used to
request access
to the organization when the user doesn't have admin permissions.
**Authorization**: Requires organization admin permissions, unless
`requestPermission` is true.
**Parameters**: Use `requestPermission` to indicate the user is
requesting access to the resource.
**Roles**: Supports admin, modeler, and member roles.
operationId: createOrganizationPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: requestPermission
in: query
required: false
description: Indicates that the user is requesting access to the resource
schema:
type: boolean
default: false
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/OrganizationPermission"
responses:
"200":
description: Organization permission created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/OrganizationPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
OrganizationPermission:
type: object
description: Represents a permission assignment for a user or group within an
organization
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- member
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete organization permission
Source: https://www.credibledata.com/docs/admin-api-reference/organizationpermissions/delete-organization-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/permissions/{userGroupId}:
delete:
tags:
- organizationPermissions
summary: Delete organization permission
description: >
Removes the permission assignment for a user or group within the
organization,
revoking their access to organizational resources.
**Authorization**: Requires organization admin permissions.
**Side Effects**: User/group loses access to organization resources.
operationId: deleteOrganizationPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Organization permission deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get organization permission
Source: https://www.credibledata.com/docs/admin-api-reference/organizationpermissions/get-organization-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/permissions/{userGroupId}:
get:
tags:
- organizationPermissions
summary: Get organization permission
description: >
Retrieves the permission details for a specific user or group within the
organization,
including their role and access level.
**Authorization**: Requires organization admin or modeler permissions.
**Response**: Returns permission object with role and metadata.
operationId: getOrganizationPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Organization permission retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/OrganizationPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
OrganizationPermission:
type: object
description: Represents a permission assignment for a user or group within an
organization
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- member
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List organization permissions
Source: https://www.credibledata.com/docs/admin-api-reference/organizationpermissions/list-organization-permissions
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/permissions:
get:
tags:
- organizationPermissions
summary: List organization permissions
description: >
Retrieves all permission assignments for the specified organization,
including user and group
permissions with their roles and access levels.
**Authorization**: Requires organization admin or modeler permissions.
**Response**: Returns array of permission objects with user/group
identifiers and roles.
operationId: listOrganizationPermissions
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: List of organization permissions retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/OrganizationPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
OrganizationPermission:
type: object
description: Represents a permission assignment for a user or group within an
organization
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- member
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update organization permission
Source: https://www.credibledata.com/docs/admin-api-reference/organizationpermissions/update-organization-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/permissions/{userGroupId}:
patch:
tags:
- organizationPermissions
summary: Update organization permission
description: >
Updates the permission assignment for a user or group within the
organization,
modifying their role and access level.
**Authorization**: Requires organization admin permissions.
**Validation**: Role changes are validated against organizational
policies.
operationId: updateOrganizationPermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/OrganizationPermission"
responses:
"200":
description: Organization permission updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/OrganizationPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
OrganizationPermission:
type: object
description: Represents a permission assignment for a user or group within an
organization
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- admin
- modeler
- member
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a new organization
Source: https://www.credibledata.com/docs/admin-api-reference/organizations/create-a-new-organization
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations:
post:
tags:
- organizations
summary: Create a new organization
description: |
Creates a new organization with the specified configuration. Organizations serve as the top-level
container for all resources including environments, packages, workspaces, and user groups.
**Authorization (two paths):**
- *Direct create.* Default. Requires the system-level `can_create_organization` permission.
- *Invite redemption.* Supply the raw invite token in the `X-Invite-Token` header. The
invite is the authorization — any authenticated user may redeem. The caller is granted
admin on the new organization, the caller's user row is ensured, MPA acceptance is
recorded (using the server's current MPA version), and the invite is marked consumed.
If the invite was minted with a `boundEmail`, the caller's email must match
(case-insensitive). If the token has already been redeemed, a 409 is returned naming
the prior organization.
**Error codes.** On 4xx the response body carries an `Error { code, message }`. Clients
should branch on `code`:
| Status | `code` | Meaning |
|--------|---------------------------|-----------------------------------------------------------|
| 400 | `VALIDATION_ERROR` | Body field validation failed (e.g. bad `displayName`). |
| 400 | `INVITE_INVALID` | `X-Invite-Token` is malformed or unknown. |
| 400 | `INVITE_EXPIRED` | `X-Invite-Token` is past its `expiresAt`. |
| 403 | `INSUFFICIENT_PERMISSIONS`| Direct create attempted without the required permission. |
| 403 | `INVITE_EMAIL_MISMATCH` | Invite is bound to a different email than the caller. |
| 409 | `ORGANIZATION_NAME_TAKEN` | Requested `name` (URL slug) is taken — retry with another.|
| 409 | `ORGANIZATION_NAME_RESERVED` | Requested `name` collides with a reserved subdomain. |
| 409 | `INVITE_ALREADY_CONSUMED` | Token was already redeemed; retry will not help. |
**Validation**: Organization names must be unique and follow naming conventions.
**Side Effects**: Creates default permissions and initializes organizational structure.
operationId: createOrganization
parameters:
- in: header
name: X-Invite-Token
required: false
schema:
type: string
description: |
Raw invite token (e.g. `ABCDE-FGHJK`). When supplied, the
system-level `can_create_organization` permission check is
bypassed — the invite is the authorization. Required for
self-serve signup; omit for direct-create by privileged users.
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Organization"
responses:
"200":
description: Organization created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Organization"
"400":
description: >
Request was rejected. `code` distinguishes the cause:
`VALIDATION_ERROR`,
`INVITE_INVALID`, or `INVITE_EXPIRED`.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
description: |
Caller is not authorized. `code` distinguishes the cause:
`INSUFFICIENT_PERMISSIONS` (direct path) or `INVITE_EMAIL_MISMATCH`
(invite path; caller's email doesn't match the bound email).
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: |
Conflict. `code` distinguishes the cause: `ORGANIZATION_NAME_TAKEN`
(retry with a different `name`), `ORGANIZATION_NAME_RESERVED`
(the requested name collides with a reserved subdomain), or
`INVITE_ALREADY_CONSUMED` (the invite is dead; retry will not help —
message includes the prior organization name).
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
schemas:
Organization:
type: object
description: Represents an organization entity that serves as the top-level
container for all resources
properties:
name:
type: string
description: |
The unique identifier for the organization. Used as the resource
name in API paths AND as the DNS subdomain label routing traffic
to the org, so it follows RFC 1035 hostname rules — lowercase
letters, digits, and hyphens; no underscores; no leading or
trailing hyphen; max 63 chars.
$ref: "#/components/schemas/DnsLabelPattern"
displayName:
description: Human-readable name for the organization, displayed in user
interfaces
$ref: "#/components/schemas/HumanTextPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was last modified
mpaVersion:
type: string
readOnly: true
description: |
Version identifier of the Master Platform Agreement the organization
accepted at creation time (file basename, e.g. `v1-2026-05-19`).
Server-set: clients do not (and cannot) submit this field — when an
organization is created via the invite-redemption path, the server
stamps its current active MPA version. Null on legacy organizations
created before MPA acceptance was required.
Only the version is exposed on this resource. The per-user / per-
timestamp audit fields (`mpa_accepted_by`, `mpa_accepted_at`)
are kept internal — useful for compliance audit on the server
side, not for API consumers. If a future use case needs them on
the API, add them then; widening is easier than narrowing.
$ref: "#/components/schemas/MpaVersionPattern"
DnsLabelPattern:
type: string
minLength: 1
maxLength: 63
pattern: ^[a-z0-9](?:[a-z0-9-]{0,61}[a-z0-9])?$
description: DNS label — 1–63 chars, lowercase letters / digits / hyphens, no
leading or trailing hyphen. Used as a subdomain for organizations.
HumanTextPattern:
type: string
minLength: 1
maxLength: 128
pattern: ^[^\u0000-\u001F\u007F]+$
description: Short human-readable text — non-empty, no ASCII control characters,
capped at 128 chars. Used for display names, person names, and similar
free-text fields where we want to keep things short and printable.
MpaVersionPattern:
type: string
minLength: 1
maxLength: 32
pattern: ^[a-zA-Z0-9._-]+$
description: MPA version identifier — alphanumeric, dot, hyphen, underscore;
mirrors the version-string convention used in the on-disk markdown file
names (e.g. v1-2026-05-19).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete an organization
Source: https://www.credibledata.com/docs/admin-api-reference/organizations/delete-an-organization
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}:
delete:
tags:
- organizations
summary: Delete an organization
description: >
Permanently deletes an organization and all associated resources
including environments,
packages, workspaces, and user groups. This operation is irreversible.
**Authorization**: Requires organization admin permissions.
**Warning**: This operation will cascade delete all child resources.
**Side Effects**: Removes all data associated with the organization.
operationId: deleteOrganization
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization to delete
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Organization deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get organization details
Source: https://www.credibledata.com/docs/admin-api-reference/organizations/get-organization-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}:
get:
tags:
- organizations
summary: Get organization details
description: >
Retrieves detailed information about a specific organization including
metadata,
configuration, and administrative details. The response includes the
current user's
permission level (admin, modeler, or member) within the organization.
**Authorization**: Requires read access to the specified organization.
operationId: getOrganization
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization to retrieve
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Organization details retrieved successfully with user permission
level
content:
application/json:
schema:
$ref: "#/components/schemas/GetOrganizationResponse"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
GetOrganizationResponse:
allOf:
- $ref: "#/components/schemas/Organization"
- type: object
properties:
userPermission:
type: string
description: The current authenticated user's permission level within this
organization
enum:
- admin
- modeler
- member
Organization:
type: object
description: Represents an organization entity that serves as the top-level
container for all resources
properties:
name:
type: string
description: |
The unique identifier for the organization. Used as the resource
name in API paths AND as the DNS subdomain label routing traffic
to the org, so it follows RFC 1035 hostname rules — lowercase
letters, digits, and hyphens; no underscores; no leading or
trailing hyphen; max 63 chars.
$ref: "#/components/schemas/DnsLabelPattern"
displayName:
description: Human-readable name for the organization, displayed in user
interfaces
$ref: "#/components/schemas/HumanTextPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was last modified
mpaVersion:
type: string
readOnly: true
description: |
Version identifier of the Master Platform Agreement the organization
accepted at creation time (file basename, e.g. `v1-2026-05-19`).
Server-set: clients do not (and cannot) submit this field — when an
organization is created via the invite-redemption path, the server
stamps its current active MPA version. Null on legacy organizations
created before MPA acceptance was required.
Only the version is exposed on this resource. The per-user / per-
timestamp audit fields (`mpa_accepted_by`, `mpa_accepted_at`)
are kept internal — useful for compliance audit on the server
side, not for API consumers. If a future use case needs them on
the API, add them then; widening is easier than narrowing.
$ref: "#/components/schemas/MpaVersionPattern"
DnsLabelPattern:
type: string
minLength: 1
maxLength: 63
pattern: ^[a-z0-9](?:[a-z0-9-]{0,61}[a-z0-9])?$
description: DNS label — 1–63 chars, lowercase letters / digits / hyphens, no
leading or trailing hyphen. Used as a subdomain for organizations.
HumanTextPattern:
type: string
minLength: 1
maxLength: 128
pattern: ^[^\u0000-\u001F\u007F]+$
description: Short human-readable text — non-empty, no ASCII control characters,
capped at 128 chars. Used for display names, person names, and similar
free-text fields where we want to keep things short and printable.
MpaVersionPattern:
type: string
minLength: 1
maxLength: 32
pattern: ^[a-zA-Z0-9._-]+$
description: MPA version identifier — alphanumeric, dot, hyphen, underscore;
mirrors the version-string convention used in the on-disk markdown file
names (e.g. v1-2026-05-19).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get user within organization context
Source: https://www.credibledata.com/docs/admin-api-reference/organizations/get-user-within-organization-context
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/users/{userName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/users/{userName}:
get:
tags:
- organizations
summary: Get user within organization context
description: >
Retrieves basic user information for a user within an organization
context.
This endpoint verifies that both the caller and the target user are
members
of the specified organization before returning user data.
**Security**: Returns 404 (not 403) if the target user doesn't exist or
is not
a member of the organization. This prevents information leakage about
user existence.
**Authorization**: Requires read access to the organization (caller must
be a member).
**Response**: Returns only basic user fields (userName, email) for
privacy.
operationId: getOrganizationUser
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userName
in: path
required: true
description: The username (email) of the user to retrieve
schema:
type: string
format: email
responses:
"200":
description: User information retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/User"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
User:
type: object
description: Represents a user account with profile information and tutorial status
properties:
userName:
type: string
format: email
description: The user's username — an email address used for authentication.
Matches the path-parameter form on /users/{userName}. (Previously
$ref'd IdentifierPattern, which disallowed '@' and '.'; that was
never enforced at runtime so production data is all emails.)
password:
type: string
description: User's password (only included in create/update requests, never in
responses)
writeOnly: true
email:
type: string
description: User's email address, used for authentication and notifications
format: email
firstName:
type: string
maxLength: 64
description: |
User's first name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
lastName:
type: string
maxLength: 64
description: |
User's last name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
businessRole:
type: string
description: User's business role or job title
tutorialStatus:
$ref: "#/components/schemas/TutorialStatus"
TutorialStatus:
type: object
description: Represents the tutorial completion status and user preferences for
onboarding
properties:
environmentTutorial:
$ref: "#/components/schemas/EnvironmentTutorial"
EnvironmentTutorial:
type: object
description: Represents environment tutorial completion status and user preferences
properties:
hasClickedCreateModel:
type: boolean
description: Whether the user has clicked the create model button during tutorial
default: false
doNotShowModelIntro:
type: boolean
description: Whether to skip showing the model introduction tutorial
default: false
doNotShowSchemaExplorerTip:
type: boolean
description: Whether to skip showing the schema explorer tip
default: false
doNotShowTutorialInHomePanel:
type: boolean
description: Whether to skip showing tutorial content in the home panel
default: false
doNotShowConnectionOnboarding:
type: boolean
description: Whether to skip the connection-page getting-started onboarding modal
default: false
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List all organizations
Source: https://www.credibledata.com/docs/admin-api-reference/organizations/list-all-organizations
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations:
get:
tags:
- organizations
summary: List all organizations
description: >
Retrieves a comprehensive list of all organizations accessible to the
authenticated user.
This endpoint returns organization metadata including names, display
names, and timestamps.
**Authorization**: Requires appropriate permissions to view
organizations.
**Rate Limiting**: Standard rate limits apply.
**Pagination**: Supports offset-based pagination with limit and offset
parameters.
operationId: listOrganizations
parameters:
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–100."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: List of organizations retrieved successfully
headers:
Total-Count:
description: Total number of organizations available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
example: ;
rel="first",
;
rel="next"
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Organization"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
components:
schemas:
Organization:
type: object
description: Represents an organization entity that serves as the top-level
container for all resources
properties:
name:
type: string
description: |
The unique identifier for the organization. Used as the resource
name in API paths AND as the DNS subdomain label routing traffic
to the org, so it follows RFC 1035 hostname rules — lowercase
letters, digits, and hyphens; no underscores; no leading or
trailing hyphen; max 63 chars.
$ref: "#/components/schemas/DnsLabelPattern"
displayName:
description: Human-readable name for the organization, displayed in user
interfaces
$ref: "#/components/schemas/HumanTextPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was last modified
mpaVersion:
type: string
readOnly: true
description: |
Version identifier of the Master Platform Agreement the organization
accepted at creation time (file basename, e.g. `v1-2026-05-19`).
Server-set: clients do not (and cannot) submit this field — when an
organization is created via the invite-redemption path, the server
stamps its current active MPA version. Null on legacy organizations
created before MPA acceptance was required.
Only the version is exposed on this resource. The per-user / per-
timestamp audit fields (`mpa_accepted_by`, `mpa_accepted_at`)
are kept internal — useful for compliance audit on the server
side, not for API consumers. If a future use case needs them on
the API, add them then; widening is easier than narrowing.
$ref: "#/components/schemas/MpaVersionPattern"
DnsLabelPattern:
type: string
minLength: 1
maxLength: 63
pattern: ^[a-z0-9](?:[a-z0-9-]{0,61}[a-z0-9])?$
description: DNS label — 1–63 chars, lowercase letters / digits / hyphens, no
leading or trailing hyphen. Used as a subdomain for organizations.
HumanTextPattern:
type: string
minLength: 1
maxLength: 128
pattern: ^[^\u0000-\u001F\u007F]+$
description: Short human-readable text — non-empty, no ASCII control characters,
capped at 128 chars. Used for display names, person names, and similar
free-text fields where we want to keep things short and printable.
MpaVersionPattern:
type: string
minLength: 1
maxLength: 32
pattern: ^[a-zA-Z0-9._-]+$
description: MPA version identifier — alphanumeric, dot, hyphen, underscore;
mirrors the version-string convention used in the on-disk markdown file
names (e.g. v1-2026-05-19).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List users in organization
Source: https://www.credibledata.com/docs/admin-api-reference/organizations/list-users-in-organization
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/users
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/users:
get:
tags:
- organizations
summary: List users in organization
description: >
Retrieves all users that are members of the specified organization,
returning
basic user information (userName, email) for each.
**Authorization**: Requires read access to the organization (caller must
be a member).
**Response**: Returns array of user objects with basic fields only.
operationId: listOrganizationUsers
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: List of organization users retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/User"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
User:
type: object
description: Represents a user account with profile information and tutorial status
properties:
userName:
type: string
format: email
description: The user's username — an email address used for authentication.
Matches the path-parameter form on /users/{userName}. (Previously
$ref'd IdentifierPattern, which disallowed '@' and '.'; that was
never enforced at runtime so production data is all emails.)
password:
type: string
description: User's password (only included in create/update requests, never in
responses)
writeOnly: true
email:
type: string
description: User's email address, used for authentication and notifications
format: email
firstName:
type: string
maxLength: 64
description: |
User's first name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
lastName:
type: string
maxLength: 64
description: |
User's last name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
businessRole:
type: string
description: User's business role or job title
tutorialStatus:
$ref: "#/components/schemas/TutorialStatus"
TutorialStatus:
type: object
description: Represents the tutorial completion status and user preferences for
onboarding
properties:
environmentTutorial:
$ref: "#/components/schemas/EnvironmentTutorial"
EnvironmentTutorial:
type: object
description: Represents environment tutorial completion status and user preferences
properties:
hasClickedCreateModel:
type: boolean
description: Whether the user has clicked the create model button during tutorial
default: false
doNotShowModelIntro:
type: boolean
description: Whether to skip showing the model introduction tutorial
default: false
doNotShowSchemaExplorerTip:
type: boolean
description: Whether to skip showing the schema explorer tip
default: false
doNotShowTutorialInHomePanel:
type: boolean
description: Whether to skip showing tutorial content in the home panel
default: false
doNotShowConnectionOnboarding:
type: boolean
description: Whether to skip the connection-page getting-started onboarding modal
default: false
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update organization details
Source: https://www.credibledata.com/docs/admin-api-reference/organizations/update-organization-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}:
patch:
tags:
- organizations
summary: Update organization details
description: >
Partially updates an organization's details. Only the provided fields
will be updated.
This operation allows for selective updates without requiring all
organization fields.
**Authorization**: Requires organization admin permissions.
**Validation**: All provided fields are validated according to their
schema constraints.
**Side Effects**: Updates the organization's `updatedAt` timestamp.
operationId: updateOrganization
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization to update
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
description: Partial organization data to update
content:
application/json:
schema:
$ref: "#/components/schemas/Organization"
responses:
"200":
description: Organization updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Organization"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Organization:
type: object
description: Represents an organization entity that serves as the top-level
container for all resources
properties:
name:
type: string
description: |
The unique identifier for the organization. Used as the resource
name in API paths AND as the DNS subdomain label routing traffic
to the org, so it follows RFC 1035 hostname rules — lowercase
letters, digits, and hyphens; no underscores; no leading or
trailing hyphen; max 63 chars.
$ref: "#/components/schemas/DnsLabelPattern"
displayName:
description: Human-readable name for the organization, displayed in user
interfaces
$ref: "#/components/schemas/HumanTextPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the organization was last modified
mpaVersion:
type: string
readOnly: true
description: |
Version identifier of the Master Platform Agreement the organization
accepted at creation time (file basename, e.g. `v1-2026-05-19`).
Server-set: clients do not (and cannot) submit this field — when an
organization is created via the invite-redemption path, the server
stamps its current active MPA version. Null on legacy organizations
created before MPA acceptance was required.
Only the version is exposed on this resource. The per-user / per-
timestamp audit fields (`mpa_accepted_by`, `mpa_accepted_at`)
are kept internal — useful for compliance audit on the server
side, not for API consumers. If a future use case needs them on
the API, add them then; widening is easier than narrowing.
$ref: "#/components/schemas/MpaVersionPattern"
DnsLabelPattern:
type: string
minLength: 1
maxLength: 63
pattern: ^[a-z0-9](?:[a-z0-9-]{0,61}[a-z0-9])?$
description: DNS label — 1–63 chars, lowercase letters / digits / hyphens, no
leading or trailing hyphen. Used as a subdomain for organizations.
HumanTextPattern:
type: string
minLength: 1
maxLength: 128
pattern: ^[^\u0000-\u001F\u007F]+$
description: Short human-readable text — non-empty, no ASCII control characters,
capped at 128 chars. Used for display names, person names, and similar
free-text fields where we want to keep things short and printable.
MpaVersionPattern:
type: string
minLength: 1
maxLength: 32
pattern: ^[a-zA-Z0-9._-]+$
description: MPA version identifier — alphanumeric, dot, hyphen, underscore;
mirrors the version-string convention used in the on-disk markdown file
names (e.g. v1-2026-05-19).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create package permission
Source: https://www.credibledata.com/docs/admin-api-reference/packagepermissions/create-package-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions:
post:
tags:
- packagePermissions
summary: Create package permission
description: >
Creates a new permission assignment for a user, group, or workspace
within the package,
granting them specific roles and access levels. Can also be used to
request access
to the package when the user doesn't have admin or modeler permissions.
**Authorization**: Requires package admin or modeler permissions, unless
`requestPermission` is true.
**Parameters**: Use `requestPermission` to indicate the user is
requesting access to the resource.
**Notification**: Use `notifyPeople` to send email notifications to
affected users.
operationId: createPackagePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: requestPermission
in: query
required: false
description: Indicates that the user is requesting access to the resource
schema:
type: boolean
default: false
- name: notifyPeople
in: query
required: false
description: Whether to notify people when permissions are granted
schema:
type: boolean
default: false
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/PackagePermission"
responses:
"200":
description: Package permission created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/PackagePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
PackagePermission:
type: object
description: Represents a permission assignment for a user, group, or workspace
within a package
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
workspace:
description: Set if this PackagePermission grants Package access to a workspace
(not a user)
type: string
$ref: "#/components/schemas/IdentifierPattern"
permission:
type: string
description: The role/permission level granted to the user, group, or workspace
enum:
- admin
- modeler
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent environment or
organization
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete package permission
Source: https://www.credibledata.com/docs/admin-api-reference/packagepermissions/delete-package-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions/{userGroupId}:
delete:
tags:
- packagePermissions
summary: Delete package permission
description: >
Removes the permission assignment for a user, group, or workspace within
the package,
revoking their access to package resources.
**Authorization**: Requires package admin or modeler permissions.
**Side Effects**: User/group/workspace loses access to package
resources.
operationId: deletePackagePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
description: The resource identifier of the User or Group Permissions for this
package.
in: path
required: true
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Package permission deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get package permission
Source: https://www.credibledata.com/docs/admin-api-reference/packagepermissions/get-package-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions/{userGroupId}:
get:
tags:
- packagePermissions
summary: Get package permission
description: >
Retrieves the permission details for a specific user, group within the
package,
including their role and access level.
**Authorization**: Requires package admin or modeler permissions.
**Response**: Returns permission object with role and metadata.
operationId: getPackagePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
description: The resource identifier of the User or Group Permissions for this
package.
in: path
required: true
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Package permission retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/PackagePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
PackagePermission:
type: object
description: Represents a permission assignment for a user, group, or workspace
within a package
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
workspace:
description: Set if this PackagePermission grants Package access to a workspace
(not a user)
type: string
$ref: "#/components/schemas/IdentifierPattern"
permission:
type: string
description: The role/permission level granted to the user, group, or workspace
enum:
- admin
- modeler
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent environment or
organization
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List package permissions
Source: https://www.credibledata.com/docs/admin-api-reference/packagepermissions/list-package-permissions
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions:
get:
tags:
- packagePermissions
summary: List package permissions
description: >
Retrieves all permission assignments for the specified package,
including user and group
permissions with their roles and access levels.
**Authorization**: Requires package admin or modeler permissions.
**Response**: Returns array of permission objects with user/group
identifiers and roles.
operationId: listPackagePermissions
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: List of package permissions retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/PackagePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
PackagePermission:
type: object
description: Represents a permission assignment for a user, group, or workspace
within a package
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
workspace:
description: Set if this PackagePermission grants Package access to a workspace
(not a user)
type: string
$ref: "#/components/schemas/IdentifierPattern"
permission:
type: string
description: The role/permission level granted to the user, group, or workspace
enum:
- admin
- modeler
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent environment or
organization
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update package permission
Source: https://www.credibledata.com/docs/admin-api-reference/packagepermissions/update-package-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/permissions/{userGroupId}:
patch:
tags:
- packagePermissions
summary: Update package permission
description: >
Updates the permission assignment for a user, group, or workspace within
the package,
modifying their role and access level.
**Authorization**: Requires package admin or modeler permissions.
**Validation**: Role changes are validated against package constraints.
operationId: updatePackagePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: userGroupId
description: The resource identifier of the User or Group Permissions for this
package.
in: path
required: true
schema:
$ref: "#/components/schemas/UserGroupId"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/PackagePermission"
responses:
"200":
description: Package permission updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/PackagePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
PackagePermission:
type: object
description: Represents a permission assignment for a user, group, or workspace
within a package
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
workspace:
description: Set if this PackagePermission grants Package access to a workspace
(not a user)
type: string
$ref: "#/components/schemas/IdentifierPattern"
permission:
type: string
description: The role/permission level granted to the user, group, or workspace
enum:
- admin
- modeler
- viewer
inheritedPermission:
type: string
description: The permission level inherited from parent environment or
organization
enum:
- admin
- modeler
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create or update package
Source: https://www.credibledata.com/docs/admin-api-reference/packages/create-or-update-package
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}:
post:
tags:
- packages
summary: Create or update package
description: >
Creates a new package or updates an existing one with a new version.
This endpoint
handles both package metadata and file uploads for package content.
**Authorization**: Requires package admin or modeler permissions.
**Content**: Accepts multipart form data with package metadata and
binary file content.
**Validation**: Validates package structure and file integrity using MD5
hash.
operationId: createOrUpdatePackage
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
content:
multipart/form-data:
schema:
type: object
properties:
package:
$ref: "#/components/schemas/Package"
version:
$ref: "#/components/schemas/Version"
packageFile:
type: string
format: binary
md5Hash:
type: string
responses:
"200":
description: Package created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy data model package containing models, queries,
and related resources
properties:
name:
type: string
description: The unique name of the package within its environment
$ref: "#/components/schemas/IdentifierPattern"
latestVersion:
type: string
description: The version identifier of the most recent published version
$ref: "#/components/schemas/SemanticVersionPattern"
description:
type: string
description: Human-readable description of the package's purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was first created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
resourceIdentifier:
description: Unique resource identifier for the package, used for API references
and permissions
type: string
nullable: false
$ref: "#/components/schemas/ResourceIdentifierPattern"
indexStatus:
$ref: "#/components/schemas/IndexStatus"
autoPromote:
type: boolean
nullable: true
description: >
Package-scoped auto-promote policy applied as a default to each
newly
published version: when true, a new version is armed (see
Version.promoteWhenReady) and the lifecycle reconciler promotes it
to
`latestVersion` once it is ready, subject to the never-been-latest
rollback guard. Newly created packages default this to `true`: a
package
created without an explicit `autoPromote` gets auto-promote enabled.
Omitting the field on update leaves the policy unchanged; toggling
it on
does not retroactively arm existing versions. Independent of
`autoArchiveTtl`.
autoArchiveTtl:
type: string
nullable: true
description: >
Package-scoped ttl auto-archive policy: how long a version is
retained
after it stops being latest, e.g. `30d`, `24h`, `2w` (units s, m, h,
d,
w). A formerly-latest version is archived (its materialized tables
reclaimed) once it has been demoted for longer than this ttl; the
current
latest is never archived. `0` archives a version as soon as it is
demoted
(keep-only-latest, modulo the reconciler tick) — note this trades
away the
cheap rollback window. A non-empty value enables auto-archive; an
empty
string disables it. Newly created packages default to `30d`: a
package
created without an explicit `autoArchiveTtl` gets 30-day
auto-archive.
Omitting the field on update leaves the policy unchanged.
Independent of
`autoPromote`.
SemanticVersionPattern:
type: string
pattern: ^[0-9]+\.[0-9]+\.[0-9]+(-[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?(\+[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?$
description: SemVer 2.0 version identifier. Required core MAJOR.MINOR.PATCH plus
optional pre-release suffix (e.g. `-rc1`, `-alpha.2`) and optional build
metadata (e.g. `+20231120.deadbeef`). Previously enforced strict
MAJOR.MINOR.PATCH only, which would have started 400-ing legitimate
pre-release versions (e.g. videoamp's -rc1/-rc2 RC builds) once
hibernate-validator started firing.
ResourceIdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_/.:-]+$
description: Resource identifier pattern supporting slashes, dots, dashes, and colons
IndexStatus:
type: string
description: "Status of the indexing process. Possible values: unknown (initial
state, indexing not yet started), indexing (currently being processed),
indexed (successfully indexed and ready for use), failed (indexing
process encountered an error)."
enum:
- unknown
- indexing
- indexed
- failed
- retry
Version:
type: object
description: Represents a specific version of a package with metadata and
lifecycle information
properties:
id:
type: string
description: The unique version identifier, typically following semantic
versioning (e.g., 1.2.3)
$ref: "#/components/schemas/SemanticVersionPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was last modified
archiveStatus:
type: string
description: Current status of the package version, controlling its availability
enum:
- archive
- unarchive
- error_state
stale:
type: boolean
readOnly: true
description: >
True when this version serves at least one stale artifact — a
materialized source or index that is serving non-current data for
any
reason (docs/persistence.md §9.7). Display-only roll-up (the OR of
its
artifacts' `stale`); the version still serves prior values.
False/absent otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: >
The earliest fresh→stale crossover instant across the version's
stale
artifacts (§9.7 roll-up). Null when no artifact carries an age-based
crossover (or the version is fresh).
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: >
The union of the version's artifacts' staleness cause(s) (§9.7).
Empty
when fresh.
promoteWhenReady:
type: boolean
readOnly: true
description: >
Whether this version is armed for auto-promote: the
version-lifecycle
reconciler promotes it to the package's `latestVersion` once it is
ready
(fully indexed and settled into a servable resting state —
materialized,
or no persist sources / DuckDB serving live) and has never been
latest.
Read-only state set by the system at publish when the package's
`autoPromote` policy is enabled (at most one version per package is
armed
at a time); cleared once the intent resolves (after promotion, or on
terminal materialization failure).
promotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently became the package's latest. Null if
it
has never been promoted. Used as the auto-promote "never been
latest"
rollback guard.
demotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently stopped being the package's latest.
Null
while it is the current latest or has never been latest.
Auto-archive's
ttl is measured from this timestamp.
metadata:
nullable: true
$ref: "#/components/schemas/VersionIndexingMetadata"
indexingProgress:
$ref: "#/components/schemas/VersionIndexingProgress"
buildStatus:
type: string
readOnly: true
description: >
Single aggregate build status for this version, rolling up its
materialization and indexing into one lifecycle so tables and
indexes
present as one family:
- `FAILED` if either side failed.
- else `BUILDING` while either side is still working (materializing, or
indexing not yet settled).
- else `UNSUPPORTED` when the version declares persist sources whose
dialect cannot be materialized in v0 (DuckDB) — nothing is built and
those sources serve live — and indexing has settled.
- else `READY` once both sides have reached a servable resting state.
Derived read-only projection.
enum:
- BUILDING
- READY
- FAILED
- UNSUPPORTED
scope:
type: string
nullable: true
readOnly: true
description: >
The version's materialization scope mode, ingested from the package
manifest root (`Package.scope`) at materialize time:
- `version`: this version owns its materialized source tables — they
are not reused across versions. (Dimension indexes are the
exception: they remain content-addressed and may still be shared
across versions regardless of scope until per-version index
isolation lands with the index-cadence scheduler — see the note on
`Index.scope`.) A package-level `materializationSchedule` is legal
only in this mode.
- `package`: materialized source tables may be reused across the
package's own versions when fresh; cadence is freshness only (no
schedule).
Null when unknown (older versions materialized before scope was
recorded); the control plane treats null as the default (`package`).
enum:
- version
- package
materializationSchedule:
type: string
nullable: true
readOnly: true
description: >
The version's re-materialization cadence — the 5-field UNIX cron
from
the package manifest's `materialization.schedule` (e.g. `0 6 * *
*`),
ingested at materialize time. Null when the package declares no
schedule (the version materializes only on publish or on-demand
rebuild).
nextScheduledAt:
type: string
format: date-time
nullable: true
readOnly: true
description: |
When the scheduler will next re-materialize this version on its
`materializationSchedule`. Null when the version has no schedule.
lastRefreshedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When a scheduled (SCHEDULER-trigger) re-materialization of this
version
last fired. Null when the version has no schedule or has not yet
fired.
materializationFreshnessWindowSeconds:
type: integer
format: int64
nullable: true
readOnly: true
description: >
The package-level freshness window declared in the package
manifest's
`materialization.freshness.window`, parsed to seconds and ingested
write-once at materialize time. This is the refresh objective /
staleness
bound that individual sources and indexes inherit as the package
default
under most-specific-wins resolution. Null when the package declares
no
freshness window. Mutually exclusive with `materializationSchedule`:
a
version configures a schedule OR a freshness window, never both.
materializationFreshnessFallback:
type: string
nullable: true
readOnly: true
description: >
The package-level freshness fallback
(`materialization.freshness.fallback`)
— the query-time behavior when the window is missed ("live" |
"stale_ok" |
"fail"), reported verbatim from the manifest. Null when unset or no
freshness is declared.
buildPlan:
nullable: true
description: >
The persist build plan's dependency graph (DAG) for this version —
the
persist sources and their dependsOn edges. Read from the publisher's
deterministic build plan. Populated only on the single-version GET
(getVersion); null on list responses and when the version declares
no
persist source or no healthy worker can serve the plan.
$ref: "#/components/schemas/BuildPlanGraph"
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
VersionIndexingMetadata:
type: object
description: Metadata from indexing failures, attached to a package version
properties:
displayErrorMessage:
type: string
description: User-friendly error message explaining why indexing failed
rawErrorMessage:
type: string
description: Detailed error message
VersionIndexingProgress:
type: object
nullable: true
description: >
Aggregate package-indexing (source-extraction) progress for a package
version, polled from the entity-indexing service while the version is
being indexed. Populated on the single-version read while indexing is in
progress (indexStatus = indexing); null once indexed/failed or when
progress is unavailable. Mirrors ConnectionIndexingProgress.
Per-dimension index progress is surfaced separately via the index-run /
dimensional-index APIs, not here.
properties:
packageProgress:
$ref: "#/components/schemas/PackageIndexingProgress"
PackageIndexingProgress:
type: object
description: Package-indexing pipeline progress (sources).
properties:
sourcesTotal:
type: integer
sourcesProcessing:
type: integer
sourcesCompleted:
type: integer
sourcesFailed:
type: integer
entitiesFound:
type: integer
nullable: true
description: Sum of compiled entities indexed over completed sources (null if no
counts recorded yet).
BuildPlanGraph:
type: object
description: >
The persist build plan's dependency graph (DAG) for a version: persist
sources
as nodes and their dependsOn relationships as edges. A deterministic
property of
the compiled package version, so identical across that version's runs.
properties:
nodes:
type: array
items:
$ref: "#/components/schemas/BuildPlanNode"
edges:
type: array
items:
$ref: "#/components/schemas/BuildPlanEdge"
BuildPlanNode:
type: object
description: One persist source in the build plan.
properties:
sourceId:
type: string
description: Stable source identifier (the publisher's sourceID).
name:
type: string
description: The persist source's name.
connectionName:
type: string
description: The connection the source materializes into.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`), for deep-linking the source
back to its model. Null when the serving worker's build plan
predates this field.
BuildPlanEdge:
type: object
description: A dependency edge — "from" must be built before "to".
properties:
from:
type: string
description: Upstream source id (a dependency).
to:
type: string
description: Downstream source id that depends on "from".
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete package
Source: https://www.credibledata.com/docs/admin-api-reference/packages/delete-package
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}:
delete:
tags:
- packages
summary: Delete package
description: >
Permanently deletes a package and all associated versions. This
operation is irreversible.
**Authorization**: Requires package admin or modeler permissions.
**Warning**: This operation will cascade delete all package versions.
**Side Effects**: Removes all versions and associated data for the
package.
operationId: deletePackage
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Package deleted successfully
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get package details
Source: https://www.credibledata.com/docs/admin-api-reference/packages/get-package-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}:
get:
tags:
- packages
summary: Get package details
description: >
Retrieves detailed information about a specific package including
metadata, version
information, and configuration details.
**Authorization**: Requires read access to the package.
**Parameters**: The `checkAdmin` parameter can be used to verify admin
privileges.
operationId: getPackage
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: checkAdmin
in: query
required: false
description: Whether to verify admin privileges for the resource
schema:
type: boolean
default: false
responses:
"200":
description: Package details retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy data model package containing models, queries,
and related resources
properties:
name:
type: string
description: The unique name of the package within its environment
$ref: "#/components/schemas/IdentifierPattern"
latestVersion:
type: string
description: The version identifier of the most recent published version
$ref: "#/components/schemas/SemanticVersionPattern"
description:
type: string
description: Human-readable description of the package's purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was first created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
resourceIdentifier:
description: Unique resource identifier for the package, used for API references
and permissions
type: string
nullable: false
$ref: "#/components/schemas/ResourceIdentifierPattern"
indexStatus:
$ref: "#/components/schemas/IndexStatus"
autoPromote:
type: boolean
nullable: true
description: >
Package-scoped auto-promote policy applied as a default to each
newly
published version: when true, a new version is armed (see
Version.promoteWhenReady) and the lifecycle reconciler promotes it
to
`latestVersion` once it is ready, subject to the never-been-latest
rollback guard. Newly created packages default this to `true`: a
package
created without an explicit `autoPromote` gets auto-promote enabled.
Omitting the field on update leaves the policy unchanged; toggling
it on
does not retroactively arm existing versions. Independent of
`autoArchiveTtl`.
autoArchiveTtl:
type: string
nullable: true
description: >
Package-scoped ttl auto-archive policy: how long a version is
retained
after it stops being latest, e.g. `30d`, `24h`, `2w` (units s, m, h,
d,
w). A formerly-latest version is archived (its materialized tables
reclaimed) once it has been demoted for longer than this ttl; the
current
latest is never archived. `0` archives a version as soon as it is
demoted
(keep-only-latest, modulo the reconciler tick) — note this trades
away the
cheap rollback window. A non-empty value enables auto-archive; an
empty
string disables it. Newly created packages default to `30d`: a
package
created without an explicit `autoArchiveTtl` gets 30-day
auto-archive.
Omitting the field on update leaves the policy unchanged.
Independent of
`autoPromote`.
SemanticVersionPattern:
type: string
pattern: ^[0-9]+\.[0-9]+\.[0-9]+(-[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?(\+[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?$
description: SemVer 2.0 version identifier. Required core MAJOR.MINOR.PATCH plus
optional pre-release suffix (e.g. `-rc1`, `-alpha.2`) and optional build
metadata (e.g. `+20231120.deadbeef`). Previously enforced strict
MAJOR.MINOR.PATCH only, which would have started 400-ing legitimate
pre-release versions (e.g. videoamp's -rc1/-rc2 RC builds) once
hibernate-validator started firing.
ResourceIdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_/.:-]+$
description: Resource identifier pattern supporting slashes, dots, dashes, and colons
IndexStatus:
type: string
description: "Status of the indexing process. Possible values: unknown (initial
state, indexing not yet started), indexing (currently being processed),
indexed (successfully indexed and ready for use), failed (indexing
process encountered an error)."
enum:
- unknown
- indexing
- indexed
- failed
- retry
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get package version source
Source: https://www.credibledata.com/docs/admin-api-reference/packages/get-package-version-source
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/source
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/source:
get:
tags:
- packages
summary: Get package version source
description: >
Retrieves the raw package archive (zip) uploaded at publish time for a
specific version,
defaulting to the package's latest version.
**Authorization**: Requires update (edit) access to the package
(`can_update_package`) — this returns raw package source, gated the same
as editing/publishing, not mere read access.
operationId: getPackageSource
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: query
required: false
description: The version to fetch the source for. Defaults to the package's
latest version.
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: Package source retrieved successfully
content:
application/octet-stream:
schema:
type: string
format: binary
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List accessible packages by organization
Source: https://www.credibledata.com/docs/admin-api-reference/packages/list-accessible-packages-by-organization
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/packages
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/packages:
get:
tags:
- packages
summary: List accessible packages by organization
description: >
Returns a list of package resource identifiers under the given
organization
that the current user has access to. By default returns only packages
the user
can share (admin/modeler role). Set `onlyShareable=false` to include all
readable packages (including viewer access).
**Note**: This endpoint provides cross-environment package visibility.
It aggregates
packages from all environments within the organization that the user has
access to.
**Authorization**: Requires read access to the organization.
**Response**: Returns array of package resource identifiers.
operationId: listOrganizationPackages
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: onlyShareable
in: query
required: false
description: When true, returns only packages the user can share
(admin/modeler). When false, returns all readable packages.
schema:
type: boolean
default: true
responses:
"200":
description: List of package resource identifiers retrieved successfully
content:
application/json:
schema:
type: array
items:
type: string
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List packages in environment
Source: https://www.credibledata.com/docs/admin-api-reference/packages/list-packages-in-environment
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages:
get:
tags:
- packages
summary: List packages in environment
description: >
Retrieves all packages within the specified environment, including
metadata such as names,
descriptions, latest versions, and creation timestamps.
**Authorization**: Requires read access to the environment.
**Response**: Returns array of package objects with full metadata.
**Pagination**: Supports offset-based pagination with limit and offset
parameters.
operationId: listPackages
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–100."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: List of packages retrieved successfully
headers:
Total-Count:
description: Total number of packages available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
example: ;
rel="first",
;
rel="next"
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Package"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy data model package containing models, queries,
and related resources
properties:
name:
type: string
description: The unique name of the package within its environment
$ref: "#/components/schemas/IdentifierPattern"
latestVersion:
type: string
description: The version identifier of the most recent published version
$ref: "#/components/schemas/SemanticVersionPattern"
description:
type: string
description: Human-readable description of the package's purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was first created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
resourceIdentifier:
description: Unique resource identifier for the package, used for API references
and permissions
type: string
nullable: false
$ref: "#/components/schemas/ResourceIdentifierPattern"
indexStatus:
$ref: "#/components/schemas/IndexStatus"
autoPromote:
type: boolean
nullable: true
description: >
Package-scoped auto-promote policy applied as a default to each
newly
published version: when true, a new version is armed (see
Version.promoteWhenReady) and the lifecycle reconciler promotes it
to
`latestVersion` once it is ready, subject to the never-been-latest
rollback guard. Newly created packages default this to `true`: a
package
created without an explicit `autoPromote` gets auto-promote enabled.
Omitting the field on update leaves the policy unchanged; toggling
it on
does not retroactively arm existing versions. Independent of
`autoArchiveTtl`.
autoArchiveTtl:
type: string
nullable: true
description: >
Package-scoped ttl auto-archive policy: how long a version is
retained
after it stops being latest, e.g. `30d`, `24h`, `2w` (units s, m, h,
d,
w). A formerly-latest version is archived (its materialized tables
reclaimed) once it has been demoted for longer than this ttl; the
current
latest is never archived. `0` archives a version as soon as it is
demoted
(keep-only-latest, modulo the reconciler tick) — note this trades
away the
cheap rollback window. A non-empty value enables auto-archive; an
empty
string disables it. Newly created packages default to `30d`: a
package
created without an explicit `autoArchiveTtl` gets 30-day
auto-archive.
Omitting the field on update leaves the policy unchanged.
Independent of
`autoPromote`.
SemanticVersionPattern:
type: string
pattern: ^[0-9]+\.[0-9]+\.[0-9]+(-[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?(\+[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?$
description: SemVer 2.0 version identifier. Required core MAJOR.MINOR.PATCH plus
optional pre-release suffix (e.g. `-rc1`, `-alpha.2`) and optional build
metadata (e.g. `+20231120.deadbeef`). Previously enforced strict
MAJOR.MINOR.PATCH only, which would have started 400-ing legitimate
pre-release versions (e.g. videoamp's -rc1/-rc2 RC builds) once
hibernate-validator started firing.
ResourceIdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_/.:-]+$
description: Resource identifier pattern supporting slashes, dots, dashes, and colons
IndexStatus:
type: string
description: "Status of the indexing process. Possible values: unknown (initial
state, indexing not yet started), indexing (currently being processed),
indexed (successfully indexed and ready for use), failed (indexing
process encountered an error)."
enum:
- unknown
- indexing
- indexed
- failed
- retry
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update package metadata
Source: https://www.credibledata.com/docs/admin-api-reference/packages/update-package-metadata
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}:
patch:
tags:
- packages
summary: Update package metadata
description: >
Updates the metadata and configuration of an existing package, including
description,
settings, and other package-level properties.
**Authorization**: Requires package admin or modeler permissions.
**Validation**: Updates are validated against package constraints and
naming rules.
operationId: updatePackage
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
responses:
"200":
description: Package updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy data model package containing models, queries,
and related resources
properties:
name:
type: string
description: The unique name of the package within its environment
$ref: "#/components/schemas/IdentifierPattern"
latestVersion:
type: string
description: The version identifier of the most recent published version
$ref: "#/components/schemas/SemanticVersionPattern"
description:
type: string
description: Human-readable description of the package's purpose and contents
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was first created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the package was last modified
replicationCount:
type: integer
description: >
Number of replicas for high availability and performance. When sent
on create, this value is stored as-is (within min/max). When omitted
on create, Credible manages it for you. When omitted on update, the
existing value is left unchanged.
minimum: 1
maximum: 10
resourceIdentifier:
description: Unique resource identifier for the package, used for API references
and permissions
type: string
nullable: false
$ref: "#/components/schemas/ResourceIdentifierPattern"
indexStatus:
$ref: "#/components/schemas/IndexStatus"
autoPromote:
type: boolean
nullable: true
description: >
Package-scoped auto-promote policy applied as a default to each
newly
published version: when true, a new version is armed (see
Version.promoteWhenReady) and the lifecycle reconciler promotes it
to
`latestVersion` once it is ready, subject to the never-been-latest
rollback guard. Newly created packages default this to `true`: a
package
created without an explicit `autoPromote` gets auto-promote enabled.
Omitting the field on update leaves the policy unchanged; toggling
it on
does not retroactively arm existing versions. Independent of
`autoArchiveTtl`.
autoArchiveTtl:
type: string
nullable: true
description: >
Package-scoped ttl auto-archive policy: how long a version is
retained
after it stops being latest, e.g. `30d`, `24h`, `2w` (units s, m, h,
d,
w). A formerly-latest version is archived (its materialized tables
reclaimed) once it has been demoted for longer than this ttl; the
current
latest is never archived. `0` archives a version as soon as it is
demoted
(keep-only-latest, modulo the reconciler tick) — note this trades
away the
cheap rollback window. A non-empty value enables auto-archive; an
empty
string disables it. Newly created packages default to `30d`: a
package
created without an explicit `autoArchiveTtl` gets 30-day
auto-archive.
Omitting the field on update leaves the policy unchanged.
Independent of
`autoPromote`.
SemanticVersionPattern:
type: string
pattern: ^[0-9]+\.[0-9]+\.[0-9]+(-[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?(\+[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?$
description: SemVer 2.0 version identifier. Required core MAJOR.MINOR.PATCH plus
optional pre-release suffix (e.g. `-rc1`, `-alpha.2`) and optional build
metadata (e.g. `+20231120.deadbeef`). Previously enforced strict
MAJOR.MINOR.PATCH only, which would have started 400-ing legitimate
pre-release versions (e.g. videoamp's -rc1/-rc2 RC builds) once
hibernate-validator started firing.
ResourceIdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_/.:-]+$
description: Resource identifier pattern supporting slashes, dots, dashes, and colons
IndexStatus:
type: string
description: "Status of the indexing process. Possible values: unknown (initial
state, indexing not yet started), indexing (currently being processed),
indexed (successfully indexed and ready for use), failed (indexing
process encountered an error)."
enum:
- unknown
- indexing
- indexed
- failed
- retry
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create system permission
Source: https://www.credibledata.com/docs/admin-api-reference/permissions/create-system-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/permissions:
post:
tags:
- permissions
summary: Create system permission
description: >
Creates a system-level permission assignment for administrative
functions,
granting users elevated privileges across the whole service.
**Authorization**: Requires system admin permissions.
**Scope**: System permissions affect access across all organizations and
resources.
**Roles**: Currently supports admin role for full system access.
operationId: createSystemPermission
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/SystemPermission"
responses:
"200":
description: System permission created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/SystemPermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
SystemPermission:
type: object
description: Represents a system-level permission assignment for administrative
functions
properties:
userEmail:
type: string
description: The email address of the user to grant system permissions to
format: email
permission:
type: string
description: The system-level permission role to grant
enum:
- admin
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a run (rebuild a version, or a single scoped unit)
Source: https://www.credibledata.com/docs/admin-api-reference/runs/create-a-run-rebuild-a-version-or-a-single-scoped-unit
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs:
post:
tags:
- runs
summary: Create a run (rebuild a version, or a single scoped unit)
description: >
Starts a run for this package's version identified by `versionId`. By
default (no scope selectors) it is a **full run** that re-materializes
every
persist source in the version **and** rebuilds every indexed dimension
it
defines — one run driving both unit families through the same two-phase
build (tables first, then indexes). It is the on-demand equivalent of
the
run a publish triggers.
The optional `sourceName` / `dimension` / `modelFilePath` selectors (see
`CreateRunRequest`) narrow the run to a single unit (Phase C per-unit
dispatch); a null selector widens back to the whole version, so the
whole-version full run stays the default. A version that predates the
content-addressed index model is discovered and migrated into it as part
of the run. The produced
units are surfaced in the run's build plan (`buildPlan.nodes`/`edges` on
`getRun`), each advancing its own serving pointer independently (a
failed
unit does not block the others). Returns the started run.
**Scheduled packages reject scoped runs.** When the version's package
declares a `materialization.schedule` (legal only in `scope: version`),
it
refreshes the whole version atomically on its cron, so the only
on-demand
rebuild it supports is the whole-version full run. A request that
carries
any scope selector (`sourceName` / `dimension` / `modelFilePath`)
against a
scheduled version is rejected with `400` rather than silently widened —
omit
the selectors to refresh the whole version instead.
**Authorization**: Requires update access to the package.
operationId: createRun
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/CreateRunRequest"
responses:
"202":
description: Run created (build started)
content:
application/json:
schema:
$ref: "#/components/schemas/Run"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: A run is already in flight for this version
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
"503":
description: No worker is currently available to run the build. Worker capacity
is an internal, transient condition (not a client error), so this is
retryable — retry shortly.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
CreateRunRequest:
type: object
description: |
Request a run for a version. By default (no scope selectors) this is a
full run: re-materialize every persist source in the version and rebuild
every indexed dimension it defines, in one run. The optional
sourceName / dimension / modelFilePath selectors narrow the run to a
single unit (Phase C per-unit dispatch); a null selector widens to the
whole version, so the whole-version full run stays the default.
required:
- versionId
properties:
versionId:
type: string
description: >
The version to (re)build. With no scope selectors the run
re-materializes all of the version's persist sources and rebuilds
all
of the dimensions they define. A version that predates the
content-addressed index model is discovered and migrated into it as
part of the same run.
sourceName:
type: string
description: >
Optional. Restrict the run to a single persist source's table (Phase
C per-source dispatch). The named source is force-rebuilt (a fresh
generation at the same content address); its persist upstreams are
referenced from their existing materialized tables, not rebuilt
(unless
includeUpstream is set). Null widens to every persist source in the
version.
includeUpstream:
type: boolean
default: false
description: >
Optional. Only meaningful when the target resolves to a source
(sourceName set — for a source rerun, or an index rerun that also
names
its source). When true, the run also force-rebuilds the target's
transitive upstream persisted sources (its full derivation closure),
so
the whole lineage feeding the target is refreshed rather than
referenced
from existing tables:
- source target: rebuild the source and every persisted source it
derives from.
- index target (dimension set): rebuild the source table the index
reads from and its upstream closure, then re-index.
When false (default): a source target rebuilds only that source (its
upstreams reused); an index target reuses the source table and only
re-indexes. Ignored for a full run or a dimension target that names
no
source.
dimension:
type: string
description: |
Optional. Restrict the run to a single indexed dimension's index.
Combined with sourceName it targets that dimension on that source;
alone it targets the dimension across the sources that define it
(disambiguated by modelFilePath when set). Null widens to every
indexed dimension in scope.
modelFilePath:
type: string
description: >
Optional. Disambiguates a dimension defined in more than one model
file. Null widens to every model file defining the matched
dimension.
Run:
type: object
description: >
A package-level build/refresh event (version-independent) — the single,
unified run resource. It records the requested scope and correlates the
dispatch; its concrete units are the typed artifacts it produced —
materialized sources (source nodes) and built indexes (index nodes) —
surfaced in the run's build plan (`buildPlan.nodes`/`edges`, populated
on
`getRun`). A run defaults to a full run spanning both families — a
publish, an on-demand rebuild, and a scheduled re-materialization all
refresh a version's tables and its indexes — but may also be scoped to a
single unit (Phase C per-unit dispatch). Each produced unit advances its
own serving pointer independently, so a partial failure leaves the run
READY while the failed unit carries its own error.
properties:
id:
type: string
buildNumber:
type: integer
description: >
Stable, 1-based build ordinal within the **package** — the "Build
gNNN"
the UI shows (zero-padded for display). Monotonic per package,
assigned
at run creation. This is the run build number, NOT the per-source
physical table generation (the g in a materialized table name),
which counts per-source rebuilds and diverges under reuse. Null only
for
legacy runs created before the number existed.
trigger:
type: string
enum:
- PUBLISH
- ON_DEMAND
- SCHEDULER
status:
type: string
description: >
Run lifecycle status, rolled up from the units it produced.
Non-terminal: BUILDING. Terminal: READY, FAILED, CANCELLED. A run is
READY once every produced unit is terminal; individual unit failures
are carried per node in the run's build plan (`buildPlan.nodes`, on
`getRun`).
enum:
- BUILDING
- READY
- FAILED
- CANCELLED
targetSourceName:
type: string
description: Requested target source (Phase C per-unit dispatch). Null on a
whole-version run (the createRun default); set when createRun scoped
the run to a single source via the sourceName selector. A null
component widens to the whole package.
targetDimension:
type: string
description: Requested target dimension (Phase C per-unit dispatch). Null on a
whole-version run; set when createRun scoped the run to a single
indexed dimension via the dimension selector.
targetModelFilePath:
type: string
description: Requested target model file (Phase C per-unit dispatch). Null on a
whole-version run; disambiguates a dimension defined in more than
one model file when the modelFilePath selector is set.
targetIncludeUpstream:
type: boolean
description: |
The scoped rerun's upstream choice (Phase C). Only meaningful with
`targetSourceName`/`targetDimension`: when true, the rerun also
force-rebuilt the target's transitive upstream persisted closure
(rather than reusing those upstream tables); false / absent = the
target alone (a source references its upstreams, an index reuses its
source table). Always false on a whole-version run.
triggeringVersionId:
type: string
description: >
The version this run was started for — the version whose publish
drove a
PUBLISH run, the version an on-demand full run rebuilds, or the
version a
scheduled re-materialization refreshes. Provenance only: the run
itself is
package-scoped and may impact other versions that bind the same
dimension.
Null only for a future package-level scoped refresh with no single
initiating version.
buildPlan:
$ref: "#/components/schemas/RunBuildPlan"
startedAt:
type: string
format: date-time
completedAt:
type: string
format: date-time
error:
type: string
description: Run-level failure reason (planning/orchestration failure); per-unit
failures live on the produced units.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlan:
type: object
description: >
A run's build plan across both unit families. Two layers:
1. A diagnostic **summary** (counters + name lists): how many persist
sources (table units) and indexed dimensions (index units) it planned,
and their outcomes. Always populated (on both `listRuns` and `getRun`).
2. A stateful **dependency graph** (`nodes` + `edges`): one node per
source
(materialized table) and per indexed dimension, each carrying that unit's
live state, wired source -> index. Populated on `getRun` only; null on
`listRuns` to keep the list payload small (mirrors how `Version.buildPlan`
is `getVersion`-only). This graph is the single source of truth for a
run's units — the internal content address (entity_id) is never exposed.
properties:
sourceCount:
type: integer
description: Number of persist sources (table units) in the run's build plan.
builtSources:
type: array
description: Sources that produced a fresh table this run.
items:
type: string
reusedSources:
type: array
description: Sources whose existing table was reused this run (their definition
and inputs were unchanged, so no rebuild was needed).
items:
type: string
unsupportedSources:
type: array
description: Sources skipped because the connection dialect can't materialize
them.
items:
type: string
failedSources:
type: object
description: Source name -> failure reason, for sources that errored this run.
additionalProperties:
type: string
dimensionCount:
type: integer
description: Number of indexed dimensions (index units) this run
produced/refreshed.
builtDimensions:
type: array
description: Dimensions that produced a READY index this run.
items:
type: string
failedDimensions:
type: object
description: Dimension -> failure reason, for dimensions that failed this run.
additionalProperties:
type: string
nodes:
type: array
description: >
The build plan's stateful graph nodes: one per source (materialized
table) and per indexed dimension, each carrying that unit's live
state.
Populated on `getRun` only; null/absent on `listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanNode"
edges:
type: array
description: >
Dependency edges over `nodes`, keyed by node `key`. Carries source
->
index edges (each indexed dimension depends on its owning source)
and
source -> source table lineage (from the run's durable build plan's
derivation DAG). Populated on `getRun` only; null/absent on
`listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanEdge"
RunBuildPlanNode:
type: object
description: >
One node in a run's build-plan graph, discriminated by `nodeType`. A
SOURCE
node is a persist source (materialized when this run produced a physical
table for it); an INDEX node is a built index for one `(source,
dimension)`.
Carries the unit's live state; fields not relevant to a node's type are
null.
The internal content address (entity_id) is never exposed.
properties:
key:
type: string
description: >
Stable within-graph identity used by `RunBuildPlanEdge`. Source
nodes are
keyed by source name; index nodes by their `source.dimension
(modelFile)`
coordinate — so a discovered-but-not-yet-built dimension still has a
key.
id:
type: string
description: >
The backing record's UUID (materialized table or index
anchor/artifact),
for deep-linking. Null for a discovered dimension with no artifact
yet.
nodeType:
type: string
description: Which family this node is — SOURCE (materialized source) or INDEX
(built index).
enum:
- SOURCE
- INDEX
sourceName:
type: string
description: The persist source (SOURCE) or the source that owns the dimension
(INDEX).
status:
type: string
description: >
Per-run WORK lifecycle for this node — the state of the work THIS
run
does on it, not the underlying artifact's steady state. PENDING: the
run
is in flight and this unit's build hasn't started. BUILDING: this
run is
actively (re)materializing/(re)indexing it. DONE: this run's build
committed (or, on a full run, reaffirmed an unchanged artifact).
FAILED:
this run's build errored (see `error`). A scoped rerun's graph
carries
only the units it works on, so every node walks PENDING -> BUILDING
->
DONE/FAILED as the run progresses.
enum:
- PENDING
- BUILDING
- DONE
- FAILED
materialized:
type: boolean
description: >
SOURCE nodes only. True when this run produced a physical table for
the
source; false for a source that only surfaces via an indexed
dimension
(e.g. a live/non-persisted twin) so its index nodes aren't orphaned.
tableName:
type: string
description: >
Physical table name of the materialized source, an immutable
generation
(e.g. orders_ab12_v3). SOURCE nodes only; null for INDEX nodes.
modelFilePath:
type: string
description: >
The model file this dimension was discovered under, to distinguish
two
same-named dimensions from different files. INDEX nodes only.
dimension:
type: string
description: The indexed dimension path (e.g. "country" or "people.name"). INDEX
nodes only; null for SOURCE nodes.
rowCount:
type: integer
format: int64
description: Indexed value count, reported by the pipeline on completion. INDEX
nodes only; null until READY or for SOURCE nodes.
lastIndexedAt:
type: string
format: date-time
description: When this index generation finished building. INDEX nodes only;
null until READY or for SOURCE nodes.
error:
type: string
description: Failure reason when a node's unit failed; null otherwise.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlanEdge:
type: object
description: A dependency edge over the run's build-plan nodes — "from" must be
built before "to".
properties:
from:
type: string
description: Upstream node `key` (a dependency, e.g. a source).
to:
type: string
description: Downstream node `key` that depends on "from" (e.g. an index on that
source).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get a run
Source: https://www.credibledata.com/docs/admin-api-reference/runs/get-a-run
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs/{runId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs/{runId}:
get:
tags:
- runs
summary: Get a run
operationId: getRun
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: runId
in: path
required: true
description: The unique identifier of the run
schema:
type: string
responses:
"200":
description: Run retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Run"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Run:
type: object
description: >
A package-level build/refresh event (version-independent) — the single,
unified run resource. It records the requested scope and correlates the
dispatch; its concrete units are the typed artifacts it produced —
materialized sources (source nodes) and built indexes (index nodes) —
surfaced in the run's build plan (`buildPlan.nodes`/`edges`, populated
on
`getRun`). A run defaults to a full run spanning both families — a
publish, an on-demand rebuild, and a scheduled re-materialization all
refresh a version's tables and its indexes — but may also be scoped to a
single unit (Phase C per-unit dispatch). Each produced unit advances its
own serving pointer independently, so a partial failure leaves the run
READY while the failed unit carries its own error.
properties:
id:
type: string
buildNumber:
type: integer
description: >
Stable, 1-based build ordinal within the **package** — the "Build
gNNN"
the UI shows (zero-padded for display). Monotonic per package,
assigned
at run creation. This is the run build number, NOT the per-source
physical table generation (the g in a materialized table name),
which counts per-source rebuilds and diverges under reuse. Null only
for
legacy runs created before the number existed.
trigger:
type: string
enum:
- PUBLISH
- ON_DEMAND
- SCHEDULER
status:
type: string
description: >
Run lifecycle status, rolled up from the units it produced.
Non-terminal: BUILDING. Terminal: READY, FAILED, CANCELLED. A run is
READY once every produced unit is terminal; individual unit failures
are carried per node in the run's build plan (`buildPlan.nodes`, on
`getRun`).
enum:
- BUILDING
- READY
- FAILED
- CANCELLED
targetSourceName:
type: string
description: Requested target source (Phase C per-unit dispatch). Null on a
whole-version run (the createRun default); set when createRun scoped
the run to a single source via the sourceName selector. A null
component widens to the whole package.
targetDimension:
type: string
description: Requested target dimension (Phase C per-unit dispatch). Null on a
whole-version run; set when createRun scoped the run to a single
indexed dimension via the dimension selector.
targetModelFilePath:
type: string
description: Requested target model file (Phase C per-unit dispatch). Null on a
whole-version run; disambiguates a dimension defined in more than
one model file when the modelFilePath selector is set.
targetIncludeUpstream:
type: boolean
description: |
The scoped rerun's upstream choice (Phase C). Only meaningful with
`targetSourceName`/`targetDimension`: when true, the rerun also
force-rebuilt the target's transitive upstream persisted closure
(rather than reusing those upstream tables); false / absent = the
target alone (a source references its upstreams, an index reuses its
source table). Always false on a whole-version run.
triggeringVersionId:
type: string
description: >
The version this run was started for — the version whose publish
drove a
PUBLISH run, the version an on-demand full run rebuilds, or the
version a
scheduled re-materialization refreshes. Provenance only: the run
itself is
package-scoped and may impact other versions that bind the same
dimension.
Null only for a future package-level scoped refresh with no single
initiating version.
buildPlan:
$ref: "#/components/schemas/RunBuildPlan"
startedAt:
type: string
format: date-time
completedAt:
type: string
format: date-time
error:
type: string
description: Run-level failure reason (planning/orchestration failure); per-unit
failures live on the produced units.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlan:
type: object
description: >
A run's build plan across both unit families. Two layers:
1. A diagnostic **summary** (counters + name lists): how many persist
sources (table units) and indexed dimensions (index units) it planned,
and their outcomes. Always populated (on both `listRuns` and `getRun`).
2. A stateful **dependency graph** (`nodes` + `edges`): one node per
source
(materialized table) and per indexed dimension, each carrying that unit's
live state, wired source -> index. Populated on `getRun` only; null on
`listRuns` to keep the list payload small (mirrors how `Version.buildPlan`
is `getVersion`-only). This graph is the single source of truth for a
run's units — the internal content address (entity_id) is never exposed.
properties:
sourceCount:
type: integer
description: Number of persist sources (table units) in the run's build plan.
builtSources:
type: array
description: Sources that produced a fresh table this run.
items:
type: string
reusedSources:
type: array
description: Sources whose existing table was reused this run (their definition
and inputs were unchanged, so no rebuild was needed).
items:
type: string
unsupportedSources:
type: array
description: Sources skipped because the connection dialect can't materialize
them.
items:
type: string
failedSources:
type: object
description: Source name -> failure reason, for sources that errored this run.
additionalProperties:
type: string
dimensionCount:
type: integer
description: Number of indexed dimensions (index units) this run
produced/refreshed.
builtDimensions:
type: array
description: Dimensions that produced a READY index this run.
items:
type: string
failedDimensions:
type: object
description: Dimension -> failure reason, for dimensions that failed this run.
additionalProperties:
type: string
nodes:
type: array
description: >
The build plan's stateful graph nodes: one per source (materialized
table) and per indexed dimension, each carrying that unit's live
state.
Populated on `getRun` only; null/absent on `listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanNode"
edges:
type: array
description: >
Dependency edges over `nodes`, keyed by node `key`. Carries source
->
index edges (each indexed dimension depends on its owning source)
and
source -> source table lineage (from the run's durable build plan's
derivation DAG). Populated on `getRun` only; null/absent on
`listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanEdge"
RunBuildPlanNode:
type: object
description: >
One node in a run's build-plan graph, discriminated by `nodeType`. A
SOURCE
node is a persist source (materialized when this run produced a physical
table for it); an INDEX node is a built index for one `(source,
dimension)`.
Carries the unit's live state; fields not relevant to a node's type are
null.
The internal content address (entity_id) is never exposed.
properties:
key:
type: string
description: >
Stable within-graph identity used by `RunBuildPlanEdge`. Source
nodes are
keyed by source name; index nodes by their `source.dimension
(modelFile)`
coordinate — so a discovered-but-not-yet-built dimension still has a
key.
id:
type: string
description: >
The backing record's UUID (materialized table or index
anchor/artifact),
for deep-linking. Null for a discovered dimension with no artifact
yet.
nodeType:
type: string
description: Which family this node is — SOURCE (materialized source) or INDEX
(built index).
enum:
- SOURCE
- INDEX
sourceName:
type: string
description: The persist source (SOURCE) or the source that owns the dimension
(INDEX).
status:
type: string
description: >
Per-run WORK lifecycle for this node — the state of the work THIS
run
does on it, not the underlying artifact's steady state. PENDING: the
run
is in flight and this unit's build hasn't started. BUILDING: this
run is
actively (re)materializing/(re)indexing it. DONE: this run's build
committed (or, on a full run, reaffirmed an unchanged artifact).
FAILED:
this run's build errored (see `error`). A scoped rerun's graph
carries
only the units it works on, so every node walks PENDING -> BUILDING
->
DONE/FAILED as the run progresses.
enum:
- PENDING
- BUILDING
- DONE
- FAILED
materialized:
type: boolean
description: >
SOURCE nodes only. True when this run produced a physical table for
the
source; false for a source that only surfaces via an indexed
dimension
(e.g. a live/non-persisted twin) so its index nodes aren't orphaned.
tableName:
type: string
description: >
Physical table name of the materialized source, an immutable
generation
(e.g. orders_ab12_v3). SOURCE nodes only; null for INDEX nodes.
modelFilePath:
type: string
description: >
The model file this dimension was discovered under, to distinguish
two
same-named dimensions from different files. INDEX nodes only.
dimension:
type: string
description: The indexed dimension path (e.g. "country" or "people.name"). INDEX
nodes only; null for SOURCE nodes.
rowCount:
type: integer
format: int64
description: Indexed value count, reported by the pipeline on completion. INDEX
nodes only; null until READY or for SOURCE nodes.
lastIndexedAt:
type: string
format: date-time
description: When this index generation finished building. INDEX nodes only;
null until READY or for SOURCE nodes.
error:
type: string
description: Failure reason when a node's unit failed; null otherwise.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlanEdge:
type: object
description: A dependency edge over the run's build-plan nodes — "from" must be
built before "to".
properties:
from:
type: string
description: Upstream node `key` (a dependency, e.g. a source).
to:
type: string
description: Downstream node `key` that depends on "from" (e.g. an index on that
source).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List runs for a package
Source: https://www.credibledata.com/docs/admin-api-reference/runs/list-runs-for-a-package
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs:
get:
tags:
- runs
summary: List runs for a package
description: >
Lists build/refresh runs for this package, most recent first. A run is a
single **package-level** build event carrying typed units — materialized
sources (table units) and built indexes (index units). A run defaults to
a
full run spanning both families — a publish, an on-demand rebuild, and a
scheduled re-materialization all refresh a version's tables and its
indexes
— but may also be scoped to a single unit (Phase C per-unit dispatch).
Runs
are version-independent: their artifacts may be shared across
versions.
Optional filters narrow the list:
* `versionId` — only runs that *impacted* the given version (i.e. whose
triggering publish was that version, or that built/refreshed a unit the
version binds). This is a derived view, not a stored scope; a refresh
with no triggering publish can still impact a version, and one run can
impact many.
* `sourceName` / `dimension` — only runs targeting that source/dimension.
**Authorization**: Requires read access to the package.
operationId: listRuns
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: query
required: false
description: Only return runs that impacted this version (derived filter).
schema:
$ref: "#/components/schemas/VersionIdPattern"
- name: sourceName
in: query
required: false
description: Only return runs targeting this source.
schema:
type: string
- name: dimension
in: query
required: false
description: Only return runs targeting this dimension.
schema:
type: string
- name: limit
in: query
required: false
description: "Maximum number of items to return. Use -1 or omit to return all
results. Valid values: -1 (all results) or 1–500."
schema:
type: integer
minimum: -1
maximum: 500
default: -1
- name: offset
in: query
required: false
description: Number of items to skip before starting to return results
schema:
type: integer
minimum: 0
default: 0
responses:
"200":
description: List of runs retrieved successfully
headers:
Total-Count:
description: Total number of runs available
schema:
type: integer
required: true
Link:
description: RFC 8288 pagination links (first, prev, next, last)
schema:
type: string
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Run"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Run:
type: object
description: >
A package-level build/refresh event (version-independent) — the single,
unified run resource. It records the requested scope and correlates the
dispatch; its concrete units are the typed artifacts it produced —
materialized sources (source nodes) and built indexes (index nodes) —
surfaced in the run's build plan (`buildPlan.nodes`/`edges`, populated
on
`getRun`). A run defaults to a full run spanning both families — a
publish, an on-demand rebuild, and a scheduled re-materialization all
refresh a version's tables and its indexes — but may also be scoped to a
single unit (Phase C per-unit dispatch). Each produced unit advances its
own serving pointer independently, so a partial failure leaves the run
READY while the failed unit carries its own error.
properties:
id:
type: string
buildNumber:
type: integer
description: >
Stable, 1-based build ordinal within the **package** — the "Build
gNNN"
the UI shows (zero-padded for display). Monotonic per package,
assigned
at run creation. This is the run build number, NOT the per-source
physical table generation (the g in a materialized table name),
which counts per-source rebuilds and diverges under reuse. Null only
for
legacy runs created before the number existed.
trigger:
type: string
enum:
- PUBLISH
- ON_DEMAND
- SCHEDULER
status:
type: string
description: >
Run lifecycle status, rolled up from the units it produced.
Non-terminal: BUILDING. Terminal: READY, FAILED, CANCELLED. A run is
READY once every produced unit is terminal; individual unit failures
are carried per node in the run's build plan (`buildPlan.nodes`, on
`getRun`).
enum:
- BUILDING
- READY
- FAILED
- CANCELLED
targetSourceName:
type: string
description: Requested target source (Phase C per-unit dispatch). Null on a
whole-version run (the createRun default); set when createRun scoped
the run to a single source via the sourceName selector. A null
component widens to the whole package.
targetDimension:
type: string
description: Requested target dimension (Phase C per-unit dispatch). Null on a
whole-version run; set when createRun scoped the run to a single
indexed dimension via the dimension selector.
targetModelFilePath:
type: string
description: Requested target model file (Phase C per-unit dispatch). Null on a
whole-version run; disambiguates a dimension defined in more than
one model file when the modelFilePath selector is set.
targetIncludeUpstream:
type: boolean
description: |
The scoped rerun's upstream choice (Phase C). Only meaningful with
`targetSourceName`/`targetDimension`: when true, the rerun also
force-rebuilt the target's transitive upstream persisted closure
(rather than reusing those upstream tables); false / absent = the
target alone (a source references its upstreams, an index reuses its
source table). Always false on a whole-version run.
triggeringVersionId:
type: string
description: >
The version this run was started for — the version whose publish
drove a
PUBLISH run, the version an on-demand full run rebuilds, or the
version a
scheduled re-materialization refreshes. Provenance only: the run
itself is
package-scoped and may impact other versions that bind the same
dimension.
Null only for a future package-level scoped refresh with no single
initiating version.
buildPlan:
$ref: "#/components/schemas/RunBuildPlan"
startedAt:
type: string
format: date-time
completedAt:
type: string
format: date-time
error:
type: string
description: Run-level failure reason (planning/orchestration failure); per-unit
failures live on the produced units.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlan:
type: object
description: >
A run's build plan across both unit families. Two layers:
1. A diagnostic **summary** (counters + name lists): how many persist
sources (table units) and indexed dimensions (index units) it planned,
and their outcomes. Always populated (on both `listRuns` and `getRun`).
2. A stateful **dependency graph** (`nodes` + `edges`): one node per
source
(materialized table) and per indexed dimension, each carrying that unit's
live state, wired source -> index. Populated on `getRun` only; null on
`listRuns` to keep the list payload small (mirrors how `Version.buildPlan`
is `getVersion`-only). This graph is the single source of truth for a
run's units — the internal content address (entity_id) is never exposed.
properties:
sourceCount:
type: integer
description: Number of persist sources (table units) in the run's build plan.
builtSources:
type: array
description: Sources that produced a fresh table this run.
items:
type: string
reusedSources:
type: array
description: Sources whose existing table was reused this run (their definition
and inputs were unchanged, so no rebuild was needed).
items:
type: string
unsupportedSources:
type: array
description: Sources skipped because the connection dialect can't materialize
them.
items:
type: string
failedSources:
type: object
description: Source name -> failure reason, for sources that errored this run.
additionalProperties:
type: string
dimensionCount:
type: integer
description: Number of indexed dimensions (index units) this run
produced/refreshed.
builtDimensions:
type: array
description: Dimensions that produced a READY index this run.
items:
type: string
failedDimensions:
type: object
description: Dimension -> failure reason, for dimensions that failed this run.
additionalProperties:
type: string
nodes:
type: array
description: >
The build plan's stateful graph nodes: one per source (materialized
table) and per indexed dimension, each carrying that unit's live
state.
Populated on `getRun` only; null/absent on `listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanNode"
edges:
type: array
description: >
Dependency edges over `nodes`, keyed by node `key`. Carries source
->
index edges (each indexed dimension depends on its owning source)
and
source -> source table lineage (from the run's durable build plan's
derivation DAG). Populated on `getRun` only; null/absent on
`listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanEdge"
RunBuildPlanNode:
type: object
description: >
One node in a run's build-plan graph, discriminated by `nodeType`. A
SOURCE
node is a persist source (materialized when this run produced a physical
table for it); an INDEX node is a built index for one `(source,
dimension)`.
Carries the unit's live state; fields not relevant to a node's type are
null.
The internal content address (entity_id) is never exposed.
properties:
key:
type: string
description: >
Stable within-graph identity used by `RunBuildPlanEdge`. Source
nodes are
keyed by source name; index nodes by their `source.dimension
(modelFile)`
coordinate — so a discovered-but-not-yet-built dimension still has a
key.
id:
type: string
description: >
The backing record's UUID (materialized table or index
anchor/artifact),
for deep-linking. Null for a discovered dimension with no artifact
yet.
nodeType:
type: string
description: Which family this node is — SOURCE (materialized source) or INDEX
(built index).
enum:
- SOURCE
- INDEX
sourceName:
type: string
description: The persist source (SOURCE) or the source that owns the dimension
(INDEX).
status:
type: string
description: >
Per-run WORK lifecycle for this node — the state of the work THIS
run
does on it, not the underlying artifact's steady state. PENDING: the
run
is in flight and this unit's build hasn't started. BUILDING: this
run is
actively (re)materializing/(re)indexing it. DONE: this run's build
committed (or, on a full run, reaffirmed an unchanged artifact).
FAILED:
this run's build errored (see `error`). A scoped rerun's graph
carries
only the units it works on, so every node walks PENDING -> BUILDING
->
DONE/FAILED as the run progresses.
enum:
- PENDING
- BUILDING
- DONE
- FAILED
materialized:
type: boolean
description: >
SOURCE nodes only. True when this run produced a physical table for
the
source; false for a source that only surfaces via an indexed
dimension
(e.g. a live/non-persisted twin) so its index nodes aren't orphaned.
tableName:
type: string
description: >
Physical table name of the materialized source, an immutable
generation
(e.g. orders_ab12_v3). SOURCE nodes only; null for INDEX nodes.
modelFilePath:
type: string
description: >
The model file this dimension was discovered under, to distinguish
two
same-named dimensions from different files. INDEX nodes only.
dimension:
type: string
description: The indexed dimension path (e.g. "country" or "people.name"). INDEX
nodes only; null for SOURCE nodes.
rowCount:
type: integer
format: int64
description: Indexed value count, reported by the pipeline on completion. INDEX
nodes only; null until READY or for SOURCE nodes.
lastIndexedAt:
type: string
format: date-time
description: When this index generation finished building. INDEX nodes only;
null until READY or for SOURCE nodes.
error:
type: string
description: Failure reason when a node's unit failed; null otherwise.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlanEdge:
type: object
description: A dependency edge over the run's build-plan nodes — "from" must be
built before "to".
properties:
from:
type: string
description: Upstream node `key` (a dependency, e.g. a source).
to:
type: string
description: Downstream node `key` that depends on "from" (e.g. an index on that
source).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Perform an action on a run
Source: https://www.credibledata.com/docs/admin-api-reference/runs/perform-an-action-on-a-run
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs/{runId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/runs/{runId}:
post:
tags:
- runs
summary: Perform an action on a run
description: |
Performs an action on a run. The action is specified via the
`action` query parameter:
* `cancel` - Cancels an in-flight (non-terminal) run.
**Authorization**: Requires update access to the package.
operationId: runAction
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: runId
in: path
required: true
description: The unique identifier of the run
schema:
type: string
- name: action
in: query
required: true
description: Action to perform on the run
schema:
type: string
enum:
- cancel
responses:
"200":
description: Action completed successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Run"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Action cannot be performed in the current state
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Run:
type: object
description: >
A package-level build/refresh event (version-independent) — the single,
unified run resource. It records the requested scope and correlates the
dispatch; its concrete units are the typed artifacts it produced —
materialized sources (source nodes) and built indexes (index nodes) —
surfaced in the run's build plan (`buildPlan.nodes`/`edges`, populated
on
`getRun`). A run defaults to a full run spanning both families — a
publish, an on-demand rebuild, and a scheduled re-materialization all
refresh a version's tables and its indexes — but may also be scoped to a
single unit (Phase C per-unit dispatch). Each produced unit advances its
own serving pointer independently, so a partial failure leaves the run
READY while the failed unit carries its own error.
properties:
id:
type: string
buildNumber:
type: integer
description: >
Stable, 1-based build ordinal within the **package** — the "Build
gNNN"
the UI shows (zero-padded for display). Monotonic per package,
assigned
at run creation. This is the run build number, NOT the per-source
physical table generation (the g in a materialized table name),
which counts per-source rebuilds and diverges under reuse. Null only
for
legacy runs created before the number existed.
trigger:
type: string
enum:
- PUBLISH
- ON_DEMAND
- SCHEDULER
status:
type: string
description: >
Run lifecycle status, rolled up from the units it produced.
Non-terminal: BUILDING. Terminal: READY, FAILED, CANCELLED. A run is
READY once every produced unit is terminal; individual unit failures
are carried per node in the run's build plan (`buildPlan.nodes`, on
`getRun`).
enum:
- BUILDING
- READY
- FAILED
- CANCELLED
targetSourceName:
type: string
description: Requested target source (Phase C per-unit dispatch). Null on a
whole-version run (the createRun default); set when createRun scoped
the run to a single source via the sourceName selector. A null
component widens to the whole package.
targetDimension:
type: string
description: Requested target dimension (Phase C per-unit dispatch). Null on a
whole-version run; set when createRun scoped the run to a single
indexed dimension via the dimension selector.
targetModelFilePath:
type: string
description: Requested target model file (Phase C per-unit dispatch). Null on a
whole-version run; disambiguates a dimension defined in more than
one model file when the modelFilePath selector is set.
targetIncludeUpstream:
type: boolean
description: |
The scoped rerun's upstream choice (Phase C). Only meaningful with
`targetSourceName`/`targetDimension`: when true, the rerun also
force-rebuilt the target's transitive upstream persisted closure
(rather than reusing those upstream tables); false / absent = the
target alone (a source references its upstreams, an index reuses its
source table). Always false on a whole-version run.
triggeringVersionId:
type: string
description: >
The version this run was started for — the version whose publish
drove a
PUBLISH run, the version an on-demand full run rebuilds, or the
version a
scheduled re-materialization refreshes. Provenance only: the run
itself is
package-scoped and may impact other versions that bind the same
dimension.
Null only for a future package-level scoped refresh with no single
initiating version.
buildPlan:
$ref: "#/components/schemas/RunBuildPlan"
startedAt:
type: string
format: date-time
completedAt:
type: string
format: date-time
error:
type: string
description: Run-level failure reason (planning/orchestration failure); per-unit
failures live on the produced units.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlan:
type: object
description: >
A run's build plan across both unit families. Two layers:
1. A diagnostic **summary** (counters + name lists): how many persist
sources (table units) and indexed dimensions (index units) it planned,
and their outcomes. Always populated (on both `listRuns` and `getRun`).
2. A stateful **dependency graph** (`nodes` + `edges`): one node per
source
(materialized table) and per indexed dimension, each carrying that unit's
live state, wired source -> index. Populated on `getRun` only; null on
`listRuns` to keep the list payload small (mirrors how `Version.buildPlan`
is `getVersion`-only). This graph is the single source of truth for a
run's units — the internal content address (entity_id) is never exposed.
properties:
sourceCount:
type: integer
description: Number of persist sources (table units) in the run's build plan.
builtSources:
type: array
description: Sources that produced a fresh table this run.
items:
type: string
reusedSources:
type: array
description: Sources whose existing table was reused this run (their definition
and inputs were unchanged, so no rebuild was needed).
items:
type: string
unsupportedSources:
type: array
description: Sources skipped because the connection dialect can't materialize
them.
items:
type: string
failedSources:
type: object
description: Source name -> failure reason, for sources that errored this run.
additionalProperties:
type: string
dimensionCount:
type: integer
description: Number of indexed dimensions (index units) this run
produced/refreshed.
builtDimensions:
type: array
description: Dimensions that produced a READY index this run.
items:
type: string
failedDimensions:
type: object
description: Dimension -> failure reason, for dimensions that failed this run.
additionalProperties:
type: string
nodes:
type: array
description: >
The build plan's stateful graph nodes: one per source (materialized
table) and per indexed dimension, each carrying that unit's live
state.
Populated on `getRun` only; null/absent on `listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanNode"
edges:
type: array
description: >
Dependency edges over `nodes`, keyed by node `key`. Carries source
->
index edges (each indexed dimension depends on its owning source)
and
source -> source table lineage (from the run's durable build plan's
derivation DAG). Populated on `getRun` only; null/absent on
`listRuns`.
items:
$ref: "#/components/schemas/RunBuildPlanEdge"
RunBuildPlanNode:
type: object
description: >
One node in a run's build-plan graph, discriminated by `nodeType`. A
SOURCE
node is a persist source (materialized when this run produced a physical
table for it); an INDEX node is a built index for one `(source,
dimension)`.
Carries the unit's live state; fields not relevant to a node's type are
null.
The internal content address (entity_id) is never exposed.
properties:
key:
type: string
description: >
Stable within-graph identity used by `RunBuildPlanEdge`. Source
nodes are
keyed by source name; index nodes by their `source.dimension
(modelFile)`
coordinate — so a discovered-but-not-yet-built dimension still has a
key.
id:
type: string
description: >
The backing record's UUID (materialized table or index
anchor/artifact),
for deep-linking. Null for a discovered dimension with no artifact
yet.
nodeType:
type: string
description: Which family this node is — SOURCE (materialized source) or INDEX
(built index).
enum:
- SOURCE
- INDEX
sourceName:
type: string
description: The persist source (SOURCE) or the source that owns the dimension
(INDEX).
status:
type: string
description: >
Per-run WORK lifecycle for this node — the state of the work THIS
run
does on it, not the underlying artifact's steady state. PENDING: the
run
is in flight and this unit's build hasn't started. BUILDING: this
run is
actively (re)materializing/(re)indexing it. DONE: this run's build
committed (or, on a full run, reaffirmed an unchanged artifact).
FAILED:
this run's build errored (see `error`). A scoped rerun's graph
carries
only the units it works on, so every node walks PENDING -> BUILDING
->
DONE/FAILED as the run progresses.
enum:
- PENDING
- BUILDING
- DONE
- FAILED
materialized:
type: boolean
description: >
SOURCE nodes only. True when this run produced a physical table for
the
source; false for a source that only surfaces via an indexed
dimension
(e.g. a live/non-persisted twin) so its index nodes aren't orphaned.
tableName:
type: string
description: >
Physical table name of the materialized source, an immutable
generation
(e.g. orders_ab12_v3). SOURCE nodes only; null for INDEX nodes.
modelFilePath:
type: string
description: >
The model file this dimension was discovered under, to distinguish
two
same-named dimensions from different files. INDEX nodes only.
dimension:
type: string
description: The indexed dimension path (e.g. "country" or "people.name"). INDEX
nodes only; null for SOURCE nodes.
rowCount:
type: integer
format: int64
description: Indexed value count, reported by the pipeline on completion. INDEX
nodes only; null until READY or for SOURCE nodes.
lastIndexedAt:
type: string
format: date-time
description: When this index generation finished building. INDEX nodes only;
null until READY or for SOURCE nodes.
error:
type: string
description: Failure reason when a node's unit failed; null otherwise.
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
RunBuildPlanEdge:
type: object
description: A dependency edge over the run's build-plan nodes — "from" must be
built before "to".
properties:
from:
type: string
description: Upstream node `key` (a dependency, e.g. a source).
to:
type: string
description: Downstream node `key` that depends on "from" (e.g. an index on that
source).
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create user account
Source: https://www.credibledata.com/docs/admin-api-reference/users/create-user-account
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /users
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/users:
post:
tags:
- users
summary: Create user account
description: >
Creates a new user account with profile information and initial
configuration.
**Authorization**: Requires system admin permissions.
**Validation**: Username and email must be unique across the system.
**Security**: Password is encrypted and stored securely.
operationId: createUser
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/User"
responses:
"200":
description: User created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/User"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
User:
type: object
description: Represents a user account with profile information and tutorial status
properties:
userName:
type: string
format: email
description: The user's username — an email address used for authentication.
Matches the path-parameter form on /users/{userName}. (Previously
$ref'd IdentifierPattern, which disallowed '@' and '.'; that was
never enforced at runtime so production data is all emails.)
password:
type: string
description: User's password (only included in create/update requests, never in
responses)
writeOnly: true
email:
type: string
description: User's email address, used for authentication and notifications
format: email
firstName:
type: string
maxLength: 64
description: |
User's first name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
lastName:
type: string
maxLength: 64
description: |
User's last name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
businessRole:
type: string
description: User's business role or job title
tutorialStatus:
$ref: "#/components/schemas/TutorialStatus"
TutorialStatus:
type: object
description: Represents the tutorial completion status and user preferences for
onboarding
properties:
environmentTutorial:
$ref: "#/components/schemas/EnvironmentTutorial"
EnvironmentTutorial:
type: object
description: Represents environment tutorial completion status and user preferences
properties:
hasClickedCreateModel:
type: boolean
description: Whether the user has clicked the create model button during tutorial
default: false
doNotShowModelIntro:
type: boolean
description: Whether to skip showing the model introduction tutorial
default: false
doNotShowSchemaExplorerTip:
type: boolean
description: Whether to skip showing the schema explorer tip
default: false
doNotShowTutorialInHomePanel:
type: boolean
description: Whether to skip showing tutorial content in the home panel
default: false
doNotShowConnectionOnboarding:
type: boolean
description: Whether to skip the connection-page getting-started onboarding modal
default: false
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete user account
Source: https://www.credibledata.com/docs/admin-api-reference/users/delete-user-account
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /users/{userName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/users/{userName}:
delete:
tags:
- users
summary: Delete user account
description: >
Permanently deletes a user account and removes all associated data.
This operation is irreversible.
**Authorization**: Requires system admin permissions.
**Warning**: This operation will remove all user data and permissions.
**Side Effects**: Removes user from all groups and revokes all
permissions.
operationId: deleteUser
parameters:
- name: userName
in: path
required: true
description: The unique identifier of the user
schema:
$ref: "#/components/schemas/EmailLikePattern"
responses:
"200":
description: User deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
EmailLikePattern:
type: string
pattern: ^[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}$
description: Valid email address pattern
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get user details
Source: https://www.credibledata.com/docs/admin-api-reference/users/get-user-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /users/{userName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/users/{userName}:
get:
tags:
- users
summary: Get user details
description: >
Retrieves detailed information about a specific user including profile
data,
tutorial status, and account configuration.
**Authorization**: Requires read access to user information.
**Security**: Password is never included in responses.
operationId: getUser
parameters:
- name: userName
in: path
required: true
description: The unique identifier of the user
schema:
$ref: "#/components/schemas/EmailLikePattern"
responses:
"200":
description: User details retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/User"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
EmailLikePattern:
type: string
pattern: ^[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}$
description: Valid email address pattern
User:
type: object
description: Represents a user account with profile information and tutorial status
properties:
userName:
type: string
format: email
description: The user's username — an email address used for authentication.
Matches the path-parameter form on /users/{userName}. (Previously
$ref'd IdentifierPattern, which disallowed '@' and '.'; that was
never enforced at runtime so production data is all emails.)
password:
type: string
description: User's password (only included in create/update requests, never in
responses)
writeOnly: true
email:
type: string
description: User's email address, used for authentication and notifications
format: email
firstName:
type: string
maxLength: 64
description: |
User's first name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
lastName:
type: string
maxLength: 64
description: |
User's last name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
businessRole:
type: string
description: User's business role or job title
tutorialStatus:
$ref: "#/components/schemas/TutorialStatus"
TutorialStatus:
type: object
description: Represents the tutorial completion status and user preferences for
onboarding
properties:
environmentTutorial:
$ref: "#/components/schemas/EnvironmentTutorial"
EnvironmentTutorial:
type: object
description: Represents environment tutorial completion status and user preferences
properties:
hasClickedCreateModel:
type: boolean
description: Whether the user has clicked the create model button during tutorial
default: false
doNotShowModelIntro:
type: boolean
description: Whether to skip showing the model introduction tutorial
default: false
doNotShowSchemaExplorerTip:
type: boolean
description: Whether to skip showing the schema explorer tip
default: false
doNotShowTutorialInHomePanel:
type: boolean
description: Whether to skip showing tutorial content in the home panel
default: false
doNotShowConnectionOnboarding:
type: boolean
description: Whether to skip the connection-page getting-started onboarding modal
default: false
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update user account
Source: https://www.credibledata.com/docs/admin-api-reference/users/update-user-account
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /users/{userName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/users/{userName}:
patch:
tags:
- users
summary: Update user account
description: >
Updates user profile information, tutorial status, and account
configuration.
**Authorization**: Requires user admin permissions or self-update
access.
**Security**: Password updates are handled securely with encryption.
operationId: updateUser
parameters:
- name: userName
in: path
required: true
description: The unique identifier of the user
schema:
$ref: "#/components/schemas/EmailLikePattern"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/User"
responses:
"200":
description: User updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/User"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
EmailLikePattern:
type: string
pattern: ^[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}$
description: Valid email address pattern
User:
type: object
description: Represents a user account with profile information and tutorial status
properties:
userName:
type: string
format: email
description: The user's username — an email address used for authentication.
Matches the path-parameter form on /users/{userName}. (Previously
$ref'd IdentifierPattern, which disallowed '@' and '.'; that was
never enforced at runtime so production data is all emails.)
password:
type: string
description: User's password (only included in create/update requests, never in
responses)
writeOnly: true
email:
type: string
description: User's email address, used for authentication and notifications
format: email
firstName:
type: string
maxLength: 64
description: |
User's first name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
lastName:
type: string
maxLength: 64
description: |
User's last name. May be empty when the row was auto-created
(e.g. Auth0 ensure-user path) before the user filled in their
profile — UI flows that capture a name should PATCH this in.
businessRole:
type: string
description: User's business role or job title
tutorialStatus:
$ref: "#/components/schemas/TutorialStatus"
TutorialStatus:
type: object
description: Represents the tutorial completion status and user preferences for
onboarding
properties:
environmentTutorial:
$ref: "#/components/schemas/EnvironmentTutorial"
EnvironmentTutorial:
type: object
description: Represents environment tutorial completion status and user preferences
properties:
hasClickedCreateModel:
type: boolean
description: Whether the user has clicked the create model button during tutorial
default: false
doNotShowModelIntro:
type: boolean
description: Whether to skip showing the model introduction tutorial
default: false
doNotShowSchemaExplorerTip:
type: boolean
description: Whether to skip showing the schema explorer tip
default: false
doNotShowTutorialInHomePanel:
type: boolean
description: Whether to skip showing tutorial content in the home panel
default: false
doNotShowConnectionOnboarding:
type: boolean
description: Whether to skip the connection-page getting-started onboarding modal
default: false
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get version details
Source: https://www.credibledata.com/docs/admin-api-reference/versions/get-version-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}:
get:
tags:
- versions
summary: Get version details
description: >
Retrieves detailed information about a specific package version
including metadata,
archive status, and creation details.
**Authorization**: Requires read access to the package.
**Response**: Returns complete version object with all metadata.
operationId: getVersion
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: path
required: true
description: The unique identifier of the version
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: Version details retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Version"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Version:
type: object
description: Represents a specific version of a package with metadata and
lifecycle information
properties:
id:
type: string
description: The unique version identifier, typically following semantic
versioning (e.g., 1.2.3)
$ref: "#/components/schemas/SemanticVersionPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was last modified
archiveStatus:
type: string
description: Current status of the package version, controlling its availability
enum:
- archive
- unarchive
- error_state
stale:
type: boolean
readOnly: true
description: >
True when this version serves at least one stale artifact — a
materialized source or index that is serving non-current data for
any
reason (docs/persistence.md §9.7). Display-only roll-up (the OR of
its
artifacts' `stale`); the version still serves prior values.
False/absent otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: >
The earliest fresh→stale crossover instant across the version's
stale
artifacts (§9.7 roll-up). Null when no artifact carries an age-based
crossover (or the version is fresh).
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: >
The union of the version's artifacts' staleness cause(s) (§9.7).
Empty
when fresh.
promoteWhenReady:
type: boolean
readOnly: true
description: >
Whether this version is armed for auto-promote: the
version-lifecycle
reconciler promotes it to the package's `latestVersion` once it is
ready
(fully indexed and settled into a servable resting state —
materialized,
or no persist sources / DuckDB serving live) and has never been
latest.
Read-only state set by the system at publish when the package's
`autoPromote` policy is enabled (at most one version per package is
armed
at a time); cleared once the intent resolves (after promotion, or on
terminal materialization failure).
promotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently became the package's latest. Null if
it
has never been promoted. Used as the auto-promote "never been
latest"
rollback guard.
demotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently stopped being the package's latest.
Null
while it is the current latest or has never been latest.
Auto-archive's
ttl is measured from this timestamp.
metadata:
nullable: true
$ref: "#/components/schemas/VersionIndexingMetadata"
indexingProgress:
$ref: "#/components/schemas/VersionIndexingProgress"
buildStatus:
type: string
readOnly: true
description: >
Single aggregate build status for this version, rolling up its
materialization and indexing into one lifecycle so tables and
indexes
present as one family:
- `FAILED` if either side failed.
- else `BUILDING` while either side is still working (materializing, or
indexing not yet settled).
- else `UNSUPPORTED` when the version declares persist sources whose
dialect cannot be materialized in v0 (DuckDB) — nothing is built and
those sources serve live — and indexing has settled.
- else `READY` once both sides have reached a servable resting state.
Derived read-only projection.
enum:
- BUILDING
- READY
- FAILED
- UNSUPPORTED
scope:
type: string
nullable: true
readOnly: true
description: >
The version's materialization scope mode, ingested from the package
manifest root (`Package.scope`) at materialize time:
- `version`: this version owns its materialized source tables — they
are not reused across versions. (Dimension indexes are the
exception: they remain content-addressed and may still be shared
across versions regardless of scope until per-version index
isolation lands with the index-cadence scheduler — see the note on
`Index.scope`.) A package-level `materializationSchedule` is legal
only in this mode.
- `package`: materialized source tables may be reused across the
package's own versions when fresh; cadence is freshness only (no
schedule).
Null when unknown (older versions materialized before scope was
recorded); the control plane treats null as the default (`package`).
enum:
- version
- package
materializationSchedule:
type: string
nullable: true
readOnly: true
description: >
The version's re-materialization cadence — the 5-field UNIX cron
from
the package manifest's `materialization.schedule` (e.g. `0 6 * *
*`),
ingested at materialize time. Null when the package declares no
schedule (the version materializes only on publish or on-demand
rebuild).
nextScheduledAt:
type: string
format: date-time
nullable: true
readOnly: true
description: |
When the scheduler will next re-materialize this version on its
`materializationSchedule`. Null when the version has no schedule.
lastRefreshedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When a scheduled (SCHEDULER-trigger) re-materialization of this
version
last fired. Null when the version has no schedule or has not yet
fired.
materializationFreshnessWindowSeconds:
type: integer
format: int64
nullable: true
readOnly: true
description: >
The package-level freshness window declared in the package
manifest's
`materialization.freshness.window`, parsed to seconds and ingested
write-once at materialize time. This is the refresh objective /
staleness
bound that individual sources and indexes inherit as the package
default
under most-specific-wins resolution. Null when the package declares
no
freshness window. Mutually exclusive with `materializationSchedule`:
a
version configures a schedule OR a freshness window, never both.
materializationFreshnessFallback:
type: string
nullable: true
readOnly: true
description: >
The package-level freshness fallback
(`materialization.freshness.fallback`)
— the query-time behavior when the window is missed ("live" |
"stale_ok" |
"fail"), reported verbatim from the manifest. Null when unset or no
freshness is declared.
buildPlan:
nullable: true
description: >
The persist build plan's dependency graph (DAG) for this version —
the
persist sources and their dependsOn edges. Read from the publisher's
deterministic build plan. Populated only on the single-version GET
(getVersion); null on list responses and when the version declares
no
persist source or no healthy worker can serve the plan.
$ref: "#/components/schemas/BuildPlanGraph"
SemanticVersionPattern:
type: string
pattern: ^[0-9]+\.[0-9]+\.[0-9]+(-[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?(\+[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?$
description: SemVer 2.0 version identifier. Required core MAJOR.MINOR.PATCH plus
optional pre-release suffix (e.g. `-rc1`, `-alpha.2`) and optional build
metadata (e.g. `+20231120.deadbeef`). Previously enforced strict
MAJOR.MINOR.PATCH only, which would have started 400-ing legitimate
pre-release versions (e.g. videoamp's -rc1/-rc2 RC builds) once
hibernate-validator started firing.
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
VersionIndexingMetadata:
type: object
description: Metadata from indexing failures, attached to a package version
properties:
displayErrorMessage:
type: string
description: User-friendly error message explaining why indexing failed
rawErrorMessage:
type: string
description: Detailed error message
VersionIndexingProgress:
type: object
nullable: true
description: >
Aggregate package-indexing (source-extraction) progress for a package
version, polled from the entity-indexing service while the version is
being indexed. Populated on the single-version read while indexing is in
progress (indexStatus = indexing); null once indexed/failed or when
progress is unavailable. Mirrors ConnectionIndexingProgress.
Per-dimension index progress is surfaced separately via the index-run /
dimensional-index APIs, not here.
properties:
packageProgress:
$ref: "#/components/schemas/PackageIndexingProgress"
PackageIndexingProgress:
type: object
description: Package-indexing pipeline progress (sources).
properties:
sourcesTotal:
type: integer
sourcesProcessing:
type: integer
sourcesCompleted:
type: integer
sourcesFailed:
type: integer
entitiesFound:
type: integer
nullable: true
description: Sum of compiled entities indexed over completed sources (null if no
counts recorded yet).
BuildPlanGraph:
type: object
description: >
The persist build plan's dependency graph (DAG) for a version: persist
sources
as nodes and their dependsOn relationships as edges. A deterministic
property of
the compiled package version, so identical across that version's runs.
properties:
nodes:
type: array
items:
$ref: "#/components/schemas/BuildPlanNode"
edges:
type: array
items:
$ref: "#/components/schemas/BuildPlanEdge"
BuildPlanNode:
type: object
description: One persist source in the build plan.
properties:
sourceId:
type: string
description: Stable source identifier (the publisher's sourceID).
name:
type: string
description: The persist source's name.
connectionName:
type: string
description: The connection the source materializes into.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`), for deep-linking the source
back to its model. Null when the serving worker's build plan
predates this field.
BuildPlanEdge:
type: object
description: A dependency edge — "from" must be built before "to".
properties:
from:
type: string
description: Upstream source id (a dependency).
to:
type: string
description: Downstream source id that depends on "from".
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List package versions
Source: https://www.credibledata.com/docs/admin-api-reference/versions/list-package-versions
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions:
get:
tags:
- versions
summary: List package versions
description: >
Retrieves all versions of a specific package, including version
identifiers, creation
timestamps, and archive status information.
**Authorization**: Requires read access to the package.
**Response**: Returns array of version objects ordered by creation date.
operationId: listVersions
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: List of versions retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Version"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Version:
type: object
description: Represents a specific version of a package with metadata and
lifecycle information
properties:
id:
type: string
description: The unique version identifier, typically following semantic
versioning (e.g., 1.2.3)
$ref: "#/components/schemas/SemanticVersionPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was last modified
archiveStatus:
type: string
description: Current status of the package version, controlling its availability
enum:
- archive
- unarchive
- error_state
stale:
type: boolean
readOnly: true
description: >
True when this version serves at least one stale artifact — a
materialized source or index that is serving non-current data for
any
reason (docs/persistence.md §9.7). Display-only roll-up (the OR of
its
artifacts' `stale`); the version still serves prior values.
False/absent otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: >
The earliest fresh→stale crossover instant across the version's
stale
artifacts (§9.7 roll-up). Null when no artifact carries an age-based
crossover (or the version is fresh).
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: >
The union of the version's artifacts' staleness cause(s) (§9.7).
Empty
when fresh.
promoteWhenReady:
type: boolean
readOnly: true
description: >
Whether this version is armed for auto-promote: the
version-lifecycle
reconciler promotes it to the package's `latestVersion` once it is
ready
(fully indexed and settled into a servable resting state —
materialized,
or no persist sources / DuckDB serving live) and has never been
latest.
Read-only state set by the system at publish when the package's
`autoPromote` policy is enabled (at most one version per package is
armed
at a time); cleared once the intent resolves (after promotion, or on
terminal materialization failure).
promotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently became the package's latest. Null if
it
has never been promoted. Used as the auto-promote "never been
latest"
rollback guard.
demotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently stopped being the package's latest.
Null
while it is the current latest or has never been latest.
Auto-archive's
ttl is measured from this timestamp.
metadata:
nullable: true
$ref: "#/components/schemas/VersionIndexingMetadata"
indexingProgress:
$ref: "#/components/schemas/VersionIndexingProgress"
buildStatus:
type: string
readOnly: true
description: >
Single aggregate build status for this version, rolling up its
materialization and indexing into one lifecycle so tables and
indexes
present as one family:
- `FAILED` if either side failed.
- else `BUILDING` while either side is still working (materializing, or
indexing not yet settled).
- else `UNSUPPORTED` when the version declares persist sources whose
dialect cannot be materialized in v0 (DuckDB) — nothing is built and
those sources serve live — and indexing has settled.
- else `READY` once both sides have reached a servable resting state.
Derived read-only projection.
enum:
- BUILDING
- READY
- FAILED
- UNSUPPORTED
scope:
type: string
nullable: true
readOnly: true
description: >
The version's materialization scope mode, ingested from the package
manifest root (`Package.scope`) at materialize time:
- `version`: this version owns its materialized source tables — they
are not reused across versions. (Dimension indexes are the
exception: they remain content-addressed and may still be shared
across versions regardless of scope until per-version index
isolation lands with the index-cadence scheduler — see the note on
`Index.scope`.) A package-level `materializationSchedule` is legal
only in this mode.
- `package`: materialized source tables may be reused across the
package's own versions when fresh; cadence is freshness only (no
schedule).
Null when unknown (older versions materialized before scope was
recorded); the control plane treats null as the default (`package`).
enum:
- version
- package
materializationSchedule:
type: string
nullable: true
readOnly: true
description: >
The version's re-materialization cadence — the 5-field UNIX cron
from
the package manifest's `materialization.schedule` (e.g. `0 6 * *
*`),
ingested at materialize time. Null when the package declares no
schedule (the version materializes only on publish or on-demand
rebuild).
nextScheduledAt:
type: string
format: date-time
nullable: true
readOnly: true
description: |
When the scheduler will next re-materialize this version on its
`materializationSchedule`. Null when the version has no schedule.
lastRefreshedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When a scheduled (SCHEDULER-trigger) re-materialization of this
version
last fired. Null when the version has no schedule or has not yet
fired.
materializationFreshnessWindowSeconds:
type: integer
format: int64
nullable: true
readOnly: true
description: >
The package-level freshness window declared in the package
manifest's
`materialization.freshness.window`, parsed to seconds and ingested
write-once at materialize time. This is the refresh objective /
staleness
bound that individual sources and indexes inherit as the package
default
under most-specific-wins resolution. Null when the package declares
no
freshness window. Mutually exclusive with `materializationSchedule`:
a
version configures a schedule OR a freshness window, never both.
materializationFreshnessFallback:
type: string
nullable: true
readOnly: true
description: >
The package-level freshness fallback
(`materialization.freshness.fallback`)
— the query-time behavior when the window is missed ("live" |
"stale_ok" |
"fail"), reported verbatim from the manifest. Null when unset or no
freshness is declared.
buildPlan:
nullable: true
description: >
The persist build plan's dependency graph (DAG) for this version —
the
persist sources and their dependsOn edges. Read from the publisher's
deterministic build plan. Populated only on the single-version GET
(getVersion); null on list responses and when the version declares
no
persist source or no healthy worker can serve the plan.
$ref: "#/components/schemas/BuildPlanGraph"
SemanticVersionPattern:
type: string
pattern: ^[0-9]+\.[0-9]+\.[0-9]+(-[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?(\+[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?$
description: SemVer 2.0 version identifier. Required core MAJOR.MINOR.PATCH plus
optional pre-release suffix (e.g. `-rc1`, `-alpha.2`) and optional build
metadata (e.g. `+20231120.deadbeef`). Previously enforced strict
MAJOR.MINOR.PATCH only, which would have started 400-ing legitimate
pre-release versions (e.g. videoamp's -rc1/-rc2 RC builds) once
hibernate-validator started firing.
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
VersionIndexingMetadata:
type: object
description: Metadata from indexing failures, attached to a package version
properties:
displayErrorMessage:
type: string
description: User-friendly error message explaining why indexing failed
rawErrorMessage:
type: string
description: Detailed error message
VersionIndexingProgress:
type: object
nullable: true
description: >
Aggregate package-indexing (source-extraction) progress for a package
version, polled from the entity-indexing service while the version is
being indexed. Populated on the single-version read while indexing is in
progress (indexStatus = indexing); null once indexed/failed or when
progress is unavailable. Mirrors ConnectionIndexingProgress.
Per-dimension index progress is surfaced separately via the index-run /
dimensional-index APIs, not here.
properties:
packageProgress:
$ref: "#/components/schemas/PackageIndexingProgress"
PackageIndexingProgress:
type: object
description: Package-indexing pipeline progress (sources).
properties:
sourcesTotal:
type: integer
sourcesProcessing:
type: integer
sourcesCompleted:
type: integer
sourcesFailed:
type: integer
entitiesFound:
type: integer
nullable: true
description: Sum of compiled entities indexed over completed sources (null if no
counts recorded yet).
BuildPlanGraph:
type: object
description: >
The persist build plan's dependency graph (DAG) for a version: persist
sources
as nodes and their dependsOn relationships as edges. A deterministic
property of
the compiled package version, so identical across that version's runs.
properties:
nodes:
type: array
items:
$ref: "#/components/schemas/BuildPlanNode"
edges:
type: array
items:
$ref: "#/components/schemas/BuildPlanEdge"
BuildPlanNode:
type: object
description: One persist source in the build plan.
properties:
sourceId:
type: string
description: Stable source identifier (the publisher's sourceID).
name:
type: string
description: The persist source's name.
connectionName:
type: string
description: The connection the source materializes into.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`), for deep-linking the source
back to its model. Null when the serving worker's build plan
predates this field.
BuildPlanEdge:
type: object
description: A dependency edge — "from" must be built before "to".
properties:
from:
type: string
description: Upstream source id (a dependency).
to:
type: string
description: Downstream source id that depends on "from".
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update version status
Source: https://www.credibledata.com/docs/admin-api-reference/versions/update-version-status
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/environments/{environmentName}/packages/{packageName}/versions/{versionId}:
patch:
tags:
- versions
summary: Update version status
description: >
Updates the status of a specific package version, typically used for
archiving or
unarchiving versions to control their availability.
**Authorization**: Requires package admin or modeler permissions.
**Operations**: Supports archiving and unarchiving version status
changes.
operationId: updateVersion
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: environmentName
in: path
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: path
required: true
description: The unique identifier of the version
schema:
$ref: "#/components/schemas/VersionIdPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Version"
responses:
"200":
description: Version updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Version"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Version:
type: object
description: Represents a specific version of a package with metadata and
lifecycle information
properties:
id:
type: string
description: The unique version identifier, typically following semantic
versioning (e.g., 1.2.3)
$ref: "#/components/schemas/SemanticVersionPattern"
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when this version was last modified
archiveStatus:
type: string
description: Current status of the package version, controlling its availability
enum:
- archive
- unarchive
- error_state
stale:
type: boolean
readOnly: true
description: >
True when this version serves at least one stale artifact — a
materialized source or index that is serving non-current data for
any
reason (docs/persistence.md §9.7). Display-only roll-up (the OR of
its
artifacts' `stale`); the version still serves prior values.
False/absent otherwise.
staleSince:
type: string
format: date-time
nullable: true
readOnly: true
description: >
The earliest fresh→stale crossover instant across the version's
stale
artifacts (§9.7 roll-up). Null when no artifact carries an age-based
crossover (or the version is fresh).
staleReasons:
type: array
readOnly: true
items:
$ref: "#/components/schemas/StalenessReason"
description: >
The union of the version's artifacts' staleness cause(s) (§9.7).
Empty
when fresh.
promoteWhenReady:
type: boolean
readOnly: true
description: >
Whether this version is armed for auto-promote: the
version-lifecycle
reconciler promotes it to the package's `latestVersion` once it is
ready
(fully indexed and settled into a servable resting state —
materialized,
or no persist sources / DuckDB serving live) and has never been
latest.
Read-only state set by the system at publish when the package's
`autoPromote` policy is enabled (at most one version per package is
armed
at a time); cleared once the intent resolves (after promotion, or on
terminal materialization failure).
promotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently became the package's latest. Null if
it
has never been promoted. Used as the auto-promote "never been
latest"
rollback guard.
demotedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When this version most recently stopped being the package's latest.
Null
while it is the current latest or has never been latest.
Auto-archive's
ttl is measured from this timestamp.
metadata:
nullable: true
$ref: "#/components/schemas/VersionIndexingMetadata"
indexingProgress:
$ref: "#/components/schemas/VersionIndexingProgress"
buildStatus:
type: string
readOnly: true
description: >
Single aggregate build status for this version, rolling up its
materialization and indexing into one lifecycle so tables and
indexes
present as one family:
- `FAILED` if either side failed.
- else `BUILDING` while either side is still working (materializing, or
indexing not yet settled).
- else `UNSUPPORTED` when the version declares persist sources whose
dialect cannot be materialized in v0 (DuckDB) — nothing is built and
those sources serve live — and indexing has settled.
- else `READY` once both sides have reached a servable resting state.
Derived read-only projection.
enum:
- BUILDING
- READY
- FAILED
- UNSUPPORTED
scope:
type: string
nullable: true
readOnly: true
description: >
The version's materialization scope mode, ingested from the package
manifest root (`Package.scope`) at materialize time:
- `version`: this version owns its materialized source tables — they
are not reused across versions. (Dimension indexes are the
exception: they remain content-addressed and may still be shared
across versions regardless of scope until per-version index
isolation lands with the index-cadence scheduler — see the note on
`Index.scope`.) A package-level `materializationSchedule` is legal
only in this mode.
- `package`: materialized source tables may be reused across the
package's own versions when fresh; cadence is freshness only (no
schedule).
Null when unknown (older versions materialized before scope was
recorded); the control plane treats null as the default (`package`).
enum:
- version
- package
materializationSchedule:
type: string
nullable: true
readOnly: true
description: >
The version's re-materialization cadence — the 5-field UNIX cron
from
the package manifest's `materialization.schedule` (e.g. `0 6 * *
*`),
ingested at materialize time. Null when the package declares no
schedule (the version materializes only on publish or on-demand
rebuild).
nextScheduledAt:
type: string
format: date-time
nullable: true
readOnly: true
description: |
When the scheduler will next re-materialize this version on its
`materializationSchedule`. Null when the version has no schedule.
lastRefreshedAt:
type: string
format: date-time
nullable: true
readOnly: true
description: >
When a scheduled (SCHEDULER-trigger) re-materialization of this
version
last fired. Null when the version has no schedule or has not yet
fired.
materializationFreshnessWindowSeconds:
type: integer
format: int64
nullable: true
readOnly: true
description: >
The package-level freshness window declared in the package
manifest's
`materialization.freshness.window`, parsed to seconds and ingested
write-once at materialize time. This is the refresh objective /
staleness
bound that individual sources and indexes inherit as the package
default
under most-specific-wins resolution. Null when the package declares
no
freshness window. Mutually exclusive with `materializationSchedule`:
a
version configures a schedule OR a freshness window, never both.
materializationFreshnessFallback:
type: string
nullable: true
readOnly: true
description: >
The package-level freshness fallback
(`materialization.freshness.fallback`)
— the query-time behavior when the window is missed ("live" |
"stale_ok" |
"fail"), reported verbatim from the manifest. Null when unset or no
freshness is declared.
buildPlan:
nullable: true
description: >
The persist build plan's dependency graph (DAG) for this version —
the
persist sources and their dependsOn edges. Read from the publisher's
deterministic build plan. Populated only on the single-version GET
(getVersion); null on list responses and when the version declares
no
persist source or no healthy worker can serve the plan.
$ref: "#/components/schemas/BuildPlanGraph"
SemanticVersionPattern:
type: string
pattern: ^[0-9]+\.[0-9]+\.[0-9]+(-[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?(\+[0-9A-Za-z-]+(\.[0-9A-Za-z-]+)*)?$
description: SemVer 2.0 version identifier. Required core MAJOR.MINOR.PATCH plus
optional pre-release suffix (e.g. `-rc1`, `-alpha.2`) and optional build
metadata (e.g. `+20231120.deadbeef`). Previously enforced strict
MAJOR.MINOR.PATCH only, which would have started 400-ing legitimate
pre-release versions (e.g. videoamp's -rc1/-rc2 RC builds) once
hibernate-validator started firing.
StalenessReason:
type: string
description: >
Machine-readable cause for an artifact's staleness (docs/persistence.md
§9.7 — one indicator, orthogonal reasons). Split into GATING reasons
(their presence sets `stale=true`) and ANNOTATION reasons (they explain
why an already-stale artifact keeps aging, never flip it on their own):
* `FRESHNESS_WINDOW_EXCEEDED` (gating) — data age passed the declared
`freshness.window` (§9.3 tables, §9.5 indexes).
* `SOURCE_BUILD_FAILED` (gating) — serving prior values because this
version's source materialization FAILED (the reused-over-failed case,
generalized; symmetric for a source whose latest rebuild failed while
a prior generation still serves).
* `REFRESH_IN_PROGRESS` (annotation) — a scheduled refresh has fired but
no fresher generation has landed yet (self-heals).
* `LAST_REFRESH_FAILED` (annotation) — the refresh stream was disarmed
after repeated fires without landing a fresher generation.
* `WINDOW_BELOW_BUILD_TIME` (annotation) — the declared freshness window
is shorter than the estimated build duration, so the objective is
physically unachievable (the rebuild cannot complete inside the
window). The window needs widening, or what it covers reducing.
enum:
- FRESHNESS_WINDOW_EXCEEDED
- SOURCE_BUILD_FAILED
- REFRESH_IN_PROGRESS
- LAST_REFRESH_FAILED
- WINDOW_BELOW_BUILD_TIME
VersionIndexingMetadata:
type: object
description: Metadata from indexing failures, attached to a package version
properties:
displayErrorMessage:
type: string
description: User-friendly error message explaining why indexing failed
rawErrorMessage:
type: string
description: Detailed error message
VersionIndexingProgress:
type: object
nullable: true
description: >
Aggregate package-indexing (source-extraction) progress for a package
version, polled from the entity-indexing service while the version is
being indexed. Populated on the single-version read while indexing is in
progress (indexStatus = indexing); null once indexed/failed or when
progress is unavailable. Mirrors ConnectionIndexingProgress.
Per-dimension index progress is surfaced separately via the index-run /
dimensional-index APIs, not here.
properties:
packageProgress:
$ref: "#/components/schemas/PackageIndexingProgress"
PackageIndexingProgress:
type: object
description: Package-indexing pipeline progress (sources).
properties:
sourcesTotal:
type: integer
sourcesProcessing:
type: integer
sourcesCompleted:
type: integer
sourcesFailed:
type: integer
entitiesFound:
type: integer
nullable: true
description: Sum of compiled entities indexed over completed sources (null if no
counts recorded yet).
BuildPlanGraph:
type: object
description: >
The persist build plan's dependency graph (DAG) for a version: persist
sources
as nodes and their dependsOn relationships as edges. A deterministic
property of
the compiled package version, so identical across that version's runs.
properties:
nodes:
type: array
items:
$ref: "#/components/schemas/BuildPlanNode"
edges:
type: array
items:
$ref: "#/components/schemas/BuildPlanEdge"
BuildPlanNode:
type: object
description: One persist source in the build plan.
properties:
sourceId:
type: string
description: Stable source identifier (the publisher's sourceID).
name:
type: string
description: The persist source's name.
connectionName:
type: string
description: The connection the source materializes into.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`), for deep-linking the source
back to its model. Null when the serving worker's build plan
predates this field.
BuildPlanEdge:
type: object
description: A dependency edge — "from" must be built before "to".
properties:
from:
type: string
description: Upstream source id (a dependency).
to:
type: string
description: Downstream source id that depends on "from".
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Adds package access to a workspace
Source: https://www.credibledata.com/docs/admin-api-reference/workspacepermissions/adds-package-access-to-a-workspace
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/workspaces/{workspaceName}/packages
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/packages:
post:
tags:
- workspacePermissions
summary: Adds package access to a workspace
operationId: createWorkspacePackagePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: environmentName
in: query
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: query
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Workspace package permission created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Workspace"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
Workspace:
type: object
description: Represents a collaborative workspace for team-based data modeling
and analysis
properties:
name:
type: string
description: The unique name of the workspace within its organization
$ref: "#/components/schemas/WorkspaceNamePattern"
description:
type: string
groupName:
type: string
nullable: true
description: Human-readable description of the workspace's purpose and scope
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was last modified
packages:
type: array
description: Array of package resource identifiers that are accessible in this
workspace
items:
type: string
$ref: "#/components/schemas/PathPattern"
workspaceType:
type: string
description: The type of workspace. PersonalInfra for personal workspaces, Group
for shared workspaces.
enum:
- PersonalInfra
- Group
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create workspace permission
Source: https://www.credibledata.com/docs/admin-api-reference/workspacepermissions/create-workspace-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/workspaces/{workspaceName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/permissions:
post:
tags:
- workspacePermissions
summary: Create workspace permission
description: >
Creates a new permission assignment for a user or group within the
workspace,
granting them specific roles and access levels. Can also be used to
request access
to the workspace when the user doesn't have manager permissions.
**Authorization**: Requires workspace manager permissions, unless
`requestPermission` is true.
**Parameters**: Use `requestPermission` to indicate the user is
requesting access to the resource.
**Roles**: Supports manager and viewer roles.
operationId: createWorkspacePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: requestPermission
in: query
required: false
description: Indicates that the user is requesting access to the resource
schema:
type: boolean
default: false
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/WorkspacePermission"
responses:
"200":
description: Workspace permission created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/WorkspacePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
WorkspacePermission:
type: object
description: Represents a permission assignment for a user or group within a workspace
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete workspace permission
Source: https://www.credibledata.com/docs/admin-api-reference/workspacepermissions/delete-workspace-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/workspaces/{workspaceName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/permissions/{userGroupId}:
delete:
tags:
- workspacePermissions
summary: Delete workspace permission
description: >
Removes the permission assignment for a user or group within the
workspace,
revoking their access to workspace resources.
**Authorization**: Requires workspace manager permissions.
**Side Effects**: User/group loses access to workspace resources.
operationId: deleteWorkspacePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Workspace permission deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get workspace permission
Source: https://www.credibledata.com/docs/admin-api-reference/workspacepermissions/get-workspace-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/{workspaceName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/permissions/{userGroupId}:
get:
tags:
- workspacePermissions
summary: Get workspace permission
description: >
Retrieves the permission details for a specific user or group within the
workspace,
including their role and access level.
**Authorization**: Requires workspace manager permissions.
**Response**: Returns permission object with role and metadata.
operationId: getWorkspacePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
responses:
"200":
description: Workspace permission retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/WorkspacePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
WorkspacePermission:
type: object
description: Represents a permission assignment for a user or group within a workspace
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List workspace permissions
Source: https://www.credibledata.com/docs/admin-api-reference/workspacepermissions/list-workspace-permissions
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/{workspaceName}/permissions
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/permissions:
get:
tags:
- workspacePermissions
summary: List workspace permissions
description: >
Retrieves all permission assignments for the specified workspace,
including user and group
permissions with their roles and access levels.
**Authorization**: Requires workspace membership (manager or viewer) or
organization admin.
Mirrors FGA `can_read_group` on the workspace's underlying group, which
resolves to
`all_member or org_admin`.
**Response**: Returns array of permission objects with user/group
identifiers and roles.
operationId: listWorkspacePermissions
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
responses:
"200":
description: List of workspace permissions retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/WorkspacePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
WorkspacePermission:
type: object
description: Represents a permission assignment for a user or group within a workspace
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Removes package access from a workspace
Source: https://www.credibledata.com/docs/admin-api-reference/workspacepermissions/removes-package-access-from-a-workspace
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/workspaces/{workspaceName}/packages
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/packages:
delete:
tags:
- workspacePermissions
summary: Removes package access from a workspace
operationId: removeWorkspacePackagePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: environmentName
in: query
required: true
description: The unique identifier of the environment
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: query
required: true
description: The unique identifier of the package
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Workspace package permission removed successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Workspace"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
Workspace:
type: object
description: Represents a collaborative workspace for team-based data modeling
and analysis
properties:
name:
type: string
description: The unique name of the workspace within its organization
$ref: "#/components/schemas/WorkspaceNamePattern"
description:
type: string
groupName:
type: string
nullable: true
description: Human-readable description of the workspace's purpose and scope
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was last modified
packages:
type: array
description: Array of package resource identifiers that are accessible in this
workspace
items:
type: string
$ref: "#/components/schemas/PathPattern"
workspaceType:
type: string
description: The type of workspace. PersonalInfra for personal workspaces, Group
for shared workspaces.
enum:
- PersonalInfra
- Group
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update workspace permission
Source: https://www.credibledata.com/docs/admin-api-reference/workspacepermissions/update-workspace-permission
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/workspaces/{workspaceName}/permissions/{userGroupId}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}/permissions/{userGroupId}:
patch:
tags:
- workspacePermissions
summary: Update workspace permission
description: >
Updates the permission assignment for a user or group within the
workspace,
modifying their role and access level.
**Authorization**: Requires workspace manager permissions.
**Validation**: Role changes are validated against workspace
constraints.
operationId: updateWorkspacePermission
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: userGroupId
in: path
required: true
description: The unique identifier of the user or group
schema:
$ref: "#/components/schemas/UserGroupId"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/WorkspacePermission"
responses:
"200":
description: Workspace permission updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/WorkspacePermission"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
UserGroupId:
type: string
description: >
A resource identifier that uniquely identifies either a user or a group
within the system.
This identifier is used throughout the API for permission management and
access control.
**Format**:
- For users: `user:{email}` or `user:{userId}`
- For groups: `group:{groupName}`
$ref: "#/components/schemas/UserGroupIdPattern"
UserGroupIdPattern:
type: string
pattern: ^(user:[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}|group:[a-zA-Z0-9._-]+)$
description: User or group identifier pattern (user must be valid email address,
group is standard identifier)
WorkspacePermission:
type: object
description: Represents a permission assignment for a user or group within a workspace
properties:
userGroupId:
$ref: "#/components/schemas/UserGroupId"
permission:
type: string
description: The role/permission level granted to the user or group
enum:
- manager
- viewer
message:
type: string
description: Optional message or note about the permission assignment
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the permission was last modified
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a new workspace
Source: https://www.credibledata.com/docs/admin-api-reference/workspaces/create-a-new-workspace
## OpenAPI
````yaml /docs/api-specs/admin.yaml post /organizations/{organizationName}/workspaces
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces:
post:
tags:
- workspaces
summary: Create a new workspace
description: >
Creates a new collaborative workspace within the organization for
team-based data
modeling and analysis activities.
**Authorization**: Requires organization admin permissions.
**Features**: Workspaces support document management and package access
control.
operationId: createWorkspace
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/Workspace"
responses:
"200":
description: Workspace created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Workspace"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Workspace:
type: object
description: Represents a collaborative workspace for team-based data modeling
and analysis
properties:
name:
type: string
description: The unique name of the workspace within its organization
$ref: "#/components/schemas/WorkspaceNamePattern"
description:
type: string
groupName:
type: string
nullable: true
description: Human-readable description of the workspace's purpose and scope
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was last modified
packages:
type: array
description: Array of package resource identifiers that are accessible in this
workspace
items:
type: string
$ref: "#/components/schemas/PathPattern"
workspaceType:
type: string
description: The type of workspace. PersonalInfra for personal workspaces, Group
for shared workspaces.
enum:
- PersonalInfra
- Group
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete workspace
Source: https://www.credibledata.com/docs/admin-api-reference/workspaces/delete-workspace
## OpenAPI
````yaml /docs/api-specs/admin.yaml delete /organizations/{organizationName}/workspaces/{workspaceName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}:
delete:
tags:
- workspaces
summary: Delete workspace
description: >
Permanently deletes a workspace and all its associated data, including
packages,
permissions, and configuration. This action cannot be undone.
operationId: deleteWorkspace
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
responses:
"200":
description: Workspace deleted successfully
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get or create personal workspace
Source: https://www.credibledata.com/docs/admin-api-reference/workspaces/get-or-create-personal-workspace
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/personal
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/personal:
get:
tags:
- workspaces
summary: Get or create personal workspace
description: >
Gets or creates a personal workspace for the current user. This
workspace is
private and only the user has permissions to read and write documents in
it.
**Authorization**: Requires only organization member permissions. The
user does not
need 'can_create_workspace' permission as personal workspaces are
automatically provisioned.
**Features**: Personal workspace for storing user-specific documents
like chat histories.
operationId: getOrCreatePersonalWorkspace
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Personal workspace retrieved or created successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Workspace"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Workspace:
type: object
description: Represents a collaborative workspace for team-based data modeling
and analysis
properties:
name:
type: string
description: The unique name of the workspace within its organization
$ref: "#/components/schemas/WorkspaceNamePattern"
description:
type: string
groupName:
type: string
nullable: true
description: Human-readable description of the workspace's purpose and scope
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was last modified
packages:
type: array
description: Array of package resource identifiers that are accessible in this
workspace
items:
type: string
$ref: "#/components/schemas/PathPattern"
workspaceType:
type: string
description: The type of workspace. PersonalInfra for personal workspaces, Group
for shared workspaces.
enum:
- PersonalInfra
- Group
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get workspace details
Source: https://www.credibledata.com/docs/admin-api-reference/workspaces/get-workspace-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces/{workspaceName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}:
get:
tags:
- workspaces
summary: Get workspace details
description: >
Retrieves detailed information about a specific workspace, including its
metadata,
associated packages, and configuration settings.
operationId: getWorkspace
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
- name: checkAdmin
in: query
required: false
description: Whether to verify admin privileges for the resource
schema:
type: boolean
default: false
responses:
"200":
description: Workspace details retrieved successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Workspace"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
Workspace:
type: object
description: Represents a collaborative workspace for team-based data modeling
and analysis
properties:
name:
type: string
description: The unique name of the workspace within its organization
$ref: "#/components/schemas/WorkspaceNamePattern"
description:
type: string
groupName:
type: string
nullable: true
description: Human-readable description of the workspace's purpose and scope
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was last modified
packages:
type: array
description: Array of package resource identifiers that are accessible in this
workspace
items:
type: string
$ref: "#/components/schemas/PathPattern"
workspaceType:
type: string
description: The type of workspace. PersonalInfra for personal workspaces, Group
for shared workspaces.
enum:
- PersonalInfra
- Group
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List workspaces in organization
Source: https://www.credibledata.com/docs/admin-api-reference/workspaces/list-workspaces-in-organization
## OpenAPI
````yaml /docs/api-specs/admin.yaml get /organizations/{organizationName}/workspaces
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces:
get:
tags:
- workspaces
summary: List workspaces in organization
description: >
Retrieves all workspaces within the specified organization, optionally
filtered to
show only writable workspaces for the current user.
**Authorization**: Requires read access to the organization.
**Filtering**: Use `onlyWritable` parameter to filter for workspaces
with write access.
operationId: listWorkspaces
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: onlyWritable
in: query
required: false
description: Whether to filter for workspaces with write access only
schema:
type: boolean
default: false
responses:
"200":
description: List of workspaces retrieved successfully
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Workspace"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
Workspace:
type: object
description: Represents a collaborative workspace for team-based data modeling
and analysis
properties:
name:
type: string
description: The unique name of the workspace within its organization
$ref: "#/components/schemas/WorkspaceNamePattern"
description:
type: string
groupName:
type: string
nullable: true
description: Human-readable description of the workspace's purpose and scope
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was last modified
packages:
type: array
description: Array of package resource identifiers that are accessible in this
workspace
items:
type: string
$ref: "#/components/schemas/PathPattern"
workspaceType:
type: string
description: The type of workspace. PersonalInfra for personal workspaces, Group
for shared workspaces.
enum:
- PersonalInfra
- Group
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update workspace details
Source: https://www.credibledata.com/docs/admin-api-reference/workspaces/update-workspace-details
## OpenAPI
````yaml /docs/api-specs/admin.yaml patch /organizations/{organizationName}/workspaces/{workspaceName}
openapi: 3.1.0
info:
title: Credible Admin API
description: >
The Credible Admin API is a comprehensive REST API that empowers
organizations to manage their Malloy data modeling ecosystem with
enterprise-grade security and governance. This API provides programmatic
access to all administrative functions, enabling seamless integration with
existing workflows and automation systems.
## Key Features
- **Organization Management**: Create and manage organizations with
fine-grained access controls
- **Environment & Package Lifecycle**: Full CRUD operations for
environments, packages, and versions
- **Connection Management**: Secure database connection configuration and
management
- **Permission Management**: Granular role-based access control (RBAC) at
organization, environment, package, workspace, and document levels
- **Workspace Management**: Collaborative workspaces for data modeling and
analysis
- **User & Group Management**: Comprehensive user administration with
group-based permissions
## Resource Hierarchy
The API follows a hierarchical resource structure with fine-grained
permission management at each level:
```
Organizations
├── Permissions
├── Environments
│ ├── Permissions
│ ├── Packages
│ │ ├── Permissions
│ │ └── Versions
│ └── Connections
├── Workspaces
│ ├── Permissions
│ └── Documents
│ └── Permissions
└── Groups
├── Permissions
└── Members
System-Level Resources:
├── Users
├── System Permissions
└── Demo Operations
```
## Authentication & Authorization
All API endpoints require proper authentication. The API implements
fine-grained authorization using role-based permissions:
- **Admin**: Full access to all resources within scope
- **Modeler**: Can create and modify data models and packages
- **Viewer**: Read-only access to resources
- **Manager**: Workspace management capabilities
- **Editor**: Document editing permissions
## Rate Limiting & Best Practices
- API requests are rate-limited to ensure system stability
- Implement proper error handling and retry logic
- Cache responses when appropriate to reduce API calls
## Support & Documentation
For additional support, examples, and integration guides, visit our
developer documentation or contact our support team.
version: v0
contact:
name: Credible Support
email: support@credibledata.com
url: https://credibledata.com/support
license:
name: Proprietary
url: https://credibledata.com/license
termsOfService: https://credibledata.com/terms
servers:
- url: https://{organization}.admin.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: organizations
description: Organization management operations for creating, updating, and
managing organizational entities
- name: organizationPermissions
description: Fine-grained permission management for organizations, including
role assignments and access controls
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: environmentPermissions
description: Permission management for environments, controlling access to
environment resources and capabilities
- name: packages
description: Package management for Malloy data models, including versioning,
publishing, and distribution
- name: packagePermissions
description: Access control for packages, managing who can view, modify, or
publish package versions
- name: versions
description: Version management for packages, including archiving, status
updates, and lifecycle management
- name: connections
description: Database connection management for secure data source configuration
and access
- name: materializations
description: Malloy Persistence materializations (per-version serving anchors
for persisted sources)
- name: indexes
description: Malloy Persistence dimensional search indexes (per-version serving
anchors for indexed dimensions)
- name: runs
description: Malloy Persistence build/refresh runs — one package-level build
event carrying typed units (materialized sources + built indexes)
- name: workspaces
description: Collaborative workspace management for team-based data modeling and
analysis
- name: workspacePermissions
description: Access control for workspaces, managing who can view, manage, or
collaborate in workspaces
- name: documents
description: Document management within workspaces, including workbooks,
dashboards, and other content
- name: documentPermissions
description: Access control for documents, managing who can view, edit, or share
document content
- name: groups
description: User group management for organizing users and managing group-based
permissions
- name: users
description: User account management including creation, updates, and profile management
- name: demo
description: Demo and self-service operations for quick setup and testing scenarios
- name: permissions
description: System-level permission management for administrative functions
- name: bookmarks
description: User bookmark management for saving references to workspaces,
models, and chats
- name: attributes
description: Trusted user attributes for fine-grain (row/column-level) access control
- name: invites
description: Organization-creation invite tokens. A super-admin mints tokens one
per call (call `POST /invites` repeatedly to populate an outreach
campaign); each token can be redeemed once by an authenticated user to
create a new organization on the fly.
paths:
/organizations/{organizationName}/workspaces/{workspaceName}:
patch:
tags:
- workspaces
summary: Update workspace details
description: >
Partially updates a workspace's details, including description and
configuration settings.
Only the provided fields will be updated.
**Authorization**: Requires workspace manager permissions.
**Fields**: Can update description and other workspace metadata.
operationId: updateWorkspace
parameters:
- name: organizationName
in: path
required: true
description: The unique identifier of the organization
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: workspaceName
in: path
required: true
description: The unique identifier of the workspace
schema:
$ref: "#/components/schemas/WorkspaceNamePattern"
requestBody:
required: true
content:
application/json:
schema:
type: object
description: Workspace update data
properties:
description:
type: string
description: Updated description of the workspace
additionalProperties: false
responses:
"200":
description: Workspace updated successfully
content:
application/json:
schema:
$ref: "#/components/schemas/Workspace"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"403":
$ref: "#/components/responses/Forbidden"
"404":
$ref: "#/components/responses/NotFound"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_ -]+$
description: Standard identifier pattern for resource names
WorkspaceNamePattern:
type: string
pattern: ^(?!.*\*)(?!.*[/]).{1,63}$
description: Workspace name pattern. Allows any character except `/` (would
split the FGA resource path — see ResourceIdentifier.parseFromFga) and
`*` (FGA wildcard). 1-63 chars.
Workspace:
type: object
description: Represents a collaborative workspace for team-based data modeling
and analysis
properties:
name:
type: string
description: The unique name of the workspace within its organization
$ref: "#/components/schemas/WorkspaceNamePattern"
description:
type: string
groupName:
type: string
nullable: true
description: Human-readable description of the workspace's purpose and scope
createdAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was created
updatedAt:
type: string
format: date-time
description: ISO 8601 timestamp indicating when the workspace was last modified
packages:
type: array
description: Array of package resource identifiers that are accessible in this
workspace
items:
type: string
$ref: "#/components/schemas/PathPattern"
workspaceType:
type: string
description: The type of workspace. PersonalInfra for personal workspaces, Group
for shared workspaces.
enum:
- PersonalInfra
- Group
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Error:
type: object
x-model-name: ModelError
description: Standard error response format used across all API endpoints
properties:
code:
type: string
description: >
Machine-readable error code that identifies the specific error
condition.
Clients should branch on `code`, not on the human-readable `message`
—
the message text is informational and may change over time.
Generic codes (may appear on any endpoint):
- `VALIDATION_ERROR`: Request body or path/query parameter failed
validation
- `AUTHENTICATION_REQUIRED`: Valid authentication is required
- `INSUFFICIENT_PERMISSIONS`: User lacks required permissions
- `RESOURCE_NOT_FOUND`: Requested resource does not exist
- `CONFLICT`: Generic resource state conflict (used when no more
specific code applies)
- `RATE_LIMIT_EXCEEDED`: API rate limit exceeded
- `INTERNAL_ERROR`: Unexpected server error
Endpoint-specific codes used by the signup / invites flow:
- `ORGANIZATION_NAME_TAKEN`: 409 on `POST /organizations` — the
requested
org name (URL slug) is already in use. Retry with a different name.
- `ORGANIZATION_NAME_RESERVED`: 409 on `POST /organizations` — the
requested
org name collides with a reserved subdomain (e.g. `signup`, `admin`,
`data`, `login`) and cannot be claimed. Retry with a different name.
- `INVITE_ALREADY_CONSUMED`: 409 on `POST /organizations` — the
supplied
invite token has already been redeemed into an existing organization.
Retry will not help; the token is dead.
- `INVITE_ALREADY_CONSUMED_REVOKE`: 409 on `DELETE /invites/{token}`
—
consumed invites are preserved for audit and cannot be revoked.
- `INVITE_INVALID`: 400 on `POST /organizations` — the supplied
invite
token is malformed or unknown.
- `INVITE_EXPIRED`: 400 on `POST /organizations` — the supplied
invite
token is past its `expiresAt`.
- `INVITE_EMAIL_MISMATCH`: 403 on `POST /organizations` — the invite
is
bound to a different email address than the caller.
message:
type: string
description: Human-readable error message providing details about what went wrong
responses:
BadRequest:
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Forbidden:
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get categorized skill set for a manifest
Source: https://www.credibledata.com/docs/coding-api-reference/codeassist/get-categorized-skill-set-for-a-manifest
## OpenAPI
```yaml /docs/api-specs/coding.yaml get /agent_skills
openapi: 3.0.0
info:
title: Coding API
description: Public API for Credible's Code Assist service. Its
externally-facing capability is a Malloy documentation search (`POST
/search_malloy_docs`) that any authenticated caller — including a customer's
own MCP server — can invoke directly with a Group Access Token. The
remaining endpoints back the Credible VS Code extension and are not part of
the external integration surface.
version: 1.0.0
servers:
- url: https://{organization}.coding.credibledata.com
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
- apiKeyAuth: []
tags:
- name: codeAssist
description: Code Assist API endpoints
paths:
/agent_skills:
get:
tags:
- codeAssist
operationId: getAgentSkills
summary: Get categorized skill set for a manifest
description: Used by the Credible VS Code extension; not part of the external
integration surface. Returns the skills referenced by a manifest in the
agent-skills repo, categorized into auto_discovered and supporting
groups. If version is omitted, the server resolves it via a Flagsmith
flag (`agent_skills_version_`) and falls back to the
latest repo tag.
parameters:
- name: manifest
in: query
required: true
description: Manifest name (e.g. "modeling-agent").
schema:
type: string
- name: version
in: query
required: false
description: Version tag. If omitted, server resolves it via Flagsmith or latest.
schema:
type: string
responses:
"200":
description: Successful response
content:
application/json:
schema:
$ref: "#/components/schemas/AgentSkillsResponse"
"400":
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"401":
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"404":
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"500":
description: An internal server error occurred.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
components:
schemas:
AgentSkillsResponse:
type: object
required:
- manifest
- version
- auto_discovered
- supporting
properties:
manifest:
type: string
description: Manifest name that was requested
version:
type: string
description: Resolved version tag served
description:
type: string
description: Human-readable description from the manifest
trigger_hint:
type: string
description: Trigger hint from the manifest for rule-file generation
auto_discovered:
type: array
items:
$ref: "#/components/schemas/AgentSkill"
description: Skills intended for auto-discovered placement (e.g. .claude/skills/)
supporting:
type: array
items:
$ref: "#/components/schemas/AgentSkill"
description: Skills intended for on-demand placement (e.g. .credible/skills/)
AgentSkill:
type: object
required:
- name
- files
properties:
name:
type: string
description: Skill name (folder name under skills/)
files:
type: array
items:
$ref: "#/components/schemas/SkillFile"
description: Files belonging to the skill
SkillFile:
type: object
required:
- relative_filepath
- file_contents
properties:
relative_filepath:
type: string
description: Relative path of the file within the skill folder
file_contents:
type: string
description: Contents of the file
ErrorResponse:
description: Standard error response body.
type: object
required:
- error_code
- message
properties:
error_code:
type: string
description: A code identifying the type of error
enum:
- INVALID_INPUT
- UNAUTHORIZED
- FORBIDDEN
- NOT_FOUND
- CONFLICT
- INTERNAL_ERROR
- BAD_GATEWAY
- GATEWAY_TIMEOUT
message:
type: string
description: A human-readable error message
details:
type: string
description: Additional error details, if available
nullable: true
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
description: |
Auth0-issued user JWT. Provide as `Authorization: Bearer `.
apiKeyAuth:
type: apiKey
in: header
name: Authorization
description: |
HMAC-signed API key JWT (Group Access Token) issued by Credible. Provide
as `Authorization: ApiKey ` (note the `ApiKey ` prefix in place
of the usual `Bearer `). Include the full string — prefix and token —
in this field.
```
---
# Get information about what extension version is supported
Source: https://www.credibledata.com/docs/coding-api-reference/codeassist/get-information-about-what-extension-version-is-supported
## OpenAPI
```yaml /docs/api-specs/coding.yaml get /extension_support
openapi: 3.0.0
info:
title: Coding API
description: Public API for Credible's Code Assist service. Its
externally-facing capability is a Malloy documentation search (`POST
/search_malloy_docs`) that any authenticated caller — including a customer's
own MCP server — can invoke directly with a Group Access Token. The
remaining endpoints back the Credible VS Code extension and are not part of
the external integration surface.
version: 1.0.0
servers:
- url: https://{organization}.coding.credibledata.com
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
- apiKeyAuth: []
tags:
- name: codeAssist
description: Code Assist API endpoints
paths:
/extension_support:
get:
tags:
- codeAssist
summary: Get information about what extension version is supported
description: Used by the Credible VS Code extension; not part of the external
integration surface. The extension calls this before authenticating to
learn the minimum supported version, so it is unauthenticated.
security: []
responses:
"200":
description: Successful response
content:
application/json:
schema:
$ref: "#/components/schemas/ExtensionSupport"
"400":
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"401":
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"403":
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"404":
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"500":
description: An internal server error occurred.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
components:
schemas:
ExtensionSupport:
description: Information about what extension version is supported
type: object
required:
- min_extension_version
properties:
min_extension_version:
description: The minimum extension version that is supported
type: string
ErrorResponse:
description: Standard error response body.
type: object
required:
- error_code
- message
properties:
error_code:
type: string
description: A code identifying the type of error
enum:
- INVALID_INPUT
- UNAUTHORIZED
- FORBIDDEN
- NOT_FOUND
- CONFLICT
- INTERNAL_ERROR
- BAD_GATEWAY
- GATEWAY_TIMEOUT
message:
type: string
description: A human-readable error message
details:
type: string
description: Additional error details, if available
nullable: true
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
description: |
Auth0-issued user JWT. Provide as `Authorization: Bearer `.
apiKeyAuth:
type: apiKey
in: header
name: Authorization
description: |
HMAC-signed API key JWT (Group Access Token) issued by Credible. Provide
as `Authorization: ApiKey ` (note the `ApiKey ` prefix in place
of the usual `Bearer `). Include the full string — prefix and token —
in this field.
```
---
# List manifests available in the agent-skills repo
Source: https://www.credibledata.com/docs/coding-api-reference/codeassist/list-manifests-available-in-the-agent-skills-repo
## OpenAPI
```yaml /docs/api-specs/coding.yaml get /agent_skills/manifests
openapi: 3.0.0
info:
title: Coding API
description: Public API for Credible's Code Assist service. Its
externally-facing capability is a Malloy documentation search (`POST
/search_malloy_docs`) that any authenticated caller — including a customer's
own MCP server — can invoke directly with a Group Access Token. The
remaining endpoints back the Credible VS Code extension and are not part of
the external integration surface.
version: 1.0.0
servers:
- url: https://{organization}.coding.credibledata.com
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
- apiKeyAuth: []
tags:
- name: codeAssist
description: Code Assist API endpoints
paths:
/agent_skills/manifests:
get:
tags:
- codeAssist
operationId: listAgentSkillsManifests
summary: List manifests available in the agent-skills repo
description: Used by the Credible VS Code extension; not part of the external
integration surface. Discovers all manifests present in the latest
version of the agent-skills repo and returns each with its resolved
(Flagsmith or latest) version.
responses:
"200":
description: Successful response
content:
application/json:
schema:
$ref: "#/components/schemas/ManifestListResponse"
"401":
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"500":
description: An internal server error occurred.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
components:
schemas:
ManifestListResponse:
type: object
required:
- manifests
properties:
manifests:
type: array
items:
$ref: "#/components/schemas/ManifestInfo"
description: Manifests discovered in the latest version of the agent-skills repo
ManifestInfo:
type: object
required:
- name
- version
properties:
name:
type: string
description: Manifest name
version:
type: string
description: Resolved version served for this manifest
ErrorResponse:
description: Standard error response body.
type: object
required:
- error_code
- message
properties:
error_code:
type: string
description: A code identifying the type of error
enum:
- INVALID_INPUT
- UNAUTHORIZED
- FORBIDDEN
- NOT_FOUND
- CONFLICT
- INTERNAL_ERROR
- BAD_GATEWAY
- GATEWAY_TIMEOUT
message:
type: string
description: A human-readable error message
details:
type: string
description: Additional error details, if available
nullable: true
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
description: |
Auth0-issued user JWT. Provide as `Authorization: Bearer `.
apiKeyAuth:
type: apiKey
in: header
name: Authorization
description: |
HMAC-signed API key JWT (Group Access Token) issued by Credible. Provide
as `Authorization: ApiKey ` (note the `ApiKey ` prefix in place
of the usual `Bearer `). Include the full string — prefix and token —
in this field.
```
---
# Search Credible documentation
Source: https://www.credibledata.com/docs/coding-api-reference/codeassist/search-credible-documentation
## OpenAPI
```yaml /docs/api-specs/coding.yaml post /search_credible_docs
openapi: 3.0.0
info:
title: Coding API
description: Public API for Credible's Code Assist service. Its
externally-facing capability is a Malloy documentation search (`POST
/search_malloy_docs`) that any authenticated caller — including a customer's
own MCP server — can invoke directly with a Group Access Token. The
remaining endpoints back the Credible VS Code extension and are not part of
the external integration surface.
version: 1.0.0
servers:
- url: https://{organization}.coding.credibledata.com
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
- apiKeyAuth: []
tags:
- name: codeAssist
description: Code Assist API endpoints
paths:
/search_credible_docs:
post:
tags:
- codeAssist
operationId: searchCredibleDocs
summary: Search Credible documentation
description: "Search Credible's documentation and return the most relevant
content as plain text. Authenticate with `Authorization: Bearer
` or `Authorization: ApiKey `."
requestBody:
required: true
content:
application/json:
schema:
type: string
description: Natural-language query about Credible.
minLength: 1
responses:
"200":
description: Successful response
content:
text/plain:
schema:
type: string
description: Relevant documentation content
"400":
description: The request was malformed or can not be performed given the state
of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"401":
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"403":
description: Can not perform the operation due to insufficient permissions or
the state of the system.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"404":
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"500":
description: An internal server error occurred.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
components:
schemas:
ErrorResponse:
description: Standard error response body.
type: object
required:
- error_code
- message
properties:
error_code:
type: string
description: A code identifying the type of error
enum:
- INVALID_INPUT
- UNAUTHORIZED
- FORBIDDEN
- NOT_FOUND
- CONFLICT
- INTERNAL_ERROR
- BAD_GATEWAY
- GATEWAY_TIMEOUT
message:
type: string
description: A human-readable error message
details:
type: string
description: Additional error details, if available
nullable: true
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
description: |
Auth0-issued user JWT. Provide as `Authorization: Bearer `.
apiKeyAuth:
type: apiKey
in: header
name: Authorization
description: |
HMAC-signed API key JWT (Group Access Token) issued by Credible. Provide
as `Authorization: ApiKey ` (note the `ApiKey ` prefix in place
of the usual `Bearer `). Include the full string — prefix and token —
in this field.
```
---
# Search Malloy documentation
Source: https://www.credibledata.com/docs/coding-api-reference/codeassist/search-malloy-documentation
## OpenAPI
```yaml /docs/api-specs/coding.yaml post /search_malloy_docs
openapi: 3.0.0
info:
title: Coding API
description: Public API for Credible's Code Assist service. Its
externally-facing capability is a Malloy documentation search (`POST
/search_malloy_docs`) that any authenticated caller — including a customer's
own MCP server — can invoke directly with a Group Access Token. The
remaining endpoints back the Credible VS Code extension and are not part of
the external integration surface.
version: 1.0.0
servers:
- url: https://{organization}.coding.credibledata.com
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
- apiKeyAuth: []
tags:
- name: codeAssist
description: Code Assist API endpoints
paths:
/search_malloy_docs:
post:
tags:
- codeAssist
operationId: searchMalloyDocs
summary: Search Malloy documentation
description: "Search Credible's packaged Malloy documentation and return a
synthesized answer with relevant passages and code snippets. The corpus
is global and the same for every caller — no organization/workspace
context is used. Authenticate with `Authorization: Bearer `
or `Authorization: ApiKey `. A per-IP rate limit may
reject sustained excess traffic with `429` when enforcement is enabled."
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/SearchMalloyDocsRequest"
responses:
"200":
description: Successful response
content:
application/json:
schema:
$ref: "#/components/schemas/SearchMalloyDocsResponse"
"401":
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"422":
description: The request body failed validation (e.g. missing, empty, or
oversized field, or wrong type). `error_code` is `INVALID_INPUT` and
`details` describes each violation.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"429":
description: Too many requests — the per-IP rate limit was exceeded. Retry after
a short back-off.
"500":
description: An internal server error occurred.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
components:
schemas:
SearchMalloyDocsRequest:
description: Request body for the search_malloy_docs endpoint.
type: object
required:
- query
properties:
query:
description: Natural-language query about Malloy syntax or language features.
Each request fans out to LLM work, so the size is capped; queries
over maxLength are rejected with 422.
type: string
minLength: 1
maxLength: 2000
SearchMalloyDocsResponse:
description: Response from the search_malloy_docs endpoint.
type: object
required:
- query
- answer
properties:
query:
description: The query that was searched (echoed back).
type: string
answer:
description: Synthesized answer with relevant documentation passages and code
snippets. Always a real synthesized answer — if the documentation
doesn't cover the topic, the answer says so in prose; a failed
search returns `500`, never a placeholder answer with `200`.
type: string
ErrorResponse:
description: Standard error response body.
type: object
required:
- error_code
- message
properties:
error_code:
type: string
description: A code identifying the type of error
enum:
- INVALID_INPUT
- UNAUTHORIZED
- FORBIDDEN
- NOT_FOUND
- CONFLICT
- INTERNAL_ERROR
- BAD_GATEWAY
- GATEWAY_TIMEOUT
message:
type: string
description: A human-readable error message
details:
type: string
description: Additional error details, if available
nullable: true
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
description: |
Auth0-issued user JWT. Provide as `Authorization: Bearer `.
apiKeyAuth:
type: apiKey
in: header
name: Authorization
description: |
HMAC-signed API key JWT (Group Access Token) issued by Credible. Provide
as `Authorization: ApiKey ` (note the `ApiKey ` prefix in place
of the usual `Bearer `). Include the full string — prefix and token —
in this field.
```
---
# Create a new database connection
Source: https://www.credibledata.com/docs/data-api-reference/connections/create-a-new-database-connection
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/connections/{connectionName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}:
post:
tags:
- connections
operationId: create-connection
summary: Create a new database connection
description: |
Creates a new database connection in the specified environment.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
responses:
"201":
description: Connection created successfully
content:
application/json:
schema:
type: object
properties:
message:
type: string
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Connection already exists
content:
application/json:
schema:
type: object
properties:
error:
type: string
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create SQL source from statement
Source: https://www.credibledata.com/docs/data-api-reference/connections/create-sql-source-from-statement
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/connections/{connectionName}/sqlSource
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}/sqlSource:
post:
tags:
- connections
operationId: post-sqlsource
summary: Create SQL source from statement
description: >
Creates a Malloy source from a SQL statement using the specified
database connection.
The SQL statement is executed to generate a source definition that can
be used in Malloy models.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
description: SQL statement to fetch the SQL source
required: true
content:
application/json:
schema:
type: object
properties:
sqlStatement:
type: string
responses:
"200":
description: SQL source information
content:
application/json:
schema:
$ref: "#/components/schemas/SqlSource"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
SqlSource:
type: object
properties:
resource:
type: string
description: Resource path to the sql source.
source:
type: string
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create SQL source from statement (per-package)
Source: https://www.credibledata.com/docs/data-api-reference/connections/create-sql-source-from-statement-per-package
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages/{packageName}/connections/{connectionName}/sqlSource
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/connections/{connectionName}/sqlSource:
post:
tags:
- connections
operationId: post-sqlsource-in-package
summary: Create SQL source from statement (per-package)
description: |
Creates a Malloy source from a SQL statement using the specified
connection, resolved in the context of the named package.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package whose connection context to use
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
description: SQL statement to fetch the SQL source
required: true
content:
application/json:
schema:
type: object
properties:
sqlStatement:
type: string
responses:
"200":
description: SQL source information
content:
application/json:
schema:
$ref: "#/components/schemas/SqlSource"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
SqlSource:
type: object
properties:
resource:
type: string
description: Resource path to the sql source.
source:
type: string
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create temporary table
Source: https://www.credibledata.com/docs/data-api-reference/connections/create-temporary-table
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/connections/{connectionName}/sqlTemporaryTable
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}/sqlTemporaryTable:
post:
tags:
- connections
operationId: post-temporarytable
summary: Create temporary table
description: >
Creates a temporary table from a SQL statement using the specified
database connection.
Temporary tables are useful for storing intermediate results during
complex queries and data processing workflows.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
description: SQL statement to create the temporary table
required: true
content:
application/json:
schema:
type: object
properties:
sqlStatement:
type: string
responses:
"200":
description: Temporary table information
content:
application/json:
schema:
$ref: "#/components/schemas/TemporaryTable"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
TemporaryTable:
type: object
properties:
resource:
type: string
description: Resource path to the temporary table.
table:
type: string
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create temporary table (per-package)
Source: https://www.credibledata.com/docs/data-api-reference/connections/create-temporary-table-per-package
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages/{packageName}/connections/{connectionName}/sqlTemporaryTable
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/connections/{connectionName}/sqlTemporaryTable:
post:
tags:
- connections
operationId: post-temporarytable-in-package
summary: Create temporary table (per-package)
description: |
Creates a temporary table from a SQL statement using the specified
database connection, resolved in the context of the named package.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package whose connection context to use
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
description: SQL statement to create the temporary table
required: true
content:
application/json:
schema:
type: object
properties:
sqlStatement:
type: string
responses:
"200":
description: Temporary table information
content:
application/json:
schema:
$ref: "#/components/schemas/TemporaryTable"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
TemporaryTable:
type: object
properties:
resource:
type: string
description: Resource path to the temporary table.
table:
type: string
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete a database connection
Source: https://www.credibledata.com/docs/data-api-reference/connections/delete-a-database-connection
## OpenAPI
````yaml /docs/api-specs/data.yaml delete /environments/{environmentName}/connections/{connectionName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}:
delete:
tags:
- connections
operationId: delete-connection
summary: Delete a database connection
description: |
Permanently deletes a database connection from the environment.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection to delete
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Connection deleted successfully
content:
application/json:
schema:
type: object
properties:
message:
type: string
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Execute SQL query
Source: https://www.credibledata.com/docs/data-api-reference/connections/execute-sql-query
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/connections/{connectionName}/sqlQuery
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}/sqlQuery:
post:
tags:
- connections
operationId: post-querydata
summary: Execute SQL query
description: >
Executes a SQL statement against the specified database connection and
returns the results.
The results include data, metadata, and execution information.
Rows returned are capped at PUBLISHER_MAX_QUERY_ROWS (default 100,000).
The cap is forwarded to the connector as a rowLimit on RunSQLOptions;
queries that return more rows than the cap fail with HTTP 413 rather
than serializing the response. Set PUBLISHER_MAX_QUERY_ROWS=0 to
disable the cap. A caller-supplied rowLimit smaller than the cap is
preserved; larger values are clamped down to cap+1.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
description: SQL statement to execute
required: true
content:
application/json:
schema:
type: object
properties:
sqlStatement:
type: string
options:
type: string
description: Options
responses:
"200":
description: Query execution results
content:
application/json:
schema:
$ref: "#/components/schemas/QueryData"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"413":
$ref: "#/components/responses/PayloadTooLarge"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
"504":
$ref: "#/components/responses/GatewayTimeout"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
QueryData:
type: object
properties:
resource:
type: string
description: Resource path to the query data.
data:
type: string
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
PayloadTooLarge:
description: |
The request was well-formed but the response exceeds a server-side
size cap. Two caps can fire:
* PUBLISHER_MAX_QUERY_ROWS (default 100000) — too many rows.
* PUBLISHER_MAX_RESPONSE_BYTES (default 50 MB) — JSON-serialized
response too large.
The error message identifies which cap fired. Refine the query (add
a LIMIT, more selective WHERE, project fewer columns) or raise the
relevant cap; retrying without changes will not succeed. The
per-cap rejection counter is exported as
publisher_query_cap_exceeded_total{cap_type, source}.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
GatewayTimeout:
description: |
The query exceeded the per-request wall-clock budget
(PUBLISHER_QUERY_TIMEOUT_MS) and was aborted server-side.
Refine the query (add a more selective WHERE, lower LIMIT,
simplify joins) or raise the timeout. Retrying without
changes is unlikely to succeed.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Execute SQL query (per-package)
Source: https://www.credibledata.com/docs/data-api-reference/connections/execute-sql-query-per-package
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages/{packageName}/connections/{connectionName}/sqlQuery
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/connections/{connectionName}/sqlQuery:
post:
tags:
- connections
operationId: post-querydata-in-package
summary: Execute SQL query (per-package)
description: |
Executes a SQL statement against the specified database connection,
resolved in the context of the named package, and returns the results.
Subject to the same PUBLISHER_MAX_QUERY_ROWS row cap as the
environment-level sqlQuery endpoint.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package whose connection context to use
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
description: SQL statement to execute
required: true
content:
application/json:
schema:
type: object
properties:
sqlStatement:
type: string
options:
type: string
description: Options
responses:
"200":
description: Query execution results
content:
application/json:
schema:
$ref: "#/components/schemas/QueryData"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"413":
$ref: "#/components/responses/PayloadTooLarge"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
"504":
$ref: "#/components/responses/GatewayTimeout"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
QueryData:
type: object
properties:
resource:
type: string
description: Resource path to the query data.
data:
type: string
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
PayloadTooLarge:
description: |
The request was well-formed but the response exceeds a server-side
size cap. Two caps can fire:
* PUBLISHER_MAX_QUERY_ROWS (default 100000) — too many rows.
* PUBLISHER_MAX_RESPONSE_BYTES (default 50 MB) — JSON-serialized
response too large.
The error message identifies which cap fired. Refine the query (add
a LIMIT, more selective WHERE, project fewer columns) or raise the
relevant cap; retrying without changes will not succeed. The
per-cap rejection counter is exported as
publisher_query_cap_exceeded_total{cap_type, source}.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
GatewayTimeout:
description: |
The query exceeded the per-request wall-clock budget
(PUBLISHER_QUERY_TIMEOUT_MS) and was aborted server-side.
Refine the query (add a more selective WHERE, lower LIMIT,
simplify joins) or raise the timeout. Retrying without
changes is unlikely to succeed.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get connection details
Source: https://www.credibledata.com/docs/data-api-reference/connections/get-connection-details
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/connections/{connectionName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}:
get:
tags:
- connections
operationId: get-connection
summary: Get connection details
description: >
Retrieves detailed information about a specific database connection
within an environment.
This includes connection configuration, credentials (if accessible), and
metadata.
Useful for inspecting connection settings and troubleshooting
connectivity issues.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Connection details and configuration
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get table details from database
Source: https://www.credibledata.com/docs/data-api-reference/connections/get-table-details-from-database
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/connections/{connectionName}/schemas/{schemaName}/tables/{tablePath}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}/schemas/{schemaName}/tables/{tablePath}:
get:
tags:
- connections
operationId: get-table
summary: Get table details from database
description: >
Retrieves a table from the specified database schema.
This endpoint is useful for discovering available data sources and
exploring the database
structure. The schema must exist in the connection for this operation to
succeed.
The tablePath is the full path to the table, including the schema name.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: schemaName
in: path
description: Name of the schema
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: tablePath
in: path
description: Full path to the table
required: true
schema:
$ref: "#/components/schemas/PathPattern"
responses:
"200":
description: Table information
content:
application/json:
schema:
$ref: "#/components/schemas/Table"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Table:
type: object
properties:
resource:
type: string
description: Resource path to the table.
source:
type: string
description: Table source as a JSON string.
columns:
description: Table fields
type: array
items:
$ref: "#/components/schemas/Column"
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get table details from database (per-package)
Source: https://www.credibledata.com/docs/data-api-reference/connections/get-table-details-from-database-per-package
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/connections/{connectionName}/schemas/{schemaName}/tables/{tablePath}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/connections/{connectionName}/schemas/{schemaName}/tables/{tablePath}:
get:
tags:
- connections
operationId: get-table-in-package
summary: Get table details from database (per-package)
description: |
Retrieves a table from the specified database schema, resolved in
the context of the named package.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package whose connection context to use
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: schemaName
in: path
description: Name of the schema
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: tablePath
in: path
description: Full path to the table
required: true
schema:
$ref: "#/components/schemas/PathPattern"
responses:
"200":
description: Table information
content:
application/json:
schema:
$ref: "#/components/schemas/Table"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
Table:
type: object
properties:
resource:
type: string
description: Resource path to the table.
source:
type: string
description: Table source as a JSON string.
columns:
description: Table fields
type: array
items:
$ref: "#/components/schemas/Column"
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List database schemas
Source: https://www.credibledata.com/docs/data-api-reference/connections/list-database-schemas
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/connections/{connectionName}/schemas
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}/schemas:
get:
tags:
- connections
operationId: list-schemas
summary: List database schemas
description: >
Retrieves a list of all schemas (databases) available in the specified
connection.
Each schema includes metadata such as name, description, and whether
it's the default schema.
This endpoint is useful for exploring the database structure and
discovering available data sources.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: A list of schemas available in the connection with metadata
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Schema"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Schema:
description: A schema name in a Connection.
type: object
properties:
name:
type: string
description: Name of the schema
description:
type: string
description: Description of the schema
isDefault:
type: boolean
description: Whether this schema is the default schema
isHidden:
type: boolean
description: Whether this schema is hidden
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List database schemas (per-package)
Source: https://www.credibledata.com/docs/data-api-reference/connections/list-database-schemas-per-package
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/connections/{connectionName}/schemas
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/connections/{connectionName}/schemas:
get:
tags:
- connections
operationId: list-schemas-in-package
summary: List database schemas (per-package)
description: |
Retrieves a list of all schemas (databases) available in the specified
connection, resolved in the context of the named package. Required for
`connectionName="duckdb"`, which is per-package; works for any other
connection name as well (resolution falls through to the environment).
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package whose connection context to use
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: A list of schemas available in the connection with metadata
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Schema"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Schema:
description: A schema name in a Connection.
type: object
properties:
name:
type: string
description: Name of the schema
description:
type: string
description: Description of the schema
isDefault:
type: boolean
description: Whether this schema is the default schema
isHidden:
type: boolean
description: Whether this schema is hidden
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List environment database connections
Source: https://www.credibledata.com/docs/data-api-reference/connections/list-environment-database-connections
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/connections
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections:
get:
tags:
- connections
operationId: list-connections
summary: List environment database connections
description: >
Retrieves a list of all database connections configured for the
specified environment.
Each connection includes its configuration, type, and status
information. This endpoint
is useful for discovering available data sources within an environment.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: A list of database connections in the environment
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Connection"
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List tables in database
Source: https://www.credibledata.com/docs/data-api-reference/connections/list-tables-in-database
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/connections/{connectionName}/schemas/{schemaName}/tables
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}/schemas/{schemaName}/tables:
get:
tags:
- connections
operationId: list-tables
summary: List tables in database
description: >
Retrieves a list of all tables and views available in the specified
database schema.
This endpoint is useful for discovering available data sources and
exploring the database
structure. The schema must exist in the connection for this operation to
succeed.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: schemaName
in: path
description: Name of the schema
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: tableNames
in: query
description: >
List of table names to filter results. When provided, only returns
metadata
for the specified tables. When omitted, returns all tables in the
schema.
required: false
schema:
type: array
items:
type: string
responses:
"200":
description: A list of table names available in the specified schema
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Table"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Table:
type: object
properties:
resource:
type: string
description: Resource path to the table.
source:
type: string
description: Table source as a JSON string.
columns:
description: Table fields
type: array
items:
$ref: "#/components/schemas/Column"
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List tables in database (per-package)
Source: https://www.credibledata.com/docs/data-api-reference/connections/list-tables-in-database-per-package
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/connections/{connectionName}/schemas/{schemaName}/tables
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/connections/{connectionName}/schemas/{schemaName}/tables:
get:
tags:
- connections
operationId: list-tables-in-package
summary: List tables in database (per-package)
description: |
Retrieves a list of all tables and views available in the specified
database schema, resolved in the context of the named package.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package whose connection context to use
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: schemaName
in: path
description: Name of the schema
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: tableNames
in: query
description: >
List of table names to filter results. When provided, only returns
metadata
for the specified tables. When omitted, returns all tables in the
schema.
required: false
schema:
type: array
items:
type: string
responses:
"200":
description: A list of table names available in the specified schema
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Table"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Table:
type: object
properties:
resource:
type: string
description: Resource path to the table.
source:
type: string
description: Table source as a JSON string.
columns:
description: Table fields
type: array
items:
$ref: "#/components/schemas/Column"
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update an existing database connection
Source: https://www.credibledata.com/docs/data-api-reference/connections/update-an-existing-database-connection
## OpenAPI
````yaml /docs/api-specs/data.yaml patch /environments/{environmentName}/connections/{connectionName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/connections/{connectionName}:
patch:
tags:
- connections
operationId: update-connection
summary: Update an existing database connection
description: |
Updates the configuration of an existing database connection.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: connectionName
in: path
description: Name of the connection to update
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
type: object
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
responses:
"200":
description: Connection updated successfully
content:
application/json:
schema:
type: object
properties:
message:
type: string
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Test database connection configuration
Source: https://www.credibledata.com/docs/data-api-reference/connectionstest/test-database-connection-configuration
## OpenAPI
````yaml /docs/api-specs/data.yaml post /connections/test
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/connections/test:
post:
tags:
- connectionsTest
operationId: test-connection-configuration
summary: Test database connection configuration
description: >
Validates a database connection configuration without adding it to any
environment.
This endpoint allows you to test connection parameters, credentials, and
network
connectivity before committing the connection to an environment. Useful
for troubleshooting
connection issues and validating configurations during setup.
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Connection"
responses:
"200":
description: Connection test result
content:
application/json:
schema:
$ref: "#/components/schemas/ConnectionStatus"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
ConnectionStatus:
type: object
description: Result of testing a database connection
properties:
status:
type: string
description: Connection test result status
enum:
- ok
- failed
errorMessage:
type: string
description: Error message if the connection test failed, null if successful
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List embedded databases
Source: https://www.credibledata.com/docs/data-api-reference/databases/list-embedded-databases
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/databases
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/databases:
get:
tags:
- databases
operationId: list-databases
summary: List embedded databases
description: >
Retrieves a list of all embedded databases within the specified package.
These are typically
DuckDB databases stored as .parquet files that provide local data
storage for the package.
Each database entry includes metadata about the database structure and
content.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: query
description: Version identifier for the package
required: false
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: A list of embedded databases in the package
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Database"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Database:
type: object
description: Embedded database within a Malloy package
properties:
resource:
type: string
description: Resource path to the database
path:
type: string
description: Relative path to the database file within its package directory
info:
$ref: "#/components/schemas/TableDescription"
type:
type: string
description: Type of embedded database
enum:
- embedded
- materialized
TableDescription:
type: object
description: Database table structure and metadata
properties:
name:
type: string
description: Name of the table
rowCount:
type: integer
description: Number of rows in the table
columns:
type: array
description: List of columns in the table
items:
$ref: "#/components/schemas/Column"
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a new environment
Source: https://www.credibledata.com/docs/data-api-reference/environments/create-a-new-environment
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments:
post:
tags:
- environments
operationId: create-environment
summary: Create a new environment
description: >
Creates a new Malloy environment with the specified configuration. An
environment serves as a
container for packages, connections, and other resources. The
environment will be initialized
with the provided metadata and can immediately accept packages and
connections.
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
responses:
"200":
description: Returns the environment created
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
Environment:
type: object
description: Represents a Malloy environment containing packages, connections,
and other resources
properties:
resource:
type: string
description: Resource path to the environment
name:
type: string
description: Environment name
readme:
type: string
description: Environment README content
location:
type: string
description: Environment location, can be an absolute path or URI (e.g. github,
s3, gcs, etc.)
connections:
type: array
description: List of database connections configured for this environment
items:
$ref: "#/components/schemas/Connection"
packages:
type: array
description: List of Malloy packages in this environment
items:
$ref: "#/components/schemas/Package"
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete an environment
Source: https://www.credibledata.com/docs/data-api-reference/environments/delete-an-environment
## OpenAPI
````yaml /docs/api-specs/data.yaml delete /environments/{environmentName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}:
delete:
tags:
- environments
operationId: delete-environment
summary: Delete an environment
description: >
Permanently deletes an environment and all its associated resources
including packages,
connections, and metadata. This operation cannot be undone, so use with
caution.
The environment must exist and be accessible for deletion.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Returns the environment deleted
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Environment:
type: object
description: Represents a Malloy environment containing packages, connections,
and other resources
properties:
resource:
type: string
description: Resource path to the environment
name:
type: string
description: Environment name
readme:
type: string
description: Environment README content
location:
type: string
description: Environment location, can be an absolute path or URI (e.g. github,
s3, gcs, etc.)
connections:
type: array
description: List of database connections configured for this environment
items:
$ref: "#/components/schemas/Connection"
packages:
type: array
description: List of Malloy packages in this environment
items:
$ref: "#/components/schemas/Package"
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get environment details and metadata
Source: https://www.credibledata.com/docs/data-api-reference/environments/get-environment-details-and-metadata
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}:
get:
tags:
- environments
operationId: get-environment
summary: Get environment details and metadata
description: >
Retrieves detailed information about a specific environment, including
its packages,
connections, configuration, and metadata. The reload parameter can be
used to
refresh the environment state from disk before returning the
information.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: reload
in: query
description: Load / reload the environment before returning result
required: false
schema:
type: boolean
responses:
"200":
description: Environment details and metadata
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Environment:
type: object
description: Represents a Malloy environment containing packages, connections,
and other resources
properties:
resource:
type: string
description: Resource path to the environment
name:
type: string
description: Environment name
readme:
type: string
description: Environment README content
location:
type: string
description: Environment location, can be an absolute path or URI (e.g. github,
s3, gcs, etc.)
connections:
type: array
description: List of database connections configured for this environment
items:
$ref: "#/components/schemas/Connection"
packages:
type: array
description: List of Malloy packages in this environment
items:
$ref: "#/components/schemas/Package"
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List all available environments
Source: https://www.credibledata.com/docs/data-api-reference/environments/list-all-available-environments
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments:
get:
tags:
- environments
operationId: list-environments
summary: List all available environments
description: >
Retrieves a list of all environments currently hosted on this Malloy
Publisher server.
Each environment contains metadata about its packages, connections, and
configuration.
This endpoint is typically used to discover available environments and
their basic information.
responses:
"200":
description: A list of all available environments
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Environment"
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
Environment:
type: object
description: Represents a Malloy environment containing packages, connections,
and other resources
properties:
resource:
type: string
description: Resource path to the environment
name:
type: string
description: Environment name
readme:
type: string
description: Environment README content
location:
type: string
description: Environment location, can be an absolute path or URI (e.g. github,
s3, gcs, etc.)
connections:
type: array
description: List of database connections configured for this environment
items:
$ref: "#/components/schemas/Connection"
packages:
type: array
description: List of Malloy packages in this environment
items:
$ref: "#/components/schemas/Package"
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update environment configuration
Source: https://www.credibledata.com/docs/data-api-reference/environments/update-environment-configuration
## OpenAPI
````yaml /docs/api-specs/data.yaml patch /environments/{environmentName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}:
patch:
tags:
- environments
operationId: update-environment
summary: Update environment configuration
description: >
Updates the configuration and metadata of an existing environment. This
allows you to
modify environment settings, update the README, change the location, or
update other
environment-level properties. The environment must exist and be
accessible.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
responses:
"200":
description: Returns the environment updated
content:
application/json:
schema:
$ref: "#/components/schemas/Environment"
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Environment:
type: object
description: Represents a Malloy environment containing packages, connections,
and other resources
properties:
resource:
type: string
description: Resource path to the environment
name:
type: string
description: Environment name
readme:
type: string
description: Environment README content
location:
type: string
description: Environment location, can be an absolute path or URI (e.g. github,
s3, gcs, etc.)
connections:
type: array
description: List of database connections configured for this environment
items:
$ref: "#/components/schemas/Connection"
packages:
type: array
description: List of Malloy packages in this environment
items:
$ref: "#/components/schemas/Package"
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments//connections/
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a materialization
Source: https://www.credibledata.com/docs/data-api-reference/materializations/create-a-materialization
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages/{packageName}/materializations
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/materializations:
post:
tags:
- materializations
operationId: create-materialization
summary: Create a materialization
description: >
Creates a materialization and starts building. Behavior depends on the
request
body (see CreateMaterializationRequest):
* Orchestrated build — supply `buildInstructions`. The publisher builds directly
into the caller-assigned names derived from the package's already-compiled build
plan (read off `Package.buildPlan`). Returns the materialization already building.
* Auto-run (standalone, default) — omit `buildInstructions`; the publisher
self-assigns names and runs all phases in one pass.
parameters:
- $ref: "#/components/parameters/environmentName"
- $ref: "#/components/parameters/packageName"
requestBody:
content:
application/json:
schema:
$ref: "#/components/schemas/CreateMaterializationRequest"
responses:
"201":
description: Materialization created
content:
application/json:
schema:
$ref: "#/components/schemas/Materialization"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Package already has an active materialization
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
parameters:
environmentName:
name: environmentName
in: path
required: true
description: Name of the environment
schema:
type: string
packageName:
name: packageName
in: path
required: true
description: Name of the package
schema:
type: string
schemas:
CreateMaterializationRequest:
type: object
description: Options for starting a materialization. Two modes — (1) auto-run
(default), omit `buildInstructions` and the publisher self-assigns names
and runs all phases in one pass; (2) orchestrated build, supply
`buildInstructions` and the publisher builds directly into the
caller-assigned names from the package's already-compiled build plan
(read off `Package.buildPlan`).
properties:
buildInstructions:
oneOf:
- $ref: "#/components/schemas/BuildInstructions"
- type: "null"
description: Orchestrated build. When present, the publisher creates the
materialization already building these caller-assigned sources
(table id, physical name, realization) into the exact names provided
— the caller derived these instructions from `Package.buildPlan` up
front. Omit for auto-run (the publisher self-assigns names and
builds all persist sources).
forceRefresh:
type: boolean
default: false
description: Build a new table even when a source's sourceEntityId is unchanged.
sourceNames:
type: array
items:
type: string
description: Restrict the plan/build to these persist source names. Omit = all
persist sources.
BuildInstructions:
type: object
description: Build input. Per-source instructions assigned by the caller.
required:
- sources
properties:
sources:
type: array
items:
$ref: "#/components/schemas/BuildInstruction"
referenceManifest:
type: array
description: Already-materialized persist upstreams the built sources may
reference but which are NOT rebuilt in this run. The publisher seeds
the build Manifest with these so a downstream source's upstream
persist reference resolves to the existing physical table instead of
recomputing it live. Only consumed on the orchestrated
(buildInstructions) path; auto-run seeds its own reference set from
the most-recent manifest.
items:
$ref: "#/components/schemas/ManifestReference"
strictUpstreams:
type: boolean
default: false
description: When true, a persist upstream that is neither built here nor
present in referenceManifest fails the build (compiler strict mode)
instead of silently recomputing it live. Per-unit dispatch should
set this true.
BuildInstruction:
type: object
required:
- sourceEntityId
- materializedTableId
- physicalTableName
- realization
properties:
sourceEntityId:
type: string
description: Identifies which planned source this instruction is for (matches
PersistSourcePlan.sourceEntityId).
sourceID:
type: string
description: Optional convenience echo of "sourceName@modelURL"; sourceEntityId
is authoritative.
materializedTableId:
type: string
description: Caller-assigned surrogate id for the materialized table about to be
produced.
physicalTableName:
type: string
description: Fully-qualified, dialect-quoted table name to create. The publisher
writes here verbatim.
realization:
$ref: "#/components/schemas/Realization"
Realization:
type: string
enum:
- SNAPSHOT
- COPY
description: SNAPSHOT = warehouse clone/snapshot; COPY = CREATE TABLE AS SELECT.
ManifestReference:
type: object
description: A reference to an already-materialized persist upstream that the
built sources may read but which is not rebuilt in this run.
required:
- sourceEntityId
- physicalTableName
properties:
sourceEntityId:
type: string
description: The upstream's content id AS REPORTED BY THE PUBLISHER in
PersistSourcePlan.sourceEntityId. It MUST equal what the compiler
recomputes for the manifest lookup (mkBuildID over the upstream's
manifest-ignorant SQL); do not substitute any other identity here.
physicalTableName:
type: string
description: Fully-qualified physical table the upstream currently serves.
Materialization:
type: object
description: A record of one materialization run for a package.
properties:
id:
type: string
environmentId:
type: string
packageName:
type: string
status:
$ref: "#/components/schemas/MaterializationStatus"
manifest:
oneOf:
- $ref: "#/components/schemas/BuildManifest"
- type: "null"
description: Build output. Null until status = MANIFEST_FILE_READY.
startedAt:
type:
- string
- "null"
format: date-time
completedAt:
type:
- string
- "null"
format: date-time
error:
type:
- string
- "null"
description: Error message if the materialization failed
metadata:
type:
- object
- "null"
description: Materialization metadata including build options, source counts,
and durations
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
MaterializationStatus:
type: string
description: Phase-aware status of a materialization run.
enum:
- PENDING
- MANIFEST_ROWS_READY
- MANIFEST_FILE_READY
- FAILED
- CANCELLED
BuildManifest:
type: object
description: Build output. Maps each sourceEntityId a build produced to its
physical table. Returned inline; the caller persists it.
properties:
builtAt:
type: string
format: date-time
entries:
type: object
additionalProperties:
$ref: "#/components/schemas/ManifestEntry"
description: Map of sourceEntityId to manifest entry.
strict:
type: boolean
description: Whether unresolved references should error.
ManifestEntry:
type: object
description: A single entry in the build manifest.
required:
- sourceEntityId
- physicalTableName
properties:
sourceEntityId:
type: string
sourceName:
type: string
materializedTableId:
type: string
description: Echoes the caller-assigned id from the BuildInstruction.
physicalTableName:
type: string
description: Name of the materialized table.
connectionName:
type: string
realization:
$ref: "#/components/schemas/Realization"
rowCount:
type:
- integer
- "null"
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete a materialization
Source: https://www.credibledata.com/docs/data-api-reference/materializations/delete-a-materialization
## OpenAPI
````yaml /docs/api-specs/data.yaml delete /environments/{environmentName}/packages/{packageName}/materializations/{materializationId}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/materializations/{materializationId}:
delete:
tags:
- materializations
operationId: delete-materialization
summary: Delete a materialization
description: |
Deletes a terminal (MANIFEST_FILE_READY, FAILED, or CANCELLED)
materialization record. By default this removes the publisher's record
only; the caller owns table GC. Set dropTables=true to also drop
the physical tables this run produced (from the materialization's
manifest) as a best-effort cleanup.
parameters:
- $ref: "#/components/parameters/environmentName"
- $ref: "#/components/parameters/packageName"
- $ref: "#/components/parameters/materializationId"
- name: dropTables
in: query
required: false
description: |
When true, also drop the physical tables recorded in the
materialization's manifest before deleting the record. Defaults to
false (record-only delete; the caller owns table GC).
schema:
type: boolean
default: false
responses:
"204":
description: Materialization deleted
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Materialization cannot be deleted while it is active
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
parameters:
environmentName:
name: environmentName
in: path
required: true
description: Name of the environment
schema:
type: string
packageName:
name: packageName
in: path
required: true
description: Name of the package
schema:
type: string
materializationId:
name: materializationId
in: path
required: true
description: ID of the materialization
schema:
type: string
responses:
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
schemas:
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get a specific materialization
Source: https://www.credibledata.com/docs/data-api-reference/materializations/get-a-specific-materialization
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/materializations/{materializationId}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/materializations/{materializationId}:
get:
tags:
- materializations
operationId: get-materialization
summary: Get a specific materialization
parameters:
- $ref: "#/components/parameters/environmentName"
- $ref: "#/components/parameters/packageName"
- $ref: "#/components/parameters/materializationId"
responses:
"200":
description: Materialization details
content:
application/json:
schema:
$ref: "#/components/schemas/Materialization"
"404":
$ref: "#/components/responses/NotFound"
components:
parameters:
environmentName:
name: environmentName
in: path
required: true
description: Name of the environment
schema:
type: string
packageName:
name: packageName
in: path
required: true
description: Name of the package
schema:
type: string
materializationId:
name: materializationId
in: path
required: true
description: ID of the materialization
schema:
type: string
schemas:
Materialization:
type: object
description: A record of one materialization run for a package.
properties:
id:
type: string
environmentId:
type: string
packageName:
type: string
status:
$ref: "#/components/schemas/MaterializationStatus"
manifest:
oneOf:
- $ref: "#/components/schemas/BuildManifest"
- type: "null"
description: Build output. Null until status = MANIFEST_FILE_READY.
startedAt:
type:
- string
- "null"
format: date-time
completedAt:
type:
- string
- "null"
format: date-time
error:
type:
- string
- "null"
description: Error message if the materialization failed
metadata:
type:
- object
- "null"
description: Materialization metadata including build options, source counts,
and durations
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
MaterializationStatus:
type: string
description: Phase-aware status of a materialization run.
enum:
- PENDING
- MANIFEST_ROWS_READY
- MANIFEST_FILE_READY
- FAILED
- CANCELLED
BuildManifest:
type: object
description: Build output. Maps each sourceEntityId a build produced to its
physical table. Returned inline; the caller persists it.
properties:
builtAt:
type: string
format: date-time
entries:
type: object
additionalProperties:
$ref: "#/components/schemas/ManifestEntry"
description: Map of sourceEntityId to manifest entry.
strict:
type: boolean
description: Whether unresolved references should error.
ManifestEntry:
type: object
description: A single entry in the build manifest.
required:
- sourceEntityId
- physicalTableName
properties:
sourceEntityId:
type: string
sourceName:
type: string
materializedTableId:
type: string
description: Echoes the caller-assigned id from the BuildInstruction.
physicalTableName:
type: string
description: Name of the materialized table.
connectionName:
type: string
realization:
$ref: "#/components/schemas/Realization"
rowCount:
type:
- integer
- "null"
Realization:
type: string
enum:
- SNAPSHOT
- COPY
description: SNAPSHOT = warehouse clone/snapshot; COPY = CREATE TABLE AS SELECT.
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List materializations for a package
Source: https://www.credibledata.com/docs/data-api-reference/materializations/list-materializations-for-a-package
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/materializations
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/materializations:
get:
tags:
- materializations
operationId: list-materializations
summary: List materializations for a package
description: Returns the materialization history for the package, ordered by
most recent first.
parameters:
- $ref: "#/components/parameters/environmentName"
- $ref: "#/components/parameters/packageName"
- name: limit
in: query
required: false
schema:
type: integer
minimum: 1
description: Maximum number of materializations to return
- name: offset
in: query
required: false
schema:
type: integer
minimum: 0
description: Number of materializations to skip
responses:
"200":
description: List of materializations
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Materialization"
"404":
$ref: "#/components/responses/NotFound"
components:
parameters:
environmentName:
name: environmentName
in: path
required: true
description: Name of the environment
schema:
type: string
packageName:
name: packageName
in: path
required: true
description: Name of the package
schema:
type: string
schemas:
Materialization:
type: object
description: A record of one materialization run for a package.
properties:
id:
type: string
environmentId:
type: string
packageName:
type: string
status:
$ref: "#/components/schemas/MaterializationStatus"
manifest:
oneOf:
- $ref: "#/components/schemas/BuildManifest"
- type: "null"
description: Build output. Null until status = MANIFEST_FILE_READY.
startedAt:
type:
- string
- "null"
format: date-time
completedAt:
type:
- string
- "null"
format: date-time
error:
type:
- string
- "null"
description: Error message if the materialization failed
metadata:
type:
- object
- "null"
description: Materialization metadata including build options, source counts,
and durations
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
MaterializationStatus:
type: string
description: Phase-aware status of a materialization run.
enum:
- PENDING
- MANIFEST_ROWS_READY
- MANIFEST_FILE_READY
- FAILED
- CANCELLED
BuildManifest:
type: object
description: Build output. Maps each sourceEntityId a build produced to its
physical table. Returned inline; the caller persists it.
properties:
builtAt:
type: string
format: date-time
entries:
type: object
additionalProperties:
$ref: "#/components/schemas/ManifestEntry"
description: Map of sourceEntityId to manifest entry.
strict:
type: boolean
description: Whether unresolved references should error.
ManifestEntry:
type: object
description: A single entry in the build manifest.
required:
- sourceEntityId
- physicalTableName
properties:
sourceEntityId:
type: string
sourceName:
type: string
materializedTableId:
type: string
description: Echoes the caller-assigned id from the BuildInstruction.
physicalTableName:
type: string
description: Name of the materialized table.
connectionName:
type: string
realization:
$ref: "#/components/schemas/Realization"
rowCount:
type:
- integer
- "null"
Realization:
type: string
enum:
- SNAPSHOT
- COPY
description: SNAPSHOT = warehouse clone/snapshot; COPY = CREATE TABLE AS SELECT.
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Perform an action on a materialization
Source: https://www.credibledata.com/docs/data-api-reference/materializations/perform-an-action-on-a-materialization
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages/{packageName}/materializations/{materializationId}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/materializations/{materializationId}:
post:
tags:
- materializations
operationId: materialization-action
summary: Perform an action on a materialization
description: |
Performs an action on a materialization. The action is specified via
the `action` query parameter:
* `stop` - Cancels a PENDING or building materialization. Returns 200.
parameters:
- $ref: "#/components/parameters/environmentName"
- $ref: "#/components/parameters/packageName"
- $ref: "#/components/parameters/materializationId"
- name: action
in: query
required: true
schema:
type: string
enum:
- stop
description: Action to perform on the materialization
responses:
"200":
description: Materialization cancelled (action=stop)
content:
application/json:
schema:
$ref: "#/components/schemas/Materialization"
"400":
$ref: "#/components/responses/BadRequest"
"404":
$ref: "#/components/responses/NotFound"
"409":
description: Materialization cannot transition to the requested state
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
components:
parameters:
environmentName:
name: environmentName
in: path
required: true
description: Name of the environment
schema:
type: string
packageName:
name: packageName
in: path
required: true
description: Name of the package
schema:
type: string
materializationId:
name: materializationId
in: path
required: true
description: ID of the materialization
schema:
type: string
schemas:
Materialization:
type: object
description: A record of one materialization run for a package.
properties:
id:
type: string
environmentId:
type: string
packageName:
type: string
status:
$ref: "#/components/schemas/MaterializationStatus"
manifest:
oneOf:
- $ref: "#/components/schemas/BuildManifest"
- type: "null"
description: Build output. Null until status = MANIFEST_FILE_READY.
startedAt:
type:
- string
- "null"
format: date-time
completedAt:
type:
- string
- "null"
format: date-time
error:
type:
- string
- "null"
description: Error message if the materialization failed
metadata:
type:
- object
- "null"
description: Materialization metadata including build options, source counts,
and durations
createdAt:
type: string
format: date-time
updatedAt:
type: string
format: date-time
MaterializationStatus:
type: string
description: Phase-aware status of a materialization run.
enum:
- PENDING
- MANIFEST_ROWS_READY
- MANIFEST_FILE_READY
- FAILED
- CANCELLED
BuildManifest:
type: object
description: Build output. Maps each sourceEntityId a build produced to its
physical table. Returned inline; the caller persists it.
properties:
builtAt:
type: string
format: date-time
entries:
type: object
additionalProperties:
$ref: "#/components/schemas/ManifestEntry"
description: Map of sourceEntityId to manifest entry.
strict:
type: boolean
description: Whether unresolved references should error.
ManifestEntry:
type: object
description: A single entry in the build manifest.
required:
- sourceEntityId
- physicalTableName
properties:
sourceEntityId:
type: string
sourceName:
type: string
materializedTableId:
type: string
description: Echoes the caller-assigned id from the BuildInstruction.
physicalTableName:
type: string
description: Name of the materialized table.
connectionName:
type: string
realization:
$ref: "#/components/schemas/Realization"
rowCount:
type:
- integer
- "null"
Realization:
type: string
enum:
- SNAPSHOT
- COPY
description: SNAPSHOT = warehouse clone/snapshot; COPY = CREATE TABLE AS SELECT.
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Compile Malloy source code
Source: https://www.credibledata.com/docs/data-api-reference/models/compile-malloy-source-code
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages/{packageName}/models/{path}/compile
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/models/{path}/compile:
post:
tags:
- models
operationId: compile-model-source
summary: Compile Malloy source code
description: |
Compiles Malloy source code in the context of a specific model file.
The submitted source is appended to the full model content, giving it
access to all sources, imports, and queries defined in the model.
Relative imports resolve correctly against sibling model files.
Returns compilation status and any problems (errors or warnings) found.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
type: string
- name: path
in: path
description: Path to the model within the package (used to resolve relative
imports)
required: true
schema:
$ref: "#/components/schemas/PathPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/CompileRequest"
responses:
"200":
description: Compilation result with status and any problems
content:
application/json:
schema:
$ref: "#/components/schemas/CompileResult"
"400":
$ref: "#/components/responses/BadRequest"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
CompileRequest:
type: object
description: Request body for compiling Malloy source code
properties:
source:
type: string
description: Malloy source code to compile
includeSql:
type: boolean
default: false
description: If true, returns the generated SQL alongside compilation results
(only available when compilation succeeds and the source contains a
runnable query).
givens:
$ref: "#/components/schemas/Givens"
required:
- source
Givens:
type: object
description: Per-query given values that override model defaults. Keys are given
names declared in the model's `given:` block. Values must match the
declared type (string, number, boolean, date, etc.). See Malloy givens
documentation for accepted value shapes.
additionalProperties: true
CompileResult:
type: object
description: Result of a Malloy source compilation check
properties:
status:
type: string
description: Overall compilation status — "error" if any problems have error
severity
enum:
- success
- error
problems:
type: array
description: List of compilation problems (errors and warnings)
items:
$ref: "#/components/schemas/CompileProblem"
sql:
type: string
description: Generated SQL for the compiled query. Only present when includeSql
is true and compilation succeeds with a runnable query.
CompileProblem:
type: object
description: A compilation problem reported by the Malloy compiler
properties:
message:
type: string
description: Human-readable problem description
severity:
type: string
description: Severity level of the problem
enum:
- error
- warn
- debug
code:
type: string
description: Machine-readable error code
at:
type: object
description: Source location of the problem
properties:
url:
type: string
description: URL of the source file
range:
type: object
description: Character range within the source file
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Execute Malloy query
Source: https://www.credibledata.com/docs/data-api-reference/models/execute-malloy-query
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages/{packageName}/models/{path}/query
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/models/{path}/query:
post:
tags:
- models
operationId: execute-query-model
summary: Execute Malloy query
description: >
Executes a Malloy query against a model and returns the results. The
query can be specified
as a raw Malloy query string or by referencing a named query within the
model. This endpoint
supports both ad-hoc queries and predefined model queries, making it
flexible for various
use cases including data exploration, reporting, and application
integration.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/VersionIdPattern"
- name: path
in: path
description: Path to the model within the package
required: true
schema:
$ref: "#/components/schemas/PathPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/QueryRequest"
responses:
"200":
description: Query execution results
content:
application/json:
schema:
$ref: "#/components/schemas/QueryResult"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"413":
$ref: "#/components/responses/PayloadTooLarge"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
"504":
$ref: "#/components/responses/GatewayTimeout"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
QueryRequest:
type: object
description: Request body for executing a Malloy query
properties:
query:
type: string
description: Query string to execute on the model. If the query parameter is
set, the queryName parameter must be empty.
sourceName:
type: string
description: |
Name of the source in the model to use for queryName, search, and
topValue requests. A bare source name only — not a parameterized
source (`orders(state is "CA")`) and not an inline source extension
(`orders extend { where: state = "CA" }`); use the query field for
those. A name that requires Malloy quoting (spaces, a hyphen, a
reserved word, a leading digit) is accepted as-is.
queryName:
type: string
description: |
Name of a query to execute on a source in the model. Requires the
sourceName parameter is set. If the queryName parameter is set, the
query parameter must be empty. A bare name only — not a dotted
view path (`orders.by_month`) and not a view refinement
(`by_month + { limit: 10 }`); use the query field for those. A
name that requires Malloy quoting (spaces, a hyphen, a reserved
word, a leading digit) is accepted as-is.
compactJson:
type: boolean
default: false
description: 'If true, returns a simple JSON array of row objects in the form
{"columnName": value}. If false (default), returns the full Malloy
result with type metadata for rendering.'
versionId:
type: string
description: Version ID
filterParams:
type: object
deprecated: true
description: >
**DEPRECATED**: Use `givens` (native Malloy runtime parameters)
instead.
Targets the deprecated `#(filter)` annotation path. A presentation
filter migrates to a `filter` given defaulting to `f''`,
which
matches every row until a caller supplies a value. Two roles must
keep
the annotation: `#(filter, required)` carries index partition
metadata
a given cannot express (migrating it returns zero rows with no
error),
and `implicit` filters are row-level security. That is why this
field
is deprecated rather than removed. See
/docs/how-to/modeling/fine-grained-acls#parameterization
for the migration shape.
Filter parameter values keyed by filter name. Used with sources that
declare `#(filter)` annotations. Each value is either a string or an
array of strings.
additionalProperties: true
bypassFilters:
type: boolean
default: false
deprecated: true
description: >
**DEPRECATED**: Use `givens` (native Malloy runtime parameters)
instead.
See /docs/how-to/modeling/fine-grained-acls#parameterization
for the migration shape.
When true, skip server-side `#(filter)` injection entirely.
givens:
$ref: "#/components/schemas/Givens"
Givens:
type: object
description: Per-query given values that override model defaults. Keys are given
names declared in the model's `given:` block. Values must match the
declared type (string, number, boolean, date, etc.). See Malloy givens
documentation for accepted value shapes.
additionalProperties: true
QueryResult:
type: object
description: Results from executing a Malloy query
properties:
result:
type: string
description: JSON string containing the query results, metadata, and execution
information
resource:
type: string
description: Resource path to the query result
renderLogs:
type: array
description: Render tag validation messages (errors, warnings) detected during
query preparation
items:
$ref: "#/components/schemas/LogMessage"
LogMessage:
type: object
description: A log message from render tag validation
properties:
url:
type: string
description: URL of the source file related to this message
range:
type: object
description: Source location range for this message
properties:
start:
type: object
properties:
line:
type: integer
character:
type: integer
end:
type: object
properties:
line:
type: integer
character:
type: integer
severity:
type: string
description: Severity level of the log message
enum:
- debug
- info
- warn
- error
message:
type: string
description: Human-readable log message
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
PayloadTooLarge:
description: |
The request was well-formed but the response exceeds a server-side
size cap. Two caps can fire:
* PUBLISHER_MAX_QUERY_ROWS (default 100000) — too many rows.
* PUBLISHER_MAX_RESPONSE_BYTES (default 50 MB) — JSON-serialized
response too large.
The error message identifies which cap fired. Refine the query (add
a LIMIT, more selective WHERE, project fewer columns) or raise the
relevant cap; retrying without changes will not succeed. The
per-cap rejection counter is exported as
publisher_query_cap_exceeded_total{cap_type, source}.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
GatewayTimeout:
description: |
The query exceeded the per-request wall-clock budget
(PUBLISHER_QUERY_TIMEOUT_MS) and was aborted server-side.
Refine the query (add a more selective WHERE, lower LIMIT,
simplify joins) or raise the timeout. Retrying without
changes is unlikely to succeed.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get compiled Malloy model
Source: https://www.credibledata.com/docs/data-api-reference/models/get-compiled-malloy-model
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/models/{path}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/models/{path}:
get:
tags:
- models
operationId: get-model
summary: Get compiled Malloy model
description: >
Retrieves a compiled Malloy model with its source information, queries,
and metadata.
The model is compiled using the specified version of the Malloy
compiler. This endpoint
provides access to the model's structure, sources, and named queries for
use in applications.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
type: string
- name: path
in: path
description: Path to the model within the package
required: true
schema:
$ref: "#/components/schemas/PathPattern"
- name: versionId
in: query
description: Version identifier for the package
required: false
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: Compiled Malloy model
content:
application/json:
schema:
$ref: "#/components/schemas/CompiledModel"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"424":
$ref: "#/components/responses/ModelCompilationError"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
PathPattern:
type: string
pattern: ^[a-zA-Z0-9_/.-]+$
description: Path pattern supporting slashes, dots, and dashes
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
CompiledModel:
type: object
description: Compiled Malloy model with sources, queries, and metadata
properties:
resource:
type: string
description: Resource path to the model
packageName:
type: string
description: Name of the package containing this model
path:
type: string
description: Relative path to the model file within its package directory
malloyVersion:
type: string
description: Version of the Malloy compiler used to generate the model data
modelInfo:
type: string
description: JSON string containing model metadata and structure information
sourceInfos:
type: array
description: Array of JSON strings containing source information for each data
source
items:
type: string
queries:
type: array
description: Array of named queries defined in the model
items:
$ref: "#/components/schemas/Query"
sources:
type: array
description: Sources defined in this model
items:
$ref: "#/components/schemas/Source"
givens:
type: array
description: Givens (runtime parameters) declared on this model via the `given:`
keyword
items:
$ref: "#/components/schemas/Given"
Query:
type: object
description: Named model query definition
properties:
name:
type: string
description: Name of the query
sourceName:
type: string
description: Name of the source this query operates on
annotations:
type: array
description: Annotations attached to the query
items:
type: string
Source:
type: object
description: A Malloy source defined in a model
properties:
name:
type: string
description: Name of the source
annotations:
type: array
description: Annotations attached to the source
items:
type: string
views:
type: array
description: Views defined in this source
items:
$ref: "#/components/schemas/View"
filters:
type: array
description: Filters declared on this source via
items:
$ref: "#/components/schemas/Filter"
givens:
type: array
description: Model-level givens (runtime parameters) available to queries on
this source. Identical to `CompiledModel.givens`; repeated here for
SDK ergonomics so consumers iterating sources can render inputs
without a second lookup.
items:
$ref: "#/components/schemas/Given"
authorize:
type: array
description: >
Effective authorize expression gating this source, declared with
an `#(authorize)` annotation on its own line directly above the
`source:` line (a source may declare at most one) — normally the
author's expression as written, whether declared on this source
itself or carried in from elsewhere (the source it extends, a
query-source base, a composite member). Where Publisher cannot
attribute an expression to a declaring source it reports `"false"`
instead: a fail-closed placeholder, not something the author wrote,
and one more reason to read this list only as "gated" rather than
as a predicate. (File-level `##(authorize)` and the retired
string-form `#(authorize) ""` annotation are both refused at
model load, so no expression here ever comes from either.) An empty
or absent list means unrestricted.
Every gate is enforced as a row filter, so a denial is not a status
code. A request against a gated source succeeds with HTTP 200 and
returns only the rows the expression admits, which may be none. That
holds for an expression comparing only givens too: reading no row
field, it admits either every row or no row rather than allowing or
refusing the source outright. Do not treat a 200 with zero rows as
"no gate applied", and do not key on 403 to detect a gate verdict —
a 403 here is a package-level access denial, decided before any gate
runs, or a case where the gate itself could not be attached at all
(the entry point's own shape dropped the field the gate reads, or a
given the gate names was not supplied).
IMPORTANT for anything re-implementing the decision: this flat list
is not a predicate you can evaluate, and it is not a count of one. A
source declares at most one gate of its own, but the list
flattens every gate carried in, so several elements are normal — a
query source over a composite reports the same authored gate twice,
once from its base and once from the resolved member. Expressions
that came from different declaring sources are AND-ed, never OR-ed:
with at most one gate per source there is no stacking left to mean
"either", so every element the list carries is a constraint that
must hold. Treat it as "at least these constraints apply" — use it
to decide THAT a source is gated, not to recompute WHETHER a given
caller passes. Reading it as a disjunction grants where Publisher
denies.
A gate reading a non-secure given is only a boundary behind a
trusted
tier, since such a value is caller-asserted; Credible resolves
`#(secure)` givens and `$GROUPS` server-side and strips any
caller-supplied copy. See the Access Control guide.
items:
type: string
View:
type: object
description: Named model view definition
properties:
name:
type: string
description: Name of the view
annotations:
type: array
description: Annotations attached to the view
items:
type: string
Filter:
type: object
deprecated: true
description: >
**DEPRECATED**: Use the `Given` schema (native Malloy runtime
parameters)
instead. See /docs/how-to/modeling/fine-grained-acls#parameterization
for the migration shape.
A filter declared via #(filter) annotation on a Malloy source.
properties:
name:
type: string
description: Display name of the filter
dimension:
type: string
description: Dimension this filter targets
type:
type: string
description: Comparator type
enum:
- equal
- in
- like
- greater_than
- less_than
implicit:
type: boolean
description: Whether this filter is hidden from users
required:
type: boolean
description: Whether a value must be provided
dimensionType:
type: string
description: Malloy data type of the dimension (e.g. string, number, boolean,
date, timestamp)
Given:
type: object
description: A given (runtime parameter) declared on a Malloy model via the
`given:` keyword. Surfaced on `CompiledModel.givens` and `Source.givens`
so callers can introspect what runtime values a model accepts.
properties:
name:
type: string
description: Name as declared in the model
type:
type: string
description: Rendered Malloy type for the given (e.g. string, number, boolean,
date, timestamp, filter)
annotations:
type: array
description: Annotations attached to the given declaration
items:
type: string
default:
type: string
description: The given's default value as a Malloy source literal (e.g. `'WN'`,
`2003`, `@2024-01-01`, `f'WN'`), exactly as written in the model.
Omitted when the given declares no default. Consumers render or
prefill it per the given's `type` (e.g. unquote a string literal for
a text input).
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ModelCompilationError:
description: Model compilation failed due to syntax or semantic errors
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List package models
Source: https://www.credibledata.com/docs/data-api-reference/models/list-package-models
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/models
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/models:
get:
tags:
- models
operationId: list-models
summary: List package models
description: >
Retrieves a list of all Malloy models within the specified package. Each
model entry
includes the relative path, package name, and any compilation errors.
This endpoint
is useful for discovering available models and checking their status.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: query
description: Version identifier for the package
required: false
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: A list of models in the package
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Model"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Model:
type: object
description: Malloy model metadata and status information
properties:
resource:
type: string
description: Resource path to the model
packageName:
type: string
description: Name of the package containing this model
path:
type: string
description: Relative path to the model file within its package directory
error:
type: string
description: Error message if the model failed to compile or load
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Execute a specific notebook cell
Source: https://www.credibledata.com/docs/data-api-reference/notebooks/execute-a-specific-notebook-cell
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/notebooks/{path}/cells/{cellIndex}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/notebooks/{path}/cells/{cellIndex}:
get:
tags:
- notebooks
operationId: execute-notebook-cell
summary: Execute a specific notebook cell
description: >
Executes a specific cell in a Malloy notebook by index. For code cells,
this compiles
and runs the Malloy code, returning query results and any new sources
defined.
For markdown cells, this simply returns the cell content.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
type: string
- name: path
in: path
description: Path to notebook within the package
required: true
schema:
type: string
- name: cellIndex
in: path
description: Index of the cell to execute (0-based)
required: true
schema:
type: integer
- name: versionId
in: query
description: Version identifier for the package
required: false
schema:
$ref: "#/components/schemas/VersionIdPattern"
- name: filter_params
in: query
deprecated: true
description: >
**DEPRECATED**: Use `givens` (native Malloy runtime parameters)
instead.
Targets the deprecated `#(filter)` annotation path. A presentation
filter migrates to a `filter` given defaulting to `f''`,
which
matches every row until a caller supplies a value. Two roles must
keep
the annotation: `#(filter, required)` carries index partition
metadata
a given cannot express (migrating it returns zero rows with no
error),
and `implicit` filters are row-level security. That is why this
field
is deprecated rather than removed. See
/docs/how-to/modeling/fine-grained-acls#parameterization
for the migration shape.
JSON-encoded filter parameter values keyed by filter name.
required: false
schema:
type: string
- name: bypass_filters
in: query
deprecated: true
description: >
**DEPRECATED**: Use `givens` (native Malloy runtime parameters)
instead.
See /docs/how-to/modeling/fine-grained-acls#parameterization
for the migration shape.
When true, skip filter injection entirely.
required: false
schema:
type: string
enum:
- "true"
- "false"
- name: givens
in: query
description: JSON-encoded given values keyed by given name
required: false
schema:
type: string
responses:
"200":
description: Cell execution result
content:
application/json:
schema:
$ref: "#/components/schemas/NotebookCellResult"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"413":
$ref: "#/components/responses/PayloadTooLarge"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
"504":
$ref: "#/components/responses/GatewayTimeout"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
NotebookCellResult:
type: object
description: Result of executing a notebook cell
properties:
type:
type: string
enum:
- markdown
- code
description: Type of notebook cell
text:
type: string
description: Text contents of the notebook cell
result:
type: string
description: JSON string containing the execution result for this cell
newSources:
type: array
description: Array of JSON strings containing SourceInfo objects made available
in this cell
items:
type: string
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
PayloadTooLarge:
description: |
The request was well-formed but the response exceeds a server-side
size cap. Two caps can fire:
* PUBLISHER_MAX_QUERY_ROWS (default 100000) — too many rows.
* PUBLISHER_MAX_RESPONSE_BYTES (default 50 MB) — JSON-serialized
response too large.
The error message identifies which cap fired. Refine the query (add
a LIMIT, more selective WHERE, project fewer columns) or raise the
relevant cap; retrying without changes will not succeed. The
per-cap rejection counter is exported as
publisher_query_cap_exceeded_total{cap_type, source}.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
GatewayTimeout:
description: |
The query exceeded the per-request wall-clock budget
(PUBLISHER_QUERY_TIMEOUT_MS) and was aborted server-side.
Refine the query (add a more selective WHERE, lower LIMIT,
simplify joins) or raise the timeout. Retrying without
changes is unlikely to succeed.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get Malloy notebook cells
Source: https://www.credibledata.com/docs/data-api-reference/notebooks/get-malloy-notebook-cells
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/notebooks/{path}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/notebooks/{path}:
get:
tags:
- notebooks
operationId: get-notebook
summary: Get Malloy notebook cells
description: >
Retrieves a Malloy notebook with its raw cell contents (markdown and
code).
Cell execution should be done separately via the execute-notebook-cell
endpoint.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
type: string
- name: path
in: path
description: Path to notebook within the package.
required: true
schema:
type: string
- name: versionId
in: query
description: Version identifier for the package
required: false
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: A Malloy notebook with raw cell contents.
content:
application/json:
schema:
$ref: "#/components/schemas/RawNotebook"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
RawNotebook:
type: object
description: Raw Malloy notebook with unexecuted cell contents
properties:
resource:
type: string
description: Resource path to the notebook
packageName:
type: string
description: Name of the package containing this notebook
path:
type: string
description: Relative path to the notebook file within its package directory
malloyVersion:
type: string
description: Version of the Malloy compiler used to generate the notebook data
notebookCells:
type: array
description: Array of notebook cells containing raw markdown and code content
items:
$ref: "#/components/schemas/NotebookCell"
annotations:
type: array
description: Array of file-level (##) annotations attached to the notebook
items:
type: string
sources:
type: array
description: Sources defined in the notebook's model
items:
$ref: "#/components/schemas/Source"
NotebookCell:
type: object
description: Individual cell within a Malloy notebook
properties:
type:
type: string
enum:
- markdown
- code
description: Type of notebook cell
text:
type: string
description: Text contents of the notebook cell (either markdown or Malloy code)
newSources:
type: array
description: Array of JSON strings containing SourceInfo objects made available
in this cell
items:
type: string
queryInfo:
type: string
description: JSON string containing QueryInfo object for the query in this cell
(if the cell contains a query)
Source:
type: object
description: A Malloy source defined in a model
properties:
name:
type: string
description: Name of the source
annotations:
type: array
description: Annotations attached to the source
items:
type: string
views:
type: array
description: Views defined in this source
items:
$ref: "#/components/schemas/View"
filters:
type: array
description: Filters declared on this source via
items:
$ref: "#/components/schemas/Filter"
givens:
type: array
description: Model-level givens (runtime parameters) available to queries on
this source. Identical to `CompiledModel.givens`; repeated here for
SDK ergonomics so consumers iterating sources can render inputs
without a second lookup.
items:
$ref: "#/components/schemas/Given"
authorize:
type: array
description: >
Effective authorize expression gating this source, declared with
an `#(authorize)` annotation on its own line directly above the
`source:` line (a source may declare at most one) — normally the
author's expression as written, whether declared on this source
itself or carried in from elsewhere (the source it extends, a
query-source base, a composite member). Where Publisher cannot
attribute an expression to a declaring source it reports `"false"`
instead: a fail-closed placeholder, not something the author wrote,
and one more reason to read this list only as "gated" rather than
as a predicate. (File-level `##(authorize)` and the retired
string-form `#(authorize) ""` annotation are both refused at
model load, so no expression here ever comes from either.) An empty
or absent list means unrestricted.
Every gate is enforced as a row filter, so a denial is not a status
code. A request against a gated source succeeds with HTTP 200 and
returns only the rows the expression admits, which may be none. That
holds for an expression comparing only givens too: reading no row
field, it admits either every row or no row rather than allowing or
refusing the source outright. Do not treat a 200 with zero rows as
"no gate applied", and do not key on 403 to detect a gate verdict —
a 403 here is a package-level access denial, decided before any gate
runs, or a case where the gate itself could not be attached at all
(the entry point's own shape dropped the field the gate reads, or a
given the gate names was not supplied).
IMPORTANT for anything re-implementing the decision: this flat list
is not a predicate you can evaluate, and it is not a count of one. A
source declares at most one gate of its own, but the list
flattens every gate carried in, so several elements are normal — a
query source over a composite reports the same authored gate twice,
once from its base and once from the resolved member. Expressions
that came from different declaring sources are AND-ed, never OR-ed:
with at most one gate per source there is no stacking left to mean
"either", so every element the list carries is a constraint that
must hold. Treat it as "at least these constraints apply" — use it
to decide THAT a source is gated, not to recompute WHETHER a given
caller passes. Reading it as a disjunction grants where Publisher
denies.
A gate reading a non-secure given is only a boundary behind a
trusted
tier, since such a value is caller-asserted; Credible resolves
`#(secure)` givens and `$GROUPS` server-side and strips any
caller-supplied copy. See the Access Control guide.
items:
type: string
View:
type: object
description: Named model view definition
properties:
name:
type: string
description: Name of the view
annotations:
type: array
description: Annotations attached to the view
items:
type: string
Filter:
type: object
deprecated: true
description: >
**DEPRECATED**: Use the `Given` schema (native Malloy runtime
parameters)
instead. See /docs/how-to/modeling/fine-grained-acls#parameterization
for the migration shape.
A filter declared via #(filter) annotation on a Malloy source.
properties:
name:
type: string
description: Display name of the filter
dimension:
type: string
description: Dimension this filter targets
type:
type: string
description: Comparator type
enum:
- equal
- in
- like
- greater_than
- less_than
implicit:
type: boolean
description: Whether this filter is hidden from users
required:
type: boolean
description: Whether a value must be provided
dimensionType:
type: string
description: Malloy data type of the dimension (e.g. string, number, boolean,
date, timestamp)
Given:
type: object
description: A given (runtime parameter) declared on a Malloy model via the
`given:` keyword. Surfaced on `CompiledModel.givens` and `Source.givens`
so callers can introspect what runtime values a model accepts.
properties:
name:
type: string
description: Name as declared in the model
type:
type: string
description: Rendered Malloy type for the given (e.g. string, number, boolean,
date, timestamp, filter)
annotations:
type: array
description: Annotations attached to the given declaration
items:
type: string
default:
type: string
description: The given's default value as a Malloy source literal (e.g. `'WN'`,
`2003`, `@2024-01-01`, `f'WN'`), exactly as written in the model.
Omitted when the given declares no default. Consumers render or
prefill it per the given's `type` (e.g. unquote a string literal for
a text input).
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List package notebooks
Source: https://www.credibledata.com/docs/data-api-reference/notebooks/list-package-notebooks
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/notebooks
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/notebooks:
get:
tags:
- notebooks
operationId: list-notebooks
summary: List package notebooks
description: >
Retrieves a list of all Malloy notebooks within the specified package.
Each notebook entry
includes the relative path, package name, and any compilation errors.
This endpoint
is useful for discovering available notebooks and checking their status.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: versionId
in: query
description: Version identifier for the package
required: false
schema:
$ref: "#/components/schemas/VersionIdPattern"
responses:
"200":
description: A list of models in the package
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Notebook"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Notebook:
type: object
description: Malloy notebook metadata and status information
properties:
resource:
type: string
description: Resource path to the notebook
packageName:
type: string
description: Name of the package containing this notebook
path:
type: string
description: Relative path to the notebook file within its package directory
error:
type: string
description: Error message if the notebook failed to compile or load
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Create a new package
Source: https://www.credibledata.com/docs/data-api-reference/packages/create-a-new-package
## OpenAPI
````yaml /docs/api-specs/data.yaml post /environments/{environmentName}/packages
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages:
post:
tags:
- packages
operationId: create-package
summary: Create a new package
description: >
Creates a new Malloy package within the specified environment. A package
serves as a
container for models, notebooks, embedded databases, and other
resources. The package
will be initialized with the provided metadata and can immediately
accept content.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
responses:
"200":
description: Returns the package created
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Delete a package
Source: https://www.credibledata.com/docs/data-api-reference/packages/delete-a-package
## OpenAPI
````yaml /docs/api-specs/data.yaml delete /environments/{environmentName}/packages/{packageName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}:
delete:
tags:
- packages
operationId: delete-package
summary: Delete a package
description: >
Permanently deletes a package and all its associated resources including
models,
notebooks, databases, and metadata. This operation cannot be undone, so
use with caution.
The package must exist and be accessible for deletion.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: Returns the package deleted
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get package details and metadata
Source: https://www.credibledata.com/docs/data-api-reference/packages/get-package-details-and-metadata
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}:
get:
tags:
- packages
operationId: get-package
summary: Get package details and metadata
description: >
Retrieves detailed information about a specific package, including its
models, notebooks,
databases, and metadata. The reload parameter can be used to refresh the
package state
from disk before returning the information. The versionId parameter
allows access to
specific package versions.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Package name
required: true
schema:
type: string
- name: versionId
in: query
description: Version identifier for the package
required: false
schema:
$ref: "#/components/schemas/VersionIdPattern"
- name: reload
in: query
description: Load / reload the package before returning result
required: false
schema:
type: boolean
responses:
"200":
description: Package details and metadata
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
VersionIdPattern:
type: string
pattern: ^[a-zA-Z0-9_.-]+$
description: Version identifier pattern supporting dots and dashes
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List environment packages
Source: https://www.credibledata.com/docs/data-api-reference/packages/list-environment-packages
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages:
get:
tags:
- packages
operationId: list-packages
summary: List environment packages
description: >
Retrieves a list of all Malloy packages within the specified
environment. Each package
contains models, notebooks, databases, and other resources. This
endpoint is useful
for discovering available packages and their basic metadata.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: A list of all packages in the environment
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Package"
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Update package configuration
Source: https://www.credibledata.com/docs/data-api-reference/packages/update-package-configuration
## OpenAPI
````yaml /docs/api-specs/data.yaml patch /environments/{environmentName}/packages/{packageName}
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}:
patch:
tags:
- packages
operationId: update-package
summary: Update package configuration
description: >
Updates the configuration and metadata of an existing package. This
allows you to
modify package settings, update the description, change the location, or
update other
package-level properties. The package must exist and be accessible.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
responses:
"200":
description: Returns the package updated
content:
application/json:
schema:
$ref: "#/components/schemas/Package"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# List package pages
Source: https://www.credibledata.com/docs/data-api-reference/pages/list-package-pages
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/pages
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/pages:
get:
tags:
- pages
operationId: list-pages
summary: List package pages
description: |
Retrieves a list of all static HTML pages (in-package data apps) within
the specified package. Each page entry includes the relative path, the
package name, a canonical resource URL, and the page title (extracted
from the file's tag, falling back to the path). Used by the
Publisher SPA to surface a clickable "Pages" section on the package
detail view, and by anyone who wants to discover in-package data apps
programmatically without scraping the directory. Recursive depth is
capped server-side to keep this cheap on large packages.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: A list of pages in the package
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/Page"
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"501":
$ref: "#/components/responses/NotImplemented"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Page:
type: object
description: Static HTML page (in-package data app) within a Malloy package
properties:
resource:
type: string
description: Canonical URL to the served page. Root-relative and does NOT carry
the /api/v0 prefix, because pages are static assets served off the
server root rather than API resources.
packageName:
type: string
description: Name of the package containing this page
path:
type: string
description: Relative path to the HTML file within its package directory
title:
type: string
description: Title extracted from the file's <title> tag, or the path if not
present
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotImplemented:
description: The requested operation is not implemented
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get server status and health information
Source: https://www.credibledata.com/docs/data-api-reference/publisher/get-server-status-and-health-information
## OpenAPI
````yaml /docs/api-specs/data.yaml get /status
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/status:
get:
tags:
- publisher
operationId: get-status
summary: Get server status and health information
description: >
Returns the current status of the Malloy Publisher server, including
initialization state,
available environments, and server timestamp. This endpoint is useful
for health checks and
monitoring server availability.
responses:
"200":
description: Returns server status
content:
application/json:
schema:
$ref: "#/components/schemas/ServerStatus"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
ServerStatus:
type: object
description: Current server status and health information
additionalProperties: true
properties:
timestamp:
type: number
description: Unix timestamp of the status check
environments:
type: array
description: List of available environments
items:
$ref: "#/components/schemas/Environment"
initialized:
type: boolean
description: Whether the server is fully initialized and ready to serve requests
operationalState:
type: string
enum:
- initializing
- serving
- draining
- throttled
description: Status of the server; initializing when the server is loading
environments, packages and connections, serving when the server is
initialized and ready to serve requests, draining when the server is
going to shut down, and throttled when the server has hit its memory
back-pressure limit and is rejecting new package loads and queries
to stay under PUBLISHER_MAX_MEMORY_BYTES (see the memory governor).
Already-loaded packages remain serviceable while throttled; callers
can treat a throttled server as unhealthy for new load. Only
reported when the memory governor is enabled.
frozenConfig:
type: boolean
description: Whether the server configuration is frozen (read-only mode). When
true, all mutation operations are disabled.
theme:
type: object
nullable: true
additionalProperties: true
description: Optional publisher UI theme metadata (branding/colors) reported by
newer publisher builds. Opaque to the control plane; surfaced here
so status deserialization tolerates it.
Environment:
type: object
description: Represents a Malloy environment containing packages, connections,
and other resources
properties:
resource:
type: string
description: Resource path to the environment
name:
type: string
description: Environment name
readme:
type: string
description: Environment README content
location:
type: string
description: Environment location, can be an absolute path or URI (e.g. github,
s3, gcs, etc.)
connections:
type: array
description: List of database connections configured for this environment
items:
$ref: "#/components/schemas/Connection"
packages:
type: array
description: List of Malloy packages in this environment
items:
$ref: "#/components/schemas/Package"
Connection:
type: object
description: Database connection configuration and metadata
properties:
resource:
type: string
description: Resource path to the connection
name:
type: string
description: Name of the connection
type:
type: string
description: Type of database connection
enum:
- postgres
- bigquery
- snowflake
- trino
- databricks
- mysql
- duckdb
- motherduck
- ducklake
- publisher
fingerprint:
type: string
description: >
Optional, opaque, stable fingerprint of this connection's data
identity. It is a hash of the configuration that determines *which
data* the connection reaches (its data-locating settings), and
deliberately excludes credentials and other secret values, so it
stays constant across credential rotation and changes only when the
connection is pointed at different data. When present, it is used as
this connection's contribution to content-addressed build
identifiers so that builds re-address only when the underlying data
identity actually changes; consumers should treat it as an opaque
token and use the supplied value verbatim rather than deriving their
own. This field is optional — when omitted, a connection identity is
derived locally instead.
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
proxy:
$ref: "#/components/schemas/ConnectionProxy"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
trinoConnection:
$ref: "#/components/schemas/TrinoConnection"
databricksConnection:
$ref: "#/components/schemas/DatabricksConnection"
mysqlConnection:
$ref: "#/components/schemas/MysqlConnection"
duckdbConnection:
$ref: "#/components/schemas/DuckdbConnection"
motherduckConnection:
$ref: "#/components/schemas/MotherDuckConnection"
ducklakeConnection:
$ref: "#/components/schemas/DucklakeConnection"
publisherConnection:
$ref: "#/components/schemas/PublisherConnection"
ConnectionAttributes:
type: object
description: Connection capabilities and configuration attributes
properties:
dialectName:
type: string
description: SQL dialect name for the connection
isPool:
type: boolean
description: Whether the connection uses connection pooling
canPersist:
type: boolean
description: Whether the connection supports persistent storage operations
canStream:
type: boolean
description: Whether the connection supports streaming query results
ConnectionProxy:
type: object
description: Optional network proxy through which the connection is reached.
Applies to any connection type whose database is not directly reachable
(e.g. behind a bastion). The proxy is established below the driver, so
the driver connects to a local endpoint transparently. Modeled as a
discriminated union on `type` so additional proxy mechanisms can be
added later.
properties:
type:
type: string
description: Proxy mechanism. Currently only SSH local port-forwarding.
enum:
- ssh
ssh:
$ref: "#/components/schemas/SshProxyConfig"
SshProxyConfig:
type: object
description: SSH bastion / jump-host config for reaching a database inside a
private network via an SSH local port-forward. Authentication is
public-key only.
properties:
host:
type: string
description: Bastion hostname or IP address (the SSH jump host)
port:
type: integer
default: 22
description: Bastion SSH port (defaults to 22)
username:
type: string
description: SSH username on the bastion
privateKey:
type: string
description: PEM-encoded SSH private key used to authenticate to the bastion.
Write-only secret (never returned by reads). When updating an
existing proxy, leave this blank to keep the stored key. The
customer authorizes the matching public key in the bastion's
authorized_keys.
privateKeyPass:
type: string
description: Passphrase for the encrypted private key, if any. Write-only secret
(never returned by reads). When updating, leave blank to keep the
stored passphrase (kept only when the private key is also kept, not
on rotation).
hostKey:
type: string
description: >
Optional pinned bastion host public key(s), as one or more OpenSSH
known_hosts lines (or bare base64 blobs), verified on every connect.
List multiple lines to pin a load-balanced/HA bastion that presents
a
different key per backend — any listed key is accepted; a mismatch
fails the connection closed. Plain and hashed (`|1|…`) lines both
work
— only the key blob is compared, never the hostname. When omitted,
the
tunnel connects without host-key verification (the self-service
default); the SSH transport is still encrypted.
PostgresConnection:
type: object
description: PostgreSQL database connection configuration
properties:
host:
type: string
description: PostgreSQL server hostname or IP address
port:
type: integer
description: PostgreSQL server port number
databaseName:
type: string
description: Name of the PostgreSQL database
userName:
type: string
description: PostgreSQL username for authentication
password:
type: string
description: PostgreSQL password for authentication
connectionString:
type: string
description: Complete PostgreSQL connection string (alternative to individual
parameters)
sslmode:
type: string
enum:
- disable
- no-verify
- verify-ca
description: TLS mode for a connection reached through a `proxy` (SSH bastion).
Because the driver connects to a local tunnel endpoint, the cert
hostname can't be checked; `verify-ca` validates the server cert
chain against the trusted CA bundle (e.g. the baked Amazon RDS
roots) without the hostname, `no-verify` encrypts without verifying,
and `disable` uses no TLS. The server defaults it to `no-verify`
when a proxy is set (so a force-SSL target isn't rejected for
plaintext) — a server-applied default, not a schema default. Only
valid on a proxied connection — a direct connection uses the
deployment PGSSLMODE and rejects this field.
BigqueryConnection:
type: object
description: Google BigQuery database connection configuration
properties:
defaultProjectId:
type: string
description: Default BigQuery project ID for queries
billingProjectId:
type: string
description: BigQuery project ID for billing purposes
location:
type: string
description: BigQuery dataset location/region
serviceAccountKeyJson:
type: string
description: JSON string containing Google Cloud service account credentials
maximumBytesBilled:
type: string
description: Maximum bytes to bill for query execution (prevents runaway costs)
queryTimeoutMilliseconds:
type: string
description: Query timeout in milliseconds
SnowflakeConnection:
type: object
description: Snowflake database connection configuration
properties:
account:
type: string
description: Snowflake account identifier
username:
type: string
description: Snowflake username for authentication
password:
type: string
description: Snowflake password for authentication
privateKey:
type: string
description: Snowflake private key for authentication
privateKeyPass:
type: string
description: Passphrase for the Snowflake private key
warehouse:
type: string
description: Snowflake warehouse name
database:
type: string
description: Snowflake database name
schema:
type: string
description: Snowflake schema name
role:
type: string
description: Snowflake role name
responseTimeoutMilliseconds:
type: integer
description: Query response timeout in milliseconds
TrinoConnection:
type: object
description: Trino database connection configuration
properties:
server:
type: string
description: Trino server hostname or IP address
port:
type: number
description: Trino server port number
catalog:
type: string
description: Trino catalog name
schema:
type: string
description: Trino schema name
user:
type: string
description: Trino username for authentication
password:
type: string
description: Trino password for authentication
peakaKey:
type: string
description: Peaka API key for authentication with Peaka-hosted Trino clusters
DatabricksConnection:
type: object
description: Databricks SQL warehouse connection configuration
properties:
host:
type: string
description: Databricks workspace host (e.g.
dbc-xxxxxxxx-xxxx.cloud.databricks.com)
path:
type: string
description: SQL warehouse HTTP path (e.g. /sql/1.0/warehouses/<warehouse-id>)
token:
type: string
description: Personal access token for authentication
oauthClientId:
type: string
description: OAuth M2M client ID (service principal)
oauthClientSecret:
type: string
description: OAuth M2M client secret (service principal)
defaultCatalog:
type: string
description: Default Unity Catalog to use for queries
defaultSchema:
type: string
description: Default schema to use for queries
setupSQL:
type: string
description: SQL statements to run when the connection is established
MysqlConnection:
type: object
description: MySQL database connection configuration
properties:
host:
type: string
description: MySQL server hostname or IP address
port:
type: integer
description: MySQL server port number
database:
type: string
description: Name of the MySQL database
user:
type: string
description: MySQL username for authentication
password:
type: string
description: MySQL password for authentication
DuckdbConnection:
type: object
description: >
DuckDB database connection configuration. Publisher intentionally
exposes only data-source intent here. Database files, working
directories, filesystem/network policy, extension loading, setup SQL,
temp directories, and resource knobs are owned by Publisher so
environment configs cannot widen deployment policy through low-level
DuckDB settings.
properties:
attachedDatabases:
type: array
items:
$ref: "#/components/schemas/AttachedDatabase"
AttachedDatabase:
type: object
description: Attached DuckDB database
properties:
name:
type: string
pattern: ^[a-zA-Z_][a-zA-Z0-9_]*$
example: test_connection, _connection, test_connection_1
type:
type: string
description: Type of database connection
enum:
- bigquery
- snowflake
- postgres
- gcs
- s3
- azure
attributes:
$ref: "#/components/schemas/ConnectionAttributes"
bigqueryConnection:
$ref: "#/components/schemas/BigqueryConnection"
snowflakeConnection:
$ref: "#/components/schemas/SnowflakeConnection"
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
s3Connection:
$ref: "#/components/schemas/S3Connection"
azureConnection:
$ref: "#/components/schemas/AzureConnection"
GCSConnection:
type: object
description: Google Cloud Storage connection configuration for DuckDB
properties:
keyId:
type: string
description: GCS HMAC access key ID
secret:
type: string
description: GCS HMAC secret key
required:
- keyId
- secret
S3Connection:
type: object
description: AWS S3 connection configuration for DuckDB
properties:
accessKeyId:
type: string
description: AWS access key ID
secretAccessKey:
type: string
description: AWS secret access key
region:
type: string
description: AWS region (e.g., us-east-1)
default: us-east-1
endpoint:
type: string
description: Custom S3-compatible endpoint URL (optional, for MinIO, etc.)
sessionToken:
type: string
description: AWS session token for temporary credentials (optional)
required:
- accessKeyId
- secretAccessKey
AzureConnection:
type: object
description: >
Azure Data Lake Storage (ADLS Gen2) / Blob Storage connection
configuration Supports https://, http://, abfss://, and az:// URL
schemes.
properties:
authType:
type: string
enum:
- service_principal
- sas_token
description: Authentication method for Azure Storage
sasUrl:
type: string
description: |
Full SAS URL including token; required for sas_token auth. Supports single file, directory glob (*.ext), or recursive (**) patterns. Example: https://account.blob.core.windows.net/container/path/*.parquet?sp=rl&st=...
tenantId:
type: string
description: Azure AD tenant ID (required for service_principal)
clientId:
type: string
description: Azure AD application (client) ID (required for service_principal)
clientSecret:
type: string
description: Azure AD client secret (required for service_principal)
accountName:
type: string
description: Azure Storage account name (required for service_principal)
fileUrl:
type: string
description: >
Azure file URL to query; required for service_principal auth.
Supports single file, directory glob (*.ext), or recursive (**)
patterns. Example:
https://account.blob.core.windows.net/container/path/**
required:
- authType
MotherDuckConnection:
type: object
description: MotherDuck database connection configuration
properties:
accessToken:
type: string
description: MotherDuck access token
database:
type: string
description: MotherDuck database name
DucklakeConnection:
type: object
description: DuckLake lakehouse connection configuration
properties:
storage:
type: object
description: Data storage connection configuration (S3 or GCS)
properties:
bucketUrl:
type: string
description: URL of the storage bucket (e.g. s3://my-bucket/path or
gs://my-bucket/path)
s3Connection:
$ref: "#/components/schemas/S3Connection"
description: AWS S3 connection configuration for data storage
gcsConnection:
$ref: "#/components/schemas/GCSConnection"
description: Google Cloud Storage connection configuration for data storage
required:
- bucketUrl
catalog:
type: object
description: Catalog metadata connection configuration
properties:
postgresConnection:
$ref: "#/components/schemas/PostgresConnection"
description: PostgreSQL connection for DuckLake metadata catalog
required:
- postgresConnection
required:
- storage
- catalog
PublisherConnection:
type: object
description: >
Malloy Publisher proxy connection. Proxies SQL to a remote Publisher
dataplane instead of connecting to a warehouse directly. The remote
dataplane owns authentication, access control, and read-only
enforcement.
properties:
connectionUri:
type: string
description: |
Full URI of the remote connection, e.g. https://org.data.example.com/api/v0/environments/<env>/connections/<name>
accessToken:
type: string
description: Bearer token for the remote dataplane (user-scoped, short-lived)
required:
- connectionUri
Package:
type: object
description: Represents a Malloy package containing models, notebooks, and
embedded databases
properties:
resource:
type: string
description: Resource path to the package
name:
type: string
description: Package name
description:
type: string
description: Package description
location:
type: string
description: Package location, can be an absolute path or URI (e.g. github, s3,
gcs, etc.)
explores:
type: array
items:
type: string
description: Optional opt-in for curated discovery. When present, only these
model file paths (relative to the package root) are listed via
`listModels()`, and within-file discovery is filtered to each
model's `export {}` closure. When absent or empty, every model is
listed with its full source set (backward-compatible). Every other
.malloy file still compiles for import/join resolution but is hidden
from listings once `explores` is declared. Notebooks are always
listed regardless of this field.
exploresWarnings:
type: array
readOnly: true
items:
type: string
description: "Actionable messages for declared explores that do not resolve to a
real model in this package (e.g. a misspelled path, or a notebook
listed as an explore). Server-computed and read-only: it is ignored
on create/update requests and only ever returned in responses.
Present only when there are such problems. Loading is fail-safe —
the unresolved entry simply lists nothing rather than exposing
everything — so this is the signal that a package is misconfigured;
publishing such a package is rejected."
warnings:
type: array
readOnly: true
description: 'Non-fatal render-tag findings collected when the package loaded: a
render annotation (e.g. `# big_value` or `# currency`) misconfigured
for the field it sits on, so it renders as "[object Object]" or an
inline error at query time but does not stop the model compiling or
the package loading. Server-computed and read-only: ignored on
create/update requests and only returned in responses. Present only
when there are such findings.'
items:
type: object
properties:
model:
type: string
description: Package-relative path of the model the finding is on.
target:
type: string
description: The query or view the finding sits on, e.g. `by_carrier` or
`flights -> by_carrier`.
message:
type: string
description: The render validator's description of the problem.
severity:
type: string
enum:
- error
- warn
description: Finding severity. Currently only `error`-severity render findings
are surfaced here; lower-severity findings remain on the
query-time `renderLogs` surface.
queryableSources:
type: string
enum:
- declared
- all
description: 'Controls whether the discovery surface is also a query boundary.
`"declared"` (the default) makes queryable == discoverable: when
`explores` is declared, only `explores` model files — and within
them only the `export {}` closure — are valid top-level query
targets; every other source still compiles, imports, joins, and
extends but is not directly queryable (denied with 404). `"all"`
decouples them: `explores`/`export {}` gate discovery only and every
compiled source stays directly queryable. When `explores` is absent
there is no curated surface, so both modes are equivalent
(everything queryable). Invalid values fall back to `"declared"`.
Identity-based access is a separate concern — see `#(authorize)`.'
manifestLocation:
type:
- string
- "null"
description: >
URI (gs:// or s3://) of the externally-computed manifest for this
package.
On (re)load the publisher reads it and binds persist references
(sourceEntityId -> physicalTableName). Null = serve live.
scope:
type: string
enum:
- version
- package
description: >-
Package-level materialization scope mode, declared at the
malloy-publisher.json manifest root. Governs the lifetime/ownership
of every persisted source and dimension index in the package, and
replaces the removed per-source/per-dimension `sharing` annotation:
- `version`: materializations are owned by (scoped to) the package
version; no cross-version reuse. Cadence is a single
package-level `materialization.schedule` OR freshness (never
both).
- `package`: materializations may be reused across the package's
own versions when fresh; cadence is freshness only (no
`schedule` allowed).
Null/absent = unknown this request; the control plane treats it as
the system default (`package`) and never as a scope change. See
docs/persistence.md §3.1.
materialization:
oneOf:
- $ref: "#/components/schemas/PackageMaterializationConfig"
- type: "null"
description: |
Package-level Malloy Persistence policy declared in
malloy-publisher.json. The control plane reads it to drive scheduled
re-materialization. The object is present whenever the package is
loaded (with `schedule: null` when none is declared), so its
presence is the authoritative manifest policy; null/absent means
only that metadata was unavailable this request, which the control
plane treats as "unknown" (never a schedule removal). A published
version's schedule is persisted write-once and thereafter only
verified, so it cannot self-wipe on a later build.
manifestBindingStatus:
type: string
readOnly: true
enum:
- unbound
- bound
- live_fallback
description: "Server-computed, read-only: whether the configured build manifest
is currently bound to this package's served models. `unbound` = no
manifest configured, so the package serves live. `bound` = a
manifest was fetched and applied, so persist sources route to their
materialized physical tables. `live_fallback` = a `manifestLocation`
is configured but the fetch/bind failed or timed out, so the package
is serving live despite intending to be materialized-routed. Lets
the caller confirm the publisher actually bound the configured
manifest rather than inferring it from logs."
manifestEntryCount:
type: integer
readOnly: true
description: "Server-computed, read-only: number of sourceEntityId ->
physical-table entries currently bound (0 when unbound or on live
fallback)."
boundManifestUri:
type:
- string
- "null"
readOnly: true
description: "Server-computed, read-only: the manifest URI actually bound to the
served models. Usually equals `manifestLocation`, but can differ
after an in-memory auto-load following a materialization build (no
URI), in which case it is null. Null whenever the package is
unbound."
buildPlan:
oneOf:
- $ref: "#/components/schemas/BuildPlan"
- type: "null"
readOnly: true
description: "Server-computed, read-only: the persist build plan for this
package version (per-source sourceEntityId, output columns, build
SQL, dependency graphs), exposed as a deterministic property of the
compiled package. A caller reads it directly off the
load/get-package response, assigns physical names/identity per
source, and issues a single build call (see
`CreateMaterializationRequest.buildInstructions`) — no separate plan
round-trip. The plan is a pure function of the compiled model +
connection config (no warehouse access), so it is stable for a given
(package version, connection config). Returned by default whenever
the package is compiled; null only when the package declares no
persist source."
PackageMaterializationConfig:
type: object
description: Package-level Malloy Persistence policy from
malloy-publisher.json's `materialization` block. Surfaced verbatim so
the control plane can drive scheduled version-level re-materialization
without re-reading the package files.
properties:
schedule:
type:
- string
- "null"
description: "5-field UNIX cron controlling how often the control plane
re-materializes this package's published versions. Null/absent = no
scheduled re-materialization (publish / on-demand only). A cron is
valid only in `scope: version` mode and is mutually exclusive with
any freshness declaration in the package (package/model-file/source/
index). A cron on a `scope: package` package, or alongside any
freshness, is rejected at publish (declare
`materialization.freshness.window` instead). See docs/persistence.md
§9.4."
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The manifest's `materialization.freshness` block, verbatim. Null =
no freshness policy declared. `window` is the control plane's
refresh objective for the package's materialized sources; `fallback`
is the declared query-time behavior when the objective is missed.
The publisher only surfaces the values — the control plane owns the
scheduling and gating logic.
Freshness:
type: object
description: Freshness policy declared in malloy-publisher.json's
`materialization.freshness` block. Fields are surfaced verbatim; invalid
values are dropped (reported as absent), never defaulted.
properties:
window:
type: string
description: Maximum acceptable staleness of the package's materialized sources,
as a duration string (e.g. "24h"). The control plane schedules
refreshes to meet it.
fallback:
type: string
enum:
- live
- stale_ok
- fail
description: "Declared query-time behavior when the freshness window is missed:
serve live, serve the stale table, or fail the query."
BuildPlan:
type: object
description: >
The package's persist build plan. Mirrors Malloy's native build plan
plus
the minimal per-source detail a caller needs to assign
identity/naming/realization. Lineage, policy, and connection capability
are intentionally omitted until they carry real data.
required:
- graphs
- sources
properties:
graphs:
type: array
description: Dependency-ordered build graphs, one per connection.
items:
$ref: "#/components/schemas/BuildGraph"
sources:
type: object
description: Map of sourceID ("sourceName@modelURL") to per-source plan.
additionalProperties:
$ref: "#/components/schemas/PersistSourcePlan"
BuildGraph:
type: object
required:
- connectionName
- nodes
properties:
connectionName:
type: string
nodes:
type: array
description: Leveled build nodes; each inner array is one parallelizable level,
levels run in order.
items:
type: array
items:
$ref: "#/components/schemas/BuildNode"
BuildNode:
type: object
required:
- sourceID
properties:
sourceID:
type: string
description: sourceName@modelURL
dependsOn:
type: array
description: Upstream sourceIDs in this graph.
items:
type: string
PersistSourcePlan:
type: object
required:
- name
- sourceID
- connectionName
- sourceEntityId
- sql
- columns
properties:
name:
type: string
sourceID:
type: string
connectionName:
type: string
dialect:
type: string
sourceEntityId:
type: string
description: Stable, content-addressed identity of this persisted source. Today
a deterministic SHA-256 hex digest (`mkBuildID`) over the source's
connection `fingerprint` and its canonical compiled SQL —
deliberately independent of package version, so it changes only when
the source's data identity changes. (Folding source scope into the
address and moving to a UUID5 form is planned but not yet shipped.)
Consumers treat it as an opaque token and use the supplied value
verbatim.
sql:
type: string
description: The source's build SQL (with the build manifest applied for
upstream rewrites).
refresh:
type:
- string
- "null"
description: The source's declared `#@ persist ... refresh=...` value ("full" |
"incremental"), reported verbatim; null = unset. Metadata
pass-through — inert to the publisher today.
freshness:
oneOf:
- $ref: "#/components/schemas/Freshness"
- type: "null"
description: The source's EFFECTIVE freshness objective after most-specific-wins
resolution (source > model-file > package). Null = unset at every
level; the control plane applies the system default. Reported
verbatim (invalid fields dropped, never defaulted).
columns:
type: array
description: Output schema of the source.
items:
$ref: "#/components/schemas/Column"
annotationFields:
type: object
additionalProperties:
type: string
description: All key=value fields of the source's `#@ persist` annotation (e.g.
`name`, `realization`). The control plane uses `name` as the
materialized table name — it may carry a dialect container path
(`dataset.table` / `project.dataset.table`) — falling back to the
Malloy source name when absent.
modelPath:
type: string
description: Package-relative path of the `.malloy` model that declares this
source (e.g. `order_rollup.malloy`). The source's sourceID embeds an
absolute `file://` modelURL with no package boundary, so this is the
only place the relative path is exposed; the control plane uses it
to let the build-plan DAG deep-link a source back to its model.
Column:
type: object
description: Database column definition
properties:
name:
type: string
description: Name of the column
type:
type: string
description: Data type of the column
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Get watch mode status
Source: https://www.credibledata.com/docs/data-api-reference/watch-mode/get-watch-mode-status
## OpenAPI
````yaml /docs/api-specs/data.yaml get /watch-mode/status
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/watch-mode/status:
get:
tags:
- watch-mode
operationId: get-watch-status
summary: Get watch mode status
description: >
Retrieves the current status of the file watching system. This includes
whether watch mode
is enabled, which environment is being watched, and the path being
monitored. Useful for
monitoring the development workflow and ensuring file changes are being
detected.
responses:
"200":
description: The current watch mode status.
content:
application/json:
schema:
$ref: "#/components/schemas/WatchStatus"
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
WatchStatus:
type: object
description: Current file watching status and configuration
properties:
enabled:
type: boolean
description: Whether file watching is currently active
environmentName:
type: string
description: Name of the environment being watched for file changes
watchingPath:
type: string
description: The file system path being monitored for changes, null if not
watching
required:
- enabled
- environmentName
- watchingPath
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Start file watching
Source: https://www.credibledata.com/docs/data-api-reference/watch-mode/start-file-watching
## OpenAPI
````yaml /docs/api-specs/data.yaml post /watch-mode/start
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/watch-mode/start:
post:
tags:
- watch-mode
operationId: start-watching
summary: Start file watching
description: >
Initiates file watching for the specified environment. This enables
real-time monitoring of
file changes within the environment directory, allowing for automatic
reloading and updates
during development. Only one environment can be watched at a time.
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/StartWatchRequest"
responses:
"200":
description: Watch mode started successfully.
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
StartWatchRequest:
type: object
description: Request to start file watching for an environment
properties:
environmentName:
type: string
description: Name of the environment to start watching for file changes
required:
- environmentName
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Stop file watching
Source: https://www.credibledata.com/docs/data-api-reference/watch-mode/stop-file-watching
## OpenAPI
````yaml /docs/api-specs/data.yaml post /watch-mode/stop
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/watch-mode/stop:
post:
tags:
- watch-mode
operationId: stop-watching
summary: Stop file watching
description: >
Stops the current file watching session. This disables real-time
monitoring of file changes
and releases system resources. Use this when development is complete or
when switching
to a different environment.
responses:
"200":
description: Watch mode stopped successfully.
"401":
$ref: "#/components/responses/Unauthorized"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
responses:
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
schemas:
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Stream package change events (SSE)
Source: https://www.credibledata.com/docs/data-api-reference/watch-mode/stream-package-change-events-sse
## OpenAPI
````yaml /docs/api-specs/data.yaml get /environments/{environmentName}/packages/{packageName}/events
openapi: 3.1.0
info:
title: Malloy Publisher - Semantic Data Model Serving API
description: >
The Malloy Publisher - Semantic Data Model Serving API provides
comprehensive access to Malloy packages and their associated resources.
A Malloy package is a directory containing Malloy models (.malloy files),
Malloy notebooks (.malloynb files), and embedded databases
(.parquet files) with a malloy-publisher.json manifest at the package's root
directory.
## Key Features
- **Environment Management**: Create and manage environments with their
associated packages and connections
- **Package Lifecycle**: Full CRUD operations for Malloy packages and their
versions
- **Model & Notebook Access**: Retrieve and execute Malloy models and
notebooks
- **Connection Management**: Secure database connection configuration and
testing
- **Query Execution**: Execute queries against models and retrieve results
- **Watch Mode**: Real-time file watching for development workflows
## Resource Hierarchy
The API follows a hierarchical resource structure:
```
Environments
├── Connections
└── Packages
├── Models
├── Notebooks
└── Databases
```
For examples, see the Malloy samples packages
(https://github.com/malloydata/malloy-samples) repository.
version: v0
servers:
- url: https://{organization}.data.credibledata.com/api/v0/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
tags:
- name: publisher
description: Publisher status and health check operations
- name: environments
description: Environment lifecycle management including creation, configuration,
and deletion of data modeling environments
- name: connections
description: Database connection management for secure data source configuration
and access
- name: connectionsTest
description: Validation of a database connection configuration before it is saved
- name: packages
description: Package management for Malloy data models, including versioning and
distribution
- name: models
description: Malloy model access and compilation operations
- name: notebooks
description: Malloy notebook access and execution operations
- name: pages
description: Static HTML pages (in-package data apps)
- name: databases
description: Embedded database management and access
- name: watch-mode
description: Real-time file watching for development workflows
- name: materializations
description: Package-level materializations for persisting Malloy sources
paths:
/environments/{environmentName}/packages/{packageName}/events:
get:
tags:
- watch-mode
operationId: stream-package-events
summary: Stream package change events (SSE)
description: |
Opens a Server-Sent Events (SSE) stream of file-change events for the
package, used by in-package HTML data apps (via the publisher.js
runtime) to live-reload when their sources are edited.
This is a long-lived `text/event-stream` connection, not a JSON
endpoint, and is therefore not surfaced through the generated API
clients — consume it with an `EventSource`. The stream emits:
- `event: hello` (`data: connected`) once on connect.
- `event: mode` (`data: enabled|disabled`) reporting whether watch
mode is currently active for the environment. When `disabled`, no
`changed` events will follow until watch mode is started.
- `event: changed` (`data: changed`) each time a watched file in the
package changes.
- periodic `: heartbeat` comments to keep idle proxies from closing
the connection.
parameters:
- name: environmentName
in: path
description: Name of the environment
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
- name: packageName
in: path
description: Name of the package
required: true
schema:
$ref: "#/components/schemas/IdentifierPattern"
responses:
"200":
description: An open Server-Sent Events stream of change events
content:
text/event-stream:
schema:
type: string
description: SSE event stream (see endpoint description for event types)
"400":
$ref: "#/components/responses/BadRequest"
"401":
$ref: "#/components/responses/Unauthorized"
"404":
$ref: "#/components/responses/NotFound"
"500":
$ref: "#/components/responses/InternalServerError"
"503":
$ref: "#/components/responses/ServiceUnavailable"
components:
schemas:
IdentifierPattern:
type: string
pattern: ^[a-zA-Z0-9_-]+$
description: Standard identifier pattern for resource names
Error:
type: object
description: Standard error response format
properties:
message:
type: string
description: Human-readable error message describing what went wrong
details:
type: string
description: Additional error details or context
required:
- message
responses:
BadRequest:
description: The request was malformed or cannot be performed given the current
state of the system
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
Unauthorized:
description: Unauthorized - authentication required
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
NotFound:
description: The specified resource was not found
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
InternalServerError:
description: The server encountered an internal error
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
ServiceUnavailable:
description: >
The service is temporarily unable to accept the request. Possible
causes:
* Initialization or draining state (rolling updates, graceful
shutdown).
* Memory back-pressure — the publisher's RSS crossed the
high-water mark derived from PUBLISHER_MAX_MEMORY_BYTES and
PUBLISHER_MEMORY_HIGH_WATER_FRACTION, so new queries are
rejected until RSS drops below the low-water mark
(PUBLISHER_MEMORY_LOW_WATER_FRACTION).
* Per-pod query concurrency cap reached — PUBLISHER_MAX_CONCURRENT_QUERIES
in-flight queries are already running on this pod.
Clients should retry with backoff; under sustained pressure, scale
out, raise PUBLISHER_MAX_MEMORY_BYTES /
PUBLISHER_MAX_CONCURRENT_QUERIES,
or refine the offending queries.
content:
application/json:
schema:
$ref: "#/components/schemas/Error"
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
````
---
# Search or enumerate indexed connection entities
Source: https://www.credibledata.com/docs/retrieval-api-reference/retrieval/search-or-enumerate-indexed-connection-entities
## OpenAPI
```yaml /docs/api-specs/retrieval.yaml post /search_connection_entities
openapi: 3.0.0
info:
title: Retrieval Public API
description: Public API for retrieving semantic data model contents.
version: v1
servers:
- url: https://{organization}.retrieval.credibledata.com/api/v1/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
- apiKeyAuth: []
tags:
- name: retrieval
description: Core retrieval API endpoints
paths:
/search_connection_entities:
post:
tags:
- retrieval
operationId: searchConnectionEntities
summary: Search or enumerate indexed connection entities
description: |
Search for (or, with `skip_matching`, enumerate) connection-scoped
entities in the connection index (tables, columns, and modeling
suggestions). Results are always grouped by table. Powers the Credible
app's connection schema viewer and the MCP `search_database_schema` /
`search_modeling_suggestions` tools. Package-scoped retrieval has moved
to `get_context`. Results are scoped to what the caller can access
(OpenFGA scoped-access checks).
**Paging (enumerate path only).** When `limit` is set on the request,
the enumerate path (no `query`) returns at most that many distinct
tables in a stable order and reports the total number of in-scope
tables on the `Total-Count` response header; page forward with `offset`.
The response body is unchanged — a bare `RetrievalResult` array — so
existing callers that ignore the header and omit `limit` are unaffected.
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/SearchConnectionEntitiesRequest"
responses:
"200":
description: OK
headers:
Total-Count:
description: >
Total number of distinct in-scope tables (before `limit`), when
the request supplied a `limit`. Lets a paging caller tell
whether
more tables remain past the returned page.
required: false
schema:
type: integer
content:
application/json:
schema:
type: array
items:
$ref: "#/components/schemas/RetrievalResult"
"400":
description: The request was malformed or cannot be performed given the state of
the system.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"401":
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"403":
description: Insufficient permissions or the state of the system prevents the
operation.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"404":
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
components:
schemas:
SearchConnectionEntitiesRequest:
description: |
Request body for the search_connection_entities endpoint. Self-contained
and scoped to the connection index — it does not reference the broader
internal retrieval context. Results are always grouped by table.
type: object
required:
- scopes
properties:
query:
description: >
Natural-language text to semantically match against indexed
entities.
When null or empty, the endpoint enumerates every indexed entity in
scope (no semantic matching) — used by callers that just want to
list
the contents of a connection.
type: string
nullable: true
scopes:
description: |
Connection scopes to search within. Results are restricted to the
union of these scopes, further intersected with what the caller can
access. At least one scope is required.
type: array
minItems: 1
items:
$ref: "#/components/schemas/ConnectionScope"
entity_types:
description: Restrict results to these entity types. When omitted, all types are
returned.
type: array
items:
$ref: "#/components/schemas/ConnectionEntityTypeEnum"
nullable: true
origin_types:
description: Restrict results to entities of these origins. When omitted, all
origins are returned.
type: array
items:
$ref: "#/components/schemas/ConnectionOriginTypeEnum"
nullable: true
include_joined_entities:
description: When true, also include entities reachable from the scoped tables
via joins. Defaults to false.
type: boolean
nullable: true
default: false
min_score:
description: Minimum cosine-similarity score for a semantic match (ignored when
enumerating). Defaults to 0.
type: number
nullable: true
top_n_results:
description: |
Maximum number of table-grouped results to return. Omit for the
service default; a value <= 0 returns every matching table.
type: integer
nullable: true
max_entities_per_result:
description: Maximum number of entities to return per table. A limit is strongly
recommended for performance.
type: integer
nullable: true
max_dimensional_values:
description: Maximum number of dimensional values to return per matched dimension.
type: integer
nullable: true
limit:
description: |
Maximum number of distinct tables to return, paged in a stable order
(by connection, catalog, schema, table). Only honored on the
enumerate path (no `query`); ranked search is not pageable. Omit for
the current unbounded behavior — every in-scope table is returned.
When set, the total number of in-scope tables is reported on the
`Total-Count` response header so the caller can compute the next
offset, and `top_n_results` is ignored (the page window bounds the
table count instead).
type: integer
minimum: 1
nullable: true
offset:
description: |
Number of tables to skip before the page (0-based), in the same
stable order as `limit`. Only honored on the enumerate path. Omit or
0 for the first page.
type: integer
minimum: 0
nullable: true
ConnectionScope:
description: |
A scope into the connection index. The organization is taken from the
authenticated request; `environment` names the project. The optional
connection/catalog/schema/table fields progressively narrow the search
to a connection, catalog, schema (dataset), or single table.
type: object
required:
- environment
properties:
environment:
description: The project (environment) that owns the connection.
type: string
connection_name:
description: Restrict to a single connection within the project.
type: string
nullable: true
catalog_name:
description: Restrict to a catalog/database tier ("project_id" in BigQuery,
"Database" in Snowflake).
type: string
nullable: true
schema_name:
description: Restrict to a schema/dataset tier ("dataset" in BigQuery, "Schema"
in Snowflake).
type: string
nullable: true
table_name:
description: Restrict to a single table.
type: string
nullable: true
ConnectionEntityTypeEnum:
description: |
The type of connection-index entity to search for. `all` is a
convenience marker that matches every concrete type.
type: string
enum:
- all
- table
- column
- dimension
- measure
- view
- join
- dimensional_value
ConnectionOriginTypeEnum:
description: |
The origin of a connection-index entity. `all` is a convenience marker
that matches every origin.
type: string
enum:
- all
- published
- sql_logs
- llm_generated
RetrievalResult:
description: A result from the retrieval endpoint (multiple can be returned)
type: object
properties:
package_info:
description: The package info for the result (can be null if the result is not
scoped by a package)
$ref: "#/components/schemas/PackageInfo"
nullable: true
model_uri:
description: The relative URI of the model for the result (can be null if the
result is not scoped by a model)
type: string
nullable: true
source:
description: The Malloy source for the result (can be null if the result is not
scoped by a source)
type: string
nullable: true
source_docs:
description: Documentation for the source (extracted from Malloy annotations)
type: string
nullable: true
score:
description: Overall score for the result (for comparing multiple results)
type: number
nullable: true
matches:
type: array
items:
$ref: "#/components/schemas/PhraseMatch"
PackageInfo:
description: Information about a package
type: object
required:
- organization
properties:
organization:
type: string
project:
type: string
nullable: true
package:
type: string
nullable: true
version:
type: string
nullable: true
PhraseMatch:
description: A set of matching entities for a specific phrase (or the whole text
if that's the phrase)
type: object
properties:
id:
description: Unique identifier for this phrase match
type: string
nullable: true
phrase:
description: The exact phrase that was matched in the original natural language
text
type: string
phrase_extended:
description: An extended version of the phrase used for better matching
type: string
phrase_type:
description: The type of phrase that was matched
type: string
phrase_dim_value_strings:
description: Dimensional value strings in the phrase (not matched entities, just
search terms)
type: array
nullable: true
items:
type: string
score:
description: The score for the phrase match
type: number
entities:
description: The entities that matched the phrase
type: array
items:
$ref: "#/components/schemas/RetrievedEntity"
RetrievedEntity:
description: >
An entity returned on the retrieval (read) path, annotated with the
scoring/match metadata produced during search.
type: object
required:
- entity
properties:
entity:
$ref: "#/components/schemas/Entity"
package_info:
$ref: "#/components/schemas/PackageInfo"
nullable: true
match_score:
description: A score indicating how well the entity matches the query (higher is
better)
type: number
nullable: true
match_reason:
type: string
nullable: true
description: The reason the model matched the entity to the query
dimensional_value_matches:
description: Matched dimensional values for this entity (if it's a dimension
with indexed values)
type: array
nullable: true
items:
$ref: "#/components/schemas/DimensionalValueMatch"
Entity:
description: A data model entity (column, dimension, measure, explore)
type: object
required:
- name
- field_type
properties:
id:
type: string
format: uuid
nullable: true
name:
type: string
field_type:
description: The type of entity (join, view, measure, dimension, column)
type: string
field_data_type:
type: string
nullable: true
is_malloy:
type: boolean
source:
type: string
nullable: true
code:
type: string
nullable: true
tags:
type: string
nullable: true
uri:
type: string
nullable: true
origin_type:
description: Where the entity is from (published, sql_logs, llm_generated)
type: string
nullable: true
join_path:
description: Path to this entity's source if joined (e.g.
"order_items.inventory_items" for "products.cost" when joined from
"order_items")
type: string
nullable: true
description:
type: string
nullable: true
keyphrase:
description: Short distilled phrase used for vector-search embedding.
LLM-generated from the description plus name/type/dtype/source
context. Not surfaced to agents; agents see `description`.
type: string
nullable: true
name_readable:
type: string
nullable: true
frequency:
description: The frequency of the dimensional value or a measure of how commonly
the entity is used
type: number
nullable: true
table_info:
description: Information about the table underlying the source this entity is from
$ref: "#/components/schemas/TableInfo"
nullable: true
join_info:
description: Information about the join (only for join entities)
$ref: "#/components/schemas/JoinInfo"
nullable: true
join_source_metadata:
description: Metadata about the joined source (only for join entities)
$ref: "#/components/schemas/JoinSourceMetadata"
nullable: true
dim_index_fingerprint:
description: Present only on `#(index)`-tagged dimension entities. Carries the
definitional inputs (the compiled fingerprint-query SQL hash plus
the required-filter set) that the controlplane folds together with
its connectionConfigHash to derive this entity's
cross-version-stable v5 `id`. MCS reports these on compile; the
controlplane owns the UUID5 derivation (see `DimIndexEntityId`) and
overwrites `id` with the result before persisting the entities
artifact. Absent on every other entity type, which keeps a per-run
random id.
$ref: "#/components/schemas/DimIndexFingerprint"
nullable: true
index_policy:
description: Present only on `#(index)`-tagged dimension entities that declare
at least one persistence-policy key. The per-dimension policy
declared on the dimension's `#(index ... )` annotation — `refresh`,
`freshness` — reported verbatim (the dimension-grain analog of
`PersistSourcePlan.{refresh,freshness}` on the source side). Scope
is uniform per package (`Package.scope`), so per-dimension `sharing`
and `schedule` are no longer supported and are rejected at publish.
Absent when the dimension declares no policy (index freshness is
opt-in per §9.5, so an unadorned `#(index)` reports nothing and the
control plane applies no proactive cadence). Invalid values are
dropped (reported absent), never defaulted.
$ref: "#/components/schemas/IndexPolicy"
nullable: true
TableInfo:
type: object
description: Information about the table underlying the source this entity is from
properties:
table_id:
type: string
nullable: true
connection_name:
description: The name of the connection this table is from
type: string
nullable: true
catalog_name:
description: The highest level of organization for a table ("project_id" in
BigQuery, and "Database" in Snowflake)
type: string
nullable: true
schema_name:
description: The second level of organization for a table ("dataset" in
BigQuery, and "Schema" in Snowflake)
type: string
nullable: true
table_name:
description: The name of the table
type: string
nullable: true
JoinInfo:
type: object
description: Metadata for join entities
properties:
join_table_id:
type: string
nullable: true
join_table_catalog:
type: string
nullable: true
join_table_schema:
type: string
nullable: true
join_table_name:
type: string
nullable: true
primary_table_field:
type: string
nullable: true
join_table_field:
type: string
nullable: true
join_type:
type: string
$ref: "#/components/schemas/JoinTypeEnum"
nullable: true
JoinTypeEnum:
description: The type of join in Malloy
type: string
enum:
- join_one
- join_many
- join_cross
JoinSourceMetadata:
type: object
description: Metadata about the joined source
properties:
original_source_name:
description: The name of the original source being joined (e.g., "airports" in
"origin is airports")
type: string
nullable: true
original_source_path:
description: The relative path to the model file containing the original source
type: string
nullable: true
is_nested_index:
description: Whether this join was indexed recursively (true for direct table
joins, extend/include cases)
type: boolean
nullable: true
DimIndexFingerprint:
description: Definitional inputs for a `#(index)`-tagged dimension's
cross-version stable entity id. Reported by MCS on the owning `Entity`;
the controlplane folds these with its connectionConfigHash to derive the
UUID5. The canonical byte layout is defined in `DimIndexEntityId`
(controlplane), which owns the UUID5; MCS pins only the
`sql_fingerprint` hash (`dim-index-entity-id.ts`).
type: object
required:
- sql_fingerprint
- required_filter_dimensions
properties:
sql_fingerprint:
description: Lowercase hex SHA-256 of the publisher-compiled fingerprint-query
SQL.
type: string
required_filter_dimensions:
description: The dimension's required-filter set. Sorted then comma-joined into
the canonical bytes; the exact set the fingerprint query grouped by.
type: array
items:
type: string
IndexPolicy:
description: 'Declared per-dimension index persistence policy, parsed from a
`#(index ... )` annotation. Mirrors the source-side
PersistSourcePlan.{refresh,freshness} on the entities channel.
Per-dimension `sharing` and `schedule` are no longer supported (scope is
package-level via `Package.scope`; a `schedule` is package-level and
`scope: version` only). Every field optional; an unset or invalid field
is omitted (never defaulted) so the control plane can distinguish
"unset" from an explicit value.'
type: object
properties:
refresh:
description: Declared `refresh=` ("full" | "incremental"). Null = unset.
Metadata pass-through.
type: string
enum:
- full
- incremental
nullable: true
freshness:
$ref: "#/components/schemas/Freshness"
nullable: true
Freshness:
description: A freshness objective parsed from a `freshness.window` /
`freshness.fallback` annotation. Fields surfaced verbatim; invalid
values are dropped (reported absent), never defaulted.
type: object
properties:
window:
description: Refresh SLO as a duration string, e.g. "1h", "24h", "7d". Null =
unset.
type: string
nullable: true
fallback:
description: Query-time behavior when the window is missed (indexes have no gate
today — metadata). Null = unset.
type: string
enum:
- live
- stale_ok
- fail
nullable: true
DimensionalValueMatch:
description: A matched dimensional value from search
type: object
properties:
value:
description: The actual dimensional value found
type: string
match_string:
description: The search string from the phrase that was used to find this value
type: string
nullable: true
score:
description: The match score from embedding search
type: number
nullable: true
frequency:
description: Usage frequency of the value (used as prominence in listing
responses)
type: number
nullable: true
ErrorResponse:
description: Standard error response
type: object
required:
- error_code
- message
properties:
error_code:
type: string
enum:
- INVALID_INPUT
- UNAUTHORIZED
- FORBIDDEN
- NOT_FOUND
- CONFLICT
- INTERNAL_ERROR
- BAD_GATEWAY
- GATEWAY_TIMEOUT
message:
type: string
details:
type: string
nullable: true
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
description: |
Auth0-issued user JWT. Provide as `Authorization: Bearer <token>`.
apiKeyAuth:
type: apiKey
in: header
name: Authorization
description: |
HMAC-signed API key JWT issued by Credible. Provide as
`Authorization: ApiKey <token>` (note the `ApiKey ` prefix in place
of the usual `Bearer `). Include the full string — prefix and
token — in this field.
```
---
# Search semantic model context
Source: https://www.credibledata.com/docs/retrieval-api-reference/retrieval/search-semantic-model-context
## OpenAPI
```yaml /docs/api-specs/retrieval.yaml post /get_context
openapi: 3.0.0
info:
title: Retrieval Public API
description: Public API for retrieving semantic data model contents.
version: v1
servers:
- url: https://{organization}.retrieval.credibledata.com/api/v1/
description: Production API server
variables:
organization:
default: demo
description: Your organization subdomain
security:
- bearerAuth: []
- apiKeyAuth: []
tags:
- name: retrieval
description: Core retrieval API endpoints
paths:
/get_context:
post:
tags:
- retrieval
operationId: getContext
summary: Search semantic model context
description: >
Search across published semantic data models. Each `search_targets`
entry picks an entity type (`source`, `dimension`, `measure`, `view`, or
`dimensional_value`) with optional `search_text`; omitting `search_text`
returns the most prominent items of that type. Results are sources with
matched entities, ranked by relevance and prominence. Use `scopes` to
narrow the search.
**Response size budget (`Max-Response-Chars` header).** Optionally send
the `Max-Response-Chars` request header set to a positive integer to
bound the serialized response size, in characters. When set, whole
source cards are dropped from the end of the page so the response body
stays within the budget; the paging envelope reports the reduced
`returned` count and a `warnings` entry explains how to see the rest
(page a listing, narrow a search). Cards are never truncated — only
dropped whole — and at least one is always kept. This is a
transport-level property of the caller's channel — an MCP host rejects
tool results above its context/token ceiling — rather than a query
parameter, so it rides on a request header instead of the request body;
the Credible MCP tools set it automatically. If the header is absent or
not a positive integer it is ignored and the response is unbounded — a
direct, non-MCP caller gets every ranked source.
requestBody:
required: true
content:
application/json:
schema:
$ref: "#/components/schemas/GetContextRequest"
responses:
"200":
description: OK
content:
application/json:
schema:
$ref: "#/components/schemas/GetContextResponse"
"400":
description: The request was malformed or cannot be performed given the state of
the system.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"401":
description: Unauthorized
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"403":
description: Insufficient permissions or the state of the system prevents the
operation.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"404":
description: The specified resource was not found.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"502":
description: An upstream service (e.g., LLM provider) returned an invalid
response.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
"504":
description: An upstream service (e.g., LLM provider) timed out.
content:
application/json:
schema:
$ref: "#/components/schemas/ErrorResponse"
components:
schemas:
GetContextRequest:
description: Request body for the get_context endpoint
type: object
required:
- search_targets
properties:
search_targets:
description: Typed search targets describing what to find. Each target specifies
a target type and optional search text for semantic matching.
type: array
items:
$ref: "#/components/schemas/SearchTarget"
scopes:
description: Optional list of scopes to narrow the search. Results will be
scoped to the union of these.
type: array
items:
$ref: "#/components/schemas/ResourceId"
nullable: true
filter_params:
description: >
Filter parameter values keyed by filter name. Used with sources that
declare `#(filter)` annotations. Each value is either a single
string
or an array of strings (matches the dataplane API's `filterParams`
shape). When the new dimensional-index path is enabled and active
for a package whose target dimension declares `#(filter, required)`,
the corresponding filter values MUST be supplied here — the request
will return 400 otherwise. Ignored on the legacy path.
type: object
additionalProperties: true
nullable: true
user_prompt:
description: >
Optional. The user's prompt that triggered this call, used for
observability and downstream ranking. On the first turn this is the
user's message verbatim. On follow-up turns where the user's message
doesn't convey intent (e.g. "yes" to an agent suggestion),
synthesize
a short prompt that captures the intent of the turn. Use the same
value for every get_context call within a single turn.
type: string
nullable: true
limit:
description: |
Maximum number of sources to return in this response (page size).
PREFER OMITTING THIS: results are ranked, so the default page
(20) already holds the best matches. When the caller supplies the
`Max-Response-Chars` header (the MCP tools always do), the
response is additionally bounded to that serialized size, so a page
over the budget comes back with fewer sources (cards are unchanged,
not stripped) plus a warning — a high `limit` does not guarantee
more sources. A large `total_available` is a signal to narrow with
`search_text` / `scopes` (or, on pure source listings, to page with
`offset`), not to raise `limit`. Reserve explicit limits above 20
for genuine bulk enumeration. Values above 150 are clamped to 150;
values below 1 are rejected with 400.
type: integer
minimum: 1
nullable: true
offset:
description: |
Number of sources to skip before the returned page, copied from a
previous response's `next_offset`. Only meaningful on pure
source-listing requests (only `source` targets, none with
`search_text`) — listings have a deterministic order that can be
resumed, while semantically ranked results do not. A non-zero
offset alongside any `search_text` target or non-source target is
rejected with 400; negative values are rejected with 400.
type: integer
minimum: 0
nullable: true
SearchTarget:
description: Describes a single target type to search for, with optional text
for semantic matching.
type: object
required:
- target_type
properties:
target_type:
description: The type of data model content to search for
$ref: "#/components/schemas/SearchTargetTypeEnum"
search_text:
description: >
String for semantic matching; null returns the most prominent items
ranked by usage.
- For `source`: brief description of the data domain (e.g.,
"ecommerce order data").
- For `dimension`: brief description of the attribute (e.g., "the
geographic region of the customer").
- For `measure`: brief description of the metric (e.g., "the total
revenue").
- For `view`: brief description of the desired analysis (e.g.,
"sales by region summary").
- For `dimensional_value`: the exact string value to match (e.g.,
"New York", "active").
type: string
nullable: true
SearchTargetTypeEnum:
description: |
The type of content a search target refers to:
- `source` — data sources that wrap and extend tables.
- `dimension` — categorical fields for grouping/filtering.
- `measure` — aggregation metrics (counts, sums, averages).
- `view` — pre-built analyses or named queries.
- `dimensional_value` — exact categorical values within a dimension.
type: string
enum:
- source
- dimension
- measure
- view
- dimensional_value
ResourceId:
description: Flat identifier for a resource within the data model hierarchy. The
optional fields form a hierarchy — if a lower-level field is set, all
fields above it must also be set (e.g., setting `source` requires
`model_path`).
type: object
required:
- environment
- package
properties:
environment:
description: The environment containing the package.
type: string
package:
description: The package name.
type: string
version:
description: The package version. When omitted, the pinned version is used.
type: string
nullable: true
model_path:
description: Relative path to the model file within the package (e.g.,
"model.malloy"). Required if `source` is set.
type: string
nullable: true
source:
description: The source name within the model. Required if `entity_name` is set.
type: string
nullable: true
entity_name:
description: The name of a specific entity to scope to (e.g., a dimension for
dimensional value searches).
type: string
nullable: true
GetContextResponse:
description: Response from the get_context endpoint
type: object
required:
- sources
properties:
sources:
description: Matched sources sorted by relevance then prominence (empty when no
good matches)
type: array
items:
$ref: "#/components/schemas/SourceResult"
ranking:
description: |
How the returned sources were ordered. `relevance` when any
search-text target contributed to the result set (semantic
ranking); `prominence` for pure listings (deterministic
usage/catalog order). Omitted when the request produced no
result set (e.g. no search targets).
type: string
enum:
- relevance
- prominence
nullable: true
total_available:
description: |
Total number of distinct sources that matched or were in scope
before the page cap was applied. When greater than `returned`,
more sources exist than were included in this response — narrow
with `search_text` / `scopes`, or (listings only) page with
`offset`. Always populated by current servers; optional only so
clients tolerate responses from servers predating this field.
type: integer
nullable: true
returned:
description: |
Number of sources included in this response. Always populated by
current servers; optional only so clients tolerate responses
from servers predating this field.
type: integer
nullable: true
next_offset:
description: |
The `offset` value that fetches the next page. Only present on
pure source-listing responses when more sources remain past this
page; pass it back via the request's `offset` field. Never present
on semantically ranked (search) responses, which cannot be resumed
— narrow the query instead.
type: integer
nullable: true
warnings:
description: Optional warnings about the result set (e.g. when results were
truncated or capped). Omitted when empty.
type: array
items:
type: string
nullable: true
SourceResult:
description: A matched source with metadata and a list of entities from the
source. Fields that would be null are omitted from the response.
type: object
required:
- source_info
properties:
source_info:
$ref: "#/components/schemas/SourceInfo"
relevance:
description: How relevant this source is to the search on a [0, 1] scale (higher
is better). Derived from source-level matching when available,
otherwise from entity relevance scores. Omitted when just listing
sources.
type: number
prominence:
description: How prominent this source is based on query usage patterns (higher
is better).
type: number
matched_targets:
description: Search targets that matched at the source level. Only includes
targets with non-null search_text (listing operations are excluded).
Omitted when empty (e.g., entity-level searches).
type: array
items:
$ref: "#/components/schemas/MatchedTarget"
entities:
description: Deduplicated entities from the source, sorted by relevance then
prominence. Omitted when empty.
type: array
items:
$ref: "#/components/schemas/SourceEntity"
SourceInfo:
description: Identification and metadata for a matched source. Fields that would
be null are omitted from the response.
type: object
required:
- resource_id
properties:
resource_id:
$ref: "#/components/schemas/ResourceId"
docs:
description: Documentation for the source (extracted from Malloy annotations)
type: string
summary:
description: LLM-generated summary of the source. Only present when source-type
search targets were used
type: string
filter_params:
description: Filters defined in the source that can be supplied to subset the
source contents. Omitted when empty.
type: array
items:
$ref: "#/components/schemas/Filter"
givens:
description: Model-level `given:` runtime parameters in scope for this source.
Each entry names a parameter the caller can supply on
`execute_query` to override the model's default. Omitted when the
source's model declares no givens.
type: array
items:
$ref: "#/components/schemas/Given"
authorize:
description: >
Access-gate expressions declared on this source via `#(authorize)`
and file-level `##(authorize)` annotations. Retrieval reports gate
**presence** and the raw text; it evaluates nothing, and this field
does not describe how Publisher combines gates or what a denial
looks like on the wire. Read the Publisher API's own
`Source.authorize` for that, and do not re-implement the access
decision from this field. Each entry lists the raw expression and
the given names it references. Omitted when the source is
unrestricted.
type: array
items:
$ref: "#/components/schemas/Authorize"
Filter:
description: >
A filter declared on a source via a `#(filter)` annotation. Describes a
single parameterized filter the source exposes at query time — the
filter's human-readable `name`, comparator `type`, the underlying
dimension it targets, and whether supplying a value is mandatory.
type: object
required:
- name
- type
properties:
name:
description: The filter's `name=` label — the human-readable identifier for this
filter, used as the key when supplying a filter value at query time.
type: string
type:
description: >
The comparator type applied to the underlying dimension. Determines
the value shape expected when supplying a filter value at query
time:
- `equal`, `like`, `greater_than`, `less_than` → a single scalar
string value
- `in` → an array of string values
type: string
enum:
- equal
- in
- like
- greater_than
- less_than
dimension:
description: The name of the underlying dimension the filter applies to.
Informational only — filter values are keyed by `name`, not
`dimension`.
type: string
required:
description: When true, a value for this filter must be supplied when querying
the source; otherwise the query will fail with a filter validation
error.
type: boolean
Given:
description: A `given:` runtime parameter declared on the source's model. The
publisher reports this on every `SourceInfo` whose model has givens, so
a caller iterating sources sees what runtime values it can supply
without a second lookup.
type: object
required:
- name
- type
properties:
name:
description: Name as declared in the model. Use this as the key when supplying a
value on `execute_query`.
type: string
type:
description: Rendered Malloy type (e.g. `string`, `number`, `boolean`, `date`,
`timestamp`, `filter<string>`). Determines the value shape expected
at query time.
type: string
annotations:
description: Annotations attached to the given declaration. May include
`description=` etc.
type: array
items:
type: string
default:
description: The given's declared default rendered as a Malloy source literal
(`'WN'`, `2003`, `@2024-01-01`, `f'WN'`). Omitted when no default is
declared. Hint for clients; omitting the given on `execute_query`
uses the default.
type: string
Authorize:
description: >
An `#(authorize)` gate expression declared on a source, or a file-level
`##(authorize)` expression in scope on the source's model, reported
verbatim. Retrieval uses gate presence only (to withhold a gated
source's dimension values from value search) and never evaluates these
expressions, so this schema deliberately says nothing about how
Publisher combines them or denies — see the Publisher API's
`Source.authorize`. Givens referenced in the expression must be supplied
by a trusted middle tier — gates over caller-asserted givens are not a
real boundary on their own.
type: object
required:
- expression
- given_names
properties:
expression:
description: The raw Malloy boolean expression as authored (e.g. `$ROLE =
'analyst'`). Use only for display; do not attempt to evaluate it
caller-side.
type: string
given_names:
description: Names of the givens referenced by this expression, extracted from
`$NAME` tokens. Lets a caller check whether its trusted context can
satisfy the gate before executing a query.
type: array
items:
type: string
MatchedTarget:
description: A search target (with non-null search_text) that matched at the
source or entity level. Fields that would be null are omitted from the
response.
type: object
required:
- search_text
- relevance
properties:
search_text:
description: The search string that produced this match
type: string
relevance:
description: Semantic match score on a [0, 1] scale (higher is better)
type: number
match_reason:
description: Why this matched the search target (from LLM evaluation)
type: string
SourceEntity:
description: A dimension, measure, or view belonging to a source in the data
model. Fields that would be null are omitted from the response.
type: object
required:
- name
- entity_type
properties:
name:
description: Exact Malloy field path (e.g., "hiring_manager.employee_count" for
joined fields)
type: string
entity_type:
description: The type of entity
$ref: "#/components/schemas/SourceEntityTypeEnum"
relevance:
description: Best semantic match score across all matched targets on a [0, 1]
scale (higher is better). Omitted when the entity was not matched
semantically (e.g., usage-ranked listing or dimensional value match
only).
type: number
prominence:
description: How prominent this entity is based on query usage patterns (higher
is better). Normalized score reflecting how frequently this entity
appears in real queries.
type: number
data_type:
description: The data type of the field
type: string
description:
description: Description of what this entity represents
type: string
values:
description: Matched dimensional values (dimensions only), sorted by relevance.
Omitted when empty.
type: array
items:
$ref: "#/components/schemas/DimensionalValue"
values_indexed:
description: When true, the dimension's values are individually indexed and can
be searched with `dimensional_value` targets. Only present on
dimensions.
type: boolean
code:
description: The entity's Malloy code definition. Returned only when the request
scopes to a specific entity (a scope with `entity_name`); omitted on
broad searches.
type: string
matched_targets:
description: Search targets that matched this entity and with what relevance.
Only includes targets with non-null search_text. Omitted when the
entity appears due to dimensional value matches or from a
usage-ranked listing.
type: array
items:
$ref: "#/components/schemas/MatchedTarget"
SourceEntityTypeEnum:
description: The type of source entity
type: string
enum:
- view
- measure
- dimension
DimensionalValue:
description: A dimensional value matched from search (always nested in its
corresponding dimension). Fields that would be null are omitted from the
response.
type: object
required:
- value
properties:
value:
description: The actual value found
type: string
relevance:
description: Semantic match score on a [0, 1] scale (higher is better). Omitted
when listed without semantic matching.
type: number
prominence:
description: How prominent this value is based on query usage patterns (higher
is better).
type: number
search_text:
description: The search string that was used to find this value
type: string
ErrorResponse:
description: Standard error response
type: object
required:
- error_code
- message
properties:
error_code:
type: string
enum:
- INVALID_INPUT
- UNAUTHORIZED
- FORBIDDEN
- NOT_FOUND
- CONFLICT
- INTERNAL_ERROR
- BAD_GATEWAY
- GATEWAY_TIMEOUT
message:
type: string
details:
type: string
nullable: true
securitySchemes:
bearerAuth:
type: http
scheme: bearer
bearerFormat: JWT
description: |
Auth0-issued user JWT. Provide as `Authorization: Bearer <token>`.
apiKeyAuth:
type: apiKey
in: header
name: Authorization
description: |
HMAC-signed API key JWT issued by Credible. Provide as
`Authorization: ApiKey <token>` (note the `ApiKey ` prefix in place
of the usual `Bearer `). Include the full string — prefix and
token — in this field.
```